The Natural Logarithm Is Just One Tool, Not a Philosophy
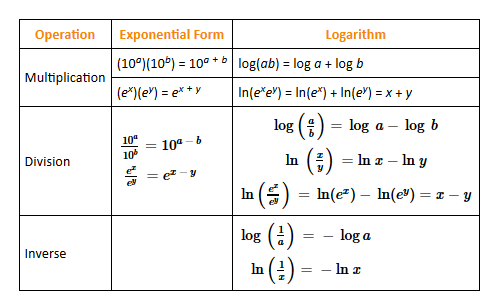
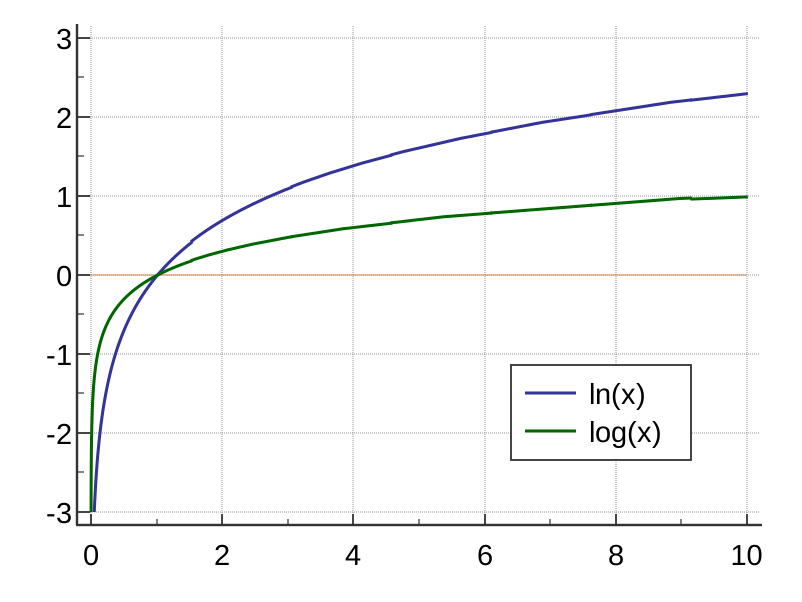
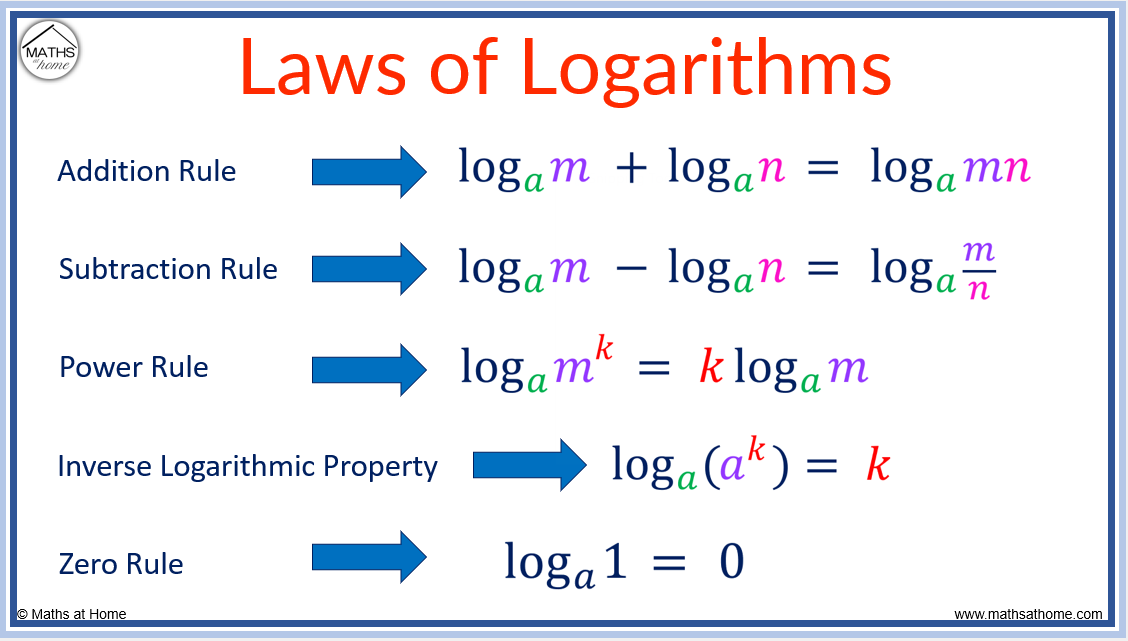
People on forums love to treat ln like it is some kind of secret decoder ring for understanding how the world works. It is not. It is a function. A very useful one, but a function nonetheless. You use it when exponential growth or decay shows up in your data, which is almost everywhere, but you do not need to mystify it. I spent years working on systems where signal processing and numerical estimation were the daily grind. The natural logarithm came up constantly, usually because something was decaying, compounding, or spreading out in a way that required linearization. That is the actual job of ln here: it turns multiplicative relationships into additive ones, which makes problems solvable with standard algebra instead of requiring numerical simulation every time.
What Is Log Ln Decoding The Mathematical Constants That Power Our World
The phrase gets used loosely online, often padded with unnecessary gravitas. At its core, what people are referring to is the application of the natural logarithm to extract meaningful parameters from exponential or power-law datasets. The "constants" part usually means things like decay rates, time constants, growth factors, or the Euler number e itself when it appears in models. Here is how the decoding actually works in practice. You start with data that follows an exponential pattern, something like y = A * e^(kt). If you take the natural log of both sides, you get ln(y) = ln(A) + kt. Now it is a straight line. You can fit it with ordinary least squares and pull out k, the rate parameter, and A, the scaling factor. That is the decoding step. You are recovering the underlying constants that generated the data. One thing most beginners miss is that this only works cleanly when the relationship is truly exponential. I once worked with a dataset that looked exponential at first glance, but was actually a stretched exponential, y = A * e^((kt)^beta). When I ran the standard ln transform, the residuals were garbage. The fix was to estimate beta numerically first, then re-run the linearization. Took about ten minutes once I stopped trying to force the standard approach. If you skip checking the residual plot, you will publish wrong constants and nobody will tell you until someone tries to use your numbers and the model falls apart.
When The Natural Log Breaks Down
There are scenarios where taking the natural log either fails entirely or produces misleading results. The first is noise. If your measurements have additive Gaussian noise, taking the log transforms that into multiplicative noise, which violates the assumptions of ordinary linear regression. In those cases, a log-transformed fit will give you biased parameter estimates. The workaround is to use a maximum likelihood approach that models the noise structure directly, or to use weighted least squares with weights inversely proportional to the variance at each point. The second failure mode is zero or negative values. You cannot take the natural log of zero or a negative number. Real sensor data often hits these boundaries, especially in engineering contexts where baseline drift or calibration offsets push readings below zero. The naive fix of adding a constant before logging introduces arbitrary bias into your estimated parameters. A better approach is to fit the offset as a parameter alongside the exponential terms, which means you are no longer doing a simple linear regression but rather a nonlinear optimization problem. For something like y = A * e^(kt) + C, you would use a solver like scipy.optimize.curve_fit or a proper nonlinear least squares routine. It adds maybe twenty minutes of runtime compared to a linear fit on a small dataset, but it saves you from publishing systematically wrong constants.
Get the Full Details

Practical Implementation
If you are doing this in Python, the straightforward path is to use numpy for the log transform and numpy.polyfit for the linear regression. Here is what the minimal working version looks like. You load your x and y data, filter out any non-positive y values, compute ln(y), then polyfit the result against x. The slope is k and the intercept gives you ln(A), so you exponentiate the intercept to recover A. For a typical dataset of a few thousand points, this runs in under a second on a modern machine. That is dramatically faster than a full nonlinear optimization, which might take a few seconds to a minute depending on complexity and initial guesses. But speed is not the only consideration. The linearized approach assumes homoscedastic errors in log space, which is rarely true. If your original measurements have roughly constant absolute uncertainty, the relative uncertainty grows as y gets smaller, meaning low-value points get overrepresented in the log-transformed fit. I found this out the hard way when modeling capacitor discharge curves. The early time points dominated the fit and the extracted time constant was off by about eight percent compared to a nonlinear fit that accounted for the noise structure. Eight percent matters when you are designing a circuit that needs to meet a timing spec.
Where This Actually Comes Up
Beyond the textbook examples of population growth and radioactive decay, ln decoding shows up in areas most people do not expect. It is used in economics for Cobb-Douglas production functions, in epidemiology for fitting infection curves in their exponential phase, in machine learning for log-likelihood optimization, and in thermodynamics for Arrhenius-type rate equations. The common thread is always the same: something changes proportionally to its current value, and you want to extract the proportionality constant. One domain where it is particularly common but poorly understood is audio signal processing. Envelope followers and compressor attack-release settings are essentially exponential curves, and analyzing them with ln transforms is standard practice. I worked on a project where we needed to characterize the release time of a hardware compressor across temperature variations. The manufacturer's spec sheet gave a single number, but our measurements showed it drifting by nearly thirty percent over the operating range. Taking the natural log of the envelope decay and fitting line segments at different temperatures revealed the drift pattern clearly. That information ended up being critical for the thermal compensation circuit design.
A Note On Overapplication
The biggest mistake I see is people applying ln transforms to data that is not exponential. Power laws, sinusoidal oscillations, logistic growth curves, and even pure noise can look vaguely "curvy" enough to tempt someone into a log transform. The residuals will tell you the truth. If you log-transform and the residuals still show structure, you have the wrong model. Going back to the drawing board is cheaper than publishing a result based on a misfitted curve. For logistic growth specifically, which is extremely common in biological and social systems, there is a valid log-based approach but it is different from the simple exponential case. You transform using ln(y/(A-y)) to linearize the logistic equation, which requires knowing or estimating the carrying capacity A first. Getting A wrong messes up the whole fit. I once spent an afternoon debugging a logistic model only to realize the assumed carrying capacity was off by a factor of two because it was based on preliminary data with poor sampling. Re-estimating A jointly with the growth rate using nonlinear optimization resolved it, but the initial waste of time was entirely avoidable with a better preliminary analysis. The natural logarithm is a workhorse function. It is not a philosophy, a decoder ring, or a universal key. It is a mathematical operation that linearizes exponential relationships, and it is extremely valuable when those relationships exist. Use it when the data justifies it, check your assumptions, look at your residuals, and do not force it into situations where it does not belong. The constants you extract will be more reliable for it.