What Data Obscurity Actually Looks Like in Practice
Most companies I talk to think they have their data covered because they've encrypted at rest and implemented role-based access controls. That's nice. It's also not the same thing as data obscurity, which is where things get complicated in modern enterprise environments. Data obscurity is the practice of making sensitive information difficult to identify or trace without actually removing or masking it at the source. You're not deleting the data. You're scrambling identifiers, tokenizing fields, applying reversible transformations, and generally making the raw content useless to anyone who doesn't have the right keys and context. The term itself comes from information security literature, but in practice it's more of a methodology than a single tool you can buy off a shelf.
What Is It Today Data Obscurity In Modern Companies Decoded
Today, data obscurity has become almost mandatory rather than optional, mainly because compliance frameworks like GDPR, HIPAA, and CCPA all treat pseudonymization and tokenization as legitimate safeguards. Companies that ignore this end up with audit findings that cost real money. But the practical implementation is where most organizations struggle. Here's the core approach: you start by identifying which data fields are considered sensitive. This isn't just PII. It includes transaction histories, medical codes, employee performance metrics, anything that could be re-identified when combined with other datasets. Once you have that list, you apply transformation techniques. Common methods include substitution, where you replace values with consistent aliases, format-preserving encryption, which keeps the data looking like the original format while scrambling the actual content, and deterministic tokenization, where a value always maps to the same substitute token across your systems. I worked with a healthcare client last year who needed to obscure patient identifiers across three different clinical systems while still maintaining referential integrity. The initial problem was that each system used a different internal ID scheme, and a naive masking approach broke their join queries. We ended up building a centralized token mapping service using AES-SIV encryption with a nonce derived from the source system. That gave us format-preserving output and consistent mapping without hard-coding relationships in the database. It took about three weeks to set up and reduced their manual reconciliation time from four hours per week down to zero.
The key insight most people miss is that obscurity and encryption are not interchangeable. Encryption is a cryptographic guarantee. Obscurity is a practical strategy that may use encryption as one tool among several. When you're designing an obscurity layer, you also need to think about key management, rotation schedules, and what happens when someone legitimately needs to see the original data. A lot of teams build the obfuscation pipeline and then have no process for lawful de-obfuscation requests, which becomes a compliance problem in itself. Another counter-intuitive point: more obscurity is not always better. If you over-obscure data in your development and testing environments, you lose the ability to validate that your transformations are working correctly. I've seen teams run production queries against test databases because the test data was so heavily tokenized that they couldn't even verify row counts matched. The workaround is to maintain a small, tightly controlled set of representative samples that use reversible transformations with known keys, separate from the full production obscurity layer. Implementation steps that actually work: first, inventory your data and classify it. This takes longer than you want it to, usually two to four weeks for a mid-size company with legacy systems. Second, choose your transformation methods based on your use case. If you need the data to remain queryable in its obscured form, format-preserving encryption is your best bet. If you need stronger security guarantees and can tolerate lookup tables for re-identification, go with tokenization. Third, implement key management properly. This means using a proper KMS, not just storing keys in environment variables. I've seen too many companies lose access to their own obscured data because they stored keys in a git repo and then forgot the commit hash.
Get the Full Details
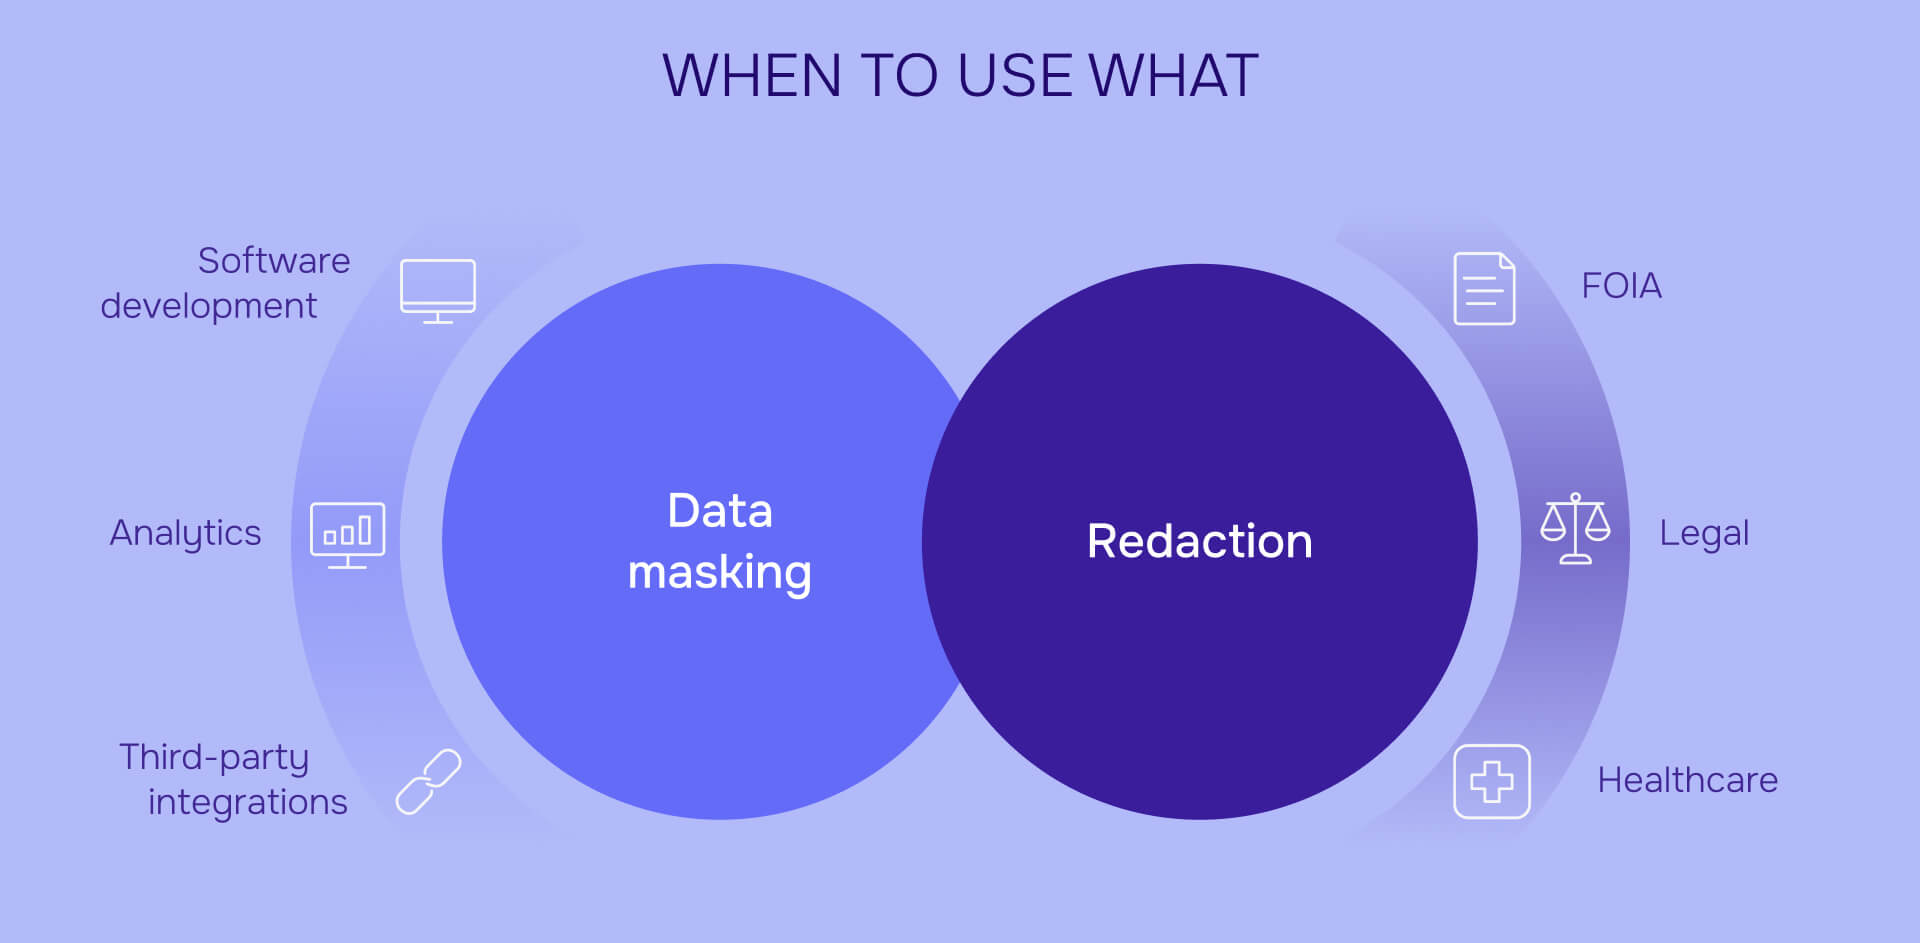
The tools available today range from commercial solutions like Microsoft Purview and Informatica to open-source libraries like Microsoft's SEAL or the Crypto++ toolkit. For most companies, a hybrid approach works best: commercial tools for the core pipeline and custom scripting around the edges for specific integration points. There are real limitations here. Data obscurity does not protect against inference attacks where someone deduces sensitive information from patterns in the obscured data. It also doesn't help if your access controls are weak. Obscuring a credit card number is useless if anyone in the organization can query the table containing it. And there's a maintenance overhead that most teams underestimate. Every time you rotate keys, update a transformation algorithm, or add a new data source, you need to reprocess existing data, which can take hours or days depending on volume. If you're dealing with highly regulated industries and need audit trails for every de-obfuscation event, consider whether a fully encrypted approach with searchable encryption might be more appropriate. Data obscurity is a solid middle ground for most situations, but it's not a universal solution.