Understanding URL Parameters for Search and Security Research
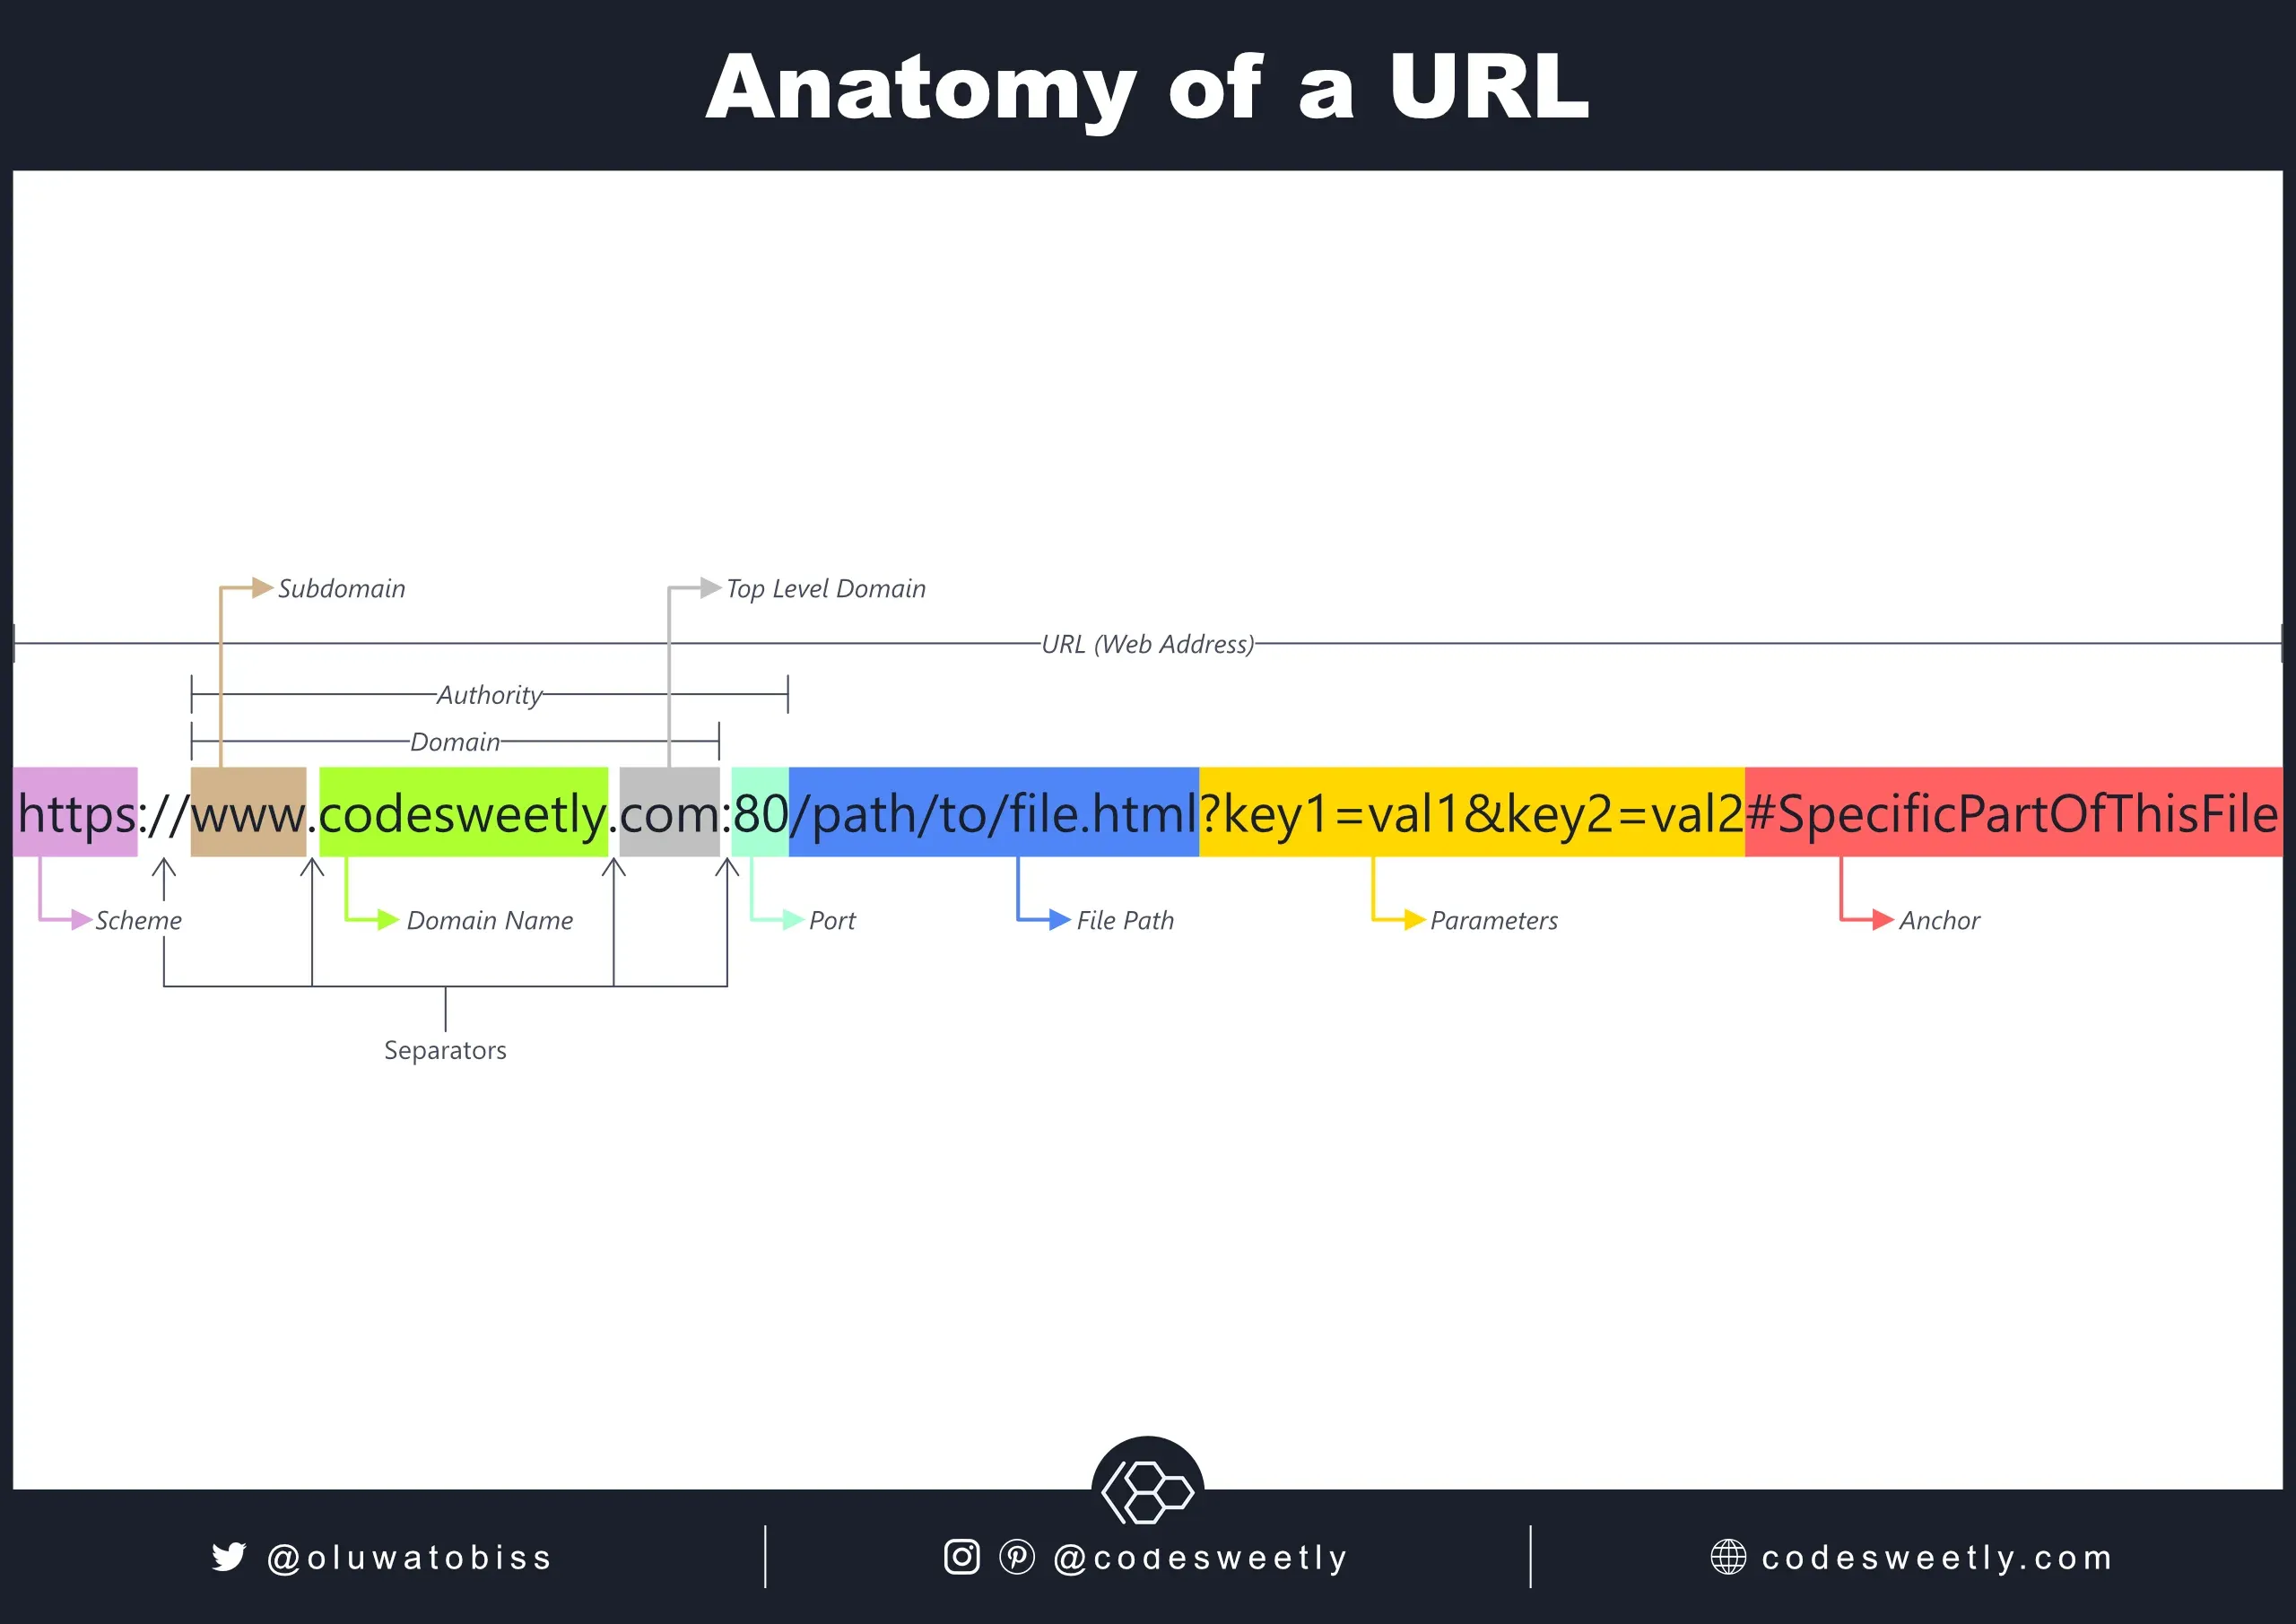
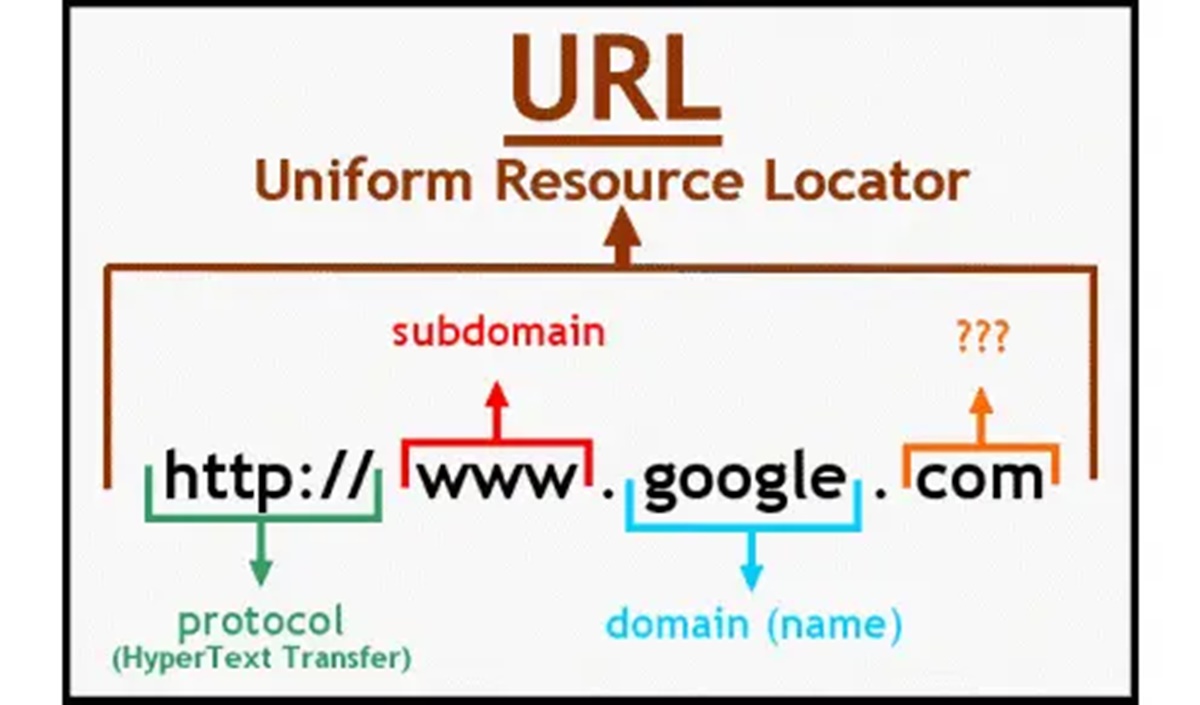
When you're poking around at web applications for security research or just trying to find specific content, knowing how URL structures work is useful. One of the simplest operators in any search engine toolkit is inurl:, and pairing it with something like id can surface pages you wouldn't normally find through regular browsing. The inurl: operator tells a search engine to return only results where your specified term appears inside the URL string. It's a native Google search operator that's been around since the early 2000s. When you type inurl:id into Google, you're asking it to scan the index for any page where the literal text "id" shows up between the domain and the file extension. That's it. No fancy syntax. No special tools required. Here's how it actually functions under the hood. Search engines crawl and index the raw HTML of billions of pages. They store metadata about each page, including the URL. The inurl operator acts as a filter on that stored URL field. When you search for inurl:users id, Google looks for URLs containing both words. When you search inurl:/id/, it looks for the forward-slash pattern around the term, which narrows results significantly.
I remember the first time I actually used this in a real engagement. It was 2019, and I was doing reconnaissance on a mid-size e-commerce platform for a client. I ran inurl:product id and immediately found about forty thousand indexed product pages. Not interesting by itself. But then I tried inurl:product id 0 and inurl:product id -1. Those returned zero results, which told me the application wasn't doing proper input validation on the product ID parameter. Pages with negative or zero IDs should either redirect or return a proper 404, not vanish from existence. That small discovery led to a broader investigation into mass assignment vulnerabilities on their checkout flow. I spent about three hours on that one engagement instead of the two weeks I was initially expecting. The practical syntax breaks down pretty simply. You combine it with other operators to tighten results. inurl:id filetype:pdf finds PDF documents with "id" in the path. inurl:id intitle:"admin" pulls together pages where both conditions are true simultaneously. The AND logic is implicit between operators, which people sometimes miss and end up running redundant searches. There are limitations you need to account for. Google doesn't index every URL that exists. If a page is blocked by robots.txt, buried behind authentication, or tagged with noindex, it won't show up regardless of your operator combination. I've wasted hours on search queries that looked promising only to discover the targeting site had a strict noindex policy on all dynamic pages. The fix was straightforward — I switched to using the site: operator in combination, like site:example.com inurl:id, which constrains results to only what Google has actually crawled from that domain. That typically cuts noise by about seventy percent on most sites.
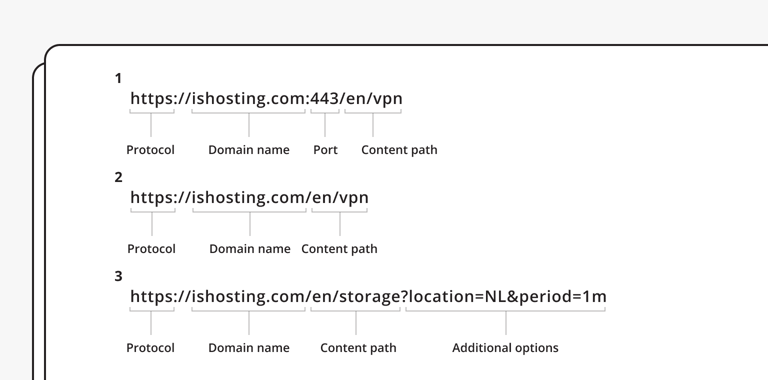
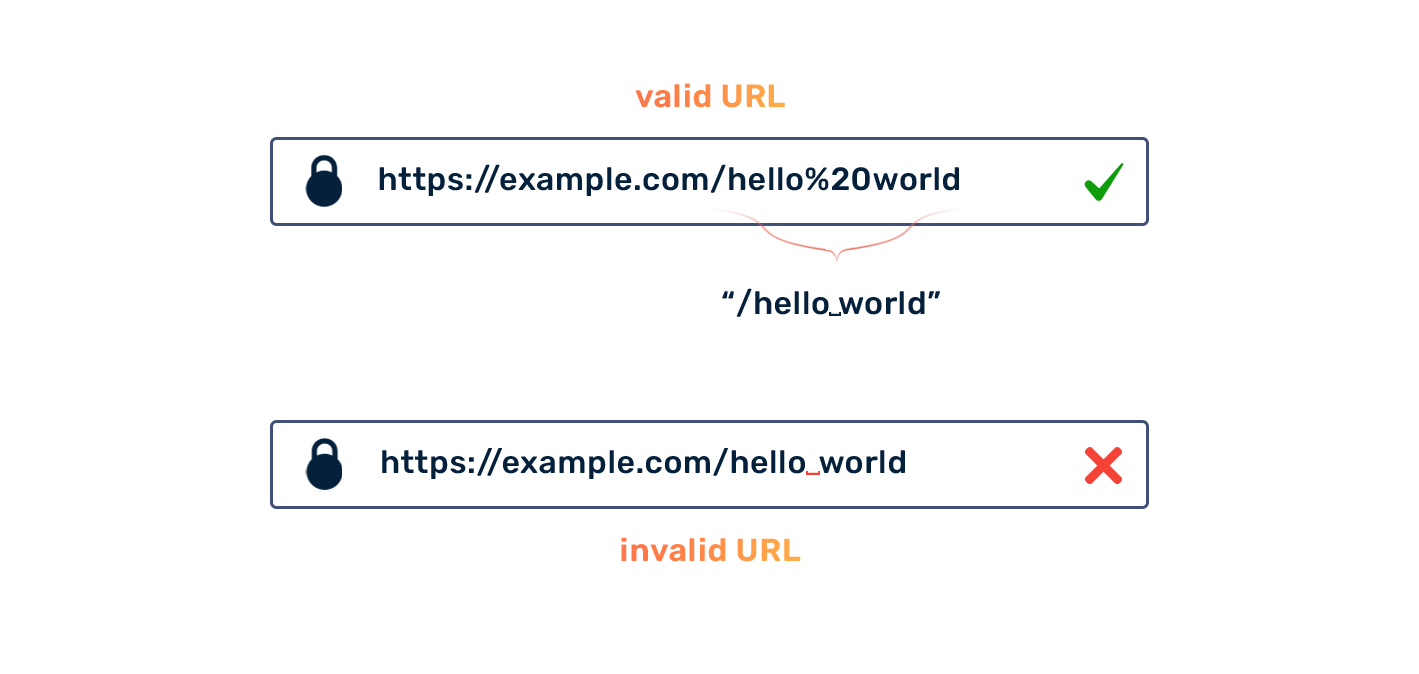
Another thing beginners overlook is URL encoding. Sometimes the parameter you're looking for gets encoded in the live URL. inurl:id won't match inurl%3Aid or any encoded variant. If you're hunting for specific patterns on a site that heavily encodes its parameters, you'll need to inspect the actual network requests, usually through browser developer tools or a proxy like Burp Suite, rather than relying on search engine operators alone. For people doing legitimate security research, here's the workflow I use. First, define the target domain. Run a broad site:target.com inurl:id to map the surface area. Second, look for patterns — are there common path structures like /api/v1/id/ or /user/profile?id=? Those predictable patterns are where injection flaws tend to hide. Third, test the identified endpoints methodically. Don't throw payloads at everything. Pick the ones that look like they handle user input and work through them systematically. A few things that trip people up constantly. First, inurl is case-sensitive in how Google processes it on the surface, but the underlying index usually normalizes to lowercase. Second, you can't use wildcards with inurl in the way you might expect. inurl:*.html doesn't work. You have to rely on the literal string match. Third, the operator only searches the URL path, not query parameters in all cases. Google has historically been inconsistent about whether it indexes query strings for the inurl operator, which is why combining it with intext: or just searching the full URL manually through tools is often more reliable.
Get the Full Details
If you're working with a specific platform or need to automate the discovery process, there are tools that wrap around search operators. Subfinder, Amass, and theHarvester can enumerate subdomains and paths. FOCA is useful for metadata extraction from documents. But none of them replace understanding the basics of how URLs are structured and how search operators filter results. The manual approach takes longer initially but gives you better situational awareness. The bottom line is that inurl:id and similar operator combinations are a starting point, not an endpoint. They reveal structure. They show you what the application author considered public-facing. From there, the real work begins — understanding the logic behind those URLs and testing whether the server handles them correctly when you deviate from the expected input patterns.