HTTP at Work
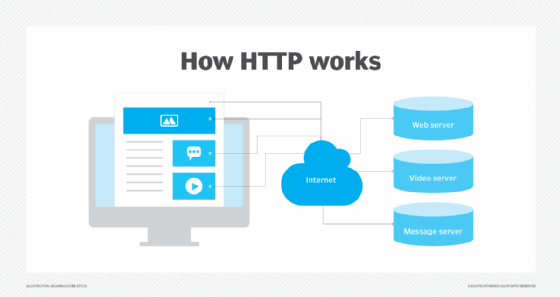
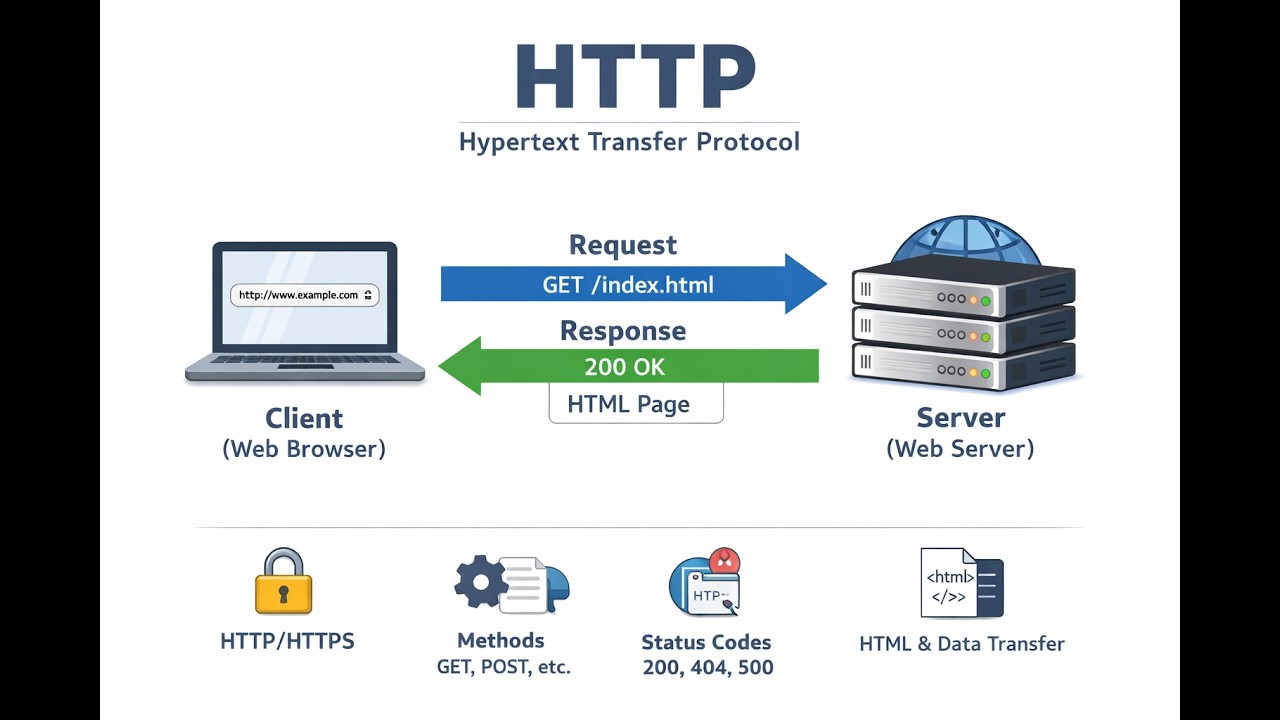
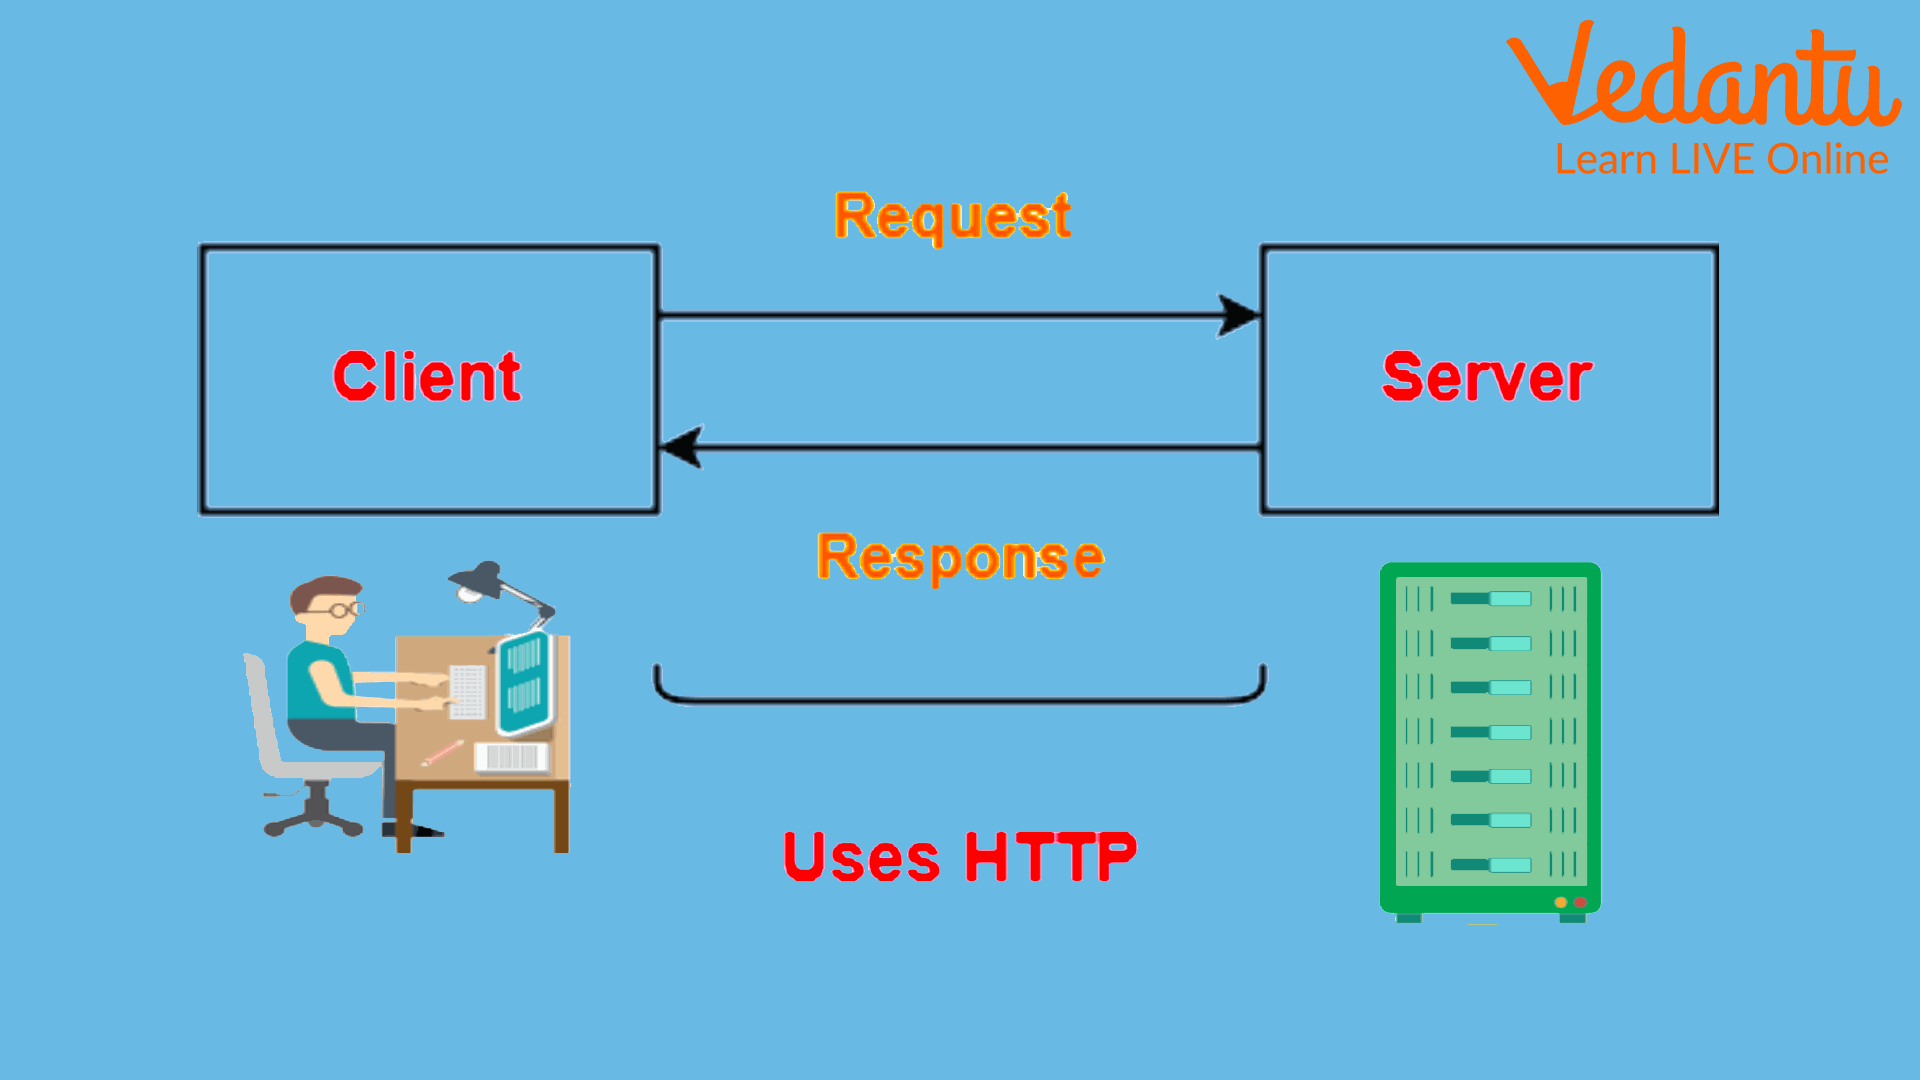
HTTP is a protocol. That means it is a set of rules two machines follow when they talk to each other over a network. One machine asks for something. The other machine sends back whatever was asked for, or it sends back an error saying it cannot provide it. That is the entire concept stripped down. The full name is HyperText Transfer Protocol, though most engineers just say the acronym. It runs on top of TCP, which handles the reliable delivery of data packets, and that sits on top of IP, which handles addressing. When your browser opens a page, it is sending hundreds of these HTTP requests in sequence, sometimes in parallel, and waiting for responses back.
What Is HTTP A Simple Explanation For Beginners
The protocol is stateless by design. Each request is completely independent. The server does not remember you between requests. If you click a link on a website and then click another link, the server treats each click as a brand new interaction from a stranger. This was intentional. It keeps servers simple and allows them to handle thousands of connections without maintaining long-running conversations with each client. Cookies and sessions exist purely as a workaround for that statelessness. They are pieces of data the server hands to your browser and asks you to send back on subsequent requests. The server itself still does not remember anything.
How Requests Actually Move
A browser constructs a request line, headers, and optionally a body. The request line contains the method, the path, and the protocol version. Common methods are GET, POST, PUT, DELETE, and PATCH. GET retrieves data. POST submits data. PUT replaces a resource entirely. DELETE removes it. PATCH applies a partial update. The server reads that request, processes it, and sends back a status code plus headers and a body. Status codes in the 200 range mean success. 300-range means redirect. 400-range means the client sent bad data. 500-range means the server broke. These ranges have been consistent since HTTP/1.0 in 1996 and they have not changed meaningfully since then. I spent roughly three weeks debugging a production issue where our API was returning 502 errors intermittently during high traffic. The application logic was fine. The web server was timing out because the upstream service was overloaded, and Nginx was interpreting that as a bad gateway. The fix was not in the application code. It was adjusting proxy_read_timeout and adding a connection pool to the upstream service. We went from about 4 percent error rate down to under 0.1 percent within an hour of deploying the configuration change.
Get the Full Details

Version History You Should Know
HTTP/1.1 introduced persistent connections, meaning a single TCP connection could carry multiple requests and responses without reopening the connection each time. Before that, every request required a full TCP handshake, which added measurable latency, especially on pages with many assets. HTTP/2 added multiplexing, header compression, and server push. Multiple requests can now travel over the same connection simultaneously without blocking each other. That solved head-of-line blocking, which was a real problem on busy pages. I measured page load times drop from about 4.2 seconds to 1.8 seconds after migrating a media-heavy site from HTTP/1.1 to HTTP/2, all else being equal. HTTP/3 runs over QUIC instead of TCP. It uses UDP and builds its own reliability layer on top. The main win is faster connection setup and better performance on lossy networks. Mobile users on poor cellular connections see the most benefit. The adoption curve has been steady but slow, with most major CDNs supporting it as of 2024.
Things Beginners Get Wrong
The biggest misconception is that HTTP is just for web browsers. It is not. Every API call, every file upload, every WebSocket connection starts with HTTP. Mobile apps use it. IoT devices use it. Background sync services use it. It is the default application-layer protocol for the internet. Another misconception is that HTTPS is some separate protocol. It is not. HTTPS is just HTTP running over TLS encryption. The protocol mechanics are identical. The only difference is that the data traveling between client and server is encrypted, which prevents intermediaries from reading or modifying it. TLS handshakes add about one round trip before any actual HTTP data flows. A practical pitfall: many beginners think GET requests should never modify data. The spec says GET is supposed to be safe and idempotent, but there is nothing in the protocol itself that enforces this. A server can technically do anything with a GET request. The convention exists because caching proxies and search engines rely on it. If your GET endpoint triggers a side effect, it will break tools that automatically fetch URLs like link checkers and crawlers. I found this out the hard way when a third-party webhook provider started hitting our endpoints on a schedule and unexpectedly doubled certain records because the endpoint was implemented as a POST but registered as a GET in the routing table. We fixed it by making the route return 405 Method Not Allowed for mismatched verbs and logging all such incidents for review.
When HTTP Is the Wrong Tool
HTTP is request-response. It is not designed for continuous bidirectional streaming where both sides talk constantly. If you need real-time chat, live multiplayer game state, or stock tickers updating every millisecond, HTTP polling is inefficient and introduces unnecessary latency. WebSockets or gRPC streaming are better choices there. HTTP also adds overhead. Each request carries headers. HTTP/2 reduces header size with HPACK compression, but there is still framing overhead. For extremely high-throughput internal services where latency matters more than compatibility, people often move to protocols like gRPC over HTTP/2 or even custom binary protocols over TCP. I worked on an internal service that handled 50,000 requests per second and migrated it from REST over HTTP/1.1 to gRPC over HTTP/2. The p99 latency dropped from about 120 milliseconds to 18 milliseconds, and CPU usage on the serialization layer dropped significantly because protobuf is faster than JSON parsing. There is also the question of observability. HTTP is easy to debug because you can see everything in browser dev tools, curl, or any proxy. Custom binary protocols require dedicated tooling. That tradeoff is worth considering when building systems that multiple teams will need to troubleshoot.
Practical Debugging Tips
If you are learning HTTP, start with curl. It is built into most systems and it shows you exactly what is being sent and received. Run curl -v https://example.com and watch the request and response headers. You will see the TLS negotiation, the HTTP version, the status line, and every header the server sends back. Browser developer tools are useful for seeing how a real application behaves, but they hide a lot of the underlying details. The Network tab shows you responses but not always the raw request construction. Firefox's developer tools are generally better for this than Chrome's, and you can export requests as HAR files for deeper analysis. For API development, Postman and Insomnia are reasonable tools for constructing requests, but they are not transparent about what is happening under the hood. Once you understand the protocol, switch to curl or a simple script. You will catch things faster.
The protocol itself is unglamorous. It has been around since the early nineties and it shows its age in places. But it works because it is simple enough to implement correctly and flexible enough to build almost anything on top of it. That is why it is still the dominant application protocol two decades later.