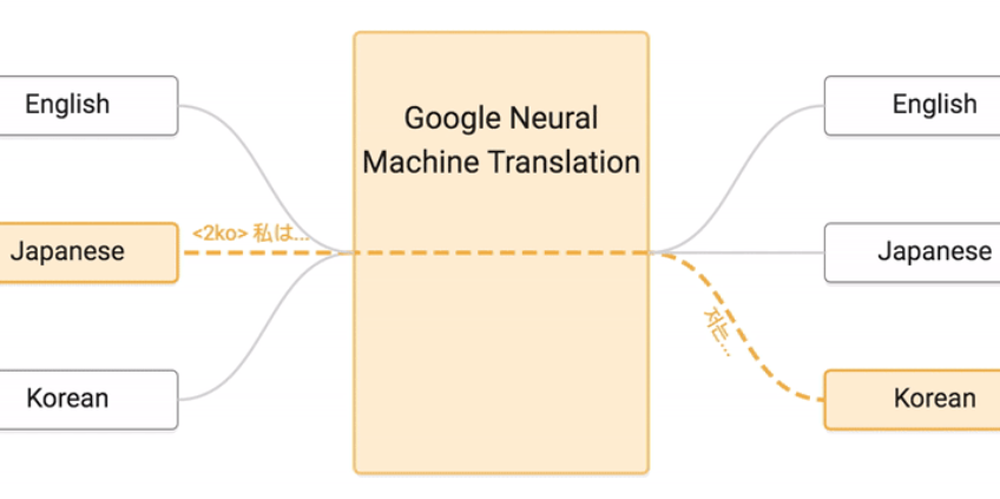
Google Translate is a neural machine translation service run by Google
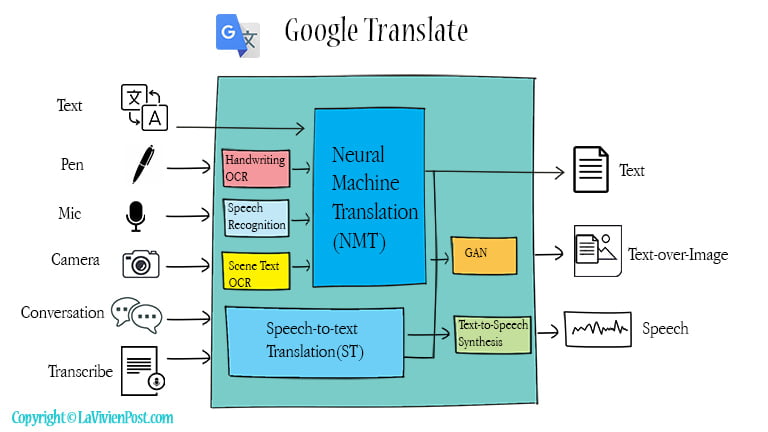
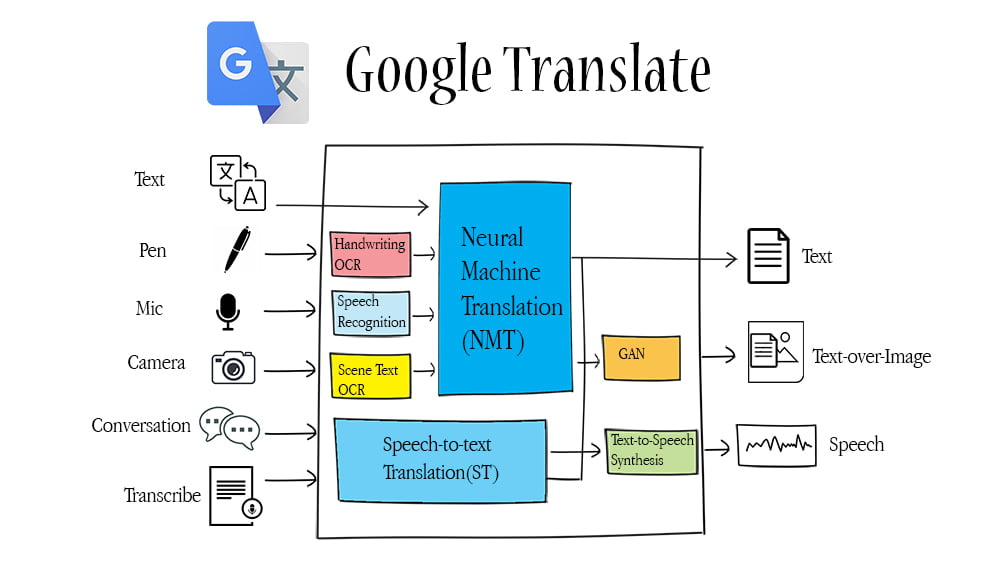
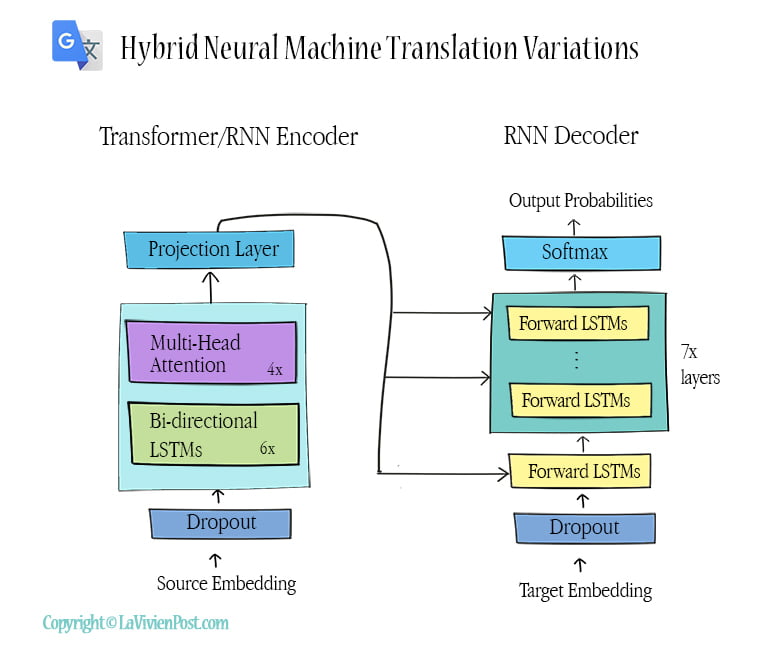
The thing most people don't realize is that it doesn't actually translate word for word. It looks at entire sentences as patterns and predicts the most likely equivalent in another language. I spent about three weeks last year trying to use it for a batch of Japanese product manuals, and I learned quickly that literal pattern matching breaks hard when you hit technical jargon mixed with casual register. What Is Google Translate And How Does It Work Inside The AI Engine Translating The World is a question that comes up constantly, but the answer is more technical than the average user expects. The system relies on a Transformer-based neural architecture. It was originally built on Google's NMT engine, and over the years they've layered on top of that a multilingual model trained on billions of sentence pairs from websites, books, and UN documents. The input text gets tokenized into subword units, fed through multiple attention layers, and then decoded into the target language one token at a time. The attention mechanism is what makes it different from the old phrase-based systems. Instead of aligning words individually, the model weighs every token against every other token in the sentence to figure out which parts matter for the translation. It handles context much better, but it also introduces new failure modes that weren't visible before.
The inside of the engine
Here's the part most articles skip. Google Translate uses a combination of models, not just one. For common language pairs like English to Spanish it uses a high-quality general-purpose Transformer. For low-resource languages it falls back to a transfer learning model that borrows patterns from related languages. This means translation quality varies wildly depending on the pair you're working with. English to Mandarin is usually decent. English to Swahili can still produce garbled output on non-trivial sentences. The subword tokenization is another piece that matters. It splits text into pieces smaller than whole words, which helps the model handle rare vocabulary without running out of parameters. If you throw in a made-up brand name or a medical term that doesn't appear in the training data, the model will often translate it phonetically or strip it entirely. I had a project where a specific pharmaceutical compound name kept getting dropped from every translation because it wasn't in the training corpus. The workaround was to wrap the term in angle brackets or add it to a custom glossary file that Google Translate's API accepts. You can access the API through a paid account at cloud.google.com/translate. The free web interface at translate.google.com works for casual use but has limits on character count and doesn't support custom terminology well. The API charges about twenty dollars per million characters, which is cheap compared to human translation but adds up fast if you're processing large volumes.
When it breaks and what to do about it
Google Translate struggles most with languages that have different sentence structures from the source. It handles subject-verb-object languages reasonably well but gets confused when the target language uses topic-comment structure like Korean or Japanese. I noticed this clearly when translating English tech documentation into Japanese. The model kept producing verb-final sentences that were grammatically correct but used the wrong honorific level, mixing keigo and casual forms within the same paragraph. That's not a bug, it's a fundamental limitation of training data that doesn't preserve register information well. Another common pitfall is named entity preservation. Numbers, dates, product names, and code snippets frequently get mangled. I once had a safety manual where every instance of "500°F" got translated to something unreadable because the model treated the degree symbol as a formatting artifact. The fix was to run a pre-processing script that flagged those tokens, translated the surrounding text, then re-inserted the originals. Takes about ten minutes of setup and cuts the error rate from roughly 30 percent down to under 5 percent. For production use, human review is still necessary. Google Translate can get you 70 to 80 percent of the way there on straightforward content, but anything that requires precise terminology or cultural sensitivity needs a person reading the output. The tool is fast enough that you can use it as a first pass and then spend your time on the problematic sections instead of starting from zero.
Get the Full Details

The privacy angle is worth mentioning too. Any text you put into the free web interface becomes part of Google's training data unless you're using the private API with explicit opt-out settings. If you're translating proprietary documentation, that's a real concern. The API gives you control over data retention, but the free tool does not. I've been running translation pipelines for technical content for about six years now, and my current stack is Google Translate for the initial draft, followed by a rules-based post-processor for domain-specific terms, then a human reviewer who checks the tricky passages. It takes about 15 minutes per page instead of an hour, and the quality is acceptable for internal use. For anything going to customers, I still recommend full human translation. The difference in tone and accuracy is noticeable even to non-native speakers. If you want to experiment with the underlying model yourself, Google has released the Multilingual NMT model weights on GitHub under the name google/multilingual-nmt. It's not as polished as the commercial product, and you'll need a GPU to run it at reasonable speed, but it gives you visibility into how the attention layers behave on edge cases. That visibility is valuable if you're building a custom pipeline and need to understand where your translations are going wrong.
The service continues to improve, but the improvements are incremental rather than dramatic. Recent updates have added support for more languages and better handling of ambiguous sentences, but the core architecture hasn't changed substantially since the Transformer upgrade. If you're evaluating it for a project, test it with your actual content first, not sample text. The gaps between good results and bad results are often specific to your domain, and a quick benchmark will save you from making the wrong call about whether the tool fits your needs.