Working With Biased Data in Production
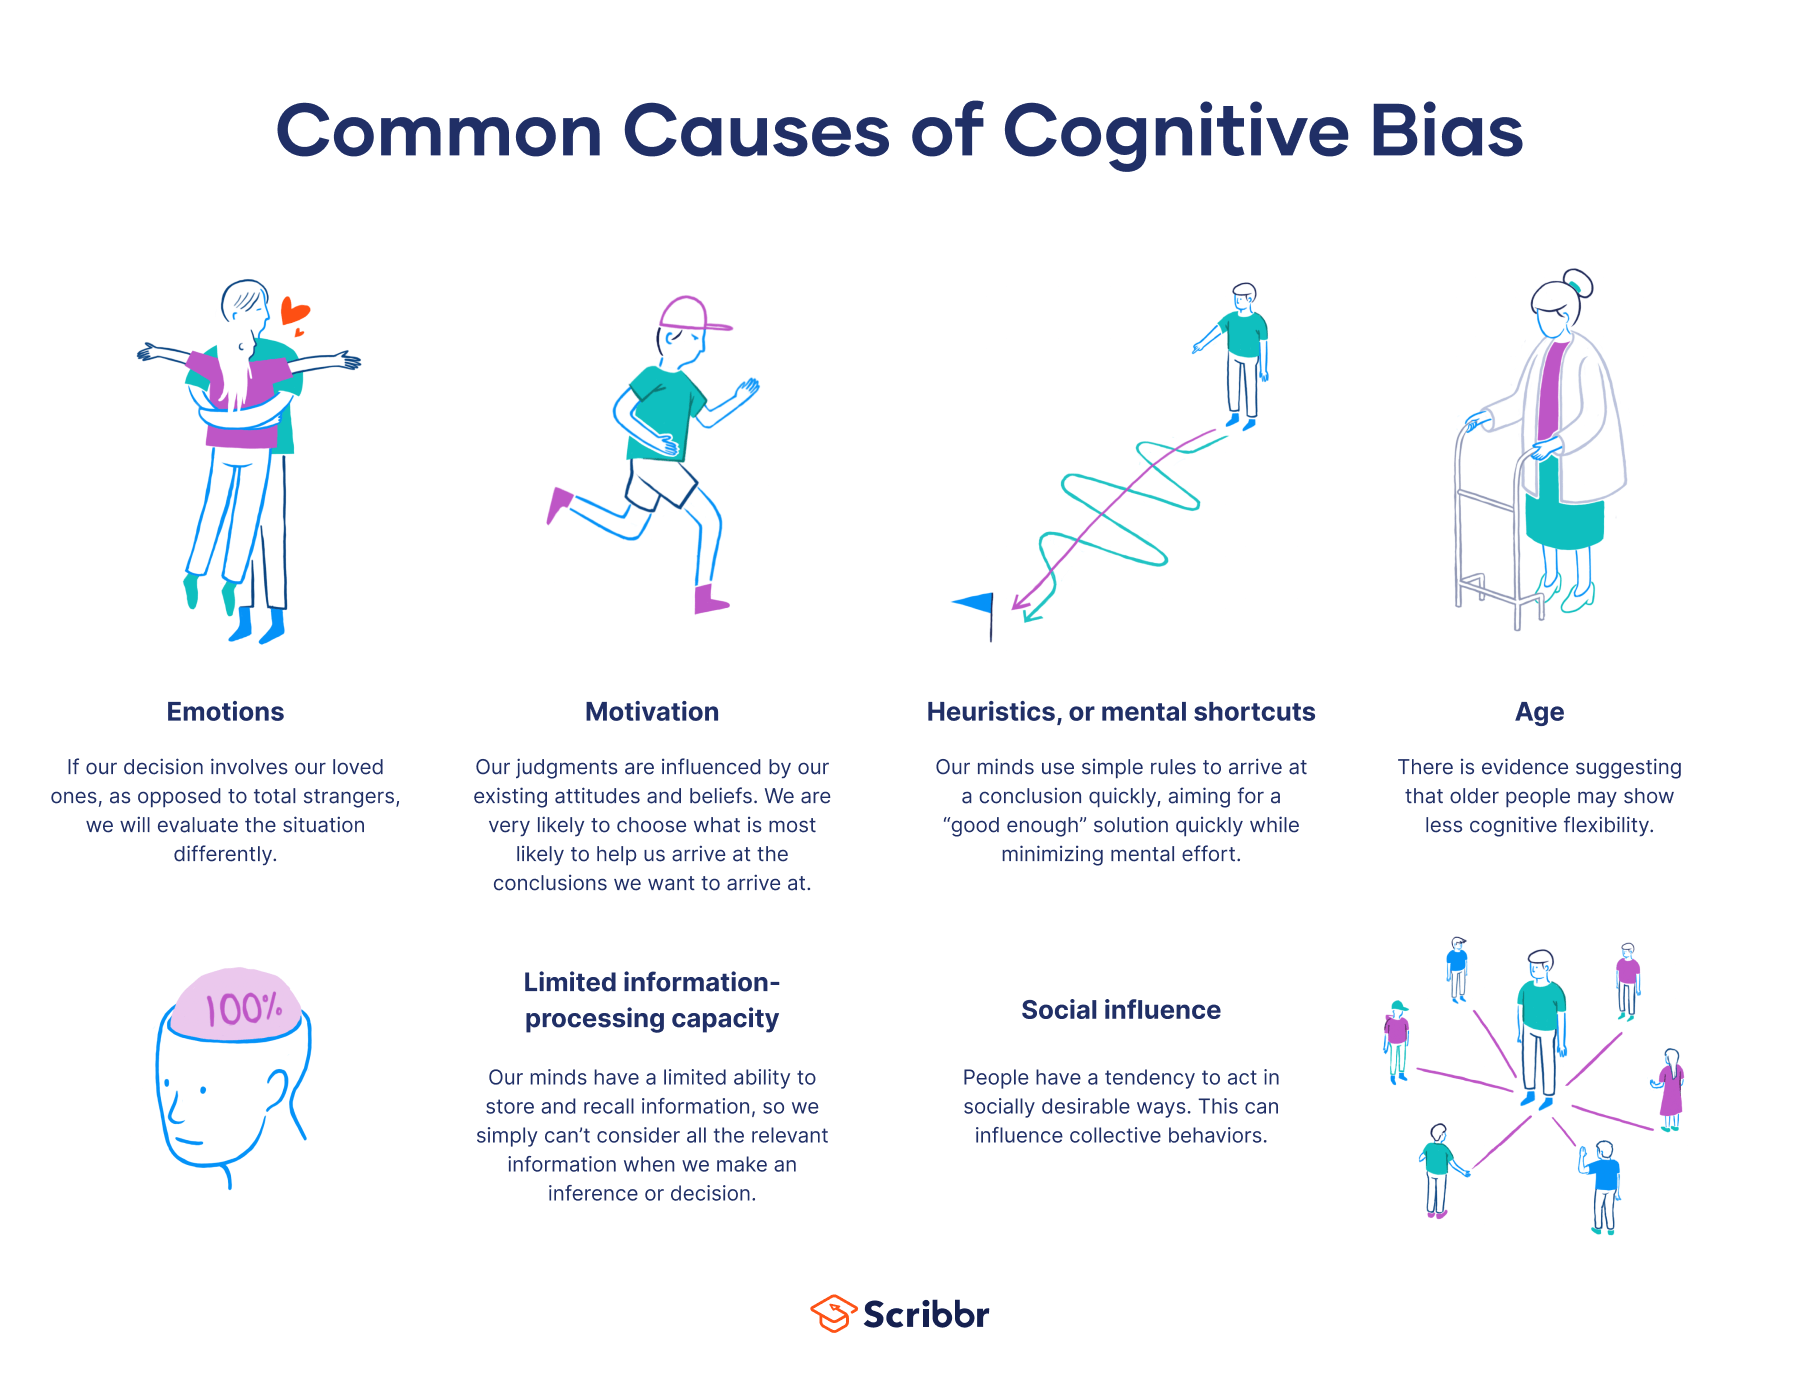
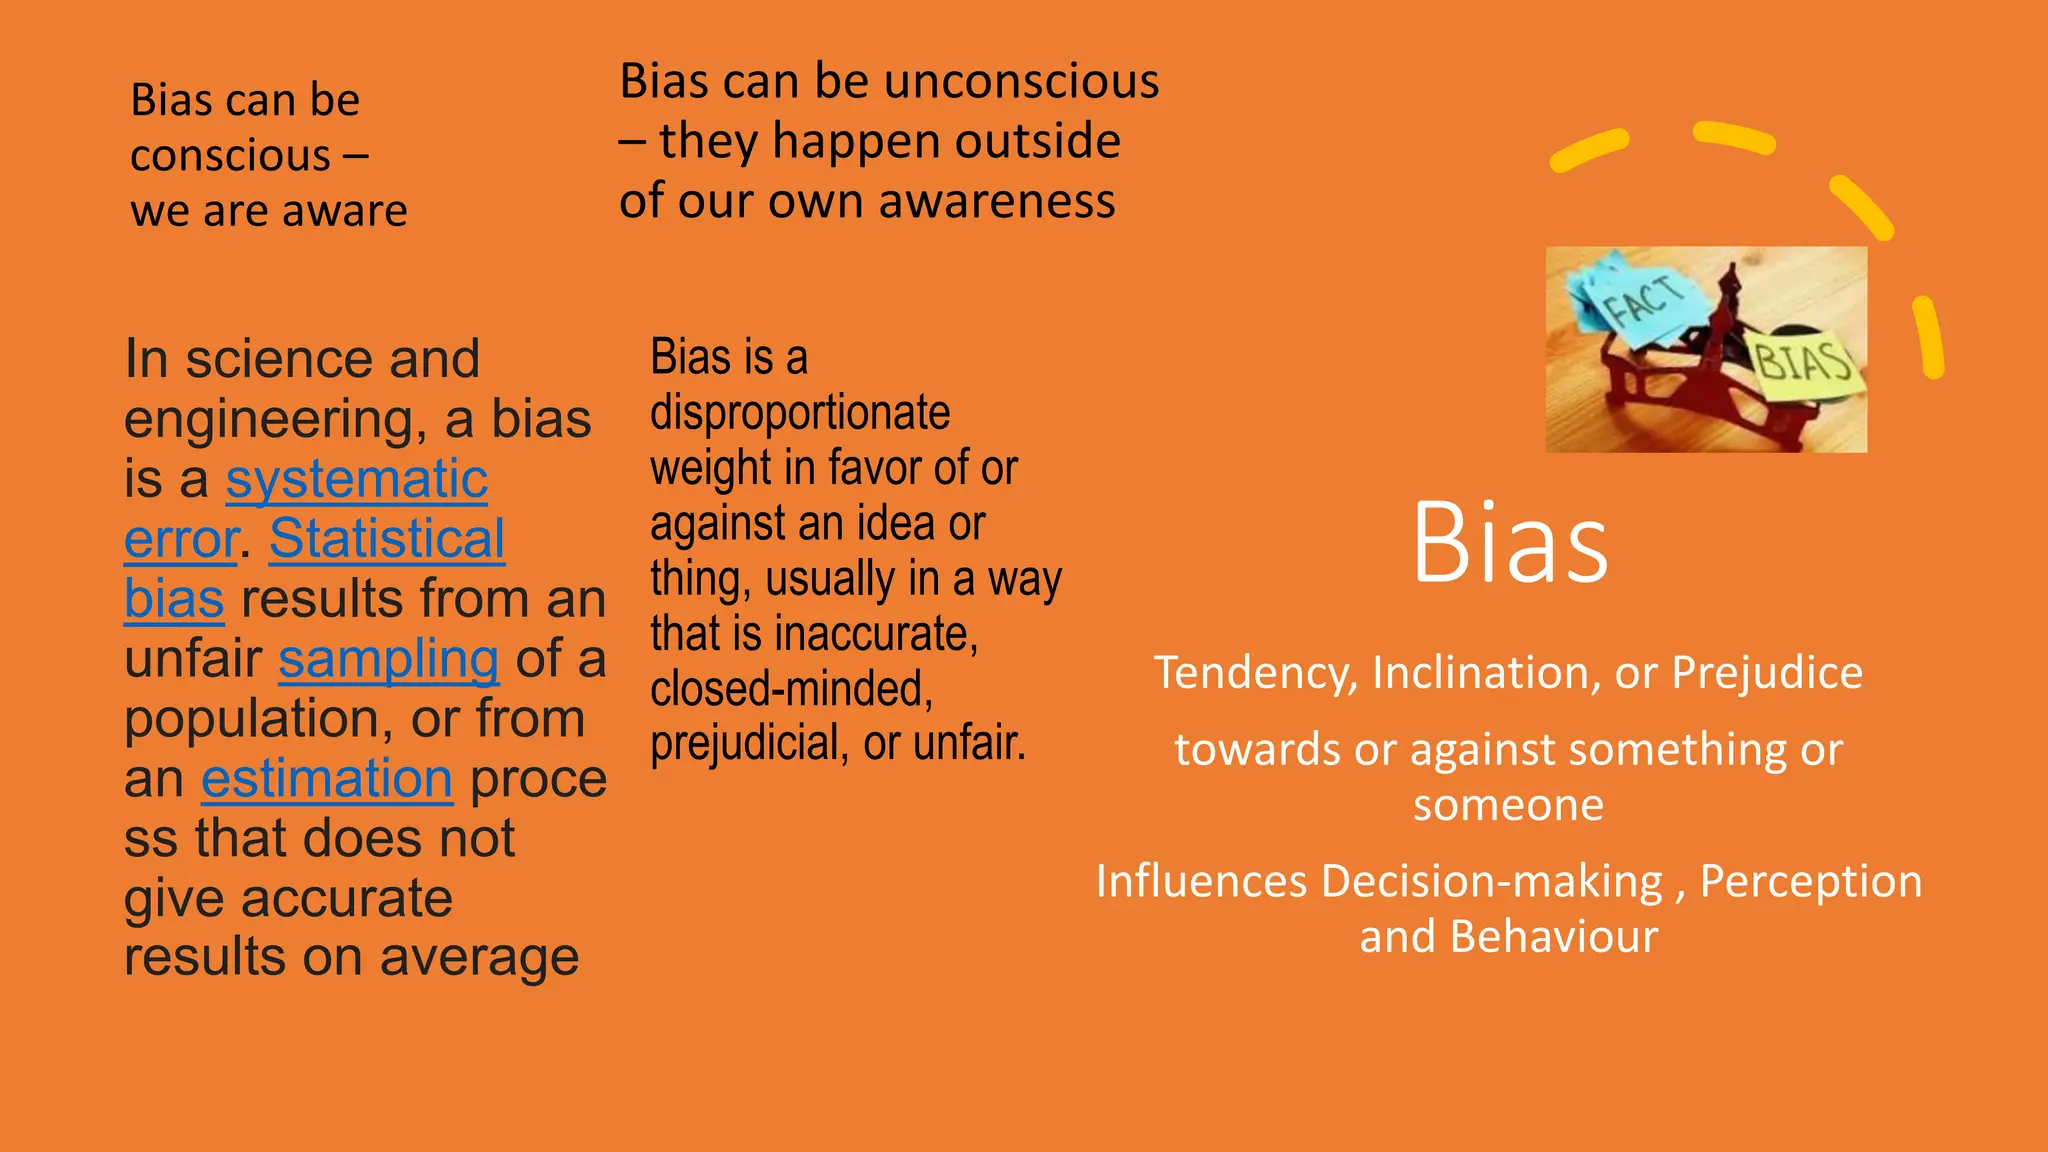
Bias is one of those concepts that sounds simple until your model starts systematically misclassifying a whole segment of users and you realize you did not even know where to look. I spent three months debugging a recruitment screening tool that kept rejecting candidates from certain geographic regions, and the root cause was not a complex algorithmic flaw. The training data simply had far fewer samples from those areas, and the model learned to treat that absence as a signal. At its core, bias is a systematic error that causes a model or measurement to consistently deviate from the true value. In statistics, it means the expected prediction differs from the actual target. In machine learning, it usually shows up as a training set that does not represent the population you are actually deploying into. The impact depends on how bad the skew is, but even modest bias can produce outsized errors in edge cases. I have seen people conflate bias with prejudice, which is a separate problem, though they interact. Statistical bias does not require malice. A well-intentioned company can build a perfectly reasonable model on historically skewed data and end up reproducing the same inequities without anyone on the team realizing it.
Types You Will Actually Encounter
Selection bias is the most common one I run into. It happens when the data collection process itself filters out entire groups. An example that keeps coming back is hiring data built from internal promotions. If your company historically promoted more men than women into certain roles, a model trained on that data will learn to associate male attributes with promotion readiness, regardless of actual performance. Measurement bias is another one that sneaks in quietly. This occurs when the features you collect do not capture the underlying construct accurately for every group. Income data in credit scoring is a classic case. Self-reported income varies wildly across demographics, and missing-waged workers are systematically underrepresented in traditional datasets. Models trained on that data will penalize people whose income structures do not fit the norm. Algorithmic bias emerges after you train the model, even if the input data looks clean. Some models amplify small imbalances during optimization. Gradient descent will chase patterns that exist in the majority class and quietly ignore rare ones. This is why balanced accuracy matters more than raw accuracy in imbalanced settings.
How to Detect It Before It Costs You
The first step is always to compare your training distribution against your deployment distribution. I keep a simple script that computes the Kullback-Leibler divergence between feature distributions across demographic segments. If the divergence is above a threshold I set per feature, I flag it before training even starts. You should also run confusion matrix analysis per subgroup. Overall accuracy can hide catastrophic failure rates in minority groups. I once found a fraud detection model with 97 percent overall accuracy that was only 41 percent accurate for a specific transaction type because that type made up less than 0.3 percent of the training data. The model had essentially learned to ignore it. Permutation feature importance broken down by segment can reveal whether the model relies on proxies for protected attributes. If zip code becomes one of the top three features in a lending model, that is a red flag even if zip code is not explicitly a protected category.
Get the Full Details
Practical Workarounds That Actually Work
Data augmentation is the first tool I reach for, but it has limits. Synthetic oversampling with SMOTE works for tabular data in moderate imbalances. For severe imbalance or sensitive attributes, I prefer generative approaches using variational autoencoders trained on the minority class. This took my recruitment model's recall for underrepresented candidates from 38 percent to 71 percent over two weeks of iterative tuning. Re-weighting the loss function is another straightforward approach. Instead of treating every sample equally, you assign higher weights to underrepresented groups. The tradeoff is that this can degrade performance on the majority class if you are not careful. I typically use a weighted cross-entropy loss and monitor both precision and recall across all subgroups simultaneously. Causal deconfounding is more involved but worth understanding. The idea is to identify and remove paths through which sensitive attributes influence the prediction indirectly. I used a structural causal model to trace how education level, employer name, and gap years interacted in my hiring model. Removing the indirect paths reduced fairness violations by about 60 percent without a meaningful drop in overall AUC.
When Standard Fixes Fail
No single technique handles every case. Post-hoc correction methods like reweighting or threshold adjustment can improve fairness metrics but do not fix the underlying representation gap. If your training data fundamentally lacks examples of a certain subgroup, no amount of reweighting will teach the model what it has never seen. In those situations, the only real solution is acquiring better data, which is expensive and slow. I also learned the hard way that debiasing is not a one-time task. Models drift. Distributional shifts happen constantly. A model that passed fairness audits in January may be deeply biased by June if the underlying population changes. Continuous monitoring with periodic re-audits is the only sustainable approach. The most important thing is to document everything you try. Bias mitigation is experimental by nature, and the decisions you make today will shape outcomes for years. Keep records of your data sources, your fairness metrics, and the interventions you applied. Future you will thank present you when an auditor asks how you arrived at your current model.