How Subscripts Actually Work Under the Hood
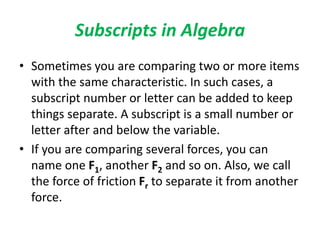
Most people think a subscript is just small text below the line. It's more than formatting. A subscript is a positional identifier that changes how a symbol is interpreted by the reader and by machines. In mathematics, it distinguishes elements within a set. In chemistry, it defines molecular composition. In computing, it's often the difference between a variable and a variable array. I spent three years debugging a physics simulation where half the errors traced back to subscript indexing mistakes. The compiler didn't complain because the code was syntactically valid. The issue was that I was referencing index 0 when the array was sized starting at 1. That tiny off-by-one shift cascaded through every calculation downstream. Took me two weeks to find it. You learn to be paranoid about subscripts early on.
What Is A Subscript The Tiny Code That Powers Math Science And Your Digital Life
The word itself comes from Latin subscriptus, meaning "written underneath." In technical writing, a subscript is a character rendered slightly below the normal baseline of a line of text. But the visual trick is only half the story. The real purpose is semantic distinction. Consider HO. The 2 isn't decorative. It tells you there are exactly two hydrogen atoms bonded to one oxygen atom. Remove that subscript and you've got HO, which is a completely different molecule. In math, x and x aren't two versions of the same x. They're distinct variables with separate values in a sequence or system of equations. In programming, subscripts become array indices. Python uses square brackets with zero-based indexing. JavaScript works the same way. Fortran starts arrays at 1 by default. This inconsistency has broken more production systems than most developers want to admit. When I moved a numerical model from a Fortran legacy codebase to a Python implementation, the first pass of results was entirely wrong because I hadn't adjusted the subscript offsets. The fix was adding a simple mapping layer: every Fortran index n maps to Python index n-1. It took about ten minutes once I caught it.
Chemistry isn't the only field that depends on this. Genetics uses subscript notation like BRCA1 and BRCA2 to label gene variants. Linguistics marks phonetic symbols with subscripts for diacritical features. Even your email client uses it when you write something like user+tag@mail.com — though that's technically an alias, not a subscript, the principle of using a modifier to distinguish instances is the same idea. The problem with subscripts is that digital rendering is inconsistent. HTML treats subscripts as a presentational element via the <sub> tag, but many screen readers either skip them entirely or pronounce them awkwardly. Accessibility is genuinely degraded in most web content. MathML was designed to fix this, and it does a better job, but browser support is still spotty outside of research and academic publishing environments. If you're working in LaTeX, subscripts are straightforward with the underscore character. f_x gives you f with a subscript x. For multi-character subscripts, you need curly braces: m_{ij} renders as m with ij as a grouped subscript. I've seen people write m_ij which only subscripts the i and leaves the j floating at baseline. This happens constantly in student papers and it's visually jarring once you know what to look for.
Get the Full Details

There's a nuance that beginners miss. Subscripts and superscripts aren't interchangeable in meaning even when they look similar. x² (x squared) and x (x subscript 2) are related visually but carry completely different mathematical operations. Confusing them in data entry or transcription is one of the most common errors in scientific computing. I once reviewed a dataset where someone had transcribed chemical formulas from a paper and accidentally used superscripts instead of subscripts for everything. The resulting compounds didn't exist in any database because the notation was technically invalid. The limitations are worth noting. Subscripts don't scale well in mobile interfaces. Small screens squeeze the text, and the subscript often becomes illegible or overlaps with the baseline. CSS has had a sub and sup font metric property for years, but few designers actually use it. Most just shrink the font size and hope for the best. The result is that subscript readability on phones is generally poor across the board. For anyone building tools that handle subscript input — whether it's a calculator app, a chemistry editor, or a math typesetting library — the practical takeaway is to normalize subscript representation internally regardless of how it enters the system. Accept <sub> tags, LaTeX underscores, Unicode subscript characters, and plain text approximations, then convert everything to a single canonical form before processing. This prevents the kind of silent data corruption I described earlier.
Unicode does include a dedicated subscript block (U+2080 through U+2089 for digits and a handful of letters like a, e, o, x), but most fonts don't include all of these glyphs. If you type a Unicode subscript character into a document and it displays as a blank box or a question mark, that's a font fallback issue, not an error in your content. Check your font stack. Switching to a font like Noto Sans or DejaVu often resolves it immediately. The bottom line is that subscripts are deceptively simple. They look like a typographic convenience but they carry real structural meaning across multiple disciplines. Getting them right matters more than most people realize, and getting them wrong produces errors that are extremely difficult to trace back to their source.