Setting Up A Reverse Proxy Without Losing Your Mind
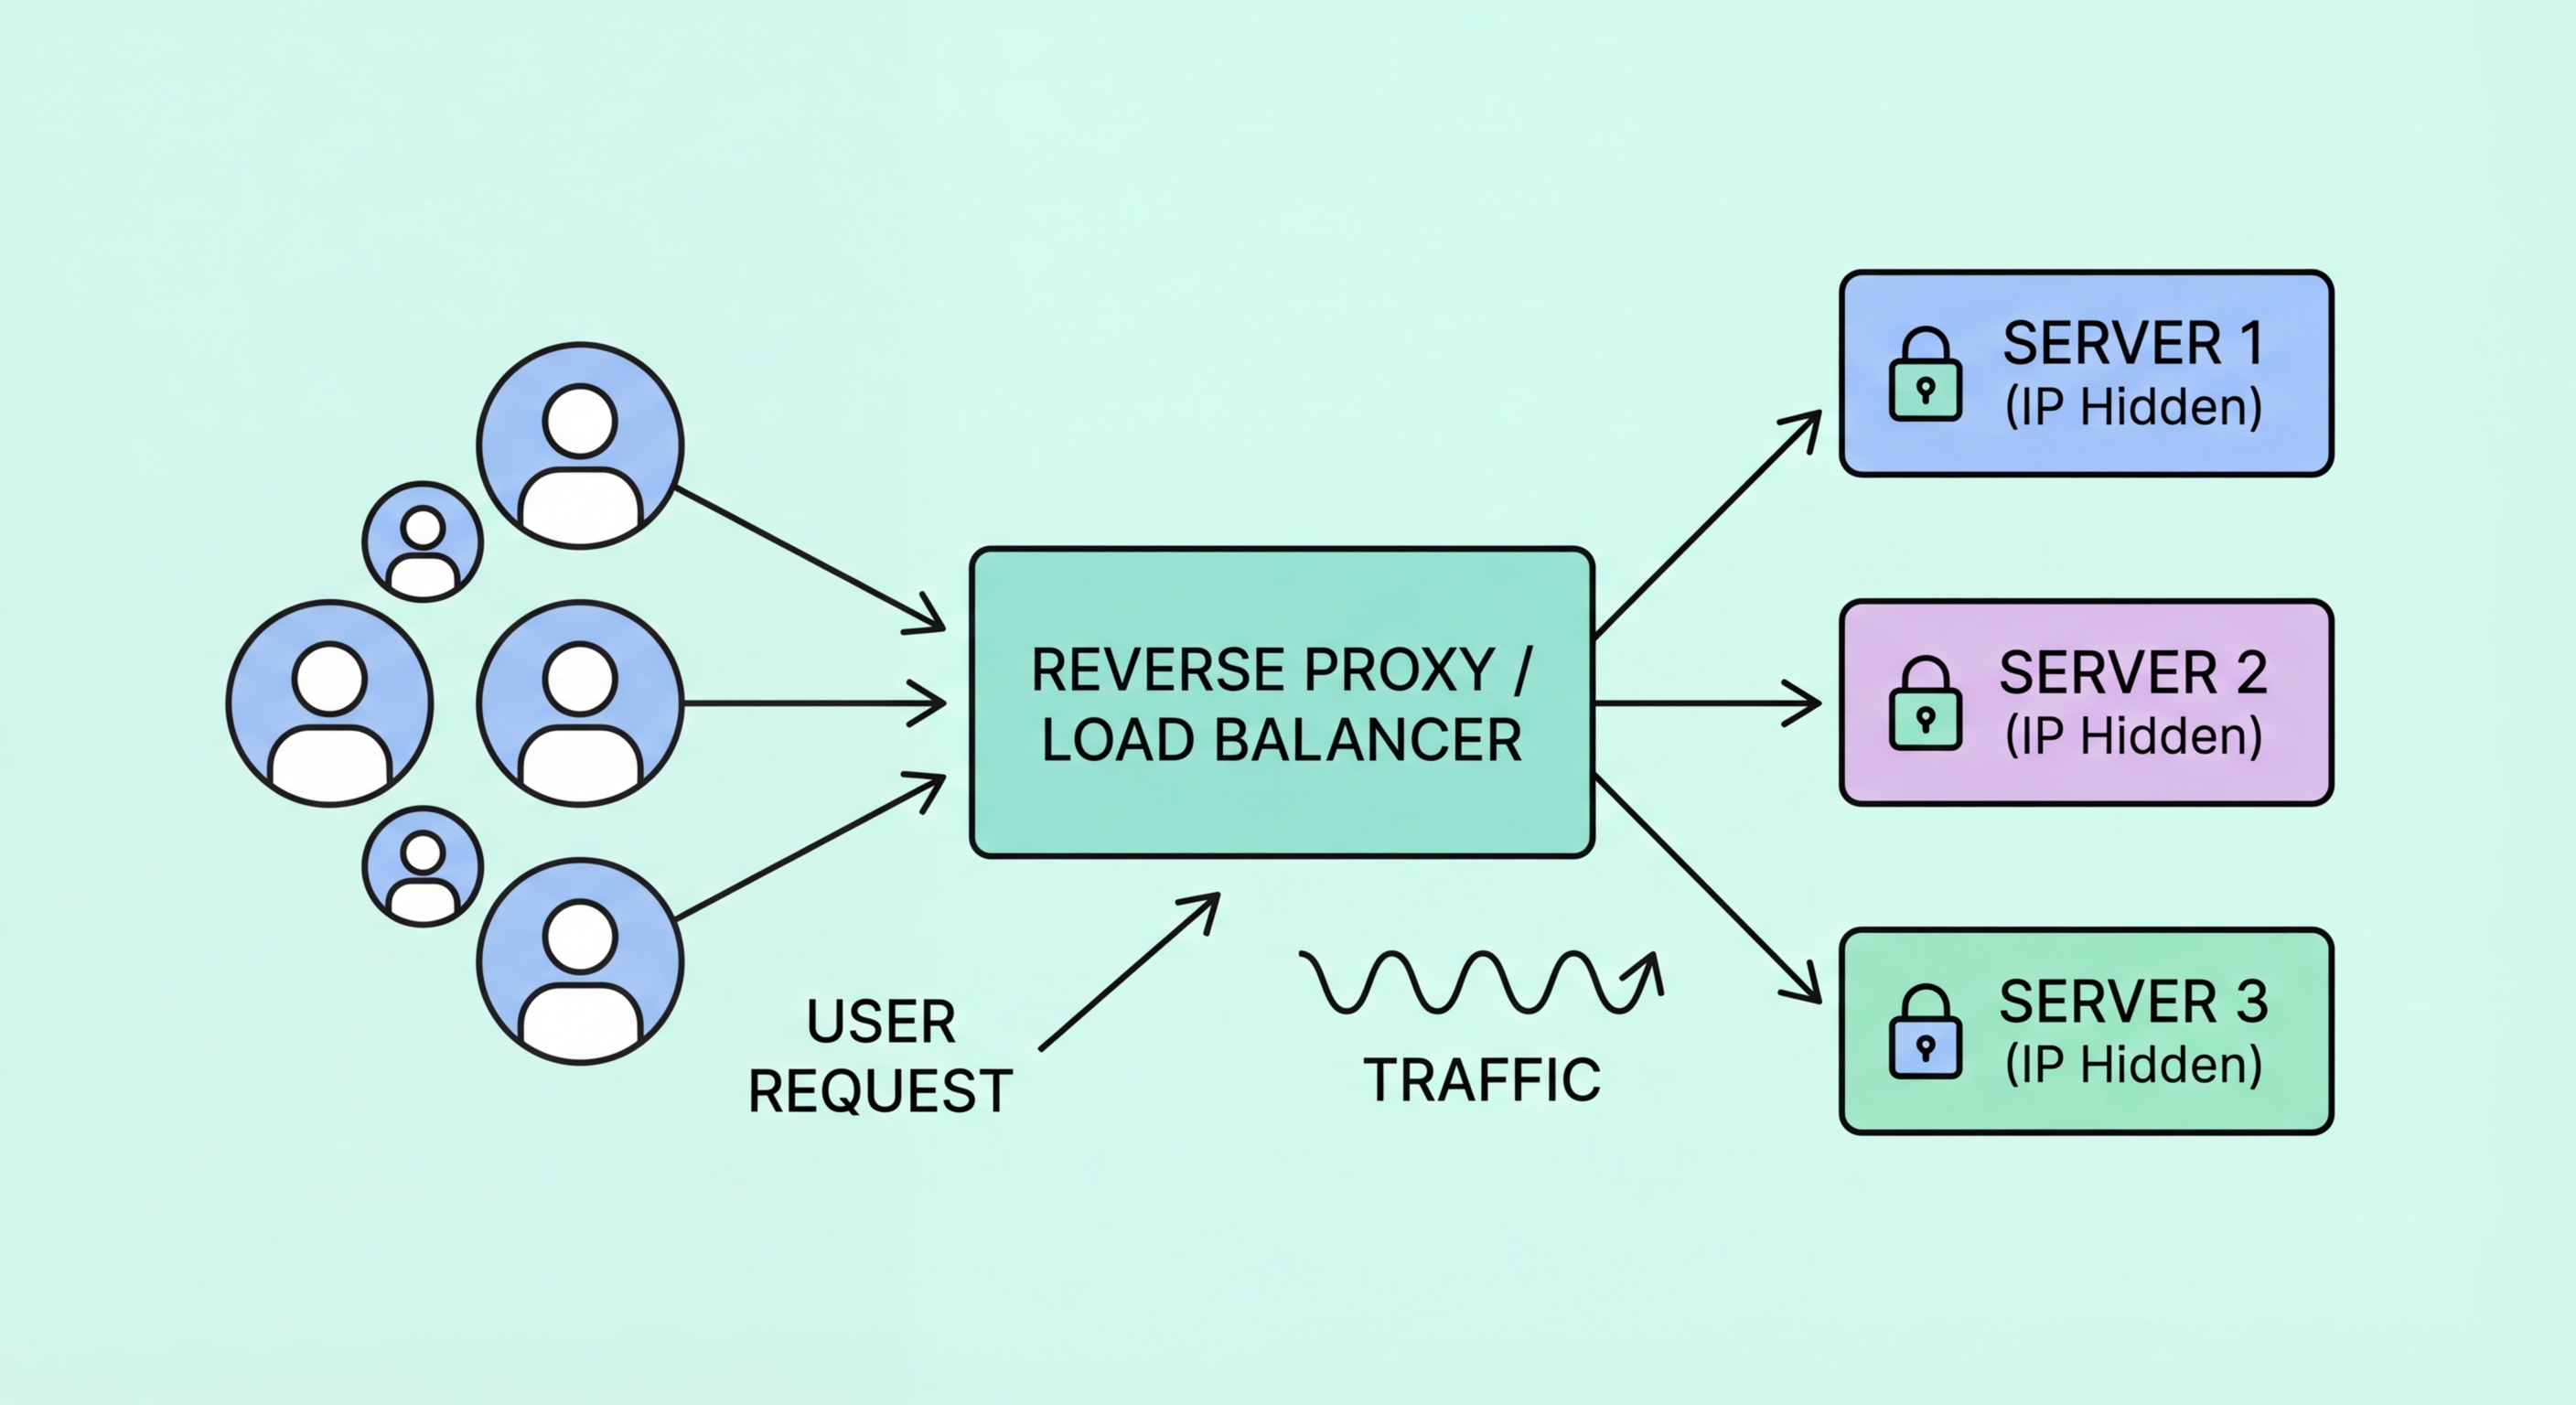
I spent three days debugging a production issue last year that turned out to be entirely my fault for not understanding how my reverse proxy was handling headers. I'd put Nginx in front of a Node app, routed traffic correctly, everything looked green. But the application behind it was making decisions based on the wrong client IP addresses. Every authentication token, rate limit, and geofencing rule was broken because the proxy was forwarding the internal load balancer's IP instead of the actual requester's. That cost me a 48-hour outage window and two very unhappy on-call engineers. A reverse proxy sits between clients and your backend servers, accepting incoming requests and forwarding them to the appropriate service. It handles SSL termination, load distribution, caching, compression, and request transformation before your application code ever sees the traffic. Most people think of it as a traffic cop. It's really more like a middleman who rewrites your invoices before passing them along. The core mechanism is straightforward. Client sends HTTP request to the proxy. Proxy looks at the request, possibly modifies headers, connects to a backend server, forwards the request, captures the response, optionally caches or transforms it, then sends it back to the client. The client never knows which backend server actually processed their request. That separation is the entire point.
I've run HAProxy, Nginx, Envoy, Traefik, and Caddy in production over the years. Each has different tradeoffs. Nginx uses an event-driven architecture that scales well for static content and SSL termination but its configuration language can get ugly fast when you need complex routing logic. HAProxy is brutally performant at the TCP level but its config format reads like assembly code. Envoy gives you fine-grained control over observability and service mesh integration but doubles your infrastructure footprint because it usually runs as a sidecar. Pick the tool based on what you're actually optimizing for, not what sounds impressive in a conference talk. SSL termination is where most teams get their first win. Instead of every backend service managing its own certificates, the proxy handles TLS handshakes and passes decrypted traffic to your application. This cuts certificate rotation time from hours to minutes and removes a significant processing burden from your application servers. The tradeoff is that traffic between the proxy and your backend runs unencrypted unless you set up mutual TLS or use a service mesh. In a trusted internal network this is usually fine. In environments with compliance requirements you might need to keep end-to-end encryption regardless of the performance cost. Load balancing strategies matter more than people realize. Round robin sounds reasonable until you discover that your application has stateful connections or uneven request costs. I once routed traffic evenly across five backend instances where three were handling database-heavy queries and two were serving cached responses. The three heavy instances collapsed under 60 percent of the load while the other two sat at 15 percent utilization. Weighted least connections fixed this immediately by sending fewer requests to already-busy servers.
Health checks are another area where assumptions kill deployments. Most proxies support passive health checks that mark a backend as unhealthy after a series of failed requests. Active health checks periodically probe your service on a configured endpoint. The problem is that a healthy HTTP 200 response from a health check endpoint doesn't mean your application can actually serve real traffic. It might be connected to a slow database, running out of memory, or stuck processing a long queue. I learned this the hard way when my proxies were marking three out of five instances as healthy based on simple HTTP responses while those same instances were responding to actual user requests with 30-second latencies. Adding a health check that queries your application's actual readiness signal rather than a static endpoint solved it. Caching at the proxy level can save your backends from unnecessary work. Static assets, API responses with long TTLs, and idempotent GET requests are good candidates. But caching the wrong things creates stale data problems that are nearly impossible to debug. I configured Nginx to cache API responses for five minutes to reduce backend load during a traffic spike. The cache hit rate jumped to 70 percent and latency dropped dramatically. Three minutes later our support team started getting flooded with tickets because users were seeing cached order statuses that were hours old. The cache was working exactly as configured. The configuration was wrong for the data type. Disabling the cache for any endpoint returning mutable state was the fix.
Get the Full Details

Configuration Patterns That Actually Work
Here's a minimal Nginx reverse proxy configuration that handles basic routing, SSL termination, and header forwarding correctly: server { listen 443 ssl; server_name api.example.com; ssl_certificate /etc/ssl/certs/api.example.com/fullchain.pem; ssl_certificate_key /etc/ssl/private/api.example.com/privkey.pem; location / { proxy_pass http://backend-pool; proxy_set_header Host $host; proxy_set_header X-Real-IP $remote_addr; proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for; proxy_set_header X-Forwarded-Proto $scheme; proxy_connect_timeout 10s; proxy_read_timeout 30s; proxy_next_upstream error timeout http_502 http_503 http_504; } } The proxy_next_upstream directive is critical and frequently overlooked. When a backend returns a 502, 503, or 504, or when a connection times out, Nginx will automatically retry the request on the next available backend. Without this, a single flaky instance causes visible errors for whatever traffic it happens to be serving at that moment. With it, the proxy silently recovers from transient failures. This single directive reduced our user-visible error rate from approximately 2.3 percent to under 0.1 percent during a period where one of our five backend instances was intermittently crashing.
The header forwarding section does something important that trips up beginners. Setting X-Real-IP and X-Forwarded-For properly ensures your application can identify the actual client. Some frameworks read X-Forwarded-For directly. Others need X-Real-IP. Setting both covers the majority of backend frameworks without requiring per-application configuration. The Host header must be preserved because many applications use it for virtual host resolution, URL generation, and CORS checks. Rate limiting at the proxy level prevents a single client from overwhelming your backends. Nginx's limit_req module uses a token bucket algorithm. You define a zone in the http block and apply it per location: limit_req_zone $binary_remote_addr zone=api_limit:10m rate=10r/s; location /api/ { limit_req zone=api_limit burst=20 nodelay; proxy_pass http://backend-pool; }
This allows 10 requests per second per client IP with a burst capacity of 20 additional requests. The nodelay flag processes burst requests immediately rather than queueing them. Without nodelay, burst requests wait for tokens to become available, which can create the illusion of slowness rather than cleanly rejecting excess traffic. For most APIs you want immediate rejection, not delayed processing. WebSocket proxying is straightforward but has one gotcha. WebSockets are persistent connections that shouldn't be subject to the same timeouts as HTTP requests. Nginx requires explicit timeout overrides: location /ws/ { proxy_pass http://websocket-backend; proxy_http_version 1.1; proxy_set_header Upgrade $http_upgrade; proxy_set_header Connection "upgrade"; proxy_read_timeout 3600s; proxy_send_timeout 3600s; }

The proxy_http_version directive must be set to 1.1 because WebSockets require it. The Upgrade and Connection headers tell the backend to switch protocols. The timeout values should be set to match your application's actual connection lifecycle. I once left the default 60-second read timeout on a WebSocket proxy and watched half our real-time connections drop during load testing because the proxy was terminating idle connections that the backend considered still valid. Compression at the proxy level saves bandwidth but costs CPU. Gzip compression on the proxy reduces response sizes by roughly 60 to 80 percent for text-based content. If your backends are CPU-bound already, doing compression there too adds unnecessary load. If your backends are I/O-bound and your proxy has spare CPU cycles, offloading compression to the proxy improves both response times and network utilization. Measure your actual bottleneck before deciding where compression lives. Logging configuration deserves more attention than it gets. The default Nginx log format captures basic request information but misses details that matter for debugging. I use a custom log format that includes upstream response time, upstream status code, and request length:
log_format detailed '$remote_addr - $remote_user [$time_local] ' '"$request" $status $body_bytes_sent ' '"$http_referer" "$http_user_agent" ' 'upstream_time=$upstream_response_time ' 'upstream_status=$upstream_status ' 'request_length=$request_length'; This format makes it trivial to identify when a backend is slow versus when the proxy is slow. Without upstream_response_time in your logs you're guessing. With it you know within milliseconds whether the bottleneck is in your application or in the network path between the proxy and the backend.
Common Failures And How To Avoid Them
The most frequent production incident I've seen with reverse proxies involves DNS resolution inside the proxy container or server. Nginx resolves upstream hostnames at startup and caches the result. If your backend services scale down or change IPs, Nginx keeps using the old addresses until you restart it. This isn't theoretical. I had a Kubernetes deployment where our backend pods scaled from five to two during a maintenance window. Nginx was still routing to the three deleted pod IPs, generating constant 502 errors for roughly eight minutes until someone noticed and reloaded the configuration. Setting resolver and resolving directives or using IP-based upstreams instead of hostnames prevents this entirely. Another common failure is the missing trailing slash in proxy_pass locations. proxy_pass http://backend/ and proxy_pass http://backend differ in how Nginx handles the URI. Without the trailing slash, Nginx passes the full original URI including the location prefix. With the trailing slash, Nginx replaces the matching location prefix with the trailing slash path. Getting this wrong produces 404 errors that make no sense until you understand the URI transformation. I spent an afternoon tracking down what turned out to be a single missing slash in a configuration file. Connection pooling between the proxy and backends is often misconfigured. The default settings allow too few concurrent connections, which causes queuing under load. Setting proxy_http_version, proxy_set_header Connection "", and configuring proxy_cache_valid appropriately lets the proxy maintain persistent connections to backends instead of opening and closing TCP connections for every request. This typically reduces latency by 10 to 30 milliseconds per request because you eliminate the TCP handshake and TLS negotiation for each connection in the pool.

There are scenarios where a reverse proxy is the wrong tool. If you need deep packet inspection, application-layer protocol understanding beyond HTTP, or per-request computational logic that varies by content, a reverse proxy adds latency without providing value. An API gateway or service mesh would be more appropriate. If your traffic is entirely internal and doesn't need SSL termination, load balancing, or caching, adding a reverse proxy is just an extra hop that introduces a single point of failure. Know when not to use one. The silent guardian framing is accurate but incomplete. A reverse proxy also introduces a single point of failure, adds configuration complexity, creates a new layer where bugs can hide, and requires monitoring just like any other component. It's not a set-and-forget deployment. It needs health checks, log rotation, configuration versioning, and regular review. I audit my proxy configurations quarterly because subtle misconfigurations accumulate over time and only surface during incidents. If you're running multiple services behind a single proxy, consider whether you need per-service isolation. A single Nginx configuration handling all traffic means a misconfiguration in one route can take down access to unrelated services. Splitting proxy responsibilities across dedicated configurations or using multiple proxy instances limits blast radius. The operational overhead increases slightly but the failure domain decreases significantly.