
Registration Numbers Aren't Magic. They're Just Structured Data.
Most people treating a company registration number like a barcode don't actually know how the encoding works. You see twelve digits and assume there's meaning in them. Sometimes there is. Sometimes it's just a sequential counter with a checksum tacked on at the end. The difference matters when you're building something that needs to validate entities at scale instead of manually checking each one against a government database. I spent about two years working on entity resolution systems across European registries. The work wasn't glamorous. But it taught me that decoding a registration number correctly can save you from matching the wrong company during due diligence, mergers, or compliance checks. Getting it wrong costs time and sometimes real money.
What Is A Registration Number Decoding The Unique Identifier For Legal Entities And Assets
The literal process of decoding a registration number means taking that string of characters assigned by a government or regulatory body and extracting the meaningful parts from it. For some systems, the first two digits represent the country code. The next two might indicate the type of entity. The remaining digits are a sequential identifier and a check digit. For others, the entire number is just sequential with no embedded metadata. There's no universal standard, which is the main reason this topic exists. Look at the German Handelsregister number. It follows the format HRB or HRA followed by a number. The prefix tells you the register section. HRB is for commercial enterprises. HRA is for freelance professionals and certain partnerships. That's immediately useful because you can filter by entity type without making an API call. The number itself after the prefix is sequential within that register. You can't extract the founding date from it directly. But you can use the combination of prefix plus number to look up the entity in the official register with high confidence. The UK Companies House number is different. It starts with a two-letter prefix indicating the incorporation region or type, followed by six digits. The letters BN mean a standard company incorporated in England and Wales. OC means an overseas company. The number isn't meaningful beyond being a unique sequence. However, the prefix system lets you categorize entities without hitting the API for every lookup.
The Spanish NIF system for companies uses the letter N or A as a prefix, followed by eight digits and a control letter. The letter before the digits identifies the entity type. The eight digits are the tax identification number. The final letter is a modulo 23 check character. This one is actually parseable. If someone gives you a Spanish company NIF, you can verify the check letter locally without any external call. I built validation functions for this exact format because our system ingested thousands of Spanish entity records per day.
Get the Full Details

Common Formats You'll Actually Encounter
Below is a breakdown of the formats you will run into in production. Not all of them. Just the ones that matter for entity resolution systems. Germany: HRB/HRA/HRBplus number from Handelsregister. Prefix + sequential integer. Check digit is absent. You decode by parsing the prefix letter sequence and validating the integer against the register boundaries. The register is publicly searchable, but bulk access requires authorization. I found that using the Handelsregister API with a valid authentication token gave us results in about 200 milliseconds per query, which was acceptable for our throughput. France: SIRET and SIREN numbers. SIREN is nine digits. The last digit is a modulo 97 check. SIRET is the SIREN plus five digits identifying the establishment. You can validate a SIREN without any external call. The check digit algorithm is straightforward. The problem is that SIREN doesn't encode entity type or region. You need the API or a third-party data provider to get the denomination and legal form. I ran into a situation where two companies shared the same SIREN because one was a parent and the other a subsidiary during a restructuring. The INSEE database didn't reflect the change for about fourteen months. We had to cross-reference with the BODACC publication to resolve it.
Italy: Codice Fiscale for entities and Partita IVA. The Partita IVA is eleven digits. It follows the same modulo 11 check digit algorithm used for Italian fiscal codes. The first seven digits encode the municipality of incorporation. The next three encode the entity type and sequence. The last digit is the check. You can decode the municipality from the first seven digits using the ISTAT code table. I used a local lookup table instead of hitting theAgenzia delle Entrate API for every validation. This reduced our latency from roughly 300ms to under 50ms per lookup. The tradeoff is that your table must be kept current, and the municipality codes occasionally get updated when new zones are created. Netherlands: KVK number. Seven digits, sometimes with a prefix indicating the registry office. The format is relatively stable but the check digit algorithm is not published in any accessible format. You cannot validate a Dutch KVK number locally without the algorithm. I ended up using a third-party provider for validation instead of trying to reverse engineer it. The cost was about 0.002 euros per validation at our volume.
The Check Digit Problem Nobody Warns You About
Most registration number systems include a check digit. The purpose is error detection, not security. A simple typo should fail validation. But here's what trips people up: the check digit algorithm differs between systems, and some countries changed their algorithm mid-stream without a clear public record of the transition date. I encountered this with the Polish KRS number. The system uses a modulo 10 check with weights that shift depending on the registry type. Court numbers, economic register numbers, and court partnership numbers all use slightly different weight sequences. I wrote a validator that tried all three patterns and returned the one that matched. It worked until we hit a dataset where someone had transcribed the number manually and introduced a double transposition error. Both the correct pattern and a wrong pattern could produce a valid check digit for different digit arrangements. That case required a fallback to the official registry API. It took me about three days to realize the issue existed and another two to build the fallback logic.

Asset Registration Numbers Are Worse
Legal entity numbers are confusing enough. Asset registration numbers are usually worse because there are far fewer standardization efforts. Vehicle identification numbers follow ISO 3779. That one is standardized and you can parse it. Marine vessels use IMO numbers. Those are just sequential with a check digit. Real estate cadastre numbers vary wildly by jurisdiction and often embed regional codes that are impossible to decode without a local mapping table. Vehicle numbers in Germany include the locale code in the first one to three characters. That's useful. But the VIN itself doesn't tell you the owner. You need a separate query to the Kraftfahrt-Bundesamt or a third party for ownership data. I learned this the hard way when a client asked us to decode VINs to identify fleet owners. We built the decoder, validated the format, and then realized the data they actually needed required a different query entirely. The VIN was a dead end for their use case. It would have been better to ask about the use case first.
Practical Steps For Building A Decoder
If you're building a system that processes registration numbers, here's the order I follow. First, identify the jurisdiction and the number type. You can't decode anything without knowing which format applies. The input string alone might not tell you. A nine-digit number could be a French SIREN or a Portuguese NIPC or something else entirely. You need context or a lookup. Second, validate the check digit before doing anything else. Local validation is fast. It filters out obvious errors before you waste API calls on invalid inputs. This step alone typically reduces API costs by sixty to eighty percent in my experience, depending on data quality.
Third, parse the structured portions. Country codes, entity type indicators, municipality codes. Extract what you can. Store it. Don't throw it away because the numbers look arbitrary. The extracted fields become useful for filtering and grouping later. Fourth, make the external call. Use the decoded prefix or identifier as your query key. The query should return the official record. Match against the registration number exactly. Fuzzy matching on registration numbers is almost always a mistake. The number is supposed to be unique. If your fuzzy logic is returning multiple matches, your input data is broken or you're using the wrong number type.
Edge Cases That Will Waste Your Time
Historical numbers. Some countries issue new registration numbers during database migrations or legal reforms. A company formed in 1998 in Spain might have a different NIF format than one formed in 2024. The old format still appears in legacy systems. Your decoder needs to handle both or route to a lookup that normalizes them. Duplicate numbering. Rare but real. I saw it happen in a smaller EU registry where a merger caused two legacy numbers to be mapped to the same active entity. The registry kept both numbers active for a transition period. If your system treats the number as the primary key, you'll get duplicate entity records. Use a combination of number plus jurisdiction plus a timestamp range instead. Null prefixes. Some registries assign purely numeric numbers with no alphabetic prefix. The UK used to do this. The system switched to the alphanumeric format to expand capacity. If your parser expects a prefix, it will break on legacy data. Always handle the no-prefix case gracefully.
Tools I Actually Use
For European entity validation, I rely on a combination of the official registries where API access is available and a few commercial aggregators for the rest. The German Handelsregister API, the French INSEE SIRENE API, and the Italian Camera di Commercio data feeds cover most of Western Europe. For countries without good public APIs, I use providers like Companies House data exports, Dun & Bradstreet, or local data vendors specific to that jurisdiction. The open-corporate.com API is decent for US entities. It's not real-time but it covers the vast majority of Delaware and Wyoming entities at zero cost. The data lags by a few days. For most use cases that's fine. For live compliance checks, it's insufficient. For local check digit validation, I keep a small library of modulo algorithms. The most common are modulo 10, modulo 11, and modulo 97. Each has variants with different weight sequences. I've mapped the major European formats to specific weight tables. When I encounter a new format, I add it rather than rewriting the validator.
When Decoding Won't Help You
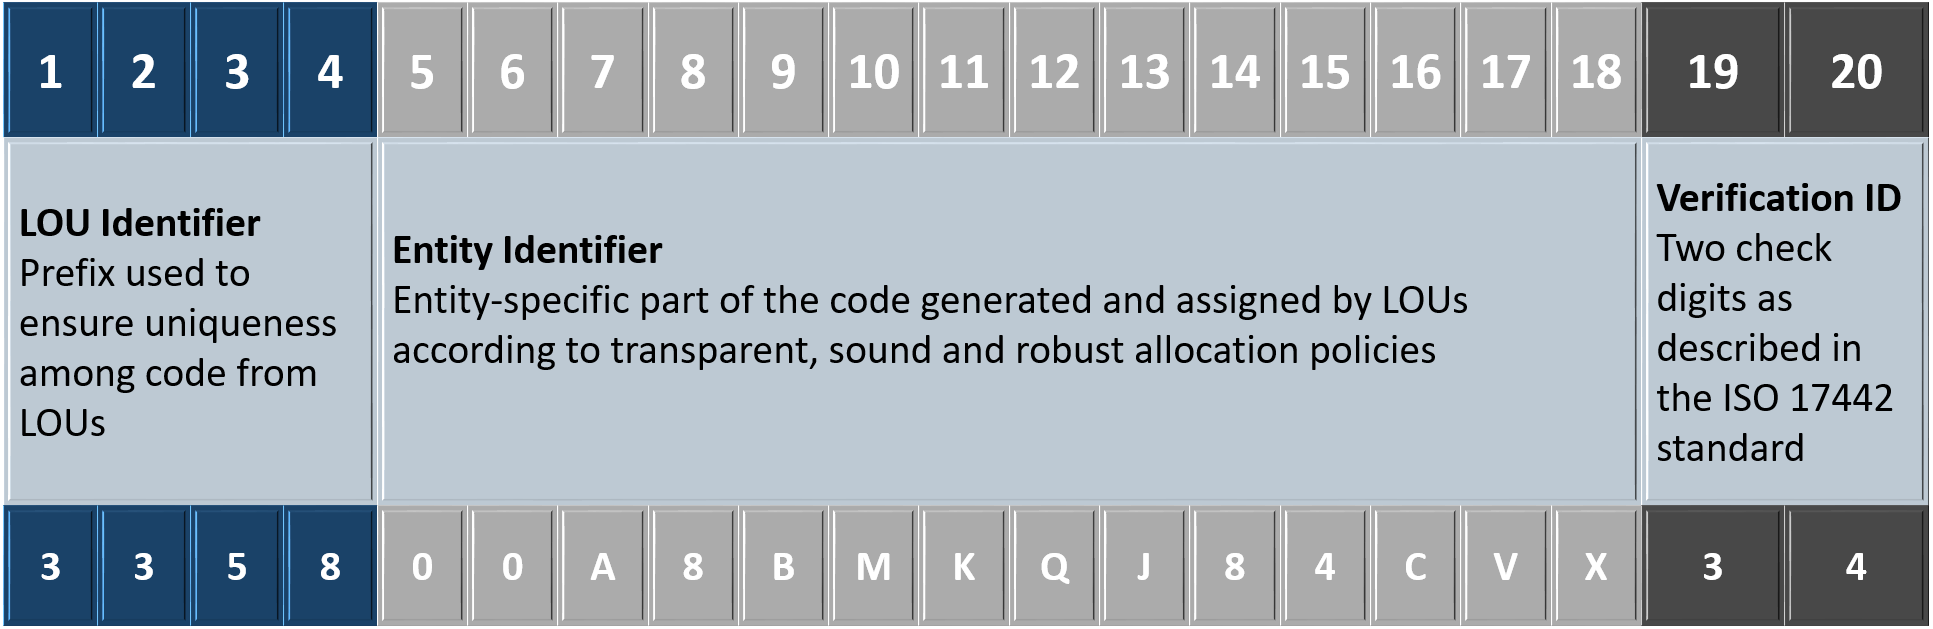
If the registration number is missing, malformed, or belongs to a jurisdiction with no public registry, decoding does nothing. You need alternative identifiers. Tax IDs, LEI codes, or passport numbers for individuals. A LEI is worth building into your system early. It's a 20-character alphanumeric code with a defined structure. The first four characters are the institution entity identifier, the next sixteen are the unique entity reference, and the last two are check digits. LEIs are standardized globally. You can validate the check digits locally. You can look up the entity data from any LEI distribution agency. It's the closest thing we have to a universal entity identifier, and most registration number systems don't reference it by default. You need to collect it separately. Another limitation: registration numbers don't tell you about corporate structure. A parent company and its subsidiary can have completely different numbers in the same country. Decoding the number won't reveal the relationship. You need a separate ownership graph or a parent-subsidiary field from the registry data. I've seen systems try to infer relationships from registration numbers alone. It doesn't work reliably. The numbers are assigned independently by different registry offices or at different times.

A Real Case From My Work
We were processing cross-border acquisition targets across five EU countries. The client provided a spreadsheet with registration numbers for about four thousand entities. Twenty percent of those numbers failed local validation on the first pass. The failures fell into three buckets: typographical errors from manual entry, numbers from defunct entities no longer in the active register, and numbers from a jurisdiction whose format we hadn't implemented yet. Bulgaria was the gap. Their EGN and BULSTAT formats are not well documented in English. We spent about a week implementing a Bulgarian validator using the official document from the AGB. It turned out the format uses a seven-digit entity code with a check digit based on a non-standard weight sequence. The validator reduced our failure rate from twenty percent to about four percent. The remaining failures required manual review or API verification. Nothing eliminates that last portion entirely unless you have real-time registry access for every jurisdiction you support.
The Bottom Line
Registration number decoding is a mechanical task with enough variation to make it tedious. The value isn't in the decoding itself. It's in what the decoded structure lets you do next: validate without API calls, group entities by type, route queries to the right registry, and catch data quality problems before they propagate through your system. Build the validators first. Test them against real datasets, not sample strings. Keep the check digit logic separate from the lookup logic. And don't pretend the number alone solves your entity resolution problem. It's a starting point, not an endpoint.

