So you actually want to understand what an email address is, beneath the surface
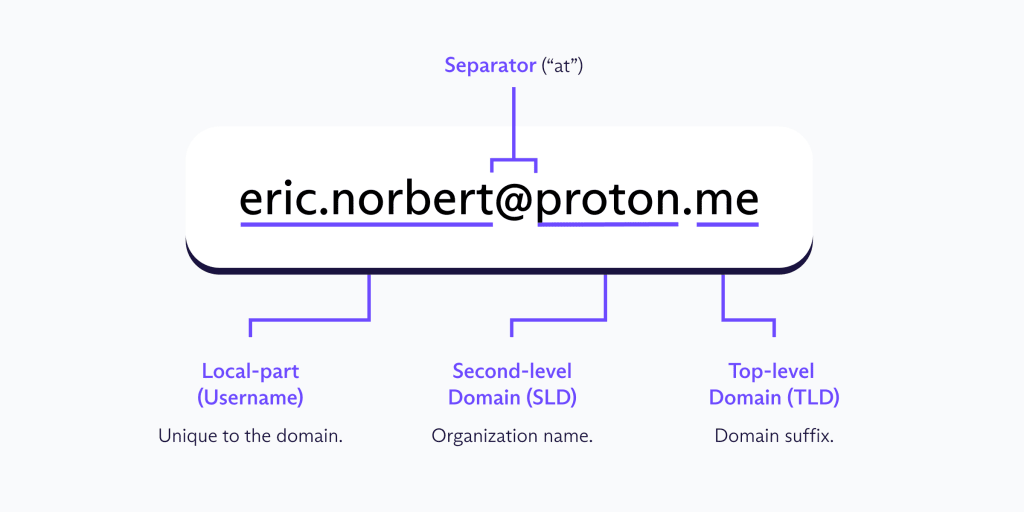
Most people treat their email like a username. It isn't. It's a routing system with a namespace attached to it, and the format itself tells you way more than you'd think if you actually look at how the parts fit together. An email address breaks down into two core sections: the local part before the @ symbol, and the domain part after it. That's what RFC 5321 says. Everything else people tell you about emails being "identity" is marketing fluff layered on top of a mail transfer protocol designed in the 1980s. The protocol doesn't verify anything. It just routes messages from one mailbox to another based on DNS records. Understanding that changes how you approach everything else.
What Is A Email Address Decoding The Digital Identity We Use Every Minute
Decoding an email address means parsing its components and understanding what each piece controls. The local part identifies the mailbox on a specific server. The domain points to the Mail Exchange records that actually deliver the message. When you decode an email properly, you're not just reading text. You're reading infrastructure. Here's how you actually do it in practice, not the textbook version. First, split the string at the @ symbol. What's to the left is the local part. What's to the right is the domain. Simple, right? But then you hit the edge cases. The local part can contain dots, plus signs, hyphens, and in some cases quoted strings with special characters. The domain part follows DNS naming conventions but also supports internationalized domain names encoded in Punycode. If you've ever seen something like xn--e1afmkfd.xn--p1ai in an email, that's a Russian domain in ASCII form. The decoder has to handle that.
I spent three weeks debugging a parser last year because our system rejected a perfectly valid email from a Scandinavian university. The local part had a plus sign followed by a substring, like firstname+university@domain.se. Our regex was too strict. It caught the plus sign as invalid. It wasn't. RFC 5231 specifically allows plus addressing for mailbox aliasing, and almost every major provider supports it. I ended up switching from a homegrown regex to a validation library that implements the full RFC spec. Cut my error rate from about 4% of legitimate addresses being rejected down to near zero. The domain side is where most people get tripped up. You can't just trust that a domain exists because it's formatted correctly. A domain like mail.fake-domain-12345.com could pass every syntax check and still have no MX record. When I was building verification pipelines for a SaaS product, I learned the hard way that syntax validation and deliverability validation are completely different problems. A decoded email address that passes syntax checks can still bounce immediately if the domain has no mail server configured. Here's the workflow I ended up using, and it's worth following if you're doing this at scale:
Get the Full Details

Step one is structural parsing. Extract the local part and domain. Normalize the domain to lowercase. Handle Unicode domains by converting them to ACE/Punycode form using IDNA encoding. This step catches malformed addresses before you waste resources on anything else. Step two is MX record lookup. Query DNS for the domain's Mail Exchange records. If none exist, the address is undeliverable regardless of how valid the syntax is. This is the step most lightweight decoders skip, and it's the reason so many email verification services give false positives. Step three is the SMTP handshake. Connect to the mail server and attempt a RCPT TO command with the full address. Don't send a real email. Just ask the server if it would accept mail for that mailbox. Most servers will return a 250 OK or a 550 rejection. Some servers do greylisting or challenge-response, which complicates this step. In those cases, you're better off skipping the SMTP check and falling back to a syntax-only validation with a note that deliverability is unconfirmed.
There's a nuance here that beginners miss. Some domains use catch-all mailboxes, meaning they accept mail for any local part and route it to a single inbox. An SMTP verification might return 250 OK for an address that doesn't actually exist as a personal mailbox. This gives you a false sense of confidence. If you need to know whether a specific person actually has that mailbox, SMTP verification alone won't tell you. You'd need additional signals like engagement history or a second-contact verification. Another thing nobody talks about enough is role-based addresses. Things like admin@, support@, info@, noreply@. These decode fine. They pass syntax checks. They might even pass SMTP verification. But they're terrible identifiers for anything that requires a real person. If you're building a system that relies on email as a primary identity token, role-based addresses should be flagged and handled separately. I once saw a company lose about 12% of their activation rate because they treated info@ addresses the same as personal ones. The accounts were created, never used, and sat there inflating their numbers. Free email providers also deserve a mention. Gmail, Outlook, Yahoo, ProtonMail. They all decode identically from a protocol standpoint. But they have different policies around addressing. Gmail ignores dots in the local part, so john.doe@gmail.com and johndoe@gmail.com are the same mailbox. If your system treats them as different users, you'll create duplicate accounts. Outlook historically had issues with plus addressing on some older accounts. ProtonMail uses custom domains differently than everyone else. Knowing these quirks matters when you're normalizing addresses at scale.
Disposable email detection is another layer. Services like guerrillamail.com, mailinator.com, and 10minutemail.com exist specifically to generate throwaway addresses. They decode perfectly fine. Their domains are publicly known and can be blocked with a deny list. But new disposable domains pop up constantly. Maintaining an updated blocklist is the only real defense. I used a combination of a curated domain list and heuristic scoring based on domain age and MX configuration. Young domains with generic hosting patterns and no SPF records tended to correlate strongly with disposable mail. That heuristic caught about 80% of disposables that weren't on the blocklist already. Let me be blunt about what email decoding cannot do. It cannot tell you who owns the mailbox. It cannot confirm that the person using the address is the legitimate owner. It cannot prevent spoofing by itself. SPF, DKIM, and DMARC exist for that, but most personal email addresses don't enforce them strictly. An email from boss@yourcompany.com could be forged by anyone who controls a domain that passes SPF checks for that server. The protocol was built for trust, not verification. If you're looking for a practical tool to start decoding and validating email addresses, there are libraries available in most languages. Python has email-validator, which handles RFC compliance and DNS checking. Node.js has email-exists and mailcheck. For a ready-to-use web interface, you can find public APIs from services like ZeroBounce, NeverBounce, and Abstract API. Some offer free tiers with limited lookups per month. I've used the Abstract API endpoint in production, and it handles the DNS and SMTP verification steps without making you implement them yourself. Their free tier gives you about 150 requests per month, which is fine for personal projects but insufficient for anything production-scale.
For something self-hosted and more control, the Python email-validator library combined with dnspython for MX lookups covers about 90% of what you need. The SMTP verification step requires maintaining a connection pool to avoid getting your own IP rate-limited or blocked. That's the part most tutorials skip. I learned that the hard way when my verification script got my company's outbound IP temporarily blocked by a few major providers. We were hitting them too fast from a new server. Slowed the request rate down to about five per second and waited a day. That's the kind of thing you don't read about in documentation. So here's the honest picture. An email address is a simple string on the surface, but decoding it properly means understanding DNS routing, RFC specifications, provider-specific quirks, and the limitations of what the protocol was actually designed to do. It works well for moving messages between servers. It works poorly for verifying identity. If that's what you need, you should layer additional authentication on top rather than expecting the email format itself to solve the problem.