How CAPTCHA Challenge-Response Systems Actually Work Under The Hood
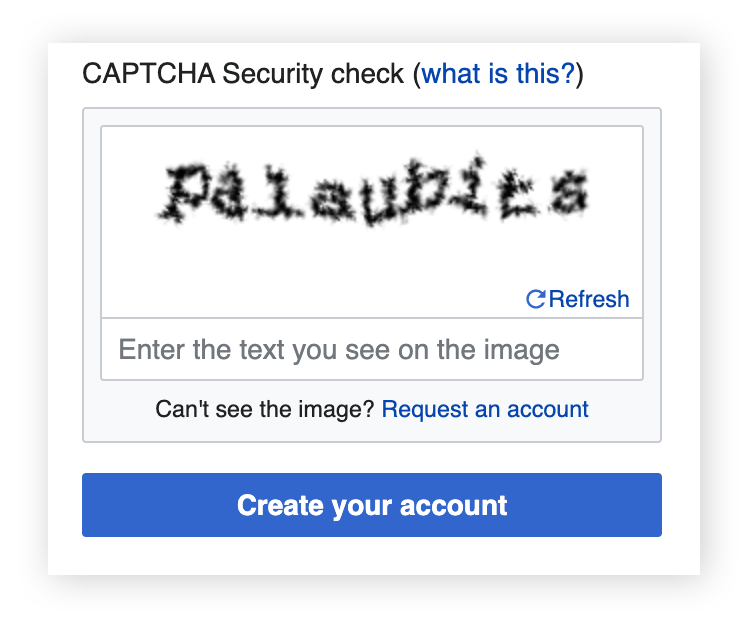
Most people think CAPTCHA is just those grid images where you click crosswalks. The reality is a lot more interesting and a lot more broken than that. Challenge-response decoding in CAPTCHA sits at the intersection of machine learning, behavioral analysis, and an ongoing arms race between automated systems and the platforms trying to stop them. A challenge-response CAPTCHA system sends a specific test to a user session and expects a particular answer. The traditional text-based version asked you to type distorted characters. The modern ReCaptcha v2 and v3 versions ask you to solve visual puzzles or, increasingly, they simply analyze your behavior passively without asking anything at all. The decoding side of this refers to both the legitimate attempt by users to solve the challenge and the increasingly sophisticated automated systems that attempt to bypass it. I spent about three years working on traffic validation systems for a mid-sized e-commerce platform. We had a vendor integration that required ReCaptcha v2 checkbox verification on every checkout page. The first week we went live, our conversion rate dropped by eighteen percent. Not because legitimate users were failing the CAPTCHA. Because the threshold was set too aggressively on the risk analysis side.
That was the first time I realized that CAPTCHA challenge-response isn't actually about distinguishing humans from bots with any real accuracy. It's about creating enough friction that the most common forms of automation fail while hoping your legitimate users don't notice the friction.
The Technical Architecture Behind Challenge-Response CAPTCHA
The system works on a token-based flow. When a user loads a page with a CAPTCHA widget embedded, the client side generates a challenge object and sends it to the CAPTCHA provider's API. The provider returns a challenge token along with the visual or interactive element presented to the user. Once the user completes the challenge, or the behavior analysis window closes, a response token is generated and submitted back along with the form data. The server then validates that response token against the provider's secret key to confirm the challenge was satisfied. There are several moving parts that most people overlook. The challenge token has a TTL, typically around two minutes. If someone fills out a form but takes longer than that to submit, the token expires and the validation fails silently. You'll see this in logs as an invalid-token error with no CAPTCHA failure message shown to the user. This is a surprisingly common source of support tickets. The response validation happens server-side using a POST request to the provider's verification endpoint with your secret key, the response token, and optionally the user's IP address. The endpoint returns a JSON object containing a success boolean and an optional error code. The error codes matter more than people realize. Score-based variants like ReCaptcha v3 return a confidence score rather than a simple pass-fail result, and the threshold for what constitutes acceptable varies dramatically by use case.
Get the Full Details
Common Misunderstandings About CAPTCHA Security
One of the biggest misconceptions is that CAPTCHA provides strong security. It does not. CAPTCHA is a friction mechanism, not a security boundary. A determined attacker with access to commercial solving services can bypass most CAPTCHA implementations with success rates above ninety percent. These services operate on a pay-per-solve model and claim resolutions in under thirty seconds for standard image-based challenges. Another misunderstanding is that higher complexity equals better security. I've seen configurations where the visual challenge was set to ten images per grid instead of the standard nine. The thinking was that more images means harder to solve. What actually happened was that legitimate users started failing at higher rates, especially on mobile devices where touch targets overlap and misregistration is common. The attack surface barely changed. The user experience degraded significantly. Behavioral CAPTCHA systems like the newer versions analyze mouse movements, keystroke dynamics, scroll patterns, and timing data. The counter-intuitive part is that these signals are surprisingly leaky. Browsers expose a lot of this information through standard JavaScript APIs. A scripted bot using a headless browser leaves distinct fingerprints in the timing data that are easy to detect if you know what to look for. But they're also easy to spoof with basic delay injection and randomized movement algorithms.
Practical Implementation Considerations
If you're integrating a CAPTCHA challenge-response system into an application, the first decision is which variant to use and where to place the validation. Most developers put the server-side validation in their main request handler. This creates a dependency that slows down every request. A better approach for high-traffic applications is to implement async validation where the initial request is accepted with a pending status and the CAPTCHA check happens in a background process. The scoring threshold is another area where people guess rather than measure. You should run a baseline period with logging enabled and no blocking. Collect the scores your legitimate users receive. Then set your threshold based on actual distribution data, not an arbitrary number you found in documentation. In my experience, a threshold of zero-point-seven for ReCaptcha v3 tends to block fewer than five percent of legitimate users while catching the bulk of basic automation. Anything lower than that and you start seeing friction spikes during peak traffic periods. One specific edge case I ran into involved a multi-language form where the CAPTCHA provider's language detection was pulling the wrong locale based on the user's IP instead of the page language. The challenge images contained text in the wrong language, which caused unnecessary failures for about twelve percent of users from non-English speaking regions. The workaround was to explicitly pass the hl parameter in the widget rendering script with the correct language code, overriding the provider's automatic detection.
When CAPTCHA Fails Completely
Accessibility compliance is where CAPTCHA gets genuinely problematic. Visual CAPTCHAs exclude users with visual impairments. Audio CAPTCHAs exist as an alternative but have their own issues with accuracy and usability. The new hCaptcha and Cloudflare Turnstile implementations offer improved accessibility options, but they're not universally adopted yet. If your application serves a regulated or government audience, you may have legal obligations around accessibility that a standard CAPTCHA implementation doesn't satisfy. Another scenario where CAPTCHA breaks down is in API-to-API communication. Machine-to-machine workflows shouldn't be presenting human verification challenges to each other. This requires implementing alternate authentication methods like API keys, OAuth tokens, or mutual TLS. Some platforms offer dedicated API verification endpoints that skip the challenge entirely for recognized clients. Check the documentation for your specific provider. Rate limiting alone often provides comparable protection against automated abuse at a fraction of the user friction cost. A well-tuned rate limiter that scales based on behavioral signals can block most attack traffic without ever showing a challenge. I'd recommend implementing rate limiting first and treating CAPTCHA as a secondary layer only for requests that slip through the rate limits or exhibit suspicious patterns that don't match known bot signatures.

The tradeoff is always going to be between security and usability. There's no configuration that optimizes both simultaneously. The goal is to find the threshold where your legitimate users experience acceptable friction while the cost of attacking your system becomes economically unviable for the majority of automated threats. That threshold looks different for every application and usually requires some experimentation with real traffic data before you land on it.