The Buffer Problem Nobody Talks About Until It Breaks
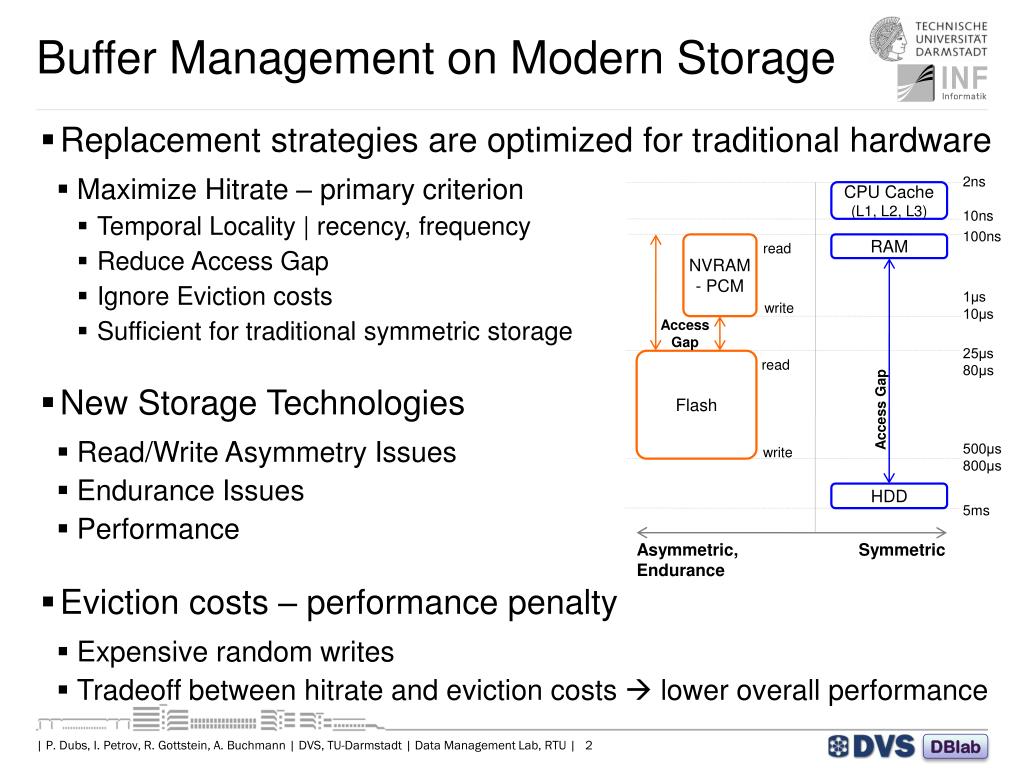
Buffers sit between your application and your storage layer, and they are the reason most read/write operations don't grind to a halt. When you write a file, the OS doesn't push every byte straight to disk. It queues data in memory, batches the writes, and flushes them when it decides the timing is right. Same thing in reverse for reads. This seems like a minor detail, but it changes how you design storage systems, how you handle security, and how you debug performance problems that make no sense on paper. I spent two years dealing with a production issue where our database latency jumped from 12 milliseconds to over 400 milliseconds during peak hours. The culprit wasn't the query planner, wasn't the index, wasn't the hardware. It was the write-back buffer strategy combined with a misconfigured flush interval. We had set the buffer pool size too high relative to available RAM, which meant the OS was constantly evicting pages just as the application needed them back. The fix wasn't adding more memory. It was tuning the dirty page ratio down from 80 percent to 40 percent and switching from background flush to write-then-flush for critical tables. Latency dropped back to baseline within an hour. That took me three weeks to figure out because the monitoring tools were all showing green across the board.
What Is A Buffer Unlocking The Power Of Digital Storage And Security
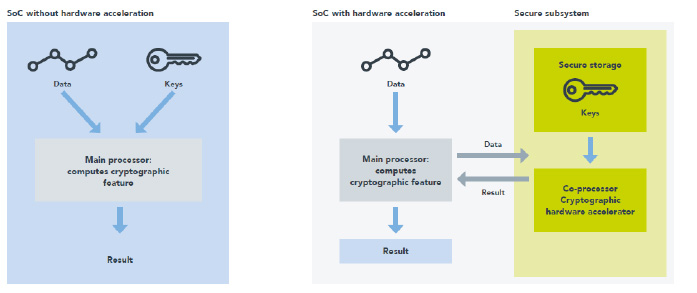
A buffer is a block of reserved memory that holds data temporarily while it is being transferred between two systems or processes that operate at different speeds. In digital storage, buffers absorb the mismatch between how fast your CPU can generate or consume data and how slow your storage device can actually accept or deliver it. Modern NVMe drives write at roughly 3,000 to 7,000 megabytes per second. Your application might be pushing data in small chunks at irregular intervals. The buffer smooths that out. It batches writes, aligns them to sector boundaries, and sends them in large sequential blocks instead of thousands of tiny random writes that destroy performance. In security, the concept flips completely. Buffers are where most memory corruption vulnerabilities live. A buffer overflow happens when a program writes more data into a buffer than it can hold, spilling into adjacent memory and overwriting control structures, pointers, or execution flow. This is not a theoretical edge case. The majority of high-severity CVEs published every year trace back to buffer management issues. ASLR, stack canaries, and non-executable memory pages exist specifically because buffers are inherently dangerous if handled carelessly. You don't get security by ignoring buffers. You get it by understanding exactly how they behave and constraining them properly. The dual nature of buffers is something most engineers only understand after causing an outage or a breach. They are simultaneously the best performance tool you have and the most common attack surface you'll face. Managing both sides requires knowing when the buffer helps you and when it is working against you. On the performance side, larger buffers usually mean fewer I/O operations and better throughput. On the security side, larger buffers mean larger attack surfaces and more memory to validate. There is no universal optimal size. It depends entirely on your workload, your threat model, and your hardware constraints.
How Buffers Actually Work Under The Hood
When your application calls write with a 4-kilobyte chunk of data, the operating system copies that chunk into a buffer managed by the page cache. The data sits there until either the buffer fills up, a flush threshold is reached, or the application explicitly requests a sync. At that point, the kernel groups multiple buffered chunks into a single sequential write to the storage device. This is why repeated small writes perform dramatically better than they should. The disk sees large sequential operations even though the application never issued one. The read path works similarly but in reverse. When your program reads data, the OS checks the buffer first. If the data is already cached from a previous access, it returns immediately without touching the disk. This is the page cache hit. If it is not there, the OS pulls a larger block from disk than the application requested and stores the extra in the buffer for future use. That prefetching is what makes sequential reads feel instant compared to random reads. The buffer absorbs the latency so your application never has to wait for every individual byte. One thing most documentation leaves out is how buffers interact with filesystem journaling. When you write to a journaled filesystem like ext4 or XFS, the buffer gets written to the journal first, then to the main filesystem structure, then the actual data blocks. The journal write is sequential and fast. The data write can be random and slow. The buffer lets the journal commit complete quickly while the data catches up in the background. This is why your system feels responsive during heavy writes. The buffer decouples the perceived latency from the actual disk latency. But it also means a power loss before the buffer flushes can leave you with a valid journal but incomplete data. That is the trade-off you accept for performance.
Get the Full Details
Buffer Management In Practice
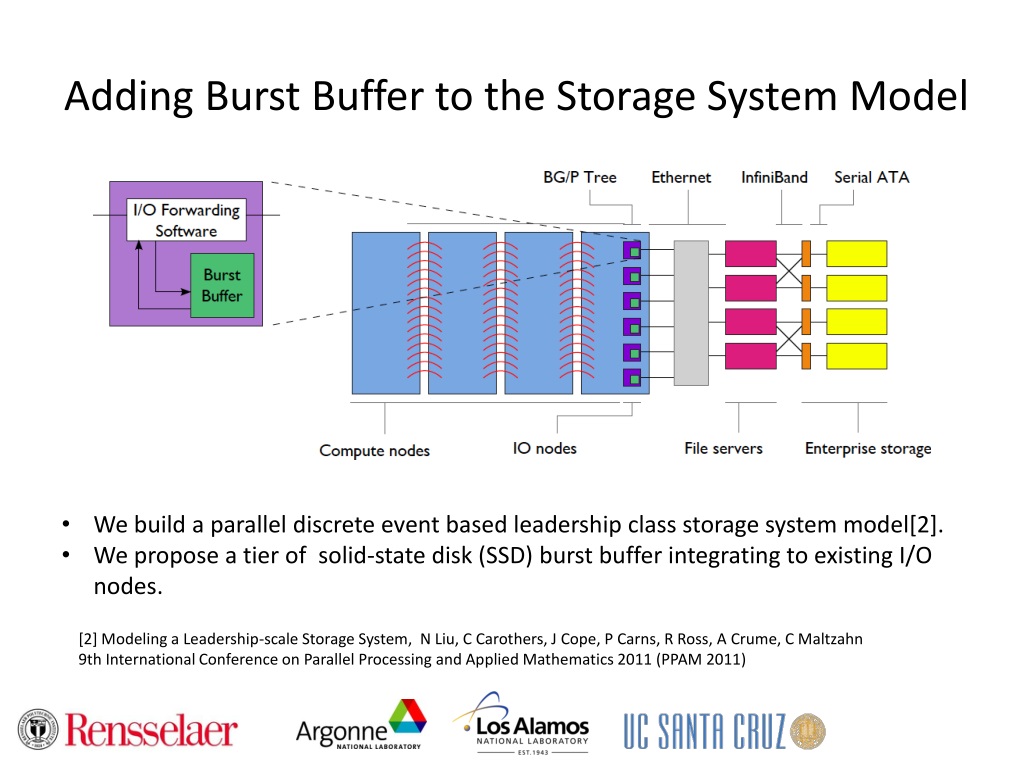
Tuning buffers is not something you do once and forget. The right configuration shifts as your workload changes. I worked on a video processing pipeline where the buffer settings made for a web server performed terribly. Video encoding generates large sequential writes at steady rates. Web servers generate small random reads and writes unpredictably. The default buffer size and flush interval that suited the web server caused massive write amplification on the video pipeline. We ended up dedicating a separate buffer pool to the encoding workload with a larger dirty ratio and longer flush delays. Throughput improved by roughly six times because the buffer was finally matching the pattern of the data instead of fighting it. For systems running databases, the buffer management happens at two levels simultaneously. The database engine maintains its own buffer pool for frequently accessed pages, and the OS maintains its own page cache for everything else. When these two layers disagree, performance tanks. If the database thinks it owns a buffer page and the OS decides to flush it out to free RAM, the database has to re-read it from disk, defeating the purpose of having a buffer pool in the first place. The workaround I used in a production environment was to reserve a portion of RAM exclusively for the database using memory lock flags, which prevented the OS from evicting those pages. This eliminated the double-buffering conflict entirely. It also meant less RAM available for the OS page cache, so we had to balance carefully based on the actual ratio of database to non-database workloads on that machine. Another practical issue that comes up constantly is buffer alignment. Storage devices have optimal block sizes determined by their physical sector geometry or internal page mapping. If your buffer writes are misaligned, the device has to perform read-modify-write cycles internally, which cuts effective write speed in half or worse on some SSDs. I saw this on a custom storage appliance where the buffer was being filled with variable-length records that didn't align to the 4-kilobyte boundary. The SSD controller was doing twice the internal erasing and rewriting it needed to. Aligning the buffer to the native block size fixed the write speed issue without changing any hardware or firmware.
Security Implications You Cannot Ignore
Buffer overflows remain one of the most exploited vulnerability classes precisely because they are so easy to introduce and so hard to detect through testing alone. A single unchecked input length in a string copy routine can give an attacker arbitrary code execution. The mitigation landscape has improved significantly. Languages like Rust prevent buffer overflows at compile time by enforcing bounds checking. Modern C compilers include stack protectors and canary values that abort the program before the overflowed buffer can be leveraged. Operating systems enforce DEP and NX bits that mark buffer memory as non-executable, so even if you overwrite the buffer, you cannot inject and run shellcode from it. But these mitigations are not foolproof. Return-oriented programming bypasses non-executable buffers by chaining existing code snippets together. Side-channel attacks leak buffer contents through timing or power analysis without touching the buffer directly. I encountered a case where a seemingly safe C++ string operation with std::string triggered a buffer overflow because of an integer overflow in the resize calculation that preceded the copy. The individual operations were safe. The combination was not. This kind of issue is nearly impossible to catch with a linter or a basic code review. It requires fuzzing and formal verification to find reliably, and even then, you only catch what you test for. Another security angle that people overlook is buffer reuse. After data is read from a buffer and the buffer is freed or reallocated, remnants of the previous data can remain in memory until they are overwritten. If the buffer is reused for a sensitive operation without proper clearing, the old data leaks into the new operation. This is called a information remanence vulnerability and it has been exploited in real attacks against encryption implementations. The workaround is straightforward: explicitly zero out buffers after use, especially buffers that held cryptographic keys or authentication tokens. But most codebases do not do this consistently because the performance cost feels unnecessary for non-sensitive operations, and developers fail to track which buffers actually hold sensitive data across the entire lifecycle.
When Buffers Fail Completely
There are scenarios where buffers do not help and may actively hurt. High-frequency trading systems and real-time control loops require deterministic latency. Buffers introduce unpredictable delays because data sits in memory until flush conditions are met. In these cases, direct I/O bypasses the buffer entirely and writes straight to disk, which trades throughput for predictability. Audio production and live video streaming face a similar problem. Buffer underruns cause audible glitches and frame drops that no amount of cache tuning can fix. The solution is often smaller buffers with stricter timing guarantees rather than larger buffers designed for maximum throughput. Another failure mode is buffer bloat. When buffers grow too large, they increase latency instead of improving it. A TCP send buffer that is several megabytes in size will cause huge queues during congestion, adding hundreds of milliseconds of delay before any packet is transmitted. This is particularly damaging for interactive applications where low latency matters more than raw bandwidth. The fix involves limiting buffer size and enabling proper congestion control algorithms. Many default system configurations today still ship with buffer sizes far larger than necessary for typical workloads, which is why enabling TCP BBR or CUBIC congestion control often produces noticeable latency improvements even when throughput stays the same. For embedded systems with severe memory constraints, maintaining a buffer is sometimes impossible. Microcontrollers with a few kilobytes of RAM cannot afford a page cache or application-level buffer. These systems use streaming I/O or ring buffers with fixed capacities that wrap around rather than grow. The performance characteristics are completely different from desktop or server environments, and tuning strategies do not transfer across. I learned this the hard way when I ported a server-side buffering algorithm to an ARM Cortex-M4 without adjusting for the memory limits. The system ran fine in simulation but degraded under real load because the buffer management overhead consumed more CPU cycles than the actual data processing.