So You Need Something Running All the Time
Most people use "24/7" as a marketing buzzword. On the implementation side, it means something much more boring and expensive. You are looking at building systems that must survive without guaranteed human oversight for any 15-minute window across every day of the year, including leap years and holidays that no one planned for. At its core, 24/7 operation is the practice of maintaining continuous service availability outside of standard business hours. This shows up in cloud infrastructure, manufacturing, healthcare, customer support, and software platforms. It is not a single tool or product you can buy off the shelf. It is an architectural and organizational commitment. You design for failure knowing that the failure might happen at 3:17 AM on a Tuesday when the only person awake is an on-call engineer who would rather not be awake. People always ask what "five nines" means. It means 99.999% uptime, which works out to about five minutes of allowed downtime per year. Three nines is 99.9%, roughly eight hours and forty-six minutes per year. Two nines is 99%, which is about three days and fifteen hours of acceptable downtime annually. Most consumer SaaS products aim for three or four nines. Payment processing and medical monitoring systems push toward five or six nines. The cost curve is not linear. Jumping from four nines to five nines typically costs three to four times more in infrastructure and staffing than the baseline operation. Jumping from five to six nines is where you either have a serious budget or you are trying to keep a nuclear power plant running.
I once spent three weeks debugging a production outage that traced back to a database failover script that had never been tested during a weekend. It ran fine during weekday load windows. On Saturday morning with a different traffic profile, it dropped connections silently. The fix was replacing the script with a stateful probe that validated connection health after failover instead of assuming success based on return codes. That is the kind of problem you do not encounter until the system is already down.
Staffing Models That Actually Work
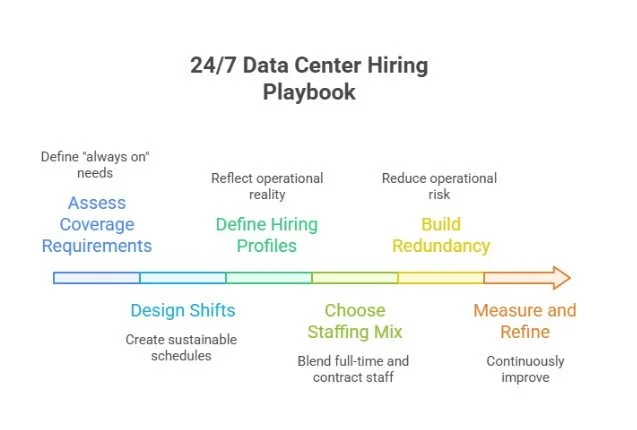
The naive approach hires people to sit at desks around the clock. This is unsustainable and rarely effective because alert fatigue destroys human attention spans after about four hours of continuous monitoring. The actual working model relies on shift rotations combined with automation that filters noise. A typical support rotation might run four shifts: early morning, afternoon, evening, and night. Each shift needs at least two qualified people so that bathroom breaks and shift overlaps do not leave the line empty. For technical on-call, most teams use a rotating pager model with a designated primary and secondary engineer. The primary responds first. The secondary covers if the primary is unreachable or needs backup. You rotate weekly or biweekly depending on team size. A team of six engineers typically rotates on-call every six to eight weeks. A team of twelve rotates monthly. Anything longer and the person carrying the page becomes a bottleneck and everyone else forgets the procedures. I built an on-call rotation schedule for a small platform that used a custom Python script generating iCalendar files synced to each engineer's work calendar. The script tracked escalation windows, time-off requests, and burnout thresholds. It flagged when someone had covered more than three weekends in a rolling sixty-day window. Without that tracking, two engineers absorbed nearly double their fair share for four months before anyone noticed because nobody wanted to be the person complaining.
Get the Full Details

Architecture Choices For Uninterrupted Operation
The technical side breaks down into redundancy, failover speed, and automated recovery. Redundancy means having at least two independent paths for any critical component. If one database server dies, another must pick up without manual intervention. Failover speed is measured in seconds or milliseconds depending on your SLA. Automated recovery means health checks, self-healing scripts, and container orchestration restart loops that do not require a human to log in. Load balancing across geographically distributed regions is standard for anything above two nines. AWS Route 53 latency-based routing, Azure Traffic Manager, and Cloudflare Anycast are common choices. The configuration is straightforward. The tuning is not. You will spend weeks adjusting TTL values, health check intervals, and failover thresholds to avoid flapping. A health check that runs every ten seconds with a three-consecutive-failure threshold will cause unnecessary failovers during brief network blips. A check that runs every sixty seconds with a two-consecutive-failure threshold will miss real failures for too long. The sweet spot depends entirely on your workload. Microservices architectures make 24/7 both easier and harder. Easier because a single failing service does not necessarily take down the entire system. Harder because you now have dozens or hundreds of services to monitor, and a cascading failure can propagate faster than any human response time. Circuit breakers and bulkhead isolation patterns are essential here. Without them, one slow downstream dependency can consume all available threads and stall the entire stack.
Monitoring Is Not The Same As Alerting
Every 24/7 operation needs a monitoring layer. Prometheus, Datadog, New Relic, and Grafana cover most modern stacks. These tools collect metrics, logs, and traces. The important distinction is that monitoring is passive data collection. Alerting is the automated decision to interrupt someone. You should separate the two. Good monitoring gives you visibility. Bad alerting gives you a smartphone vibrating at 2 AM for a non-critical issue that could wait until 9 AM. I configured an alerting pipeline that evaluated severity before paging anyone. Metrics falling below warning thresholds triggered dashboard updates. Only metrics breaching critical thresholds with sustained duration triggeredPagerDuty pages. This reduced false page volume by about seventy percent within the first month. The dashboard still showed the same data. Engineers only woke up for things that actually required action. Nobody thanked me at first because the dashboard looked exactly the same, but the sleep quality improved noticeably.
The Hidden Costs Nobody Talks About
Beyond infrastructure and staffing, 24/7 operations carry significant organizational costs. Documentation decays faster because there is no downtime buffer for housekeeping. Hiring is harder because candidates with families or health constraints self-select out. Turnover increases in sustained on-call roles even with proper rotation. Compliance overhead grows because regulated industries require audit trails that span every hour of every day. There is also the legal and reputational dimension. When a system operates 24/7, the expectation shifts. Users assume it always works. A four-hour outage on a system marketed as "always on" generates significantly more backlash than the same outage on a system that admits limited hours. The marketing promise creates a higher legal exposure window for breach claims. Read your SLA carefully before you publish an availability number you cannot guarantee.
When 24/7 Is The Wrong Decision
Not every system needs continuous operation. Internal tools, batch processing pipelines, development environments, and low-traffic informational sites perform better on scheduled availability windows. A system that runs Monday through Friday from 7 AM to 11 PM Eastern time costs less, requires fewer staff, and produces higher quality engineering because the team has predictable rest periods. You save money and reduce burnout simultaneously. If your user base is predominantly in one or two time zones and your service does not handle emergencies, consider a 16/7 or 20/5 model instead. Customer support can still offer next-business-day responses for non-urgent tickets while engineers maintain normal schedules. This approach works well for B2B SaaS platforms, content management systems, and educational software. It fails for anything involving financial transactions, medical alerts, emergency communications, or global e-commerce with real-time inventory needs.
Practical Steps To Start Implementing 24/7
Begin with a clear definition of what 24/7 means for your specific service. Is it application uptime, database availability, or full end-to-end customer support? Write it down. Pick a target availability percentage and calculate the acceptable annual downtime. Build a baseline monitoring setup before you add redundancy. You need to know what normal looks like before you can detect when it goes wrong. Invest in automated health checks and synthetic transactions that simulate real user flows at all hours. Deploy a simple on-call rotation before scaling up. Iterate from there. Most teams underestimate the documentation requirement. Everything that matters to the system must be written down in a way that someone half-asleep can follow at midnight. The reality of 24/7 operations is not glamorous. It is spreadsheets, on-call calendars, redundant servers in different availability zones, and a permanent low-grade anxiety that one poorly configured health check will cost you a weekend. The systems that survive do so because they were built deliberately with failure as a constant assumption rather than an exception. If you are willing to accept the cost and the lifestyle impact, it works. If you are doing it because marketing told you customers expect it, you should reconsider the scope before you commit resources.