A Practical Guide To Finding And Resolving Ambiguity In Legal Text Datasets
What Does Precisely Mean Pinpointing Ambiguity In Language Law And Data
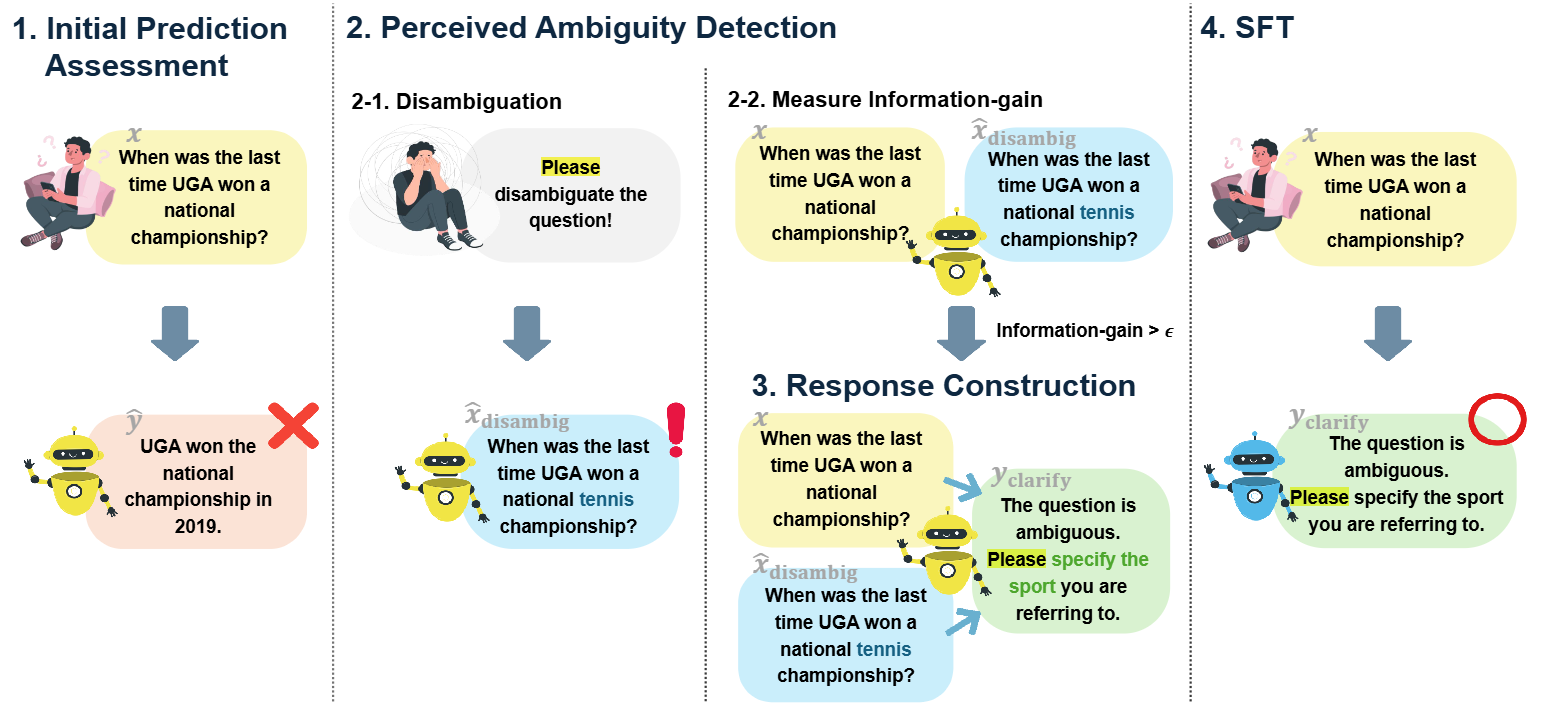
The phrase itself points to a specific workflow. You are taking legal or regulatory language and determining exactly where meaning breaks down, varies between sources, or cannot be reliably mapped to a structured data field. This is not a theoretical exercise. It is something you do when your NLP pipeline keeps misclassifying contract clauses, or when a compliance system returns conflicting signals on the same input. The goal is to stop guessing and start cataloging every point of uncertainty with enough detail that another human or model can resolve it later. Legal language is written to be deliberate, which means it is full of hedging, cross-references, jurisdictional exceptions, and defined terms that only make sense in context. When you strip that context out and try to extract structured fields, ambiguity surfaces immediately. A single phrase like "within a reasonable time" might appear in dozens of clauses across different contracts, but each one means something slightly different depending on the surrounding obligations, the type of party involved, and the industry standard in that jurisdiction. I worked on a project last year where we were building a dataset of vendor agreement clauses to train a model that could flag non-standard renewal terms. We had about 40,000 contracts from the technology sector. The model kept performing well on known patterns and then completely failed on anything involving notice periods tied to performance milestones. The problem was not data volume. It was that "performance milestone" was defined differently in nearly every agreement. Some contracts tied it to revenue thresholds, some to delivery dates, some to acceptance testing, and a few didn't define it at all but referenced an exhibit that was missing. No amount of training data could fix that without first resolving the underlying ambiguity in the source material.
The Method I Use For Pinpointing Ambiguity
Start with extraction, not classification. Most teams jump straight into labeling data or fine-tuning a model, but that is backwards. You need to understand what the ambiguity looks like before you try to solve it. I pull the raw text first, run a basic extraction pass to get clauses into individual records, and then read through them without trying to force them into categories. The actual pinpointing happens in three layers. First, I identify lexical ambiguity, which is when a word or phrase has multiple possible meanings within the legal domain. Terms like "delivery," "acceptance," "force majeure," and "material breach" all have standard definitions, but those definitions shift depending on context. Second, I look for structural ambiguity, where the relationship between clauses is unclear. Does obligation A modify obligation B, or are they independent? Is a limitation of liability capped globally or per incident? These are harder to spot because they require reading across paragraphs rather than examining a single sentence. The third layer is contextual ambiguity, which is the most frustrating one. This is when the meaning of a clause depends on information that is not present in the text itself. A clause might say "as defined in Exhibit C" and Exhibit C is on a different page, or it might rely on a definition from a master agreement that was not included in your dataset. I have seen entire training sets built on clauses that were meaningless without their referenced exhibits. The model learns patterns that do not actually exist in the wild because the data was incomplete from the start.
A Specific Workaround I Developed
During that vendor agreement project, I hit a wall with the renewal term clauses. The model was predicting "standard renewal" for anything that contained the word "renewal" even when the clause specified a different notice period or required mutual consent. I spent about two weeks manually reviewing a subset of 800 contracts and building a decision tree that forced every clause through a series of disambiguation questions before it could be labeled. The decision tree looked like this: does the clause specify a notice period? If yes, what is the timeframe? Is the notice period measured in calendar days or business days? Does the clause require affirmative action from the vendor, or is it automatic? Is there a cap on the number of renewals? Each answer narrowed the possible classifications. I then used this tree to re-label the entire dataset, which took about three days of focused work. The model's F1 score on renewal terms jumped from 0.61 to 0.84 after the re-labeling. That is a concrete example of why pinpointing ambiguity before training matters more than anything else in this process.
Get the Full Details

Tools That Actually Help
You do not need expensive software for this. I use a combination of regular expressions for pattern detection, a custom Python script that flags undefined terms by cross-referencing them against a glossary I maintain, and a simple spreadsheet for tracking every ambiguous clause I find. The spreadsheet columns are: clause ID, text excerpt, type of ambiguity, suspected cause, resolution needed, and current status. This sounds basic but it is the most useful tool in the workflow because it forces you to make a decision on every ambiguous item rather than skipping past it. For larger-scale projects, I recommend using a semi-automated approach where an LLM pre-screens clauses for potential ambiguity and highlights them for human review. The model should never be the final arbiter. LLMs are particularly bad at distinguishing between stylistic variation and genuine ambiguity. They will flag a clause as ambiguous because it uses unusual phrasing, even when the meaning is perfectly clear. I use them as a first pass to reduce the volume of text I need to read manually, not as a replacement for actual analysis.
Common Mistakes To Avoid
The biggest mistake I see is treating all ambiguity as the same problem. It is not. Lexical ambiguity requires a different resolution strategy than structural ambiguity, which in turn requires something different from contextual ambiguity. If you try to solve all three with the same tool, you will get mediocre results across the board. Another mistake is stopping the pinpointing process too early. You will encounter ambiguity that is easy to spot and ambiguity that hides deep inside a nested clause. The easy ones get fixed first, which gives you a false sense that the dataset is clean. It is not. A third mistake is documenting ambiguity without resolving it. I have seen datasets where the annotators flagged ambiguous clauses and left them unlabeled, expecting the next person to figure it out. That does not work. If a clause is ambiguous and you cannot resolve it with the information available, either exclude it from the training set or mark it as unresolvable with a detailed explanation of why. Leaving it in the dataset as "uncertain" just teaches your model to be uncertain everywhere.
When This Approach Fails
Pinpointing ambiguity does not work well when the source documents are themselves contradictory across jurisdictions. If you are working with international contracts where the same term has legally different meanings in different countries, no amount of disambiguation will give you a single clean label. In those cases, you need to segment the data by jurisdiction first and treat each segment as a separate problem. It adds complexity but it is the only honest way to handle it. Another scenario where this breaks down is when the dataset is too small to support meaningful pattern recognition. If you have fewer than 500 documents and the ambiguous clauses are scattered across many different types, you may not have enough signal to build a reliable decision tree. In that case, the most practical approach is to hire a domain expert to review the ambiguous subset manually and create a targeted glossary rather than trying to automate the whole thing.
What Does Precisely Mean Pinpointing Ambiguity In Language Law And Data
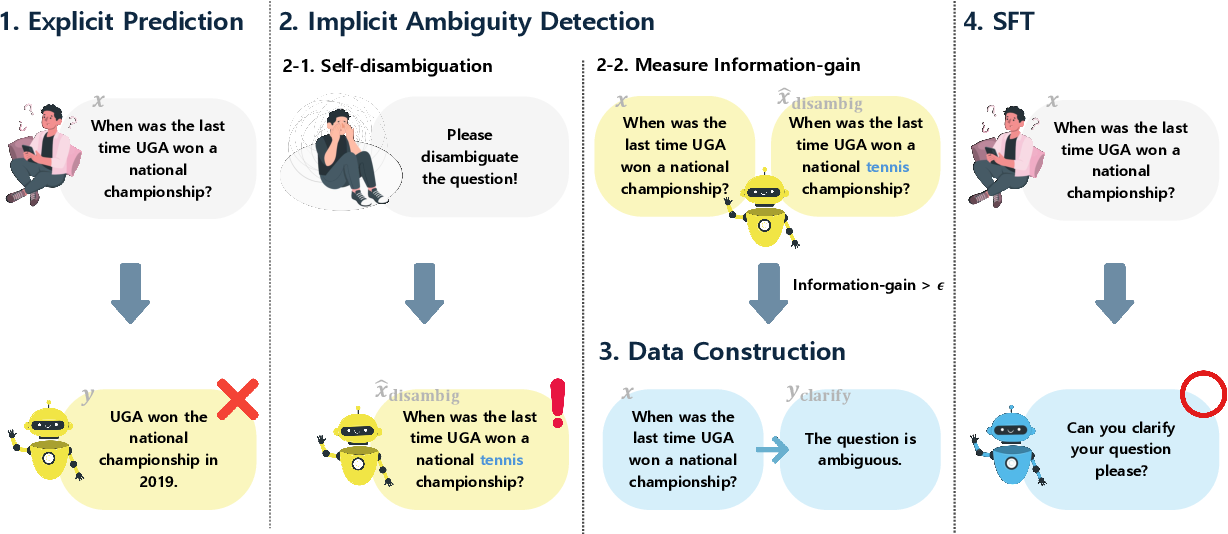
It means systematically identifying where legal text resists clean classification, understanding why it resists, and creating enough documentation and structured labels that downstream systems can either work with the data as-is or flag the problematic cases for human review. It is tedious. It requires reading actual legal text instead of treating it as tokens to be processed. And it is the only reason I have been able to build datasets that actually perform outside of controlled environments. If you are starting this work, begin with a small subset of your data, read every clause manually before writing a single line of automation code, and build your decision tree from what you actually find rather than from what you expect to find. The two hours you spend on that initial reading will save you two weeks of debugging a model that learned the wrong patterns because the underlying data was ambiguous and nobody checked.