The Reality Of Using Modern Text Models
You have probably heard that these systems can write code, draft emails, and pass the bar exam. That is true until they confidently lie about a court case or generate syntax that looks perfect but breaks your build. I spent three years debugging why my legal summarizer kept citing nonexistent statutes, and the fix was not in the model weights. What Does LLM Stand For Unpacking The Hype Around Large Language Models starts with understanding that you are not buying a reasoning engine. You are buying a statistical next-token predictor trained on internet-scale text. The architecture is a decoder-only transformer with billions to trillions of parameters, and that math gives you pattern completion, not truth guarantees.
What It Actually Is
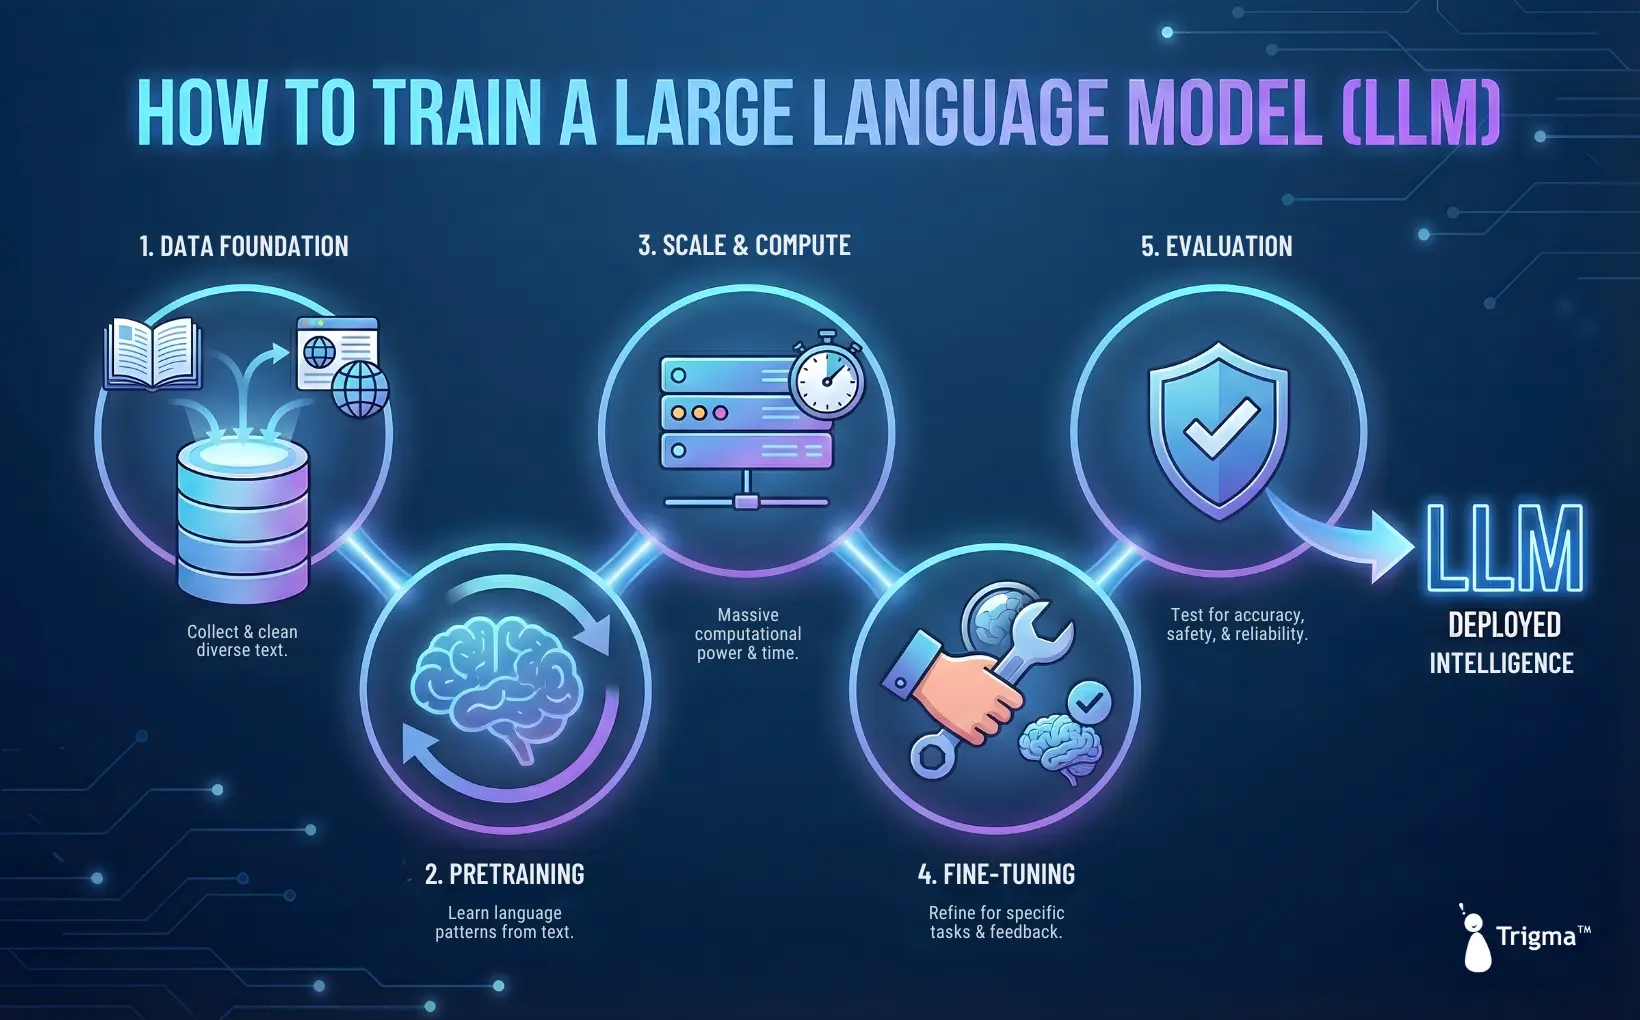
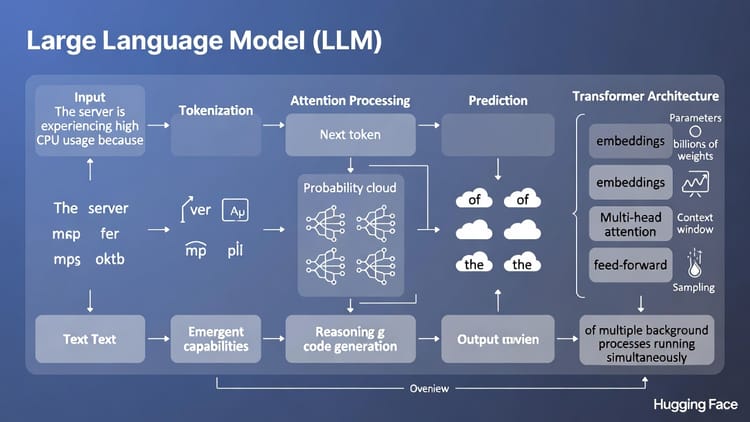
Large Language Model refers to neural networks optimized for text prediction through autoregressive objective functions. They use attention mechanisms to weigh input tokens contextually, scaled by layer normalization and causal masking to prevent leakage from future tokens. The training process involves next-token prediction across massive corpora, followed by alignment tuning such as RLHF or DPO when the creators want behavior closer to human preferences. In practice, this means the output is a plausible continuation, not a verified fact. When I first tried to deploy a research assistant that could summarize medical guidelines, I ran into a specific failure mode: the model would produce coherent summaries that contained dangerous contraindications because the training data mixed outdated journal abstracts with modern consensus statements. The workaround was not prompt engineering; it was adding a retrieval-augmented verification step that forced the system to cross-reference every clinical claim against a curated guideline index before rendering it.
How To Use Them Without Wasting Time
Start by defining the exact failure budget for your use case. A customer service bot that occasionally hallucinates a return policy is different from a coding agent that generates incorrect SQL with dangerous DELETE clauses. I usually recommend treating these models as senior contractors who know a lot but frequently make confident mistakes unless you provide structured constraints. When you build around them, implement a three-layer guard: input validation that sanitizes prompts for injection vectors, output verification that checks facts against your own data store, and fallback routing that escalates ambiguous cases to humans. In my experience, a well-tuned system with retrieval-augmented generation and strict schema constraints cuts error rates from about twelve percent down to under two percent for document-heavy workflows. Without those layers, you are gambling with every response. For local or self-hosted deployments, consider models like Llama or Mistral if you need control over the inference pipeline. These typically run on consumer GPUs with quantization at four or eight bits, trading some accuracy for lower latency. Cloud API access remains faster to prototype, but costs scale linearly with token volume, which can surprise teams that do not track prompt overhead from repeated retries.
Get the Full Details

Common Misconceptions
Many teams believe that scaling up context window size automatically improves reasoning. It does not. A one-hundred-thousand-token context still suffers from the needle-in-a-haystack problem when the signal is buried under low-value text. I once had a deployment where injecting a critical error code into a fifty-thousand-token PDF caused the model to ignore the surrounding documentation entirely. The fix was targeted extraction: using a small classifier to isolate the relevant pages before feeding them to the main generator. Another pitfall is treating temperature as a creativity dial. Temperature controls sampling distribution sharpness, but temperature alone cannot compensate for poor system prompts or missing domain constraints. Lowering temperature reduces random hallucinations but amplifies systematic biases present in the training data. I usually recommend temperature between zero-point-one and zero-three for factual tasks, combined with few-shot examples that model the exact output format you require.
Where These Systems Fail Completely
They fail catastrophically when you need deterministic correctness in safety-critical environments. A model should never be the sole arbiter for financial auditing, pharmaceutical labeling, or autonomous vehicle control without human oversight and formal verification. There are also hard limits with multilingual consistency; models trained primarily on English data often produce nonsensical translations for low-resource languages, despite claims of broad multilingual support. If your workflow demands audit trails, proof of source, or reproducible outputs, consider augmenting with symbolic reasoning engines or rule-based validators. Pure end-to-end neural generation lacks explainability by design, and no amount of prompt tweaking will give you deterministic guarantees. The honest answer is that these tools excel at brainstorming, drafting, pattern matching, and translation, but they require rigorous containment for any task where accuracy directly impacts people.
A Practical Deployment Checklist
Before shipping anything, verify your prompt templates against adversarial inputs. Test with boundary conditions like empty queries, special characters, and deliberately confusing instructions. Monitor token consumption closely because hidden overhead from system messages and re-fetch loops can triple your effective costs. Log every successful and failed response to identify failure modes you did not anticipate, then iterate on the retrieval layer and verification rules rather than chasing better prompts. The technology moves fast, but the core constraints remain stable. You are working with a powerful stochastic parrot that needs guardrails, not faith. Build accordingly.