So You Want To Understand Deceptive Language
Deceptive language is just language designed to make someone believe something that isn't true, or to make them overlook something important. That sounds almost tautological, but the actual mechanics beneath that definition are worth examining because most people only encounter it at surface level — a headline that misleads, a product claim that waffles, a sentence where the grammar makes two interpretations possible and the speaker intends only one. I work with text analysis, mostly in the context of automated moderation and content evaluation, and I can tell you that spotting deception isn't about finding "obviously false" statements. The things people get caught on are usually honest mistakes or sloppy phrasing. The genuinely deceptive content is constructed to look ordinary. It passes casual reading.
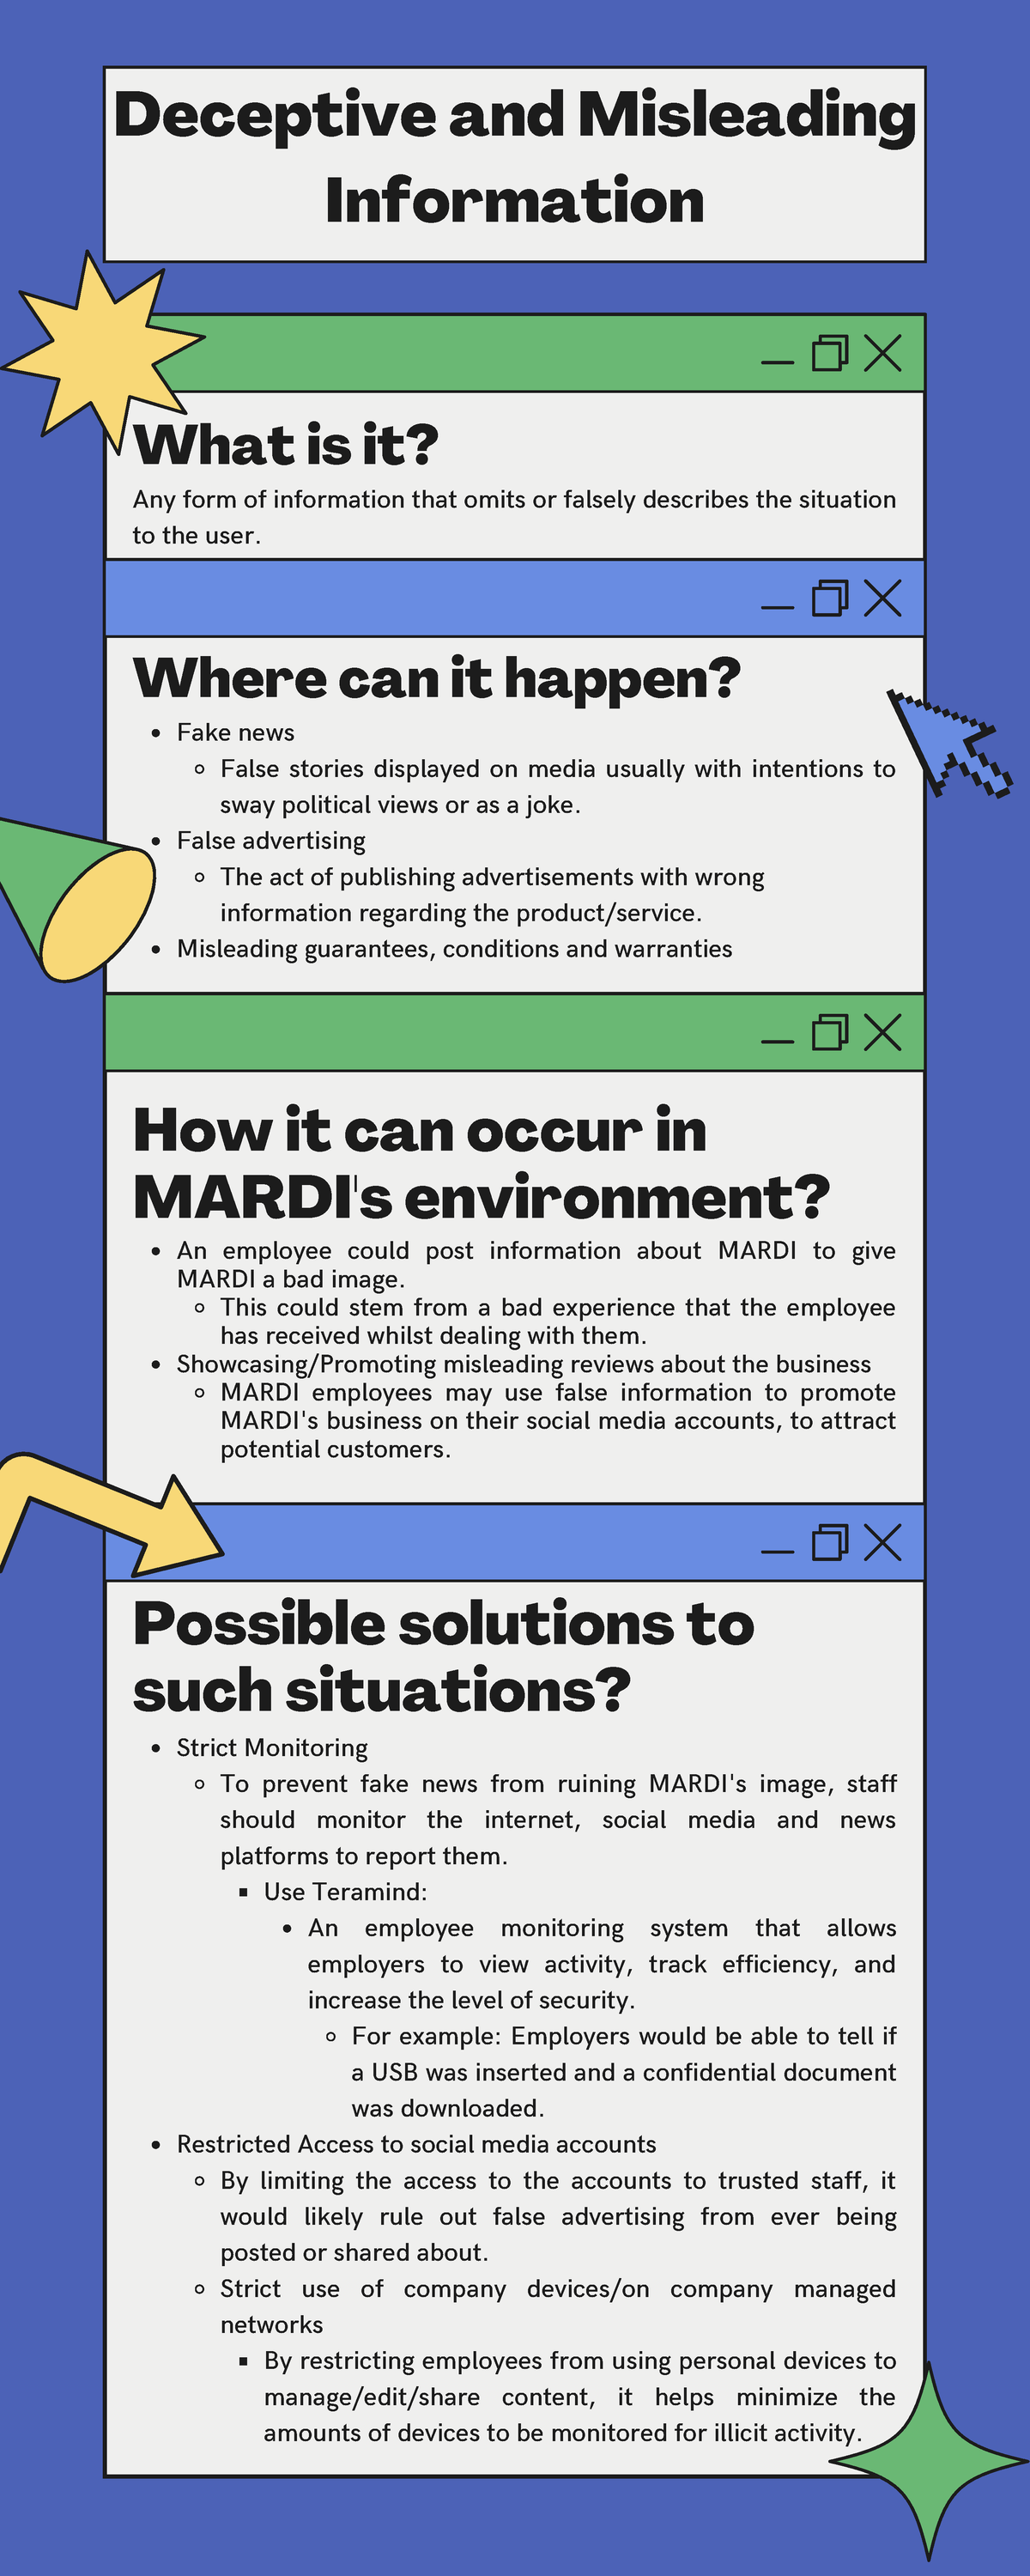
What Does Deceptive Mean Unpacking The Mechanics And Impact Of Misleading Information
At the core, deception in language operates on three axes: omission, distortion, and misdirection. Omission means leaving out a detail that would change interpretation. Distortion means actively presenting something in a way that diverges from reality. Misdirection means steering attention toward something irrelevant while the actual claim goes unexamined. The tricky part is that these three mechanisms frequently overlap in a single sentence. Consider this kind of product copy: "Our formula is clinically proven to support healthier skin. Results may vary."
On the surface that looks like an honest disclaimer, but look closer. "Clinically proven" doesn't tell you what was tested, against what, or whether the trial was statistically significant. "Support healthier skin" uses a verb that implies function without committing to a measurable outcome. The disclaimer about varying results doesn't actually hedge the claim — it's boilerplate. This is omission dressed up as transparency. In my work parsing marketing copy for a compliance client, I spent three weeks tracking down one particular ad campaign that used this exact structure across forty-seven landing pages. Every page was individually approved by legal. They were all technically defensible. None of them actually said anything that could be verified. The workaround I used was building a constraint check — a script that flagged any claim containing unmodified comparative superlatives or unverifiable health-related verbs like "support," "promote," or "enhance" when paired with a single generic disclaimer. It cut our review time from about two hours per page down to roughly twelve minutes. Here's something most people don't consider when evaluating deceptive language: the most reliable signal often isn't in the words themselves but in the grammatical structure around them. Research in computational linguistics has shown that deceptive text tends to use fewer first-person pronouns and fewer causal connectors. The writer is subtly distancing themselves from the claim and avoiding making explicit logical links between evidence and conclusion. That's not a hard rule — it's a statistical tendency that holds across domains, from political speech to product reviews.
Get the Full Details

I once ran into a case involving a marketplace seller who had a pattern of listing items as "brand new" while including photos clearly showing used packaging and wear. Their text descriptions were spotless — proper grammar, complete sentences, zero red flags by conventional standards. The deception was entirely visual, but the language did the heavy lifting by anchoring the buyer's expectation before they examined the images. When I built a detection model around this, the most predictive features weren't linguistic at all. They were cross-modal — mismatch signals between text description and image metadata. That was a genuinely counter-intuitive result. The language wasn't deceptive. It was normal. The deception lived in the gap between modalities. If you're trying to build systems or processes that catch deceptive language, the common pitfall is optimizing for false positives instead of false negatives. You'll catch more noise if you cast a wide net, but you'll also waste resources on legitimate content. A better approach is building multi-layered detection where basic linguistic signals feed into a second layer that evaluates context — source credibility, claim verifiability, and internal consistency across multiple statements from the same author or organization. There are tools available if you want to get practical about this. Some open-source options include the LIWC dictionary for psycholinguistic analysis, which gives you ready-made feature counts on pronoun usage, emotional tone, and cognitive processing words. There's also the Berkeley Argument Reasoning Classification task dataset if you want labeled training data. For the detection models themselves, transformer-based classifiers trained on the LIAR dataset or the FakeNewsNet collection tend to perform adequately, though they're far from production-grade on their own.
A word of caution: no automated system currently achieves reliable deception detection below roughly seventy percent accuracy on out-of-domain text. That means if you're deploying this for content moderation, plan for significant manual review overhead. The systems work reasonably well on text that resembles their training distribution — political falsehoods, product scams, generated fake reviews — but they degrade quickly when the deceptive patterns shift. I've seen models trained on political discourse perform poorly on commercial content and vice versa, sometimes with accuracy dropping into the low sixties. Another limitation worth noting is that the field conflates deception with misinformation and disinformation without always distinguishing between them. Misinformation is false content shared without harmful intent. Disinformation is false content shared with the intent to deceive. Deceptive language can appear in all three categories, but the detection strategies differ substantially. Disinformation often employs coordinated inauthentic behavior — multiple accounts amplifying the same narrative — which is better detected through network analysis than linguistic analysis. If you're only looking at the text, you're missing half the picture. For anyone actually working with this, I'd recommend starting with a narrow scope. Pick one domain — say, e-commerce product claims or news headlines — and build detection around that. General-purpose systems fail because the linguistic markers of deception vary by context. A financial prospectus uses different hedging patterns than a political tweet. Understanding the specific ecosystem you're operating in matters more than any sophisticated model you could throw at the problem.
The impact of deceptive language extends well beyond individual instances of bad content. When systems fail to catch it reliably, the cost accumulates — consumers lose money, platforms lose trust, and the cost of verification falls on everyone who has to double-check what should be straightforward claims. That's why getting this right, even incrementally, matters more than the usual tech-industry hand-waving about "AI helping humans make better decisions" suggests.
.jpg?width=790&height=1975&name=Misleading and Deceptive Conduct Infographic (1).jpg)


