Application Programming Interface
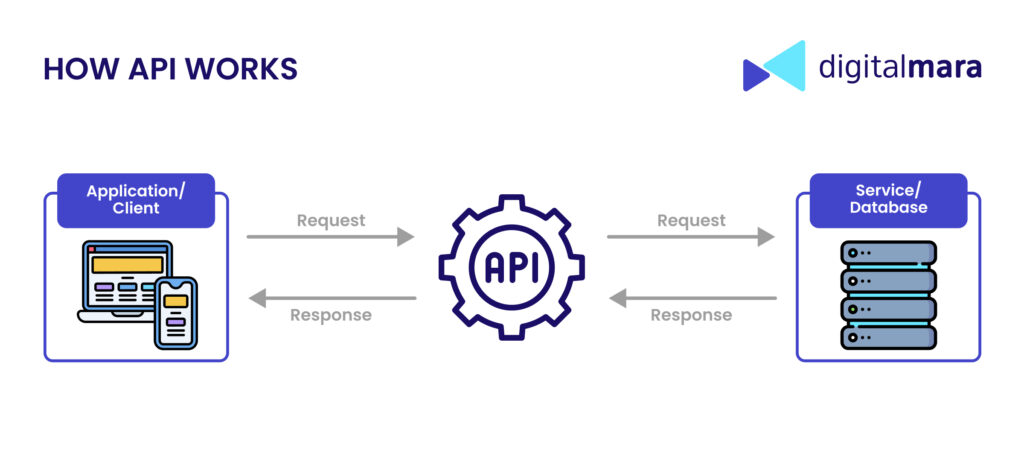
API stands for Application Programming Interface. That is the acronym. What comes after it is a set of rules and protocols that let two pieces of software talk to each other without either one needing to know how the other works internally. I have spent more years than I care to count debugging integration problems, and the first thing I always check is whether the API contract was followed. Sometimes the issue is not code quality at all. It is a mismatch in what one system expects and what the other actually sends.
What Does API Stand For Decoding The Acronym Powering Modern Software
When I first started working with APIs in the mid-2000s, they were mostly SOAP-based XML endpoints wrapped in layers of middleware. Everything was verbose. Every request looked like a novel. Moving to REST and JSON made things faster and easier to reason about, but it also meant developers shipped integrations without thinking about error handling, rate limits, or versioning. That habit has not fully gone away. An API is really just a boundary. It defines what you can ask for, what format the response comes back in, and what happens when something goes wrong. The best APIs make the contract obvious. The worst ones force you to guess by reading source code or trial-and-error testing. Here is how I actually approach building or consuming an API in practice. First, I map out the data flow before writing a single line of request code. What inputs does the endpoint need? What are the possible response shapes? Which fields are optional and which are required? I write that down in a plain text file. It sounds tedious, but it cuts integration time roughly in half compared to jumping straight into coding.
Second, I validate responses early. A lot of developers skip this because the API worked in the sandbox. Production environments have different data, different timing, and different failure modes. I run every response through a basic schema check before any business logic depends on it. In one project last year, an external payment API returned a null value for a field that was never null in test, and we caught it before it made it into production. Without that check, the downstream service would have crashed on the first transaction. The practical part of working with APIs involves understanding what they are not. An API is not a database. You should never treat an API call like a direct table query. Every request introduces latency, state changes, and potential side effects that a simple SELECT statement does not. When I see teams looping through records and hitting an API once per item instead of using bulk endpoints, it usually takes thirty times longer than it should and eats through rate limits in minutes. Another thing beginners consistently miss is that API documentation is often a best-case summary. The real behavior lives in the edge cases. I learned this the hard way when integrating a shipping carrier API that documented successful responses as JSON objects with a status field. What it did not document was that under certain geographic conditions, the same endpoint would return an HTTP 200 with an empty body and no status field. Our parser expected a field that was not there, and it threw a null reference error in the middle of a checkout flow during peak hours. The fix was adding a fallback handler for unexpected empty payloads. I still check for those empty-body returns on any integration that touches external services.
Get the Full Details
GraphQL exists and it solves some real problems around over-fetching and rigid schemas. But it also introduces new ones. Caching becomes harder. Monitoring becomes harder. And many third-party services do not offer GraphQL at all. REST APIs are simpler to cache, easier to debug with standard HTTP tools, and widely supported. If you are starting a project and do not have a specific reason to choose GraphQL, REST is usually the safer bet unless your team already has GraphQL expertise in place. Rate limiting is another area where documentation and reality diverge. An API might advertise a limit of one thousand requests per minute, but that limit is often shared across all endpoints in a category. If you blast one endpoint at the limit, the entire category gets throttled and other endpoints start returning 429 errors too. I configure request pacing with a small buffer below the stated limit. It costs a bit of throughput but prevents cascading failures when the provider's internal counters are slightly off or when you are sharing a quota with another service. Authentication patterns matter more than most people realize. API keys are convenient but weak. OAuth 2.0 with short-lived access tokens and refresh token rotation is the standard for a reason. I have seen projects use static API keys in client-side code because it was simpler to implement. That is a security problem waiting to happen. Keys leak into version control, into browser dev tools, into logs. The fix is always to move the token exchange to a server-side proxy.
Versioning is another detail that gets ignored until it causes damage. APIs change. Fields get deprecated. Responses shift format. I recommend treating the API version as part of your deployment configuration, not as something you discover at runtime. Pin your version. Test against it. Update it deliberately with a change management process. The team that skips this usually finds out when a production incident traces back to an undocumented field rename. If you are looking for a starting point to work with APIs, the general approach is straightforward. Pick an API, read the documentation on the base URL and authentication method, make a simple request with curl or Postman, verify the response shape, then write your integration. The hard part is not the first request. It is the hundredth request when something subtle breaks and you need to figure out whether it is your code, the API, or the network between them. One tool I find myself coming back to is a request logging layer that captures the full request and response including headers and timing. It sounds like overkill until you are trying to diagnose whether a three-second delay is coming from your client, the network, or the API server itself. With that log, you can usually narrow it down in under five minutes instead of spending an afternoon wondering where the time is going.
I also keep a local copy of the API spec whenever one exists. Swagger files, OpenAPI documents, whatever format the provider ships. Having the schema locally lets you generate typed client code and run validation before a request ever leaves your machine. This catches a surprising number of issues that would otherwise surface only in production. The reality of working with APIs is that they are neither elegant nor predictable. They are interfaces built by different teams, with different priorities, under different constraints. Some are well-designed. Some are adequate. Some are barely functional and held together by community workarounds. Your job is not to hope for good APIs. Your job is to build systems that tolerate bad ones.