On actually seeing what a city is
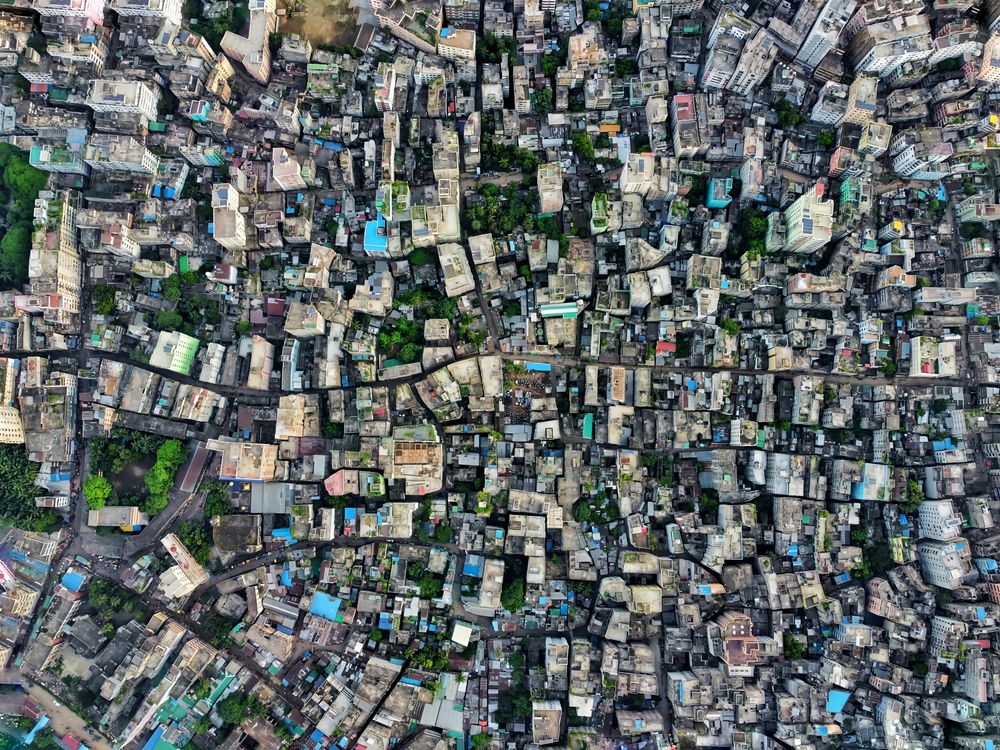
Most people think they know what an urban landscape is. They picture skylines from above or the grid of streets from a satellite map. That is not what it looks like. It looks like mismatched infrastructure sitting on top of older infrastructure, with every layer half-repaired and never fully planned. You can spend years studying cities on paper and still miss the part that matters.What Does A City Really Look Like Unpacking The Urban Landscape
The practical way to unpack this starts with ground-level observation combined with layered data. You need to walk or bike through neighborhoods at different times. Then you pull zoning maps, parcel records, transit frequency, and historical aerials. You compare them. The mismatch between what the map says and what the street actually shows is where the real picture lives.I used to rely on aerial photos alone when I was younger. One neighborhood in particular threw that approach apart completely. The zoning map showed mixed residential and commercial, the parcel data suggested a dense corridor, but the actual street had been split by a freight rail line in the 1970s and never reconnected. Pedestrian flow hit a hard wall. Transit stops sat on one side. Workers crossed illegally at two points because the legal overpass was a quarter mile away. The city looked fine on paper. It did not look fine in reality. The workaround was simple but tedious. I started pulling traffic count data, cross-referencing it with pedestrian injury reports and bus ridership by stop. Then I walked every block myself during morning and evening commute windows. What the numbers hid became obvious in person. The real urban landscape is made of these friction points. They are usually invisible until someone forces you to look at them.
How to actually read a city layer by layer
You do not need a fancy tool to start. You need a method that forces you to see the gaps between datasets. Most people merge maps and call it analysis. That produces pretty pictures and wrong conclusions. The better path is to treat each data layer as suspect until you verify it against physical evidence. Step one is zoning and land use. Pull the current zoning map for your target area. Note the color codes. Then go outside. Zoning maps rarely capture informal use. A lot marked “light industrial” might run a warehouse by day and a pop-up market by weekend. The map does not record that. You do. Step two is transportation and movement. Get the transit schedule and count actual arrivals for one hour. Timetables assume perfect reliability. They are wrong. Buses skip stops. Trains delay. The real service level is what you measure, not what the PDF says. I once found a bus line scheduled every twelve minutes that effectively ran every twenty-eight because of crew scheduling gaps. The route existed on paper. The service did not. Step three is parcel and property data. This is where most projects stall. Parcel boundaries are messy. Owner names change. Vacant lots get recorded under shell companies. Tax assessments lag behind market shifts by years. The workaround here is to cross-reference with building permit records and utility connection data. If a parcel shows a single-family home but the water meter records double the residential usage, something else is happening there. You check physically. Step four is historical context. Pull Sanborn fire insurance maps if they exist for your area. These show building footprints from the early 1900s and often reveal street alignments that were paved over. You will spot alleys that no longer exist, foundations of demolished structures, and infill patterns that modern maps hide. This layer explains why a road curves for no reason or why a block feels misaligned with its neighbors.Counter-intuitive truths most beginners miss
The first truth is that density is not the same as livability or even functionality. High-density areas often have worse pedestrian experience because density alone does not dictate sidewalk width, shade, crossing frequency, or enclosure. You can build towers on top of empty plazas and call it dense. It is not. It is concentrated emptiness. The second truth is that the most important urban features are often the ones with no data. Stormwater catch basins. Informal pathways worn into grass. Property lines that shifted due to a river moving three inches a year. These do not appear on standard GIS layers. They only show up when you walk long enough to notice patterns in wear, drainage, and desire lines.I spent weeks trying to understand why a particular commercial corridor failed despite good foot traffic. The data said everything should work. The street lighting was adequate. Retail vacancy was below city average. Transit stopped two blocks away at worst. The problem turned out to be a single sidewalk bump caused by a tree root lifting one section by roughly four inches. Not illegal, not dangerous enough to fix, but enough to make strollers, wheelchairs, and carts bounce repeatedly. People avoided the path without knowing why. The fix was a simple grind. The insight came from watching someone struggle with a grocery cart at exactly the wrong spot.
Tools that actually help versus tools that just look nice
ArcGIS or QGIS will handle your map layers. Use whatever you already know. The value is not in the software. It is in how you stack the data. OpenStreetMap exports are useful for street networks but unreliable for pedestrian infrastructure. They often omit crosswalks, curb cuts, and sidewalk presence entirely. Verify with fieldwork. For historical comparison, the Library of Congress has digitized Sanborn maps for many U.S. cities. Local planning departments hold parcel data but often behind slow web portals. If you need speed, FOIA requests for raw GIS shapefiles usually get you cleaner data than what sits on public websites.One thing I learned the hard way: do not trust automated overlap tools between zoning and parcels without manual spot checks. I once ran a script that flagged fifty “violations” in a neighborhood. After walking the sites, eight were legitimate. The rest were either old data not updated after subdivisions, or parcels split before the current zoning map was drawn. Automation without field validation produces noise dressed as insight.
Get the Full Details
Where this approach breaks down
It does not scale well across large regions. Walking and cross-referencing is slow. You might spend forty hours producing a solid analysis of a three-square-mile area. That is not a complaint. It is a boundary condition. If you need citywide coverage, you sacrifice depth. Accept that tradeoff upfront. Historical data is incomplete for many cities. Smaller municipalities never produced Sanborn maps. Some cities lack detailed parcel archives before the 1990s. You will hit dead ends and have to infer from tax records or newspaper archives instead. The method still works, but the evidence chain weakens. Finally, this approach does not predict future development. It reveals current reality and historical cause. If you want forecasting, you need separate models fed by different inputs. Mixing description with prediction is how bad urban policy gets justified.The city is not a puzzle to solve. It is a record of decisions, accidents, maintenance cycles, and adaptation. What it looks like depends entirely on how deep you are willing to look. Most people stop at the satellite view. The actual landscape shows itself only if you keep going.