Latency in Practice
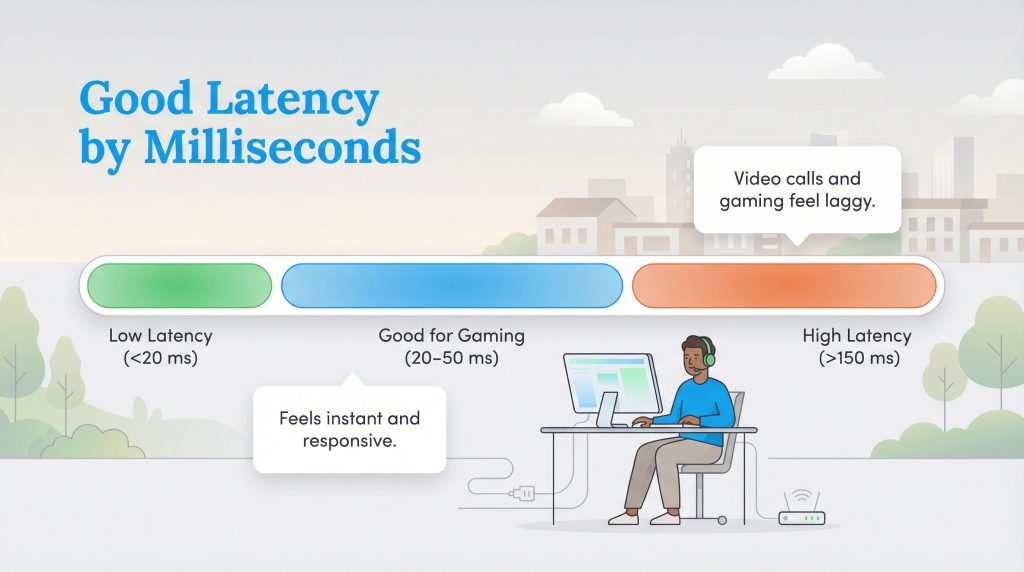
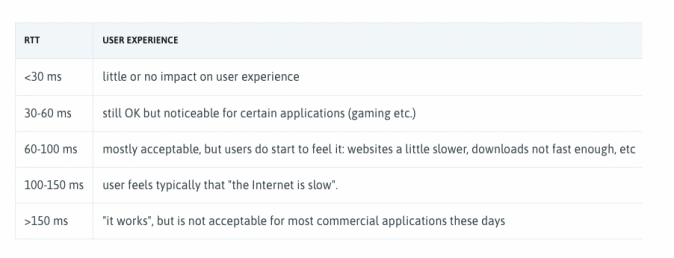
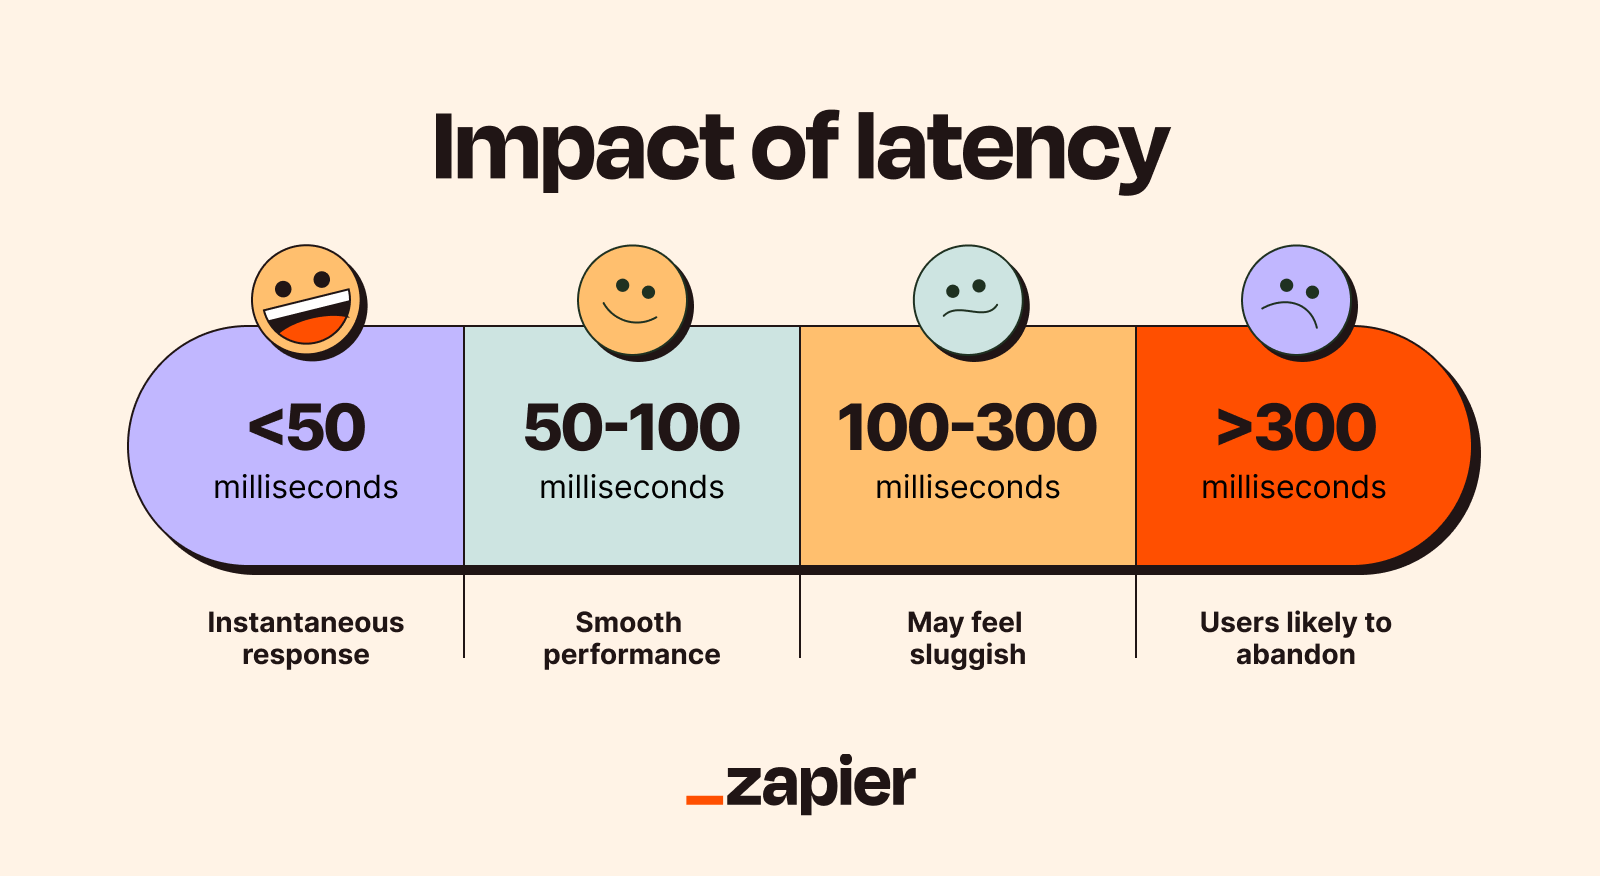
Most people look at a number like 60 milliseconds and have no real idea what that translates to in their actual workflow. The gap between theoretical speed and what you experience day to day is wider than most benchmarks show. I spent years tuning data pipelines and real-time systems before I stopped treating latency numbers as abstract and started mapping them to concrete human experience. 60 milliseconds is roughly the duration of one frame at 16.6 frames per second, which is below the threshold where most humans notice visual stutter. In a web application, that amount of latency on a server response will feel sluggish on a single page load but may go unnoticed in a background data fetch. The context matters far more than the raw number. I once had a trading dashboard that registered 60ms of p99 latency on order book updates. On paper it looked fine, until I realized traders were refreshing manually because the UI felt stale, and every refresh added another 60ms queue on top of what was already there. The fix wasn't reducing latency further, it was pushing updates via a persistent WebSocket rather than polling, which eliminated the repeated request overhead entirely and made the existing 60ms irrelevant to the user experience.
How 60ms Breaks Down in Real Systems
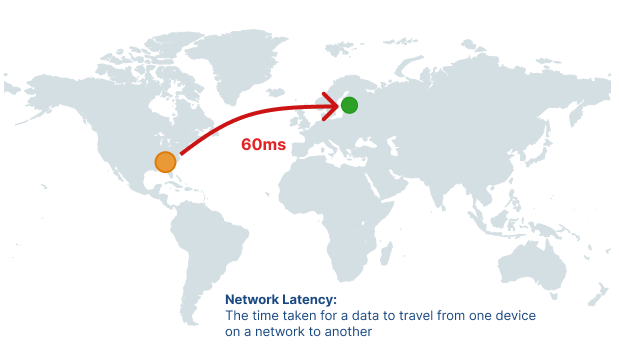
A single 60ms delay is usually not one bottleneck, it is several small delays stacked together. Network round-trip time might account for 20 to 30 milliseconds depending on geographic distance and protocol. Database query execution could take another 15 milliseconds. Serialization, middleware processing, and framework overhead typically consume the remainder. When you are building a system that depends on this kind of latency profile, you need to measure it under load, not in isolation. A response that takes 60ms when your database has two active connections will degrade to 200ms or more once you hit twenty concurrent users. That scaling behavior is where most projects run into trouble, not the base latency itself. Here is a practical breakdown of where those 60 milliseconds typically come from:
Network propagation on a regional connection: approximately 15 to 25ms. Database query with proper indexing: around 5 to 15ms. Application logic and serialization: 10 to 20ms. Connection pooling overhead and middleware: 5 to 10ms. This adds up quickly when each layer is optimized independently without looking at the total path.
Get the Full Details

Where 60ms Matters and Where It Does Not
Interactive applications like gaming, financial platforms, and collaborative tools feel every millisecond of a 60ms delay because the feedback loop is continuous. A video streaming service or a batch reporting tool will not notice much difference at the same latency level since the user is not expecting immediate responses. I learned this the hard way while optimizing a real-time multiplayer game backend. We spent three weeks shaving latency from 80ms down to 45ms on the authentication service, only to discover that the actual gameplay packets were running at 12ms because they used a completely separate network path. All that optimization work had zero impact on what players experienced. Focusing on the right endpoint saved us months of unnecessary refactoring.
Measuring What You Actually Care About
Raw server response time is not the same as what the user perceives. If you want accurate data, measure end-to-end latency using synthetic monitoring from multiple geographic regions and include the full request lifecycle: DNS resolution, TCP handshake, TLS negotiation, server processing, and response download. Tools like k6, Locust, or even simple curl commands with timing breakdowns can give you a starting point. Percentile tracking is essential here. An average latency of 60ms means very little if your p99 is sitting at 400ms during peak traffic. Reporting the p50, p95, and p99 together gives you a realistic picture of what different segments of your users are experiencing at any given time.
Pitfalls That Blow Past Your 60ms Target
The most common reason latency silently creeps up is unbounded database queries, missing indexes, or N+1 query patterns in application code. A single unindexed join on a moderately sized table can add 30 to 50 milliseconds on its own, wiping out your entire budget before the response even leaves the server. Caching misconfiguration is another frequent culprit. Stale cache entries force backends to regenerate expensive computations repeatedly, and cache stampedes after invalidation spikes can temporarily push latency well beyond acceptable thresholds. Setting appropriate TTL values and using staggered refresh strategies prevents this without requiring complex infrastructure. Connection exhaustion is a bottleneck nobody anticipates until production breaks. If your application pool is set too low, requests queue up waiting for a database or API connection, and queue wait time directly inflates perceived latency. Monitor active connections versus your pool size in real time and set alerts well before you hit capacity.
When 60ms Is Already Too Slow
For high-frequency trading, live video conferencing, or real-time bidding systems, 60ms is an eternity. These domains typically require sub-10ms latencies and achieve them only through specialized infrastructure like in-memory data stores, co-located servers, and custom networking protocols. If you fall into one of these categories, the advice above does not apply and you should be looking at fundamentally different architecture rather than incremental optimization. For most standard web and mobile applications, however, 60ms is a perfectly reasonable target if you focus on the right layers first. Start with database query performance and caching strategy, then move to network-level improvements like CDN placement and connection reuse. The returns diminish rapidly after that unless you have a specific use case that demands it. The biggest mistake I see teams make is optimizing the wrong part of the stack because it is the easiest to instrument. Response time logs are everywhere, but they do not tell you whether the delay came from the database, the network, or the application framework. Distributed tracing solves this by letting you see exactly where time is spent across each service call in your pipeline.
Once you know where the 60 milliseconds actually lives, you can decide whether to reduce it, work around it, or accept it as acceptable for your particular use case. Most projects turn out to need fewer changes than they expect once they stop guessing.