Understanding Where We Actually Are Right Now
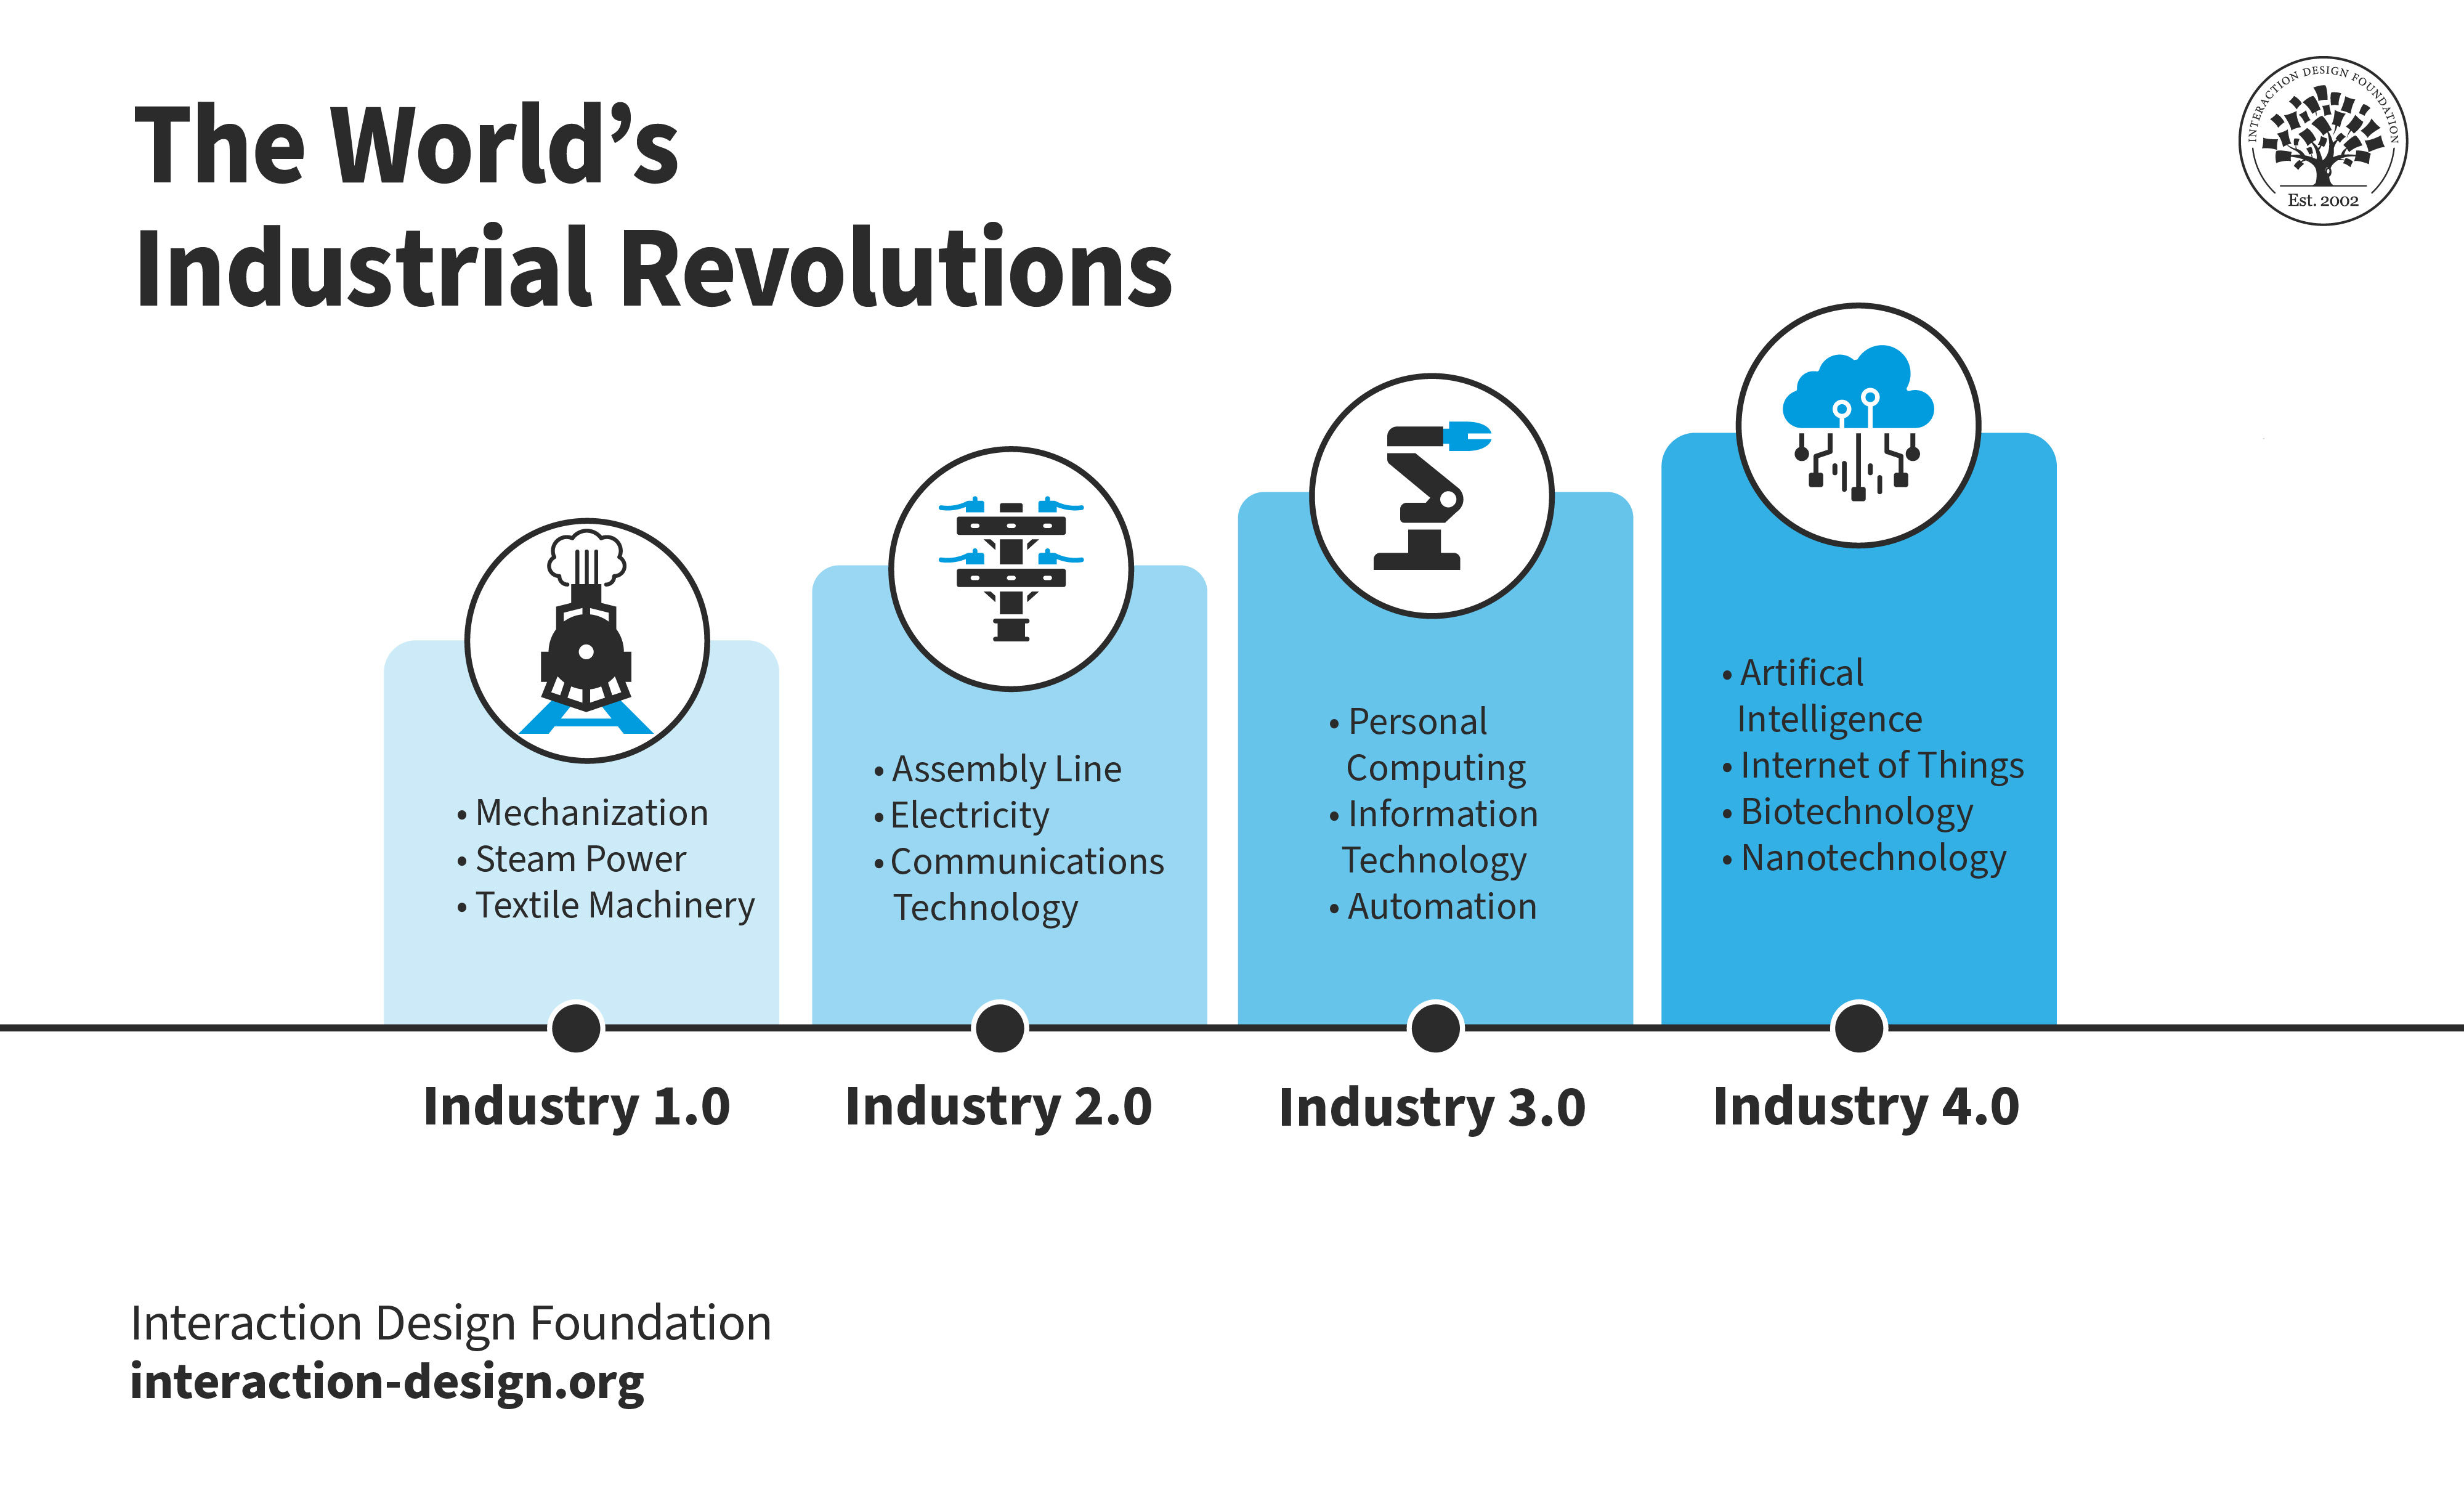
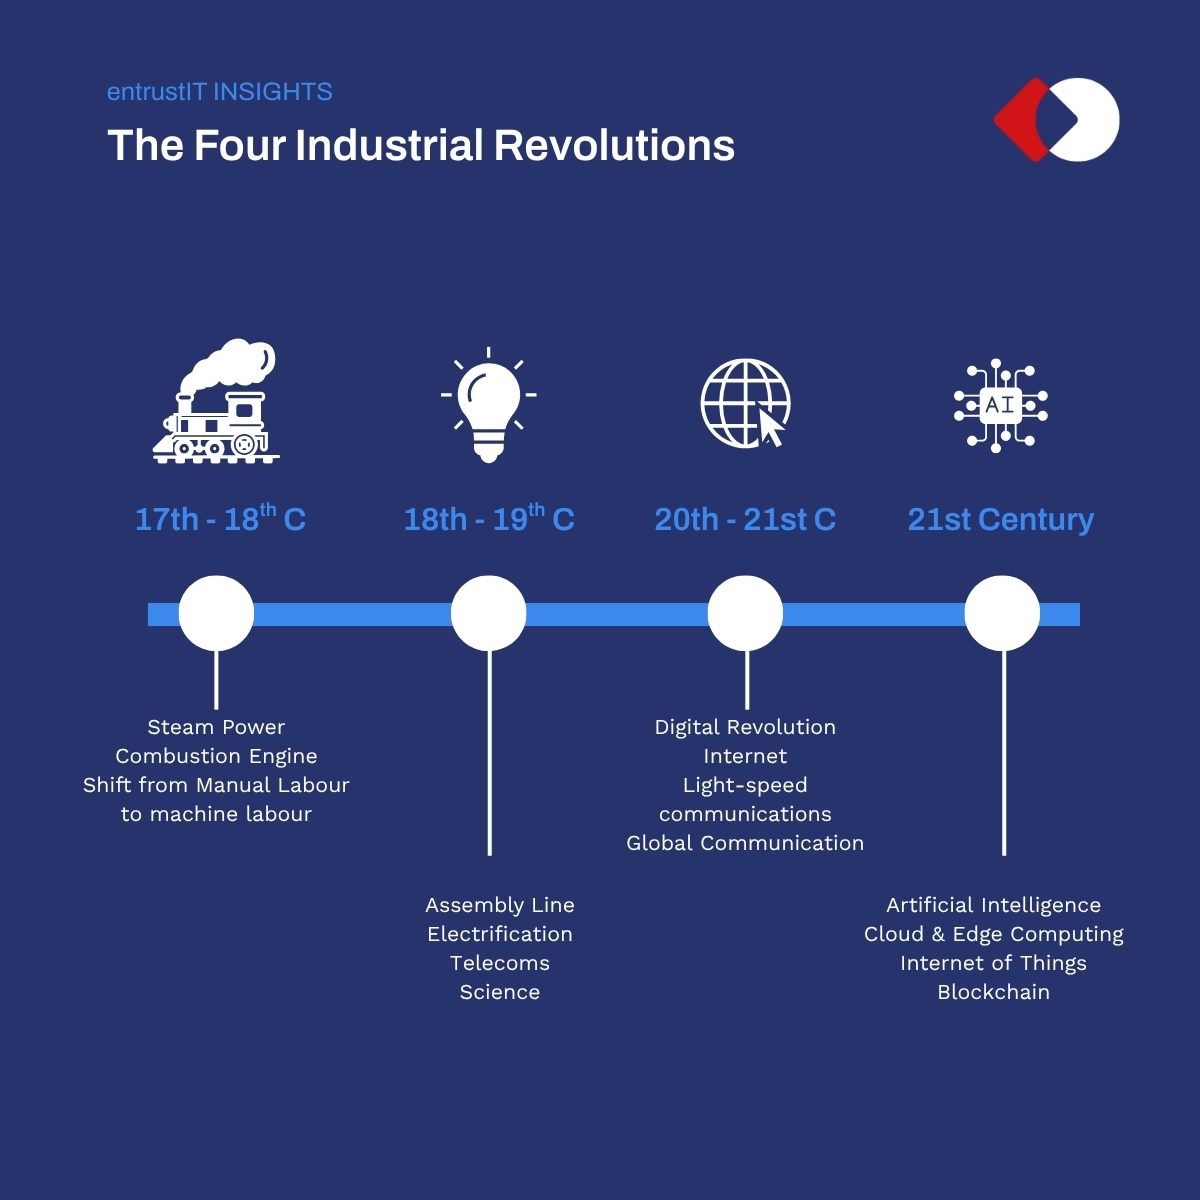
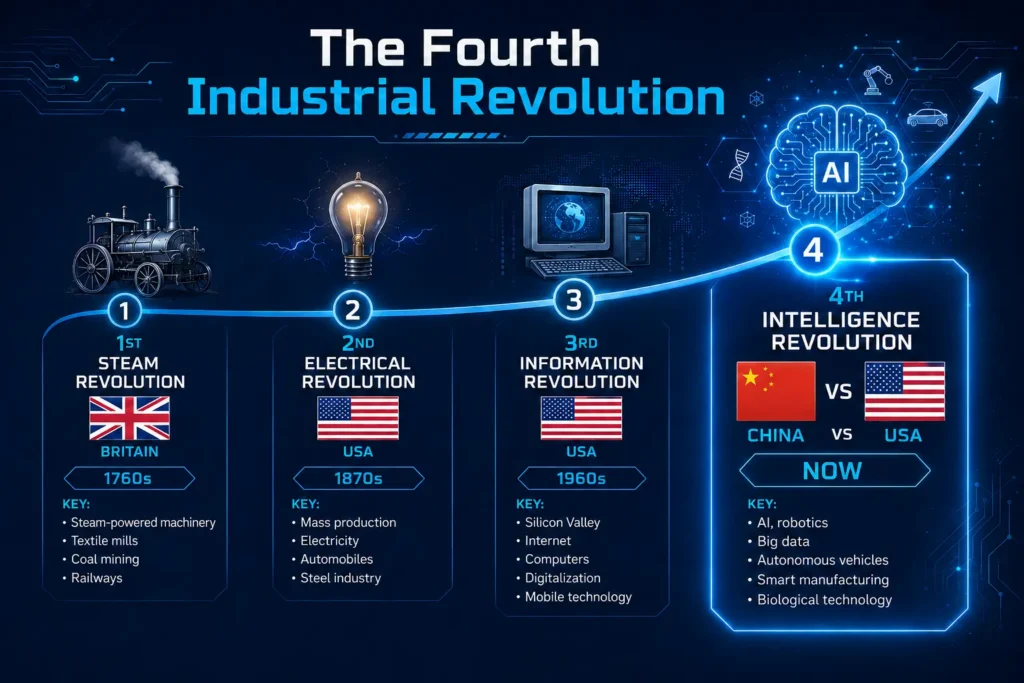
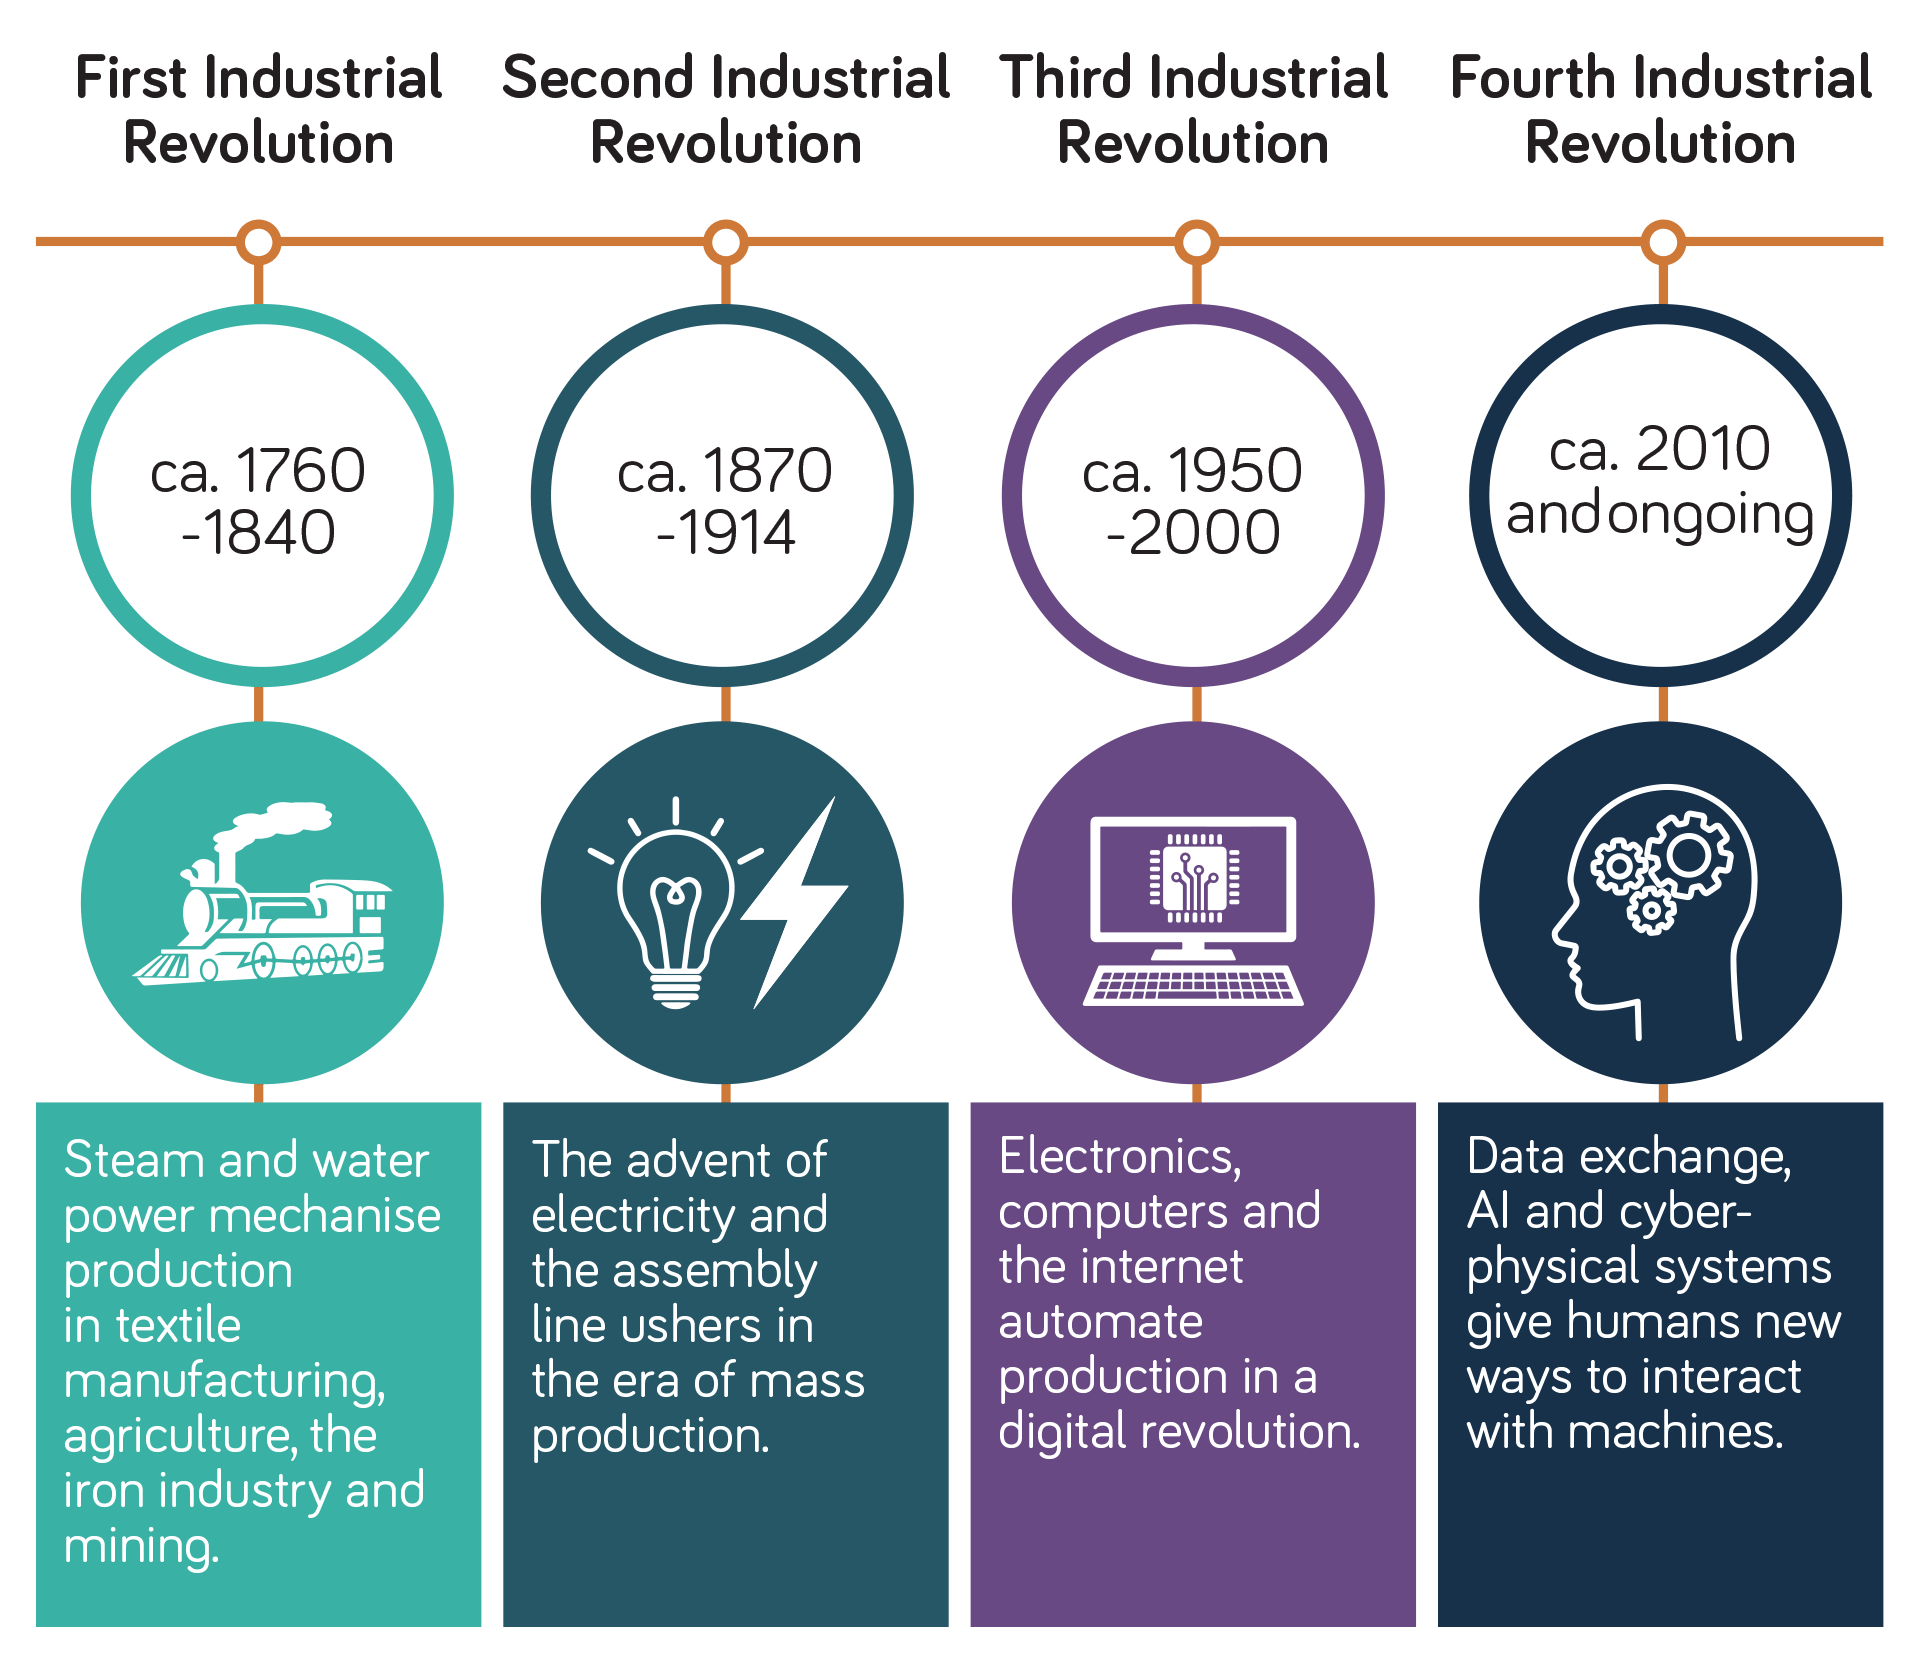
The Fourth Industrial Revolution isn't some distant future concept. It is happening in factories and offices as we speak. The phrase itself was coined by Klaus Schwab around 2016, but the actual shift started earlier and most people still do not fully grasp what is changing under their feet. The simple answer to what century we are living in is straightforward: we are in the 21st century, and the dawn of this industrial shift is already well underway. What makes the current era different from the third industrial revolution is the convergence of technologies. Earlier waves of automation replaced muscle with electricity and then replaced repetitive mental tasks with digital computers. This new phase merges physical, digital, and biological systems in ways that previous eras simply did not. You see it when a factory floor uses predictive maintenance sensors alongside cloud-based analytics and robotics that can adjust their own parameters in real time.
What Century Were Living In Exploring The Dawn Of The Fourth Industrial Revolution
We are exploring this period because the boundaries between what is physical and what is digital have blurred completely. A smart thermostat is no longer a novelty. It is a standard data-gathering node in a larger network. The fourth industrial revolution is defined by that kind of integration at scale, not by any single technology standing alone. Here is how it actually works in practice. Most organizations start with data infrastructure. You need to know what information you can collect before you can do anything meaningful with machine learning models, digital twins, or autonomous systems. The bottleneck is rarely the technology itself. It is usually getting legacy equipment to talk to modern cloud platforms. I dealt with this directly when managing a mid-size manufacturing facility that had CNC machines running thirty-year-old control protocols alongside a brand-new MES system. The workaround involved deploying edge computing gateways that could translate those old Modbus and Profibus signals into MQTT formats without interrupting the production line. The whole migration took about six weeks for the initial setup, and another three weeks of debugging before the data pipeline stabilized. One thing most beginners miss is that connectivity alone does not create value. Plenty of companies have built IoT sensor networks and then discovered they were drowning in noise data with no clear downstream use. The key is to start with a specific operational problem and work backward to the data architecture, not the other way around. If you cannot articulate the business question within the first two weeks of a project, you are probably building something that will sit unused.
Another counter-intuitive reality is that the fourth industrial revolution favors simpler models in production over more sophisticated ones. A basic linear regression deployed reliably across a thousand endpoints often outperforms an elaborate deep learning model that only runs on a single high-end server. MLOps maturity matters far more than model complexity. Deploying and monitoring is where most projects fail, not the modeling phase itself. There are significant downsides that nobody talks about enough. The energy consumption of large-scale AI training and data centers is real and growing. A single large model training run can consume as much electricity as several hundred homes use in a year. The supply chain vulnerability for rare earth minerals used in sensors and batteries is another bottleneck that rarely gets addressed in promotional material. Geopolitical concentration of manufacturing for semiconductors means any disruption in a small number of regions can cascade across the entire technology stack. If you are looking to engage with this shift practically, start by auditing your existing processes for data generation. Identify where human judgment is being applied repeatedly to the same type of decision. Those are your highest-ROI automation targets. The tools you need are usually already available. Open-source frameworks like TensorFlow and PyTorch handle model development. Platforms like Kubernetes manage deployment at scale. For edge deployment, solutions like NVIDIA Jetson or even Raspberry Pi setups can run inference locally without constant cloud connectivity.
Get the Full Details
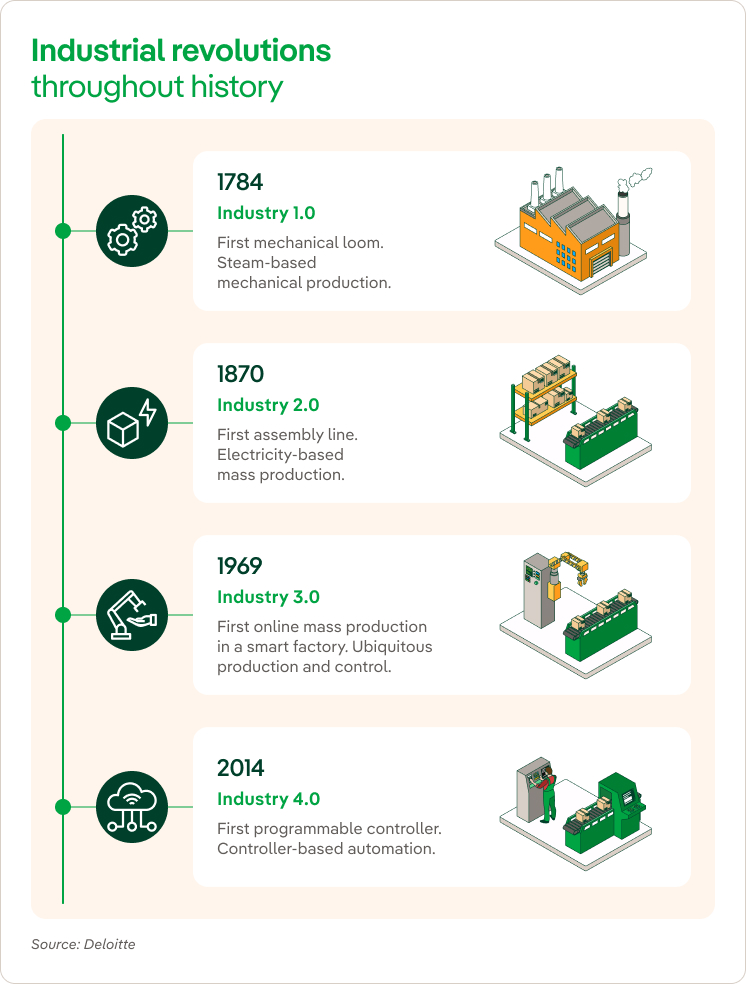
The timeline for full adoption across industries varies wildly. Healthcare moves slowly due to regulation and liability concerns. Consumer technology moves incredibly fast, often outpacing the infrastructure and workforce needed to support it sustainably. Manufacturing sits somewhere in the middle and tends to adopt in patches rather than wholesale transformations. What is clear is that the era we are in demands a different mindset than the previous century provided. The speed of change means continuous learning is not optional. It is a baseline requirement for anyone working in technical or operational roles. The people who adapt fastest are not necessarily the ones with the fanciest degrees. They are the ones who understand the systems they work in well enough to spot where automation and integration can actually reduce friction instead of creating new problems.