Polygenic Characteristics and the Study of Complex Traits
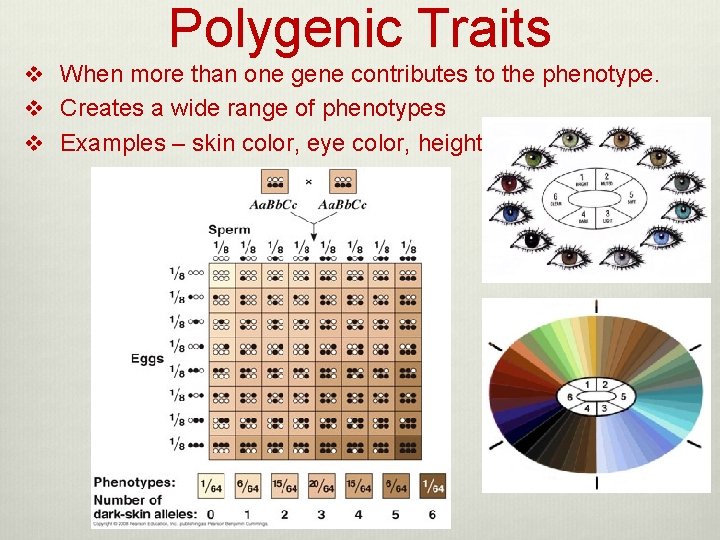
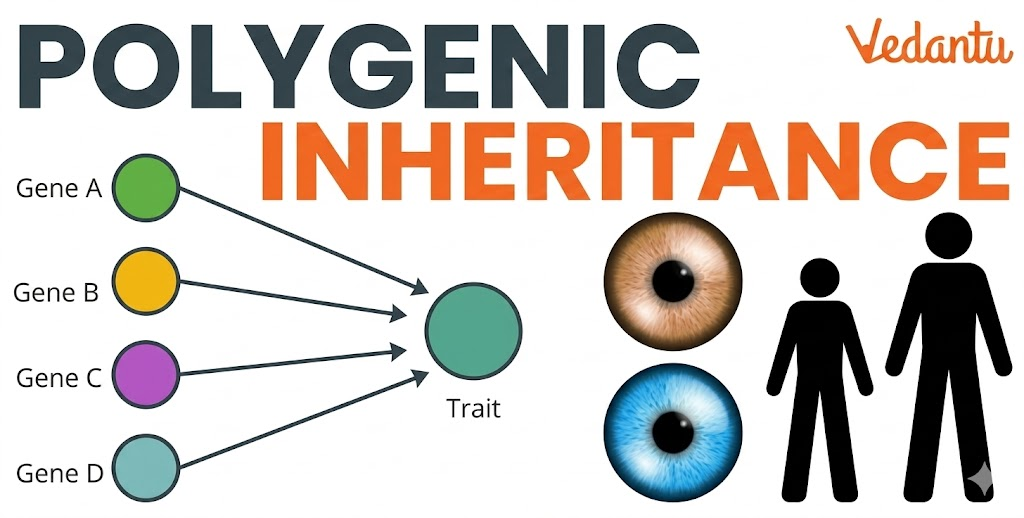
Most people think genetics is simple — you inherit a gene, you get a trait. Height, eye color, that kind of thing. Then someone tells you about polygenic characteristics and suddenly the picture gets messy. It's supposed to be more accurate though. Real biology rarely follows a neat single-gene pattern.What Are Polygenic Characteristics Unlocking The Secrets Of Complex Traits The first issue that always bites people is population stratification. If your discovery GWAS was done mostly in European ancestry samples and you apply the score to someone with different ancestry, the predictions drift. Not because the biology changed, but because allele frequencies and linkage disequilibrium patterns differ across populations. I ran into this a couple of years ago when a collaborator wanted to validate a cardiovascular PRS in a cohort with mixed South Asian and European ancestry. The AUC dropped from about 0.62 to 0.54 without any adjustments. We ended up using ancestry-specific weights and a principal component correction layer, which brought it back to roughly 0.59. Still not great, but closer to what the original study reported in its own population. It wasn't broken. The variants were there, just with very small individual effect sizes. As sample sizes grew to millions of participants, the explained variance climbed close to the twin-study estimates. The lesson is that you need enormous samples to detect the tiny effects that actually drive most polygenic traits. A GWAS with 10,000 participants will miss the vast majority of signal for anything but the most strongly associated loci. That's why recent big consortium efforts in the UK Biobank and similar datasets have been so valuable.
Another counter-intuitive point: high polygenic heritability doesn't mean your PRS will be useful clinically. I saw a paper on a schizophrenia PRS that showed strong population-level discrimination but couldn't actually classify any individual as high risk with useful specificity. The distribution of scores overlaps too much between cases and controls. You might know someone is above average genetically, but that doesn't tell you much about whether they'll actually develop the condition. Environment and random developmental factors fill in a lot of the gap.
Building a Working PRS Pipeline
If you're actually going to calculate polygenic scores, here's what the process looks like in practice. You'll need three things: summary statistics from a GWAS, your target genotype data, and a clumping and thresholding or more advanced method like LDpred or PRS-CS.Start by clumping your SNPs. This removes variants that are in high linkage disequilibrium with each other so you don't double-count the same signal. The standard tool is PLINK. You run a clumping step with a reasonable r² threshold — usually 0.1 or 0.2 — and a physical distance window, often 250 kilobases. Then you pick a p-value threshold and keep only variants below that. Simple clumping and thresholding is fast and usually adequate. More sophisticated methods model the full LD structure and can squeeze out a bit more predictive power, but they require more compute and careful parameter tuning. One edge case that costs people a lot of time: mismatched reference panels. If your clumping LD reference doesn't match the ancestry of your target data, the clumping results will be off. I once spent an afternoon debugging weird score distributions before realizing the LD reference was 1000 Genomes EUR and my target cohort was predominantly Middle Eastern. Switching to a more appropriate panel fixed it immediately. Always check ancestry alignment between your reference and target sets before running the pipeline.
Get the Full Details

Limits You Should Accept Upfront
Polygenic scores have real constraints. They don't work well for traits with low heritability. They degrade outside the population their discovery GWAS was built on. They capture only additive genetic variance, missing epistatic interactions and structural variants that standard SNP arrays don't even type. And they're basically useless for traits heavily driven by rare variants with large effects — exome sequencing or whole genome sequencing data is needed there.There's also the issue of winner's curse. Effect sizes from discovery GWAS tend to be inflated, especially for smaller studies. When you apply those inflated weights to a new sample, your predictions will systematically overestimate the trait. This is one reason independent validation cohorts matter. Don't trust a PRS result from the same population it was trained on. That's circular and it happens more often than it should. The field has moved toward methods that correct for this, like cross-validation within the GWAS summary statistics or using independent holdout samples. PRS-CS and LDpred2 are better at handling shrinkage and reducing inflation than older threshold-based approaches. If you're starting a new project, skip the basic clumping and thresholding unless you have a good reason. The modern methods are worth the extra setup time. What polygenic characteristics have really unlocked isn't a magic prediction engine. It's a way to quantify how much of a trait's variation tracks with common genetic variation across a population. That's useful for understanding biology, for risk stratification in research settings, and for identifying shared genetic architecture between seemingly unrelated conditions. It's not a crystal ball. The numbers are meaningful at scale, not at the individual level for most traits currently studied. Anyone selling you otherwise hasn't spent enough time working with real genotype data.