Line Segments in Practice
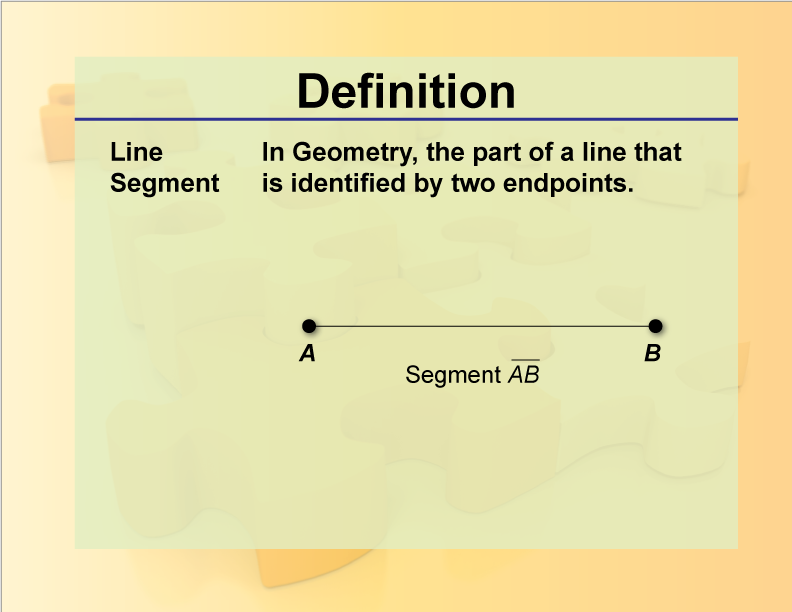
A line segment is just a piece of a line with two endpoints. That's it. But in real work—computer graphics, CAD, surveying, game development—you spend most of your time dealing with the stuff that happens between those endpoints, not the definition itself. The definition comes second to the operations. You need to know how to check if a point lies on a segment, how to find the distance from a point to a segment, how to detect whether two segments intersect, and how to handle cases where they're collinear and overlapping. These are the things that show up in bug reports at 4pm on a Friday. I spent three days tracking down a rendering artifact where buildings in a city environment were missing small patches of sidewalk. The issue was a segment intersection function that treated two nearly-collinear segments as non-intersecting because the cross product came out smaller than the epsilon threshold. The workaround was to add a collinearity check before the standard intersection test and handle overlap as a separate case. Took me an hour once I knew what to look for.
The Core Operations You'll Actually Use
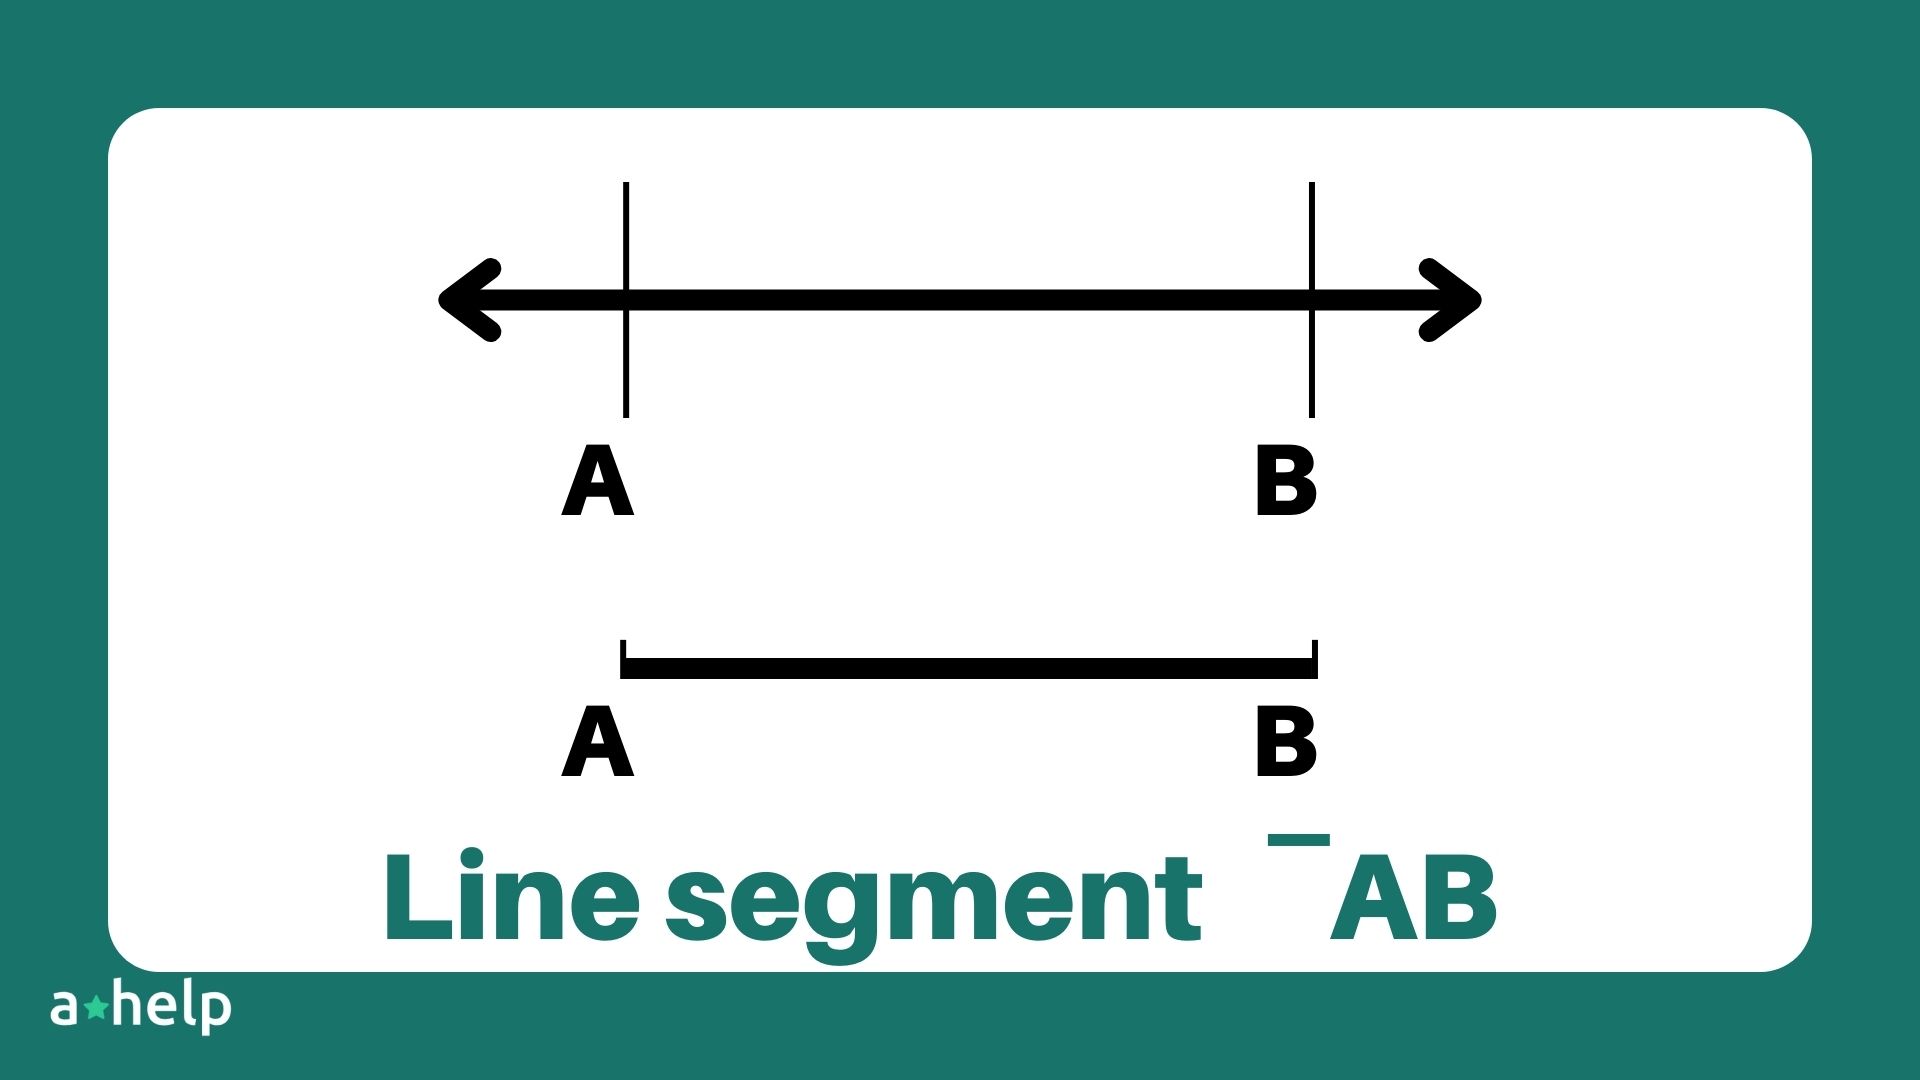
Start with the distance from a point to a segment. A naive approach projects the point onto the infinite line and takes that distance. That only works if the projection falls between the endpoints. If it doesn't, the closest point is one of the endpoints. This distinction matters everywhere—collision detection, nearest-neighbor searches, mesh simplification. For segment-segment intersection, the standard approach uses the cross product to determine orientation. Given segments AB and CD, you check whether C and D lie on opposite sides of line AB, and whether A and B lie on opposite sides of line CD. If both conditions are true, the segments intersect. The edge cases are where people get burned: collinear segments, shared endpoints, and segments that just barely touch at an endpoint. One thing beginners miss is that the cross product method gives you the intersection parameter t along the first segment. If you need the actual intersection point, you don't interpolate between A and B directly using floating-point arithmetic on the endpoint coordinates. You compute t first, then use it. Doing it the naive way introduces rounding errors that become visible when you're rendering at scale or running thousands of queries per frame.
When Precision Breaks Down
Double precision gets you so far. In GIS work or when dealing with coordinates that span large geographic areas, you'll hit limits where the coordinate values themselves consume most of the mantissa and you can't distinguish between two nearby points. The workaround I use is coordinate normalization—shift all points so the average is near zero before running intersection tests. This isn't always possible if you're working with fixed coordinate systems, but when you can do it, it makes a measurable difference in robustness. Another failure mode: segments that are defined by noisy data. GPS traces, scanned measurements, sensor readings. The segments don't represent exact geometry; they represent approximations. Running exact intersection logic on noisy segments produces garbage results. The fix is either to snap endpoints to a grid or to use a tolerance-based approach where "intersection" means "the segments come within distance d of each other." Neither is more correct in an absolute sense. It depends on what your data actually represents.
Get the Full Details
Implementation Notes
If you're implementing this from scratch, start with a clean reference implementation and test against known cases before optimizing. The canonical test suite includes: Get all of these returning the right answer consistently, then worry about speed. I've seen people optimize the intersection function by removing the collinear check and claiming a 15% speedup. That's true until their software starts misreporting collisions in a physics simulation, and then you've lost a week debugging instead of gaining an hour. For production code, consider using an existing library like CGAL or the computational geometry routines in your language's standard library rather than rolling your own. The edge cases are not obvious, and they will find you eventually.
Where Line Segments Show Up
You encounter them whenever you approximate curves or define boundaries. Vector graphics formats store everything as segments. Finite element meshes are built from segments in 2D. Pathfinding algorithms treat walkable space as a graph of connected segments. Even in 3D work, the underlying geometry often reduces to segment calculations at some layer of the pipeline. The reason they feel "unseen" is that well-written code abstracts them away. You call a function that tells you whether two objects collide, and the function internally runs segment intersection tests you never think about. When the abstraction leaks—when you're getting false negatives or the wrong intersection point—that's when you start paying attention to what's underneath.