Variables Are Just Labels You Attach to Things You Can Measure
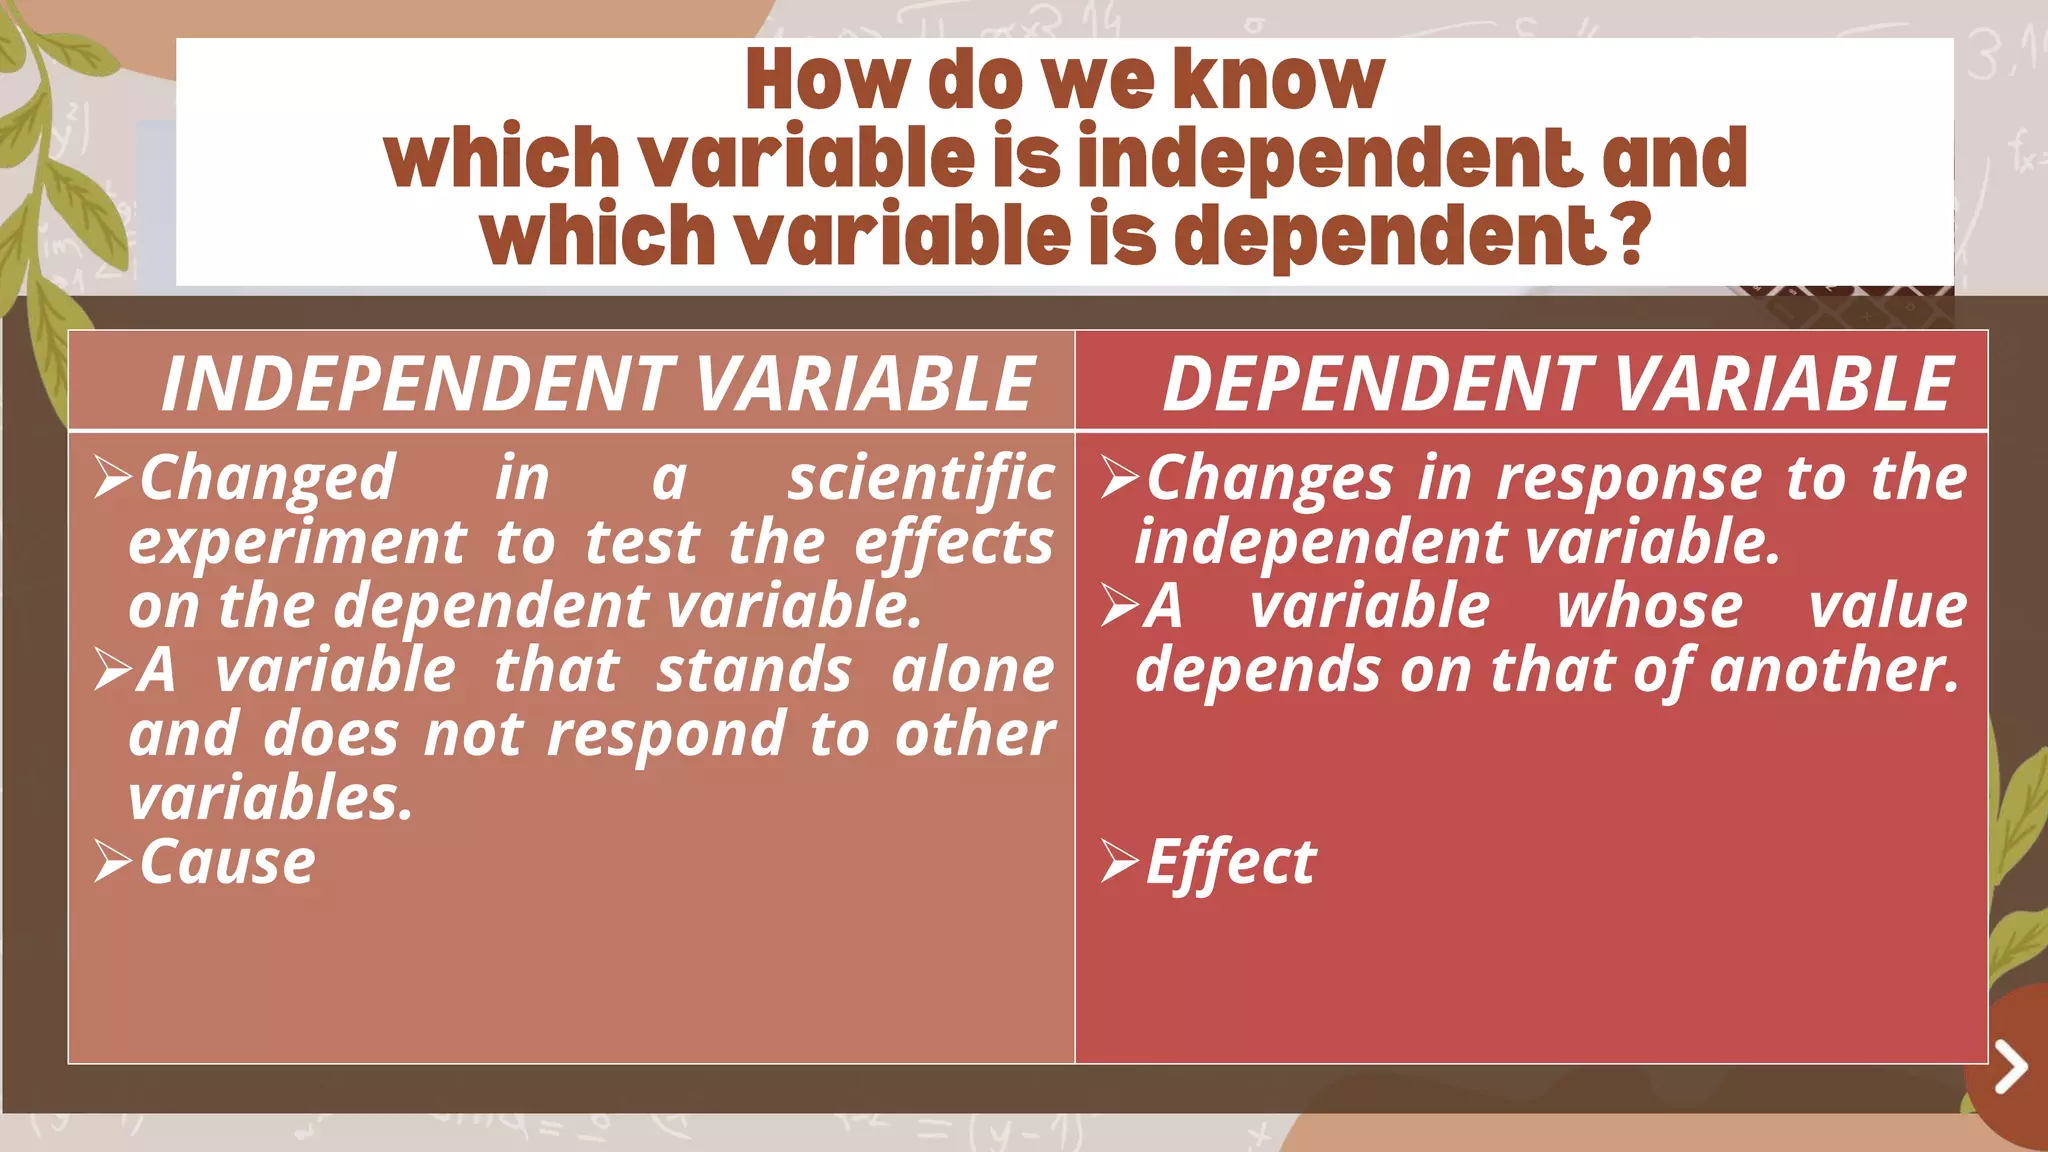
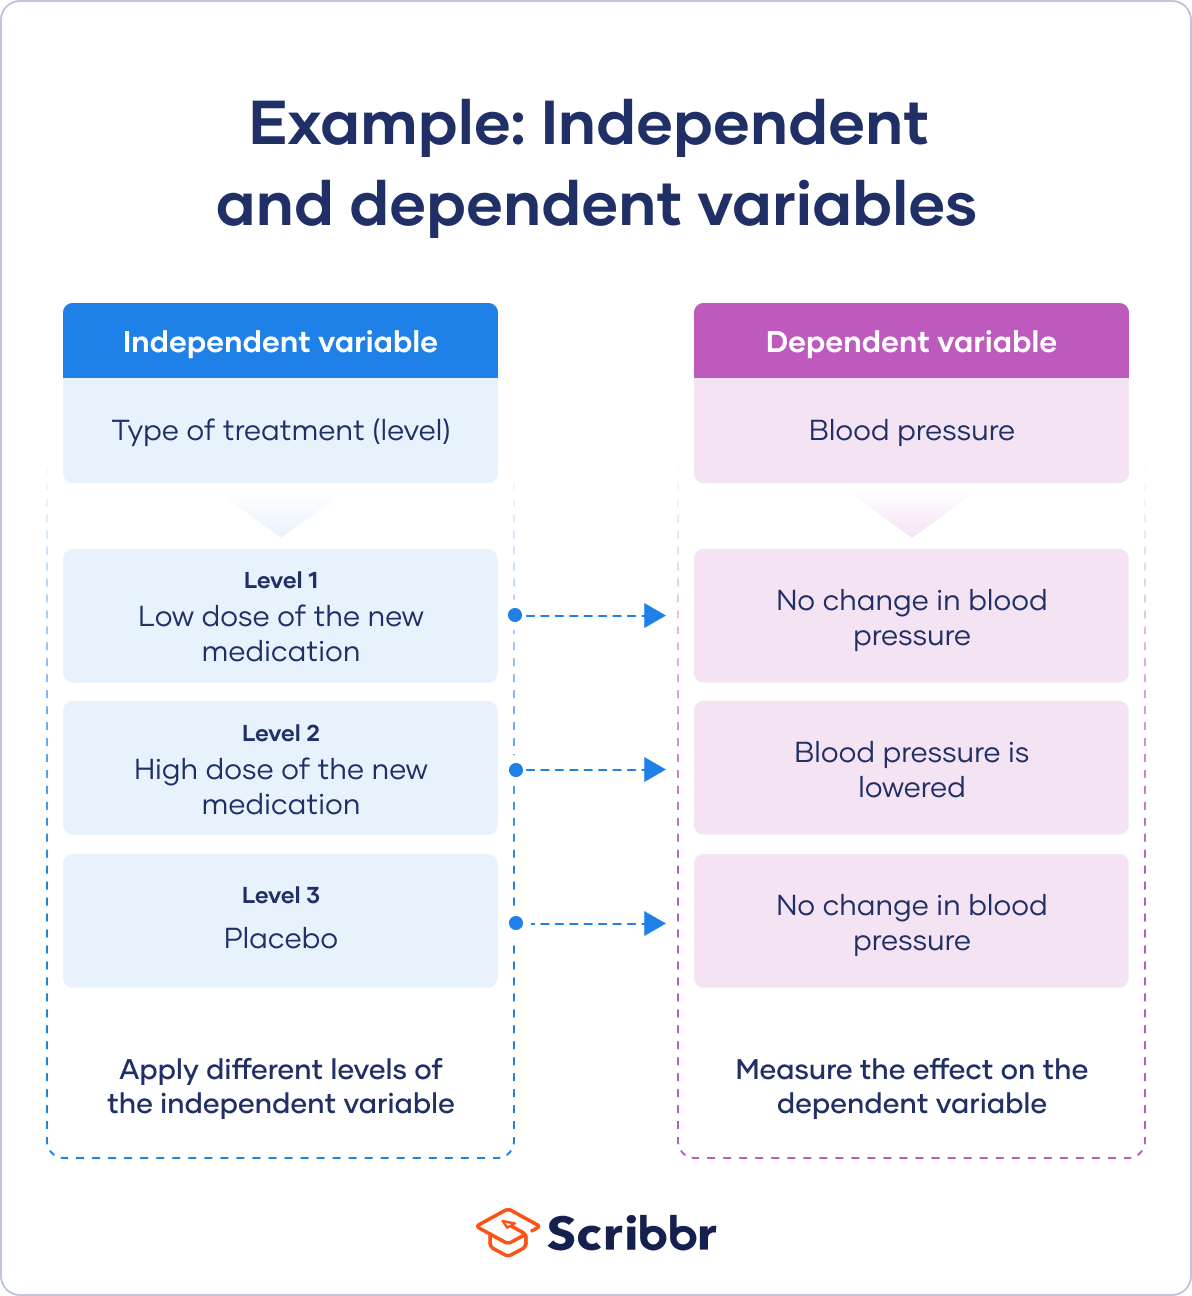
I spent years debugging why our lab's pharmacology studies kept producing inconsistent dose-response curves. The problem wasn't the equipment or the protocol. It was that nobody was explicitly tracking which factors were being changed versus which were simply being observed. This is where What Are Independent Variables And Dependent Variables In Science The Core Language Of Cause And Effect becomes the actual work, not just textbook definitions. The real value is in correctly assigning those labels before you run a single trial. An independent variable is whatever you deliberately manipulate or select different levels of. A dependent variable is whatever changes in response, and that change is what you record. Everything else is either a control or a confounder you need to identify and manage. Sounds trivial until you realize most failed experiments fail because someone confused which category a factor belonged to.
What Are Independent Variables And Dependent Variables In Science The Core Language Of Cause And Effect
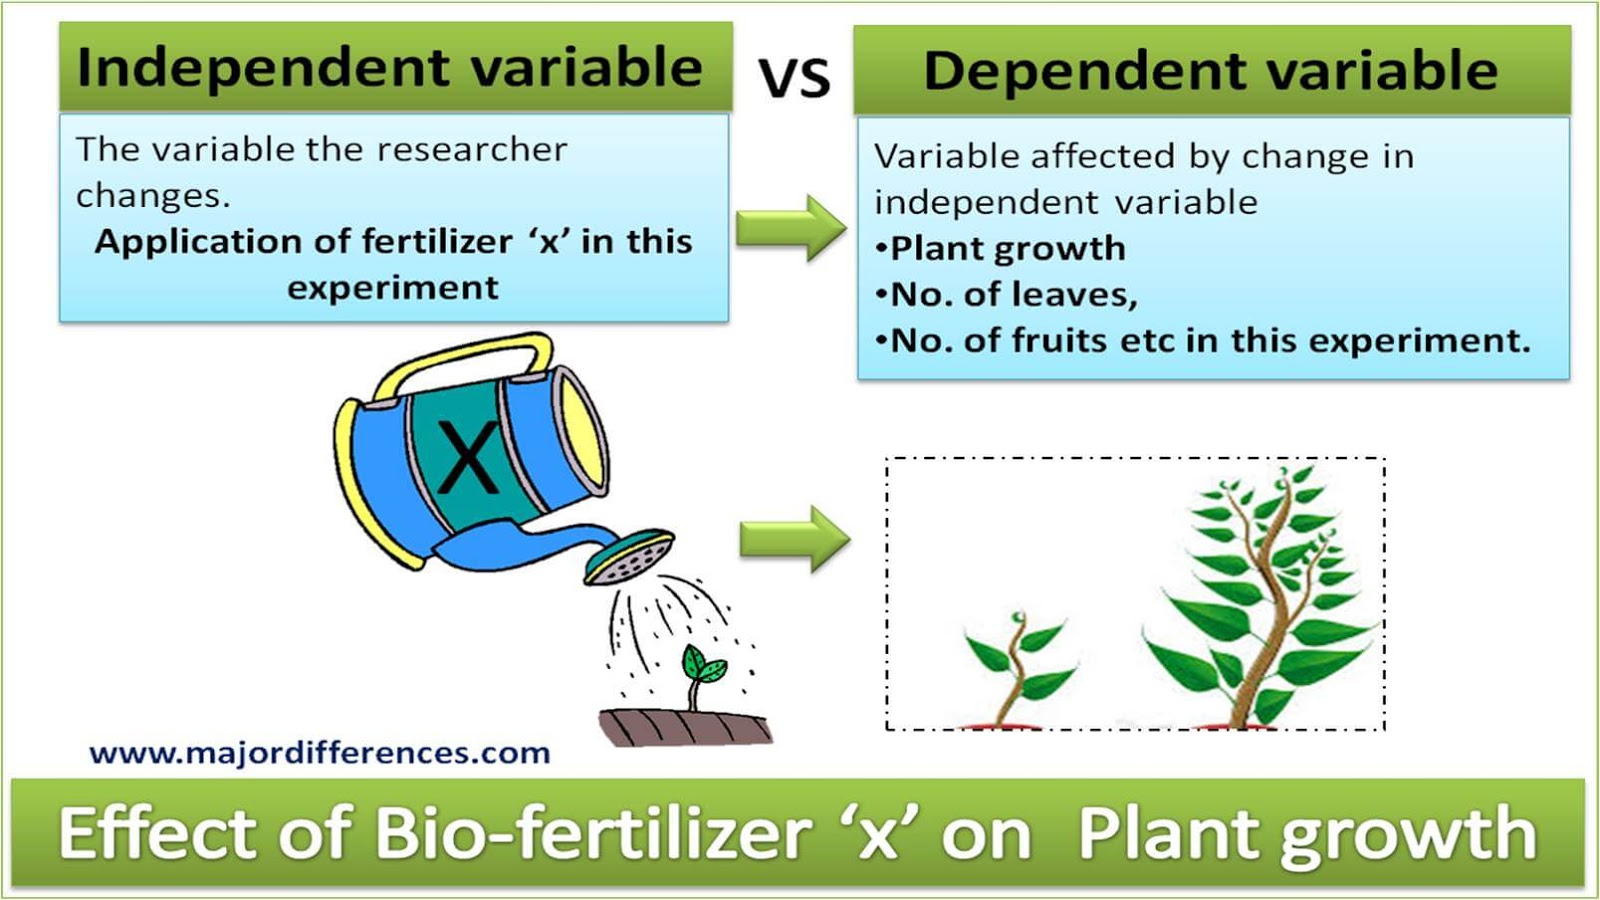
Here is the practical way to think about it that no introductory textbook really drives home clearly enough. Start by identifying every measurable quantity in your system. Then ask yourself: which one am I choosing the value for? That is your independent variable. Which one am I waiting to see shift after I set the first one? That is your dependent variable. The dependency relationship is the whole point. The dependent variable depends on the independent variable by definition of your experimental design. If you cannot articulate the causal direction, you do not have a valid experiment. You have observations at best. I once ran a soil microbiome study where we varied nitrogen fertilizer levels and measured plant biomass. Simple enough. The complication was that we also needed to account for soil moisture because the greenhouse benches had uneven irrigation patterns. Moisture was not part of our planned design, but it co-varied with our independent variable because the high-nitrogen plots happened to be on the drier side of the bench. We ended up with a classic confounding problem where nitrogen and moisture were moving together and we could not tell which one was driving the biomass differences.
The workaround was brutal but straightforward. We redesigned the layout using a randomized block design, splitting the bench into blocks based on moisture gradient and randomly assigning fertilizer treatments within each block. We then measured soil moisture at every sampling point and included it as a covariate in an ANCOVA model. This let us partition the variance attributable to nitrogen separately from the variance attributable to moisture. It added about three days of field work and a week of statistical cleanup, but it saved the study from producing garbage results that would have required a full replication.
Get the Full Details
How To Set Up Your Variables Before You Touch Any Equipment
Write down the question you are trying to answer in one sentence. Identify every quantity that could plausibly affect the answer. Assign each one to a column: independent, dependent, controlled, or potential confounder. If a factor could affect the dependent variable but you are not manipulating it, it belongs in the confounder column until you prove otherwise. That distinction matters because it determines whether you control it, randomize it, measure it as a covariate, or ignore it. Controlled variables are the ones you hold constant. Temperature, humidity, time of day, batch of reagents. The goal is to prevent those factors from introducing noise or bias into your dependent variable measurements. When you hold them constant, any variation in the dependent variable is more likely to come from the independent variable rather than from some unmeasured environmental drift. Potential confounders are the dangerous ones because they look like controls but are not actually held constant. In my soil study, the greenhouse bench gradient was a hidden confounder. It looked like we had randomized properly because we shuffled the pots visually. But the irrigation pipes created a systematic moisture gradient that correlated with our treatment assignment. Visual randomization does not replace proper randomization algorithms. This is a mistake I see in undergraduate labs constantly.
Counter-Intuitive Cases Where The Classification Shifts
Variables are not inherently independent or dependent. They take on those roles based on what you are testing in a specific experiment. Temperature is an independent variable when you are studying how heat affects enzyme activity. But temperature can become a dependent variable when you are studying how a chemical reaction changes the thermal profile of a solution. The same physical quantity, different roles in different experimental contexts. This creates confusion when people try to define variables based on the subject matter rather than the experimental design. Concentration, pH, light intensity, time. None of these are inherently independent or dependent. They become what you make them by how you set up the experiment. Another thing beginners miss is the difference between discrete and continuous independent variables. Discrete variables take distinct values like treatment groups or species presence. Continuous variables take any value within a range like temperature or concentration. The analysis choices diverge significantly after this point. Discrete independent variables typically call for t-tests or ANOVA. Continuous independent variables often call for regression. Mixing these up leads to inappropriate statistical tests and invalid p-values.
There is also the case of paired or matched designs where the independent variable is applied to related units rather than independent ones. Drug response measured in the same subjects before and after treatment is a paired design. The independence assumption of a standard t-test is violated. You need a paired t-test or repeated measures ANOVA instead. This is another area where the variable classification alone does not tell you which analysis to use. The experimental structure matters equally.

Common Pitfalls That Wreck Data Quality
The biggest pitfall is manipulating too many independent variables simultaneously without a factorial design. If you change both temperature and pH in an unspecified way, you cannot determine which change caused any observed effect on your dependent variable. Factorial designs exist specifically to solve this problem by crossing levels of multiple independent variables and allowing you to estimate main effects and interaction effects separately. A second pitfall is defining the dependent variable operationally in a way that introduces measurement bias. If you are measuring plant growth by visual estimation rather than by ruler or scanner, your dependent variable now includes observer expectation as a source of error. Blind measurement protocols eliminate this. Have someone who does not know which treatment each sample received record the measurements. It adds ten minutes to data collection and prevents entire classes of bias that are nearly impossible to detect retrospectively. A third pitfall is treating a continuous dependent variable as categorical after data collection. This is called dichotomization and it throws away information. If you measure reaction time in milliseconds and then split people at the median into fast and slow groups for a t-test, you reduce statistical power significantly. A continuous analysis retains more information and usually detects effects that a categorized analysis misses. Keep dependent variables continuous whenever possible.
When This Framework Completely Fails
Observational studies are the main case where independent and dependent variable classification breaks down in practice. In epidemiology, nutrition research, and social science, you often cannot manipulate the presumed cause. You observe existing differences and try to infer causation from correlation. This is where the language of independent and dependent variables becomes misleading. You are not manipulating anything. You are modeling associations. Granger causality tests, instrumental variable approaches, and structural equation modeling exist to handle these situations, but they come with heavy assumptions that are often unjustified. Without randomization, you cannot rule out confounding with certainty. Causal inference from observational data is possible but it requires transparent acknowledgment of limitations and sensitivity analyses to test how robust your conclusions are to unmeasured confounders. Ecological systems present another failure mode. Food webs, climate models, and ecosystem dynamics involve feedback loops where what you label the independent variable today becomes the dependent variable tomorrow. A population of predators depends on prey availability, but predator density also affects prey availability. The system is circular. Linear variable classification cannot capture this. Dynamic systems modeling or agent-based simulation is required instead.
A Practical Checklist Before You Start Any Experiment
State the research question in one sentence. List all measurable quantities. Classify each as independent, dependent, controlled, or potential confounder. Verify that your randomization method actually breaks correlations between treatment assignment and confounders. Define operational procedures for measuring every dependent variable with units and precision. Plan your statistical analysis before you collect data, not after. If you cannot specify the analysis beforehand, you do not understand your variables well enough to run the experiment. Document everything. I keep a lab notebook where I write the variable classification table at the top of every project. It forces me to confront the design before I waste time collecting unusable data. This habit replaced approximately six months of problematic pilot studies across three different projects in my career. The time investment is about two hours per project. The return on that investment is usually immediate once you see how cleanly the subsequent data analysis goes. The independent variable is the lever you pull. The dependent variable is the reading on the gauge you watch. Everything else is noise you either control, randomize, or measure and account for statistically. Get the classification right and the rest of the experiment follows logically. Get it wrong and you spend months debugging data that was never going to answer your question.