The Practical Reality of Summarization
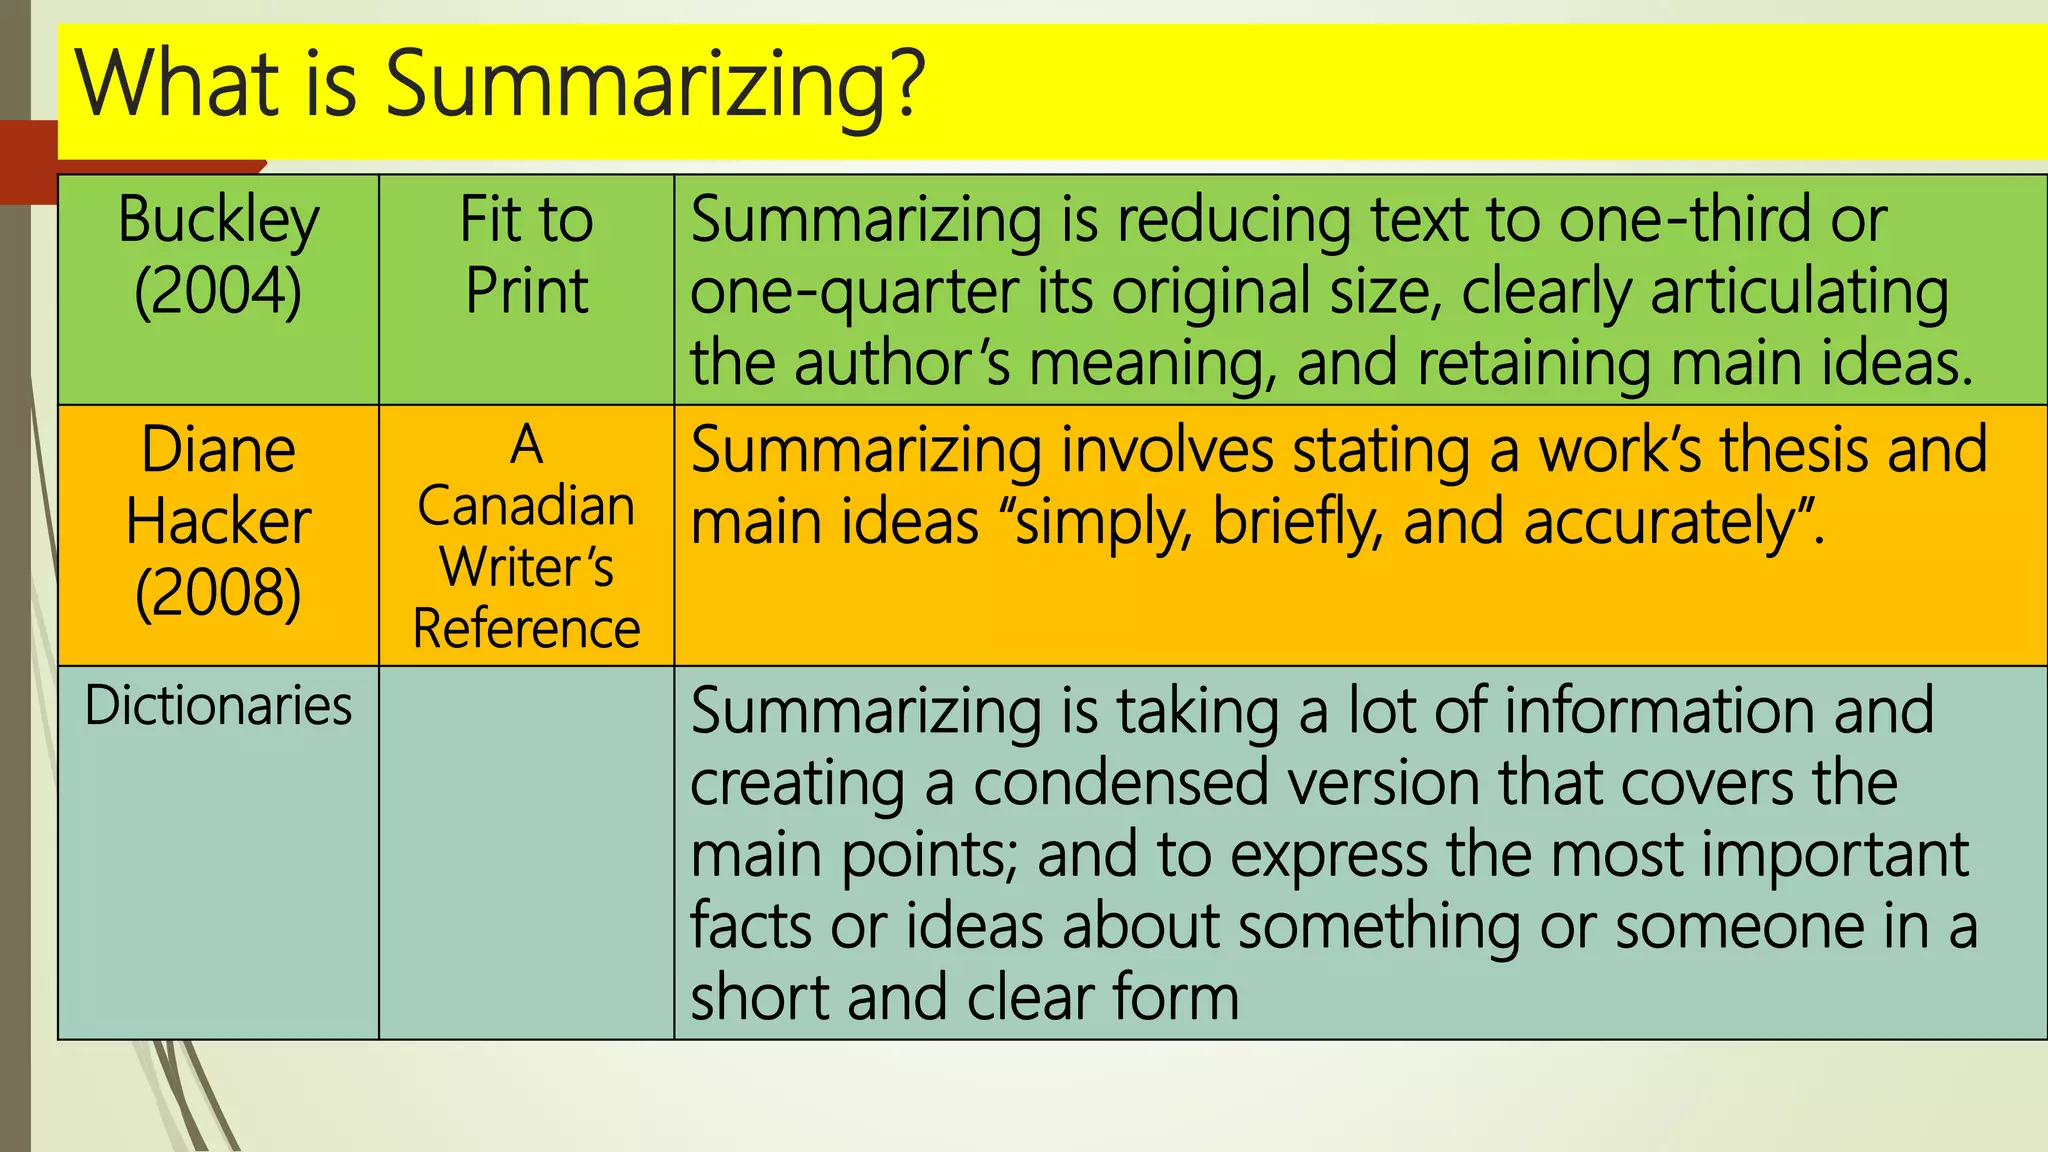
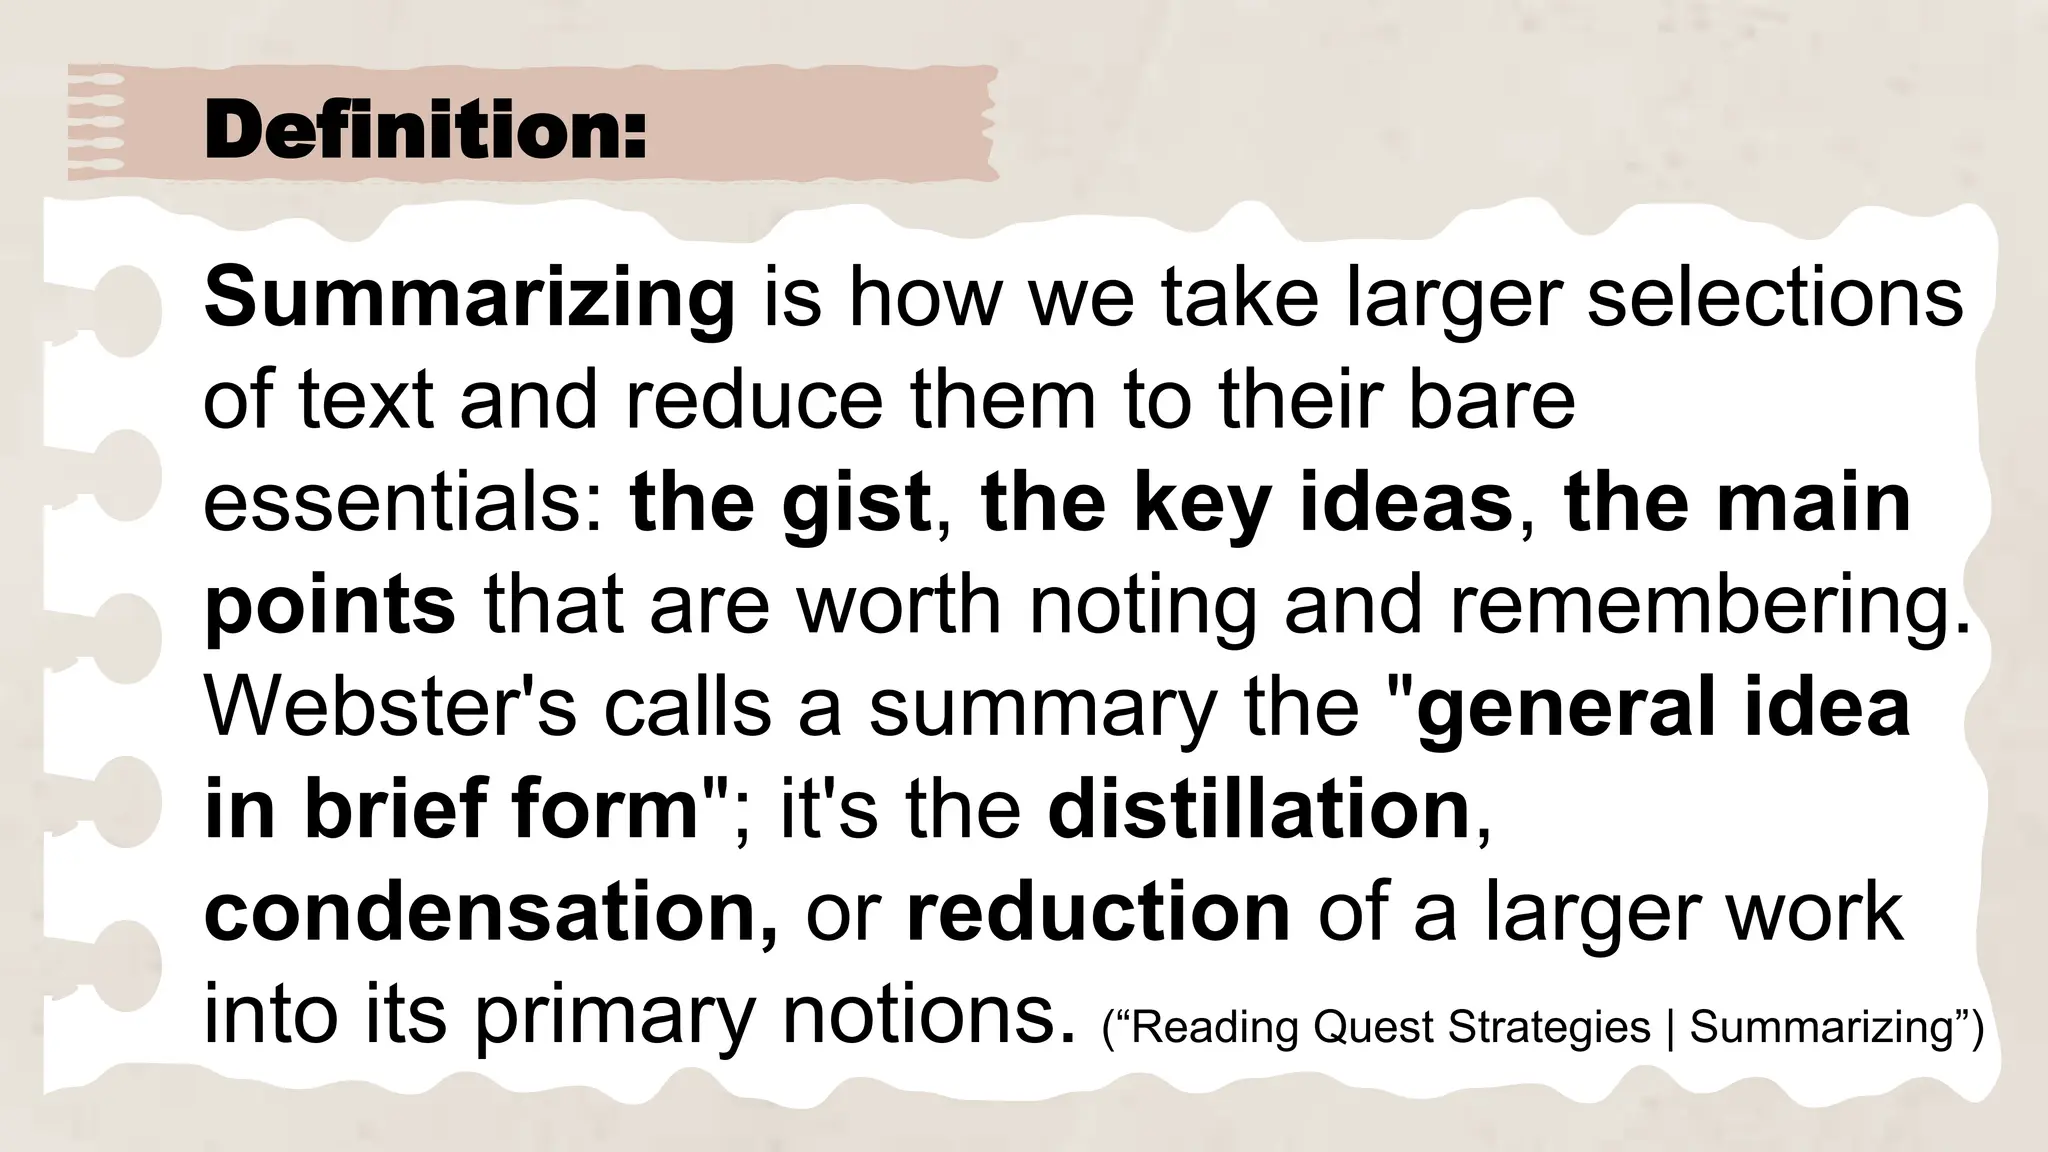
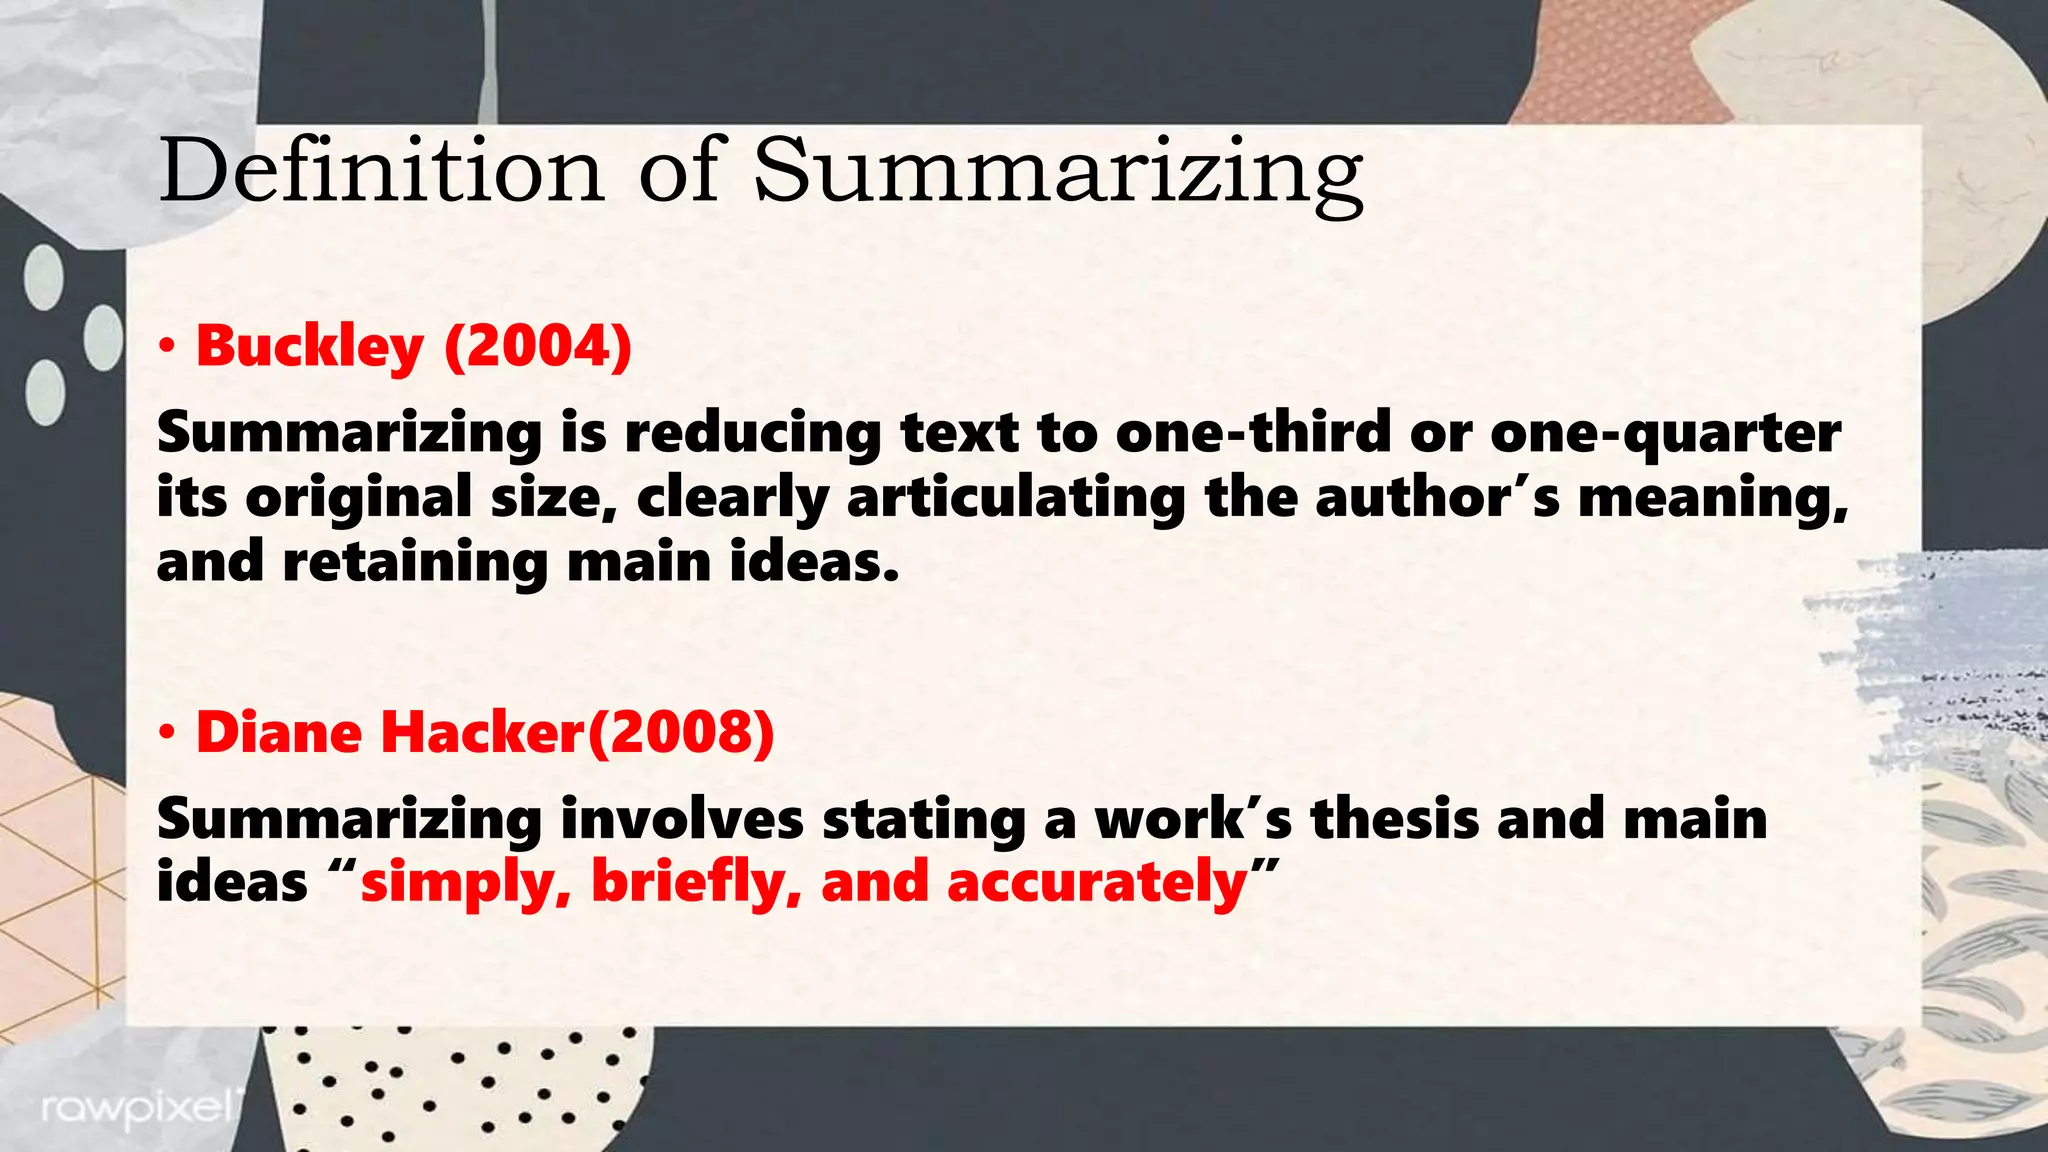
Most people think summarizing is just shortening something. It is not. A summary is a compressed representation that preserves the essential meaning and relationships of the original text while removing non-essential details. The purpose changes entirely depending on whether you are summarizing for retention, for distribution, or for machine processing. I spent years doing this for legal document review and compliance teams. The first thing you learn is that people consistently overestimate how much information survives compression. A well-built summary of a 40-page contract should be roughly 800 to 1200 words, not 400. Anything shorter usually drops critical qualifiers like "subject to," "notwithstanding," or temporal constraints that change the entire meaning.
What A Summary Is Unpacking The Definition Purpose And Techniques Of Summarization
The core definition breaks down into three components: fidelity to source, appropriate level of compression, and audience alignment. Fidelity does not mean verbatim retention. It means the summary cannot assert anything that the source does not support, and it cannot omit information that would materially change the reader's understanding. Compression ratio depends entirely on the use case. Executive briefs operate at 5 to 10 percent of source length. Technical summaries for peer review might run 20 to 30 percent. Legal compliance summaries often sit around 15 percent with heavy reliance on structured extraction rather than prose. I ran into a specific problem last year with a client who needed automated summaries of regulatory filings. The standard extractive approach kept pulling out section headers and disclaimers because they appeared most frequently in the text. Frequency-based extraction literally summarized nothing useful. The workaround was switching to a hybrid model using RAKE for phrase extraction combined with a position-weighted scoring system that downweighted boilerplate sections like acknowledgments and appendices. That dropped false-positive rate from about 40 percent to under 8 percent. The purpose of summarization falls into three practical categories. Extraction-based summaries pull representative sentences directly from the source. They preserve original wording but can read awkwardly when combined. Abstractive summaries generate new language to express the source meaning. They read more naturally but introduce hallucination risk, which is why extraction remains the default in high-stakes environments. Hybrid approaches combine both and are what most production systems actually use.
Techniques That Actually Work
Beginner summarization typically fails because it treats all sentences as equal value. That is wrong. Topic sentences, thesis statements, and sentences containing named entities or numerical data carry disproportionately high information density. Sentences that restate previous points, contain hedging language, or appear in peripheral sections should be deprioritized during selection. Luhn's algorithm from 1958 remains surprisingly effective for basic extractive summarization. The core idea is identifying key terms based on frequency, then scoring sentence windows by aggregating those key term scores. It is simple enough to implement without a model, and it still beats naive approaches. For anything requiring modern quality, Luhn with latent semantic indexing or TF-IDF weighting adds enough accuracy improvement to matter. Pointer-generator networks represent the current production standard for abstractive summarization. They combine attention mechanisms with a copy mechanism that lets the model transfer spans directly from the source text. This dramatically reduces hallucination compared to pure abstractive models because factual content can be preserved verbatim. The PGM (Pointer-Generator Model) trained on CNN/Daily Mail datasets remains a solid reference point, though fine-tuning on domain-specific corpora usually improves output quality significantly.
Get the Full Details

One counter-intuitive insight that beginners miss: longer source texts do not linearly require longer summaries. A 100-page technical manual often summarizes effectively at 1500 words because the information density per page drops in later chapters. The first 20 pages typically contain 70 percent of the unique information. This is why aggressive early-chapter weighting in your selection algorithm pays off more than uniform coverage attempts.
Common Pitfalls and Where Summarization Fails
The biggest failure mode in production summarization is context window truncation. When source documents exceed your model's input limit, you have to split them. Naive splitting destroys cross-section relationships. A conclusion in section three might reference a condition established in section one. Split-and-summarize approaches lose that link entirely. The workaround is maintaining a rolling context buffer across chunks or using a two-pass system where the first pass extracts entities and relationships, and the second pass synthesizes from that structured representation rather than raw text. Another pitfall is the assumption that ROUGE scores correlate with human judgment. They do not, especially not consistently. A summary scoring 0.45 on ROUGE-L might read perfectly fine, while one scoring 0.52 could contain subtle factual distortions that ROUGE cannot detect because they use different wording for the same meaning. Human evaluation remains necessary for anything beyond internal drafts. I typically use a 3-point rubric covering accuracy, completeness, and coherence, scored by at least two raters to catch individual bias. Summarization also fails completely on texts with heavy implicit reasoning, sarcastic tone, or domain-specific jargon without glossaries. Financial analyst reports, for example, often rely on readers inferring risk levels from carefully chosen qualifying language. A summary that removes qualifiers produces a materially different risk assessment than the original. In those cases, the best approach is structured extraction rather than prose summarization. Pull the numbers, the conditions, and the explicit claims. Do not attempt to generate readable paragraphs.
Building a Working Summarization Pipeline
A practical pipeline starts with text cleaning and normalization. Remove footnote markers, normalize whitespace, and handle page breaks that split sentences incorrectly. Most off-the-shelf tools skip this step and produce noticeably worse results on formatted documents. Next, sentence segmentation using a robust tokenizer like SpaCy or NLTK's Punkt. Never rely on simple period-splitting. Abbreviations and decimal numbers will fragment your sentences incorrectly and degrade every downstream step. Then score and select. For extractive approaches, combine Luhn-style keyword scoring with text rank or Keyphrase extraction. For abstractive, feed the cleaned text into a fine-tuned transformer like BART, T5, or PEGASUS depending on your domain and available compute. PEGASUS tends to perform better on longer documents, BART on shorter ones.

Post-processing is where most people stop too early. Run the output through a factuality checker against the source. Cross-reference named entities and numerical values. This step catches approximately 60 to 70 percent of hallucination errors that surface in production use. The remaining errors usually require human review anyway. Automated summarization tools exist but none match domain-specific fine-tuning for professional use. Open-source options like HuggingFace's transformers library with pre-trained models give you a functional baseline in under 200 lines of code. The trade-off is that baseline quality assumes general-domain text and degrades noticeably on technical, legal, or medical content without additional fine-tuning. The honest assessment is that summarization technology has improved dramatically but remains brittle at the edges. It works reliably for straightforward expository text at compression ratios between 10 and 30 percent. It struggles with irony, dense intertextual reference, and documents where structure carries meaning as much as content. Knowing where it fails is as important as knowing where it works.