Understanding the Architecture Before You Build Anything
Most people looking into realtime financial profiling start with the wrong end of the stack. They obsess over visualization dashboards before they understand how data actually moves from source to consumer. The Whaletail Forum Reveals The Hidden Power Behind Realtime Data Sharing In Modern Financial Profiling discussion threads consistently show that the real friction lives in the ingestion layer, not the presentation layer. I spent roughly eighteen months building and then dismantling a profiling pipeline that tried to aggregate transaction feeds, credit bureau signals, and alternative data sources all through a single Kafka cluster. It collapsed under latency spikes every time we hit 40,000 events per second. The bottleneck wasn't compute. It was schema drift across sources. The core insight from those discussions comes down to a pattern most teams miss: realtime profiling works when you treat identity resolution as a streaming problem, not a batch problem. You need eventual consistency for customer IDs across datasets, but you cannot afford finality locks on your processing windows. The Whaletail threads break this down using exactly what I ended up implementing — a layered identity graph that runs as a separate stateful service behind an API gateway, with the profiling engine consuming resolved identities through a materialized view that updates every three seconds. Practical setup: you will need a schema registry that enforces compatibility rules at the producer level, not the consumer level. When a bureau feed changes its date format from DDMMYYYY to ISO8601 mid-stream, your pipeline should reject the message before it touches any downstream processing. I configured Confluent Schema Registry with strict backward compatibility and set the tolerance to reject any envelope change that doesn't preserve field ordering for key columns like account_id and timestamp. This caught about twelve breaking changes per month in my environment before they could corrupt the profile store.
The Data Flow You Actually Need
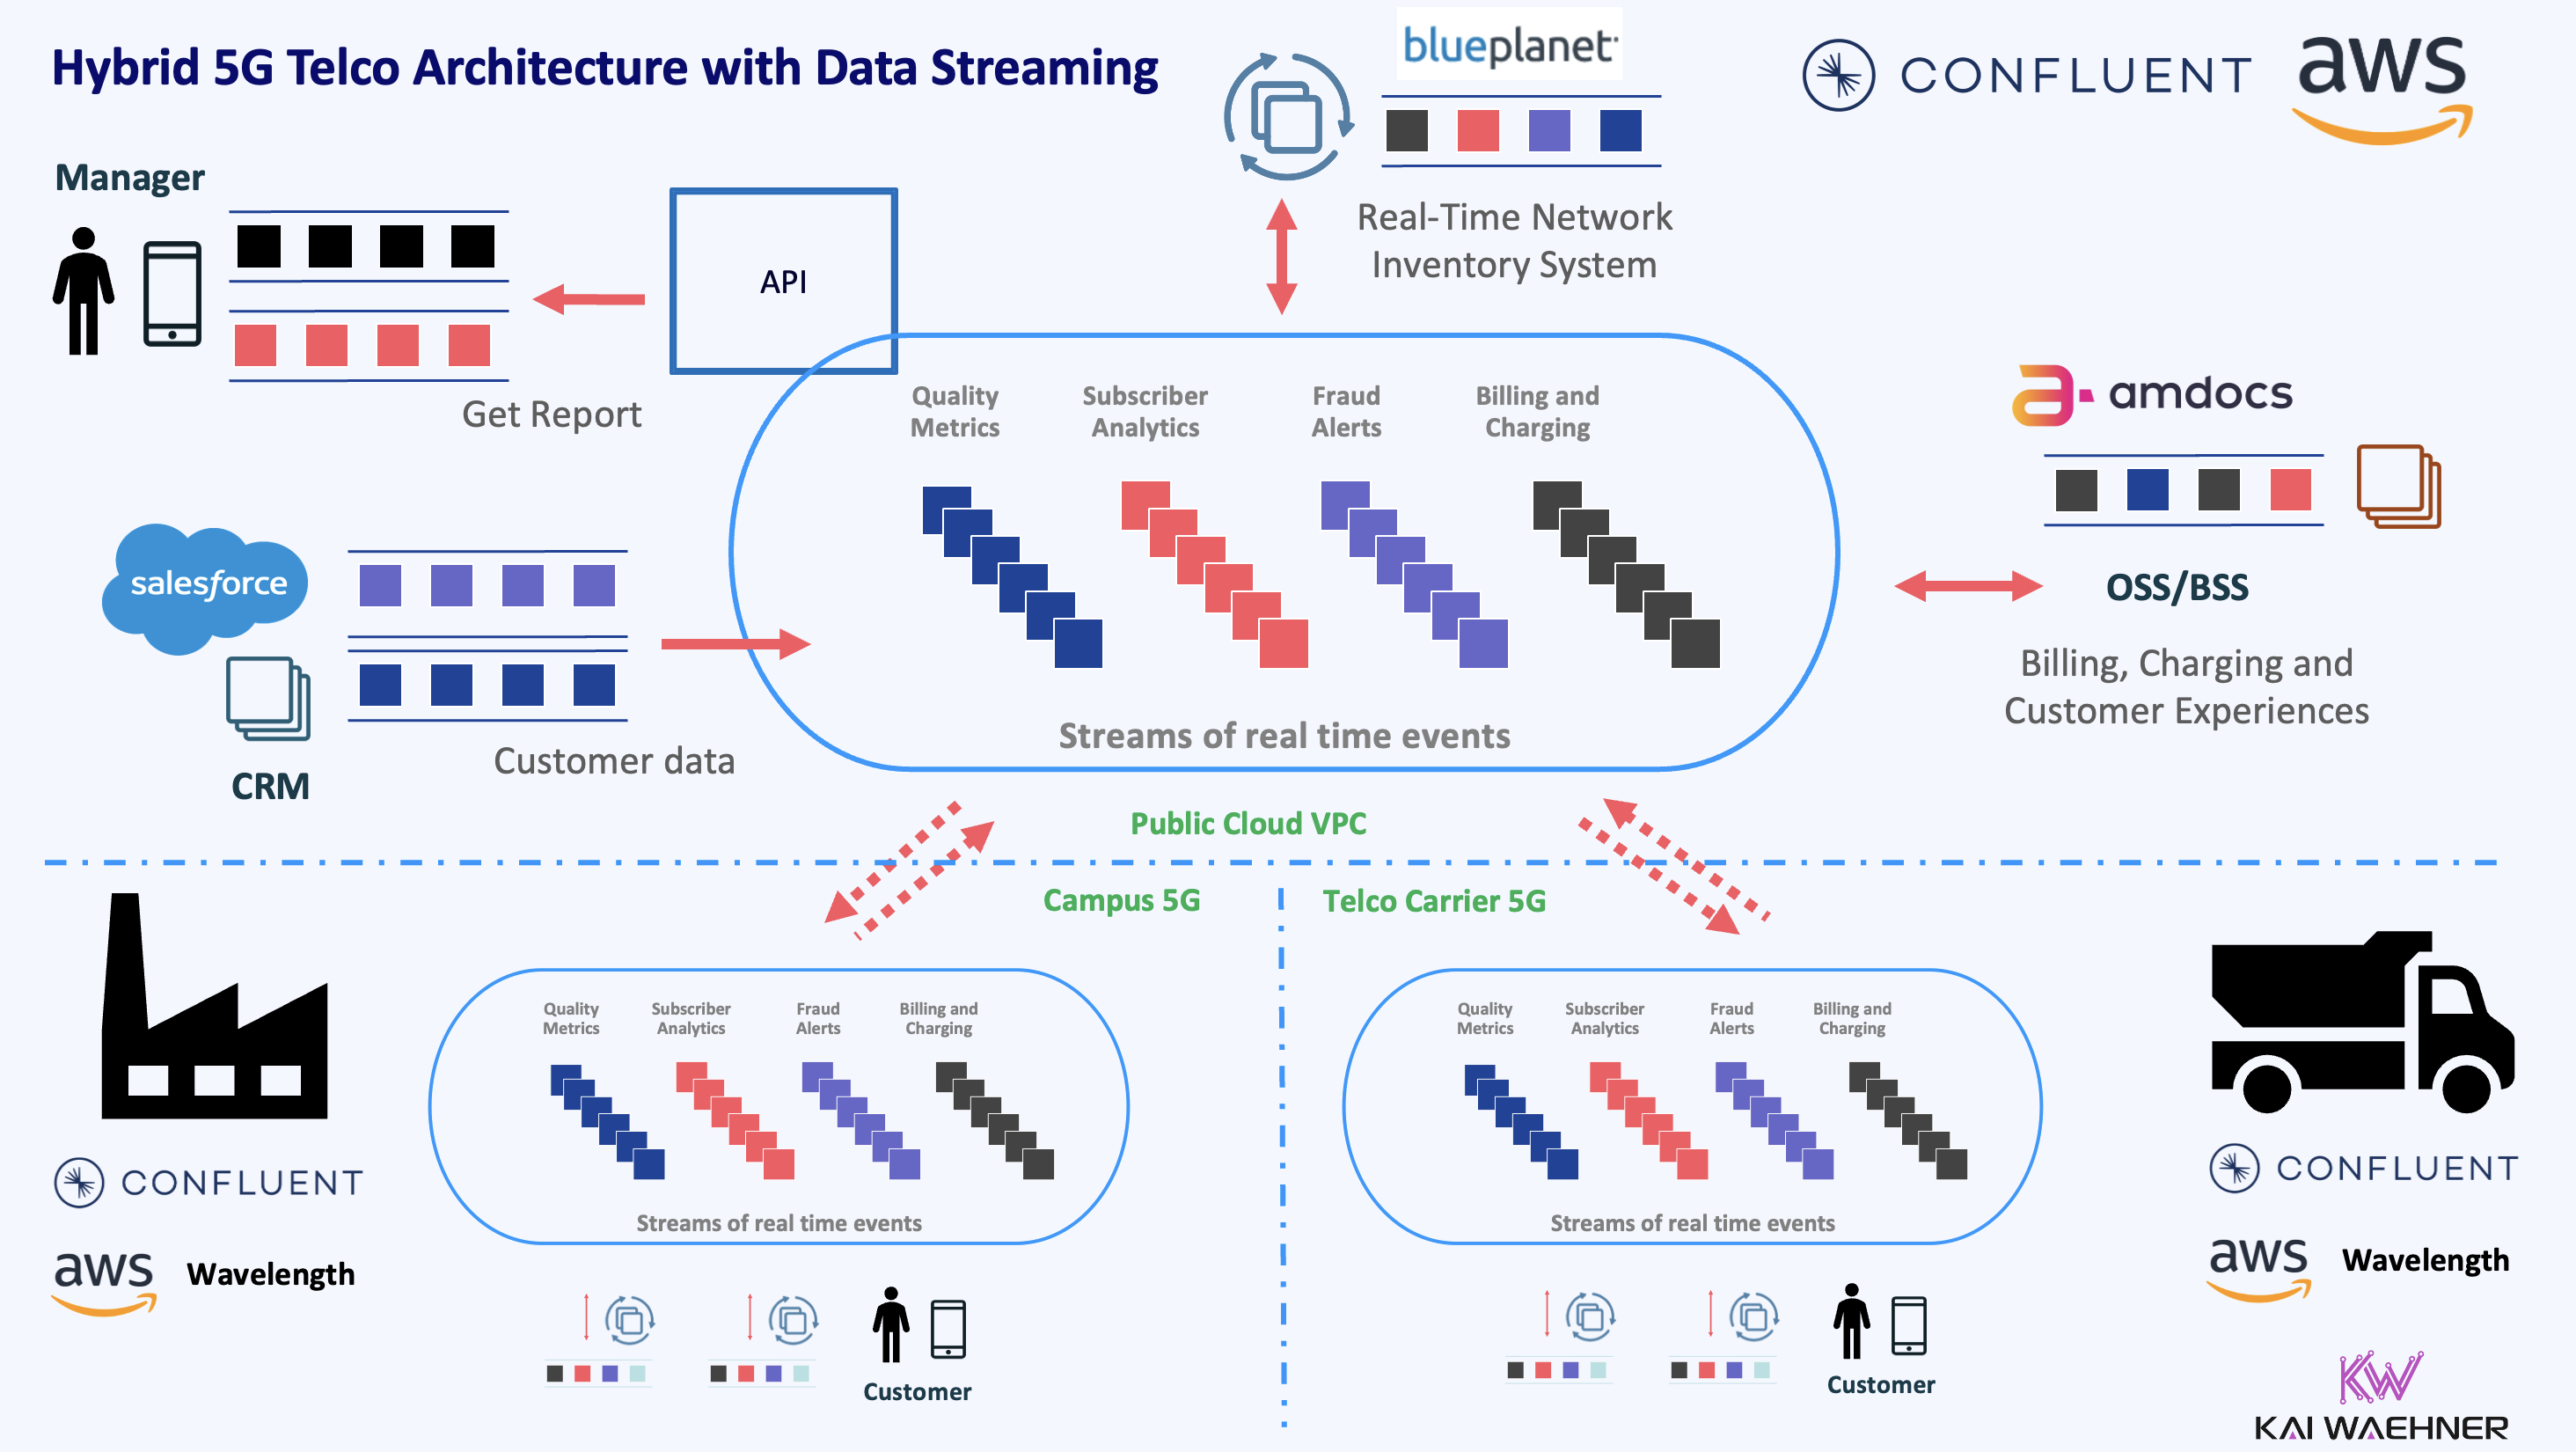
Here is the flow that survived production. Sources emit raw events into topic partitions keyed by an ephemeral device or session identifier. A stream processor resolves that ephemeral ID against the identity graph using a windowed lookup with a twenty-second tolerance. Resolved identities flow into a second topic where profiling aggregations happen — rolling fifteen-minute windows for velocity checks, daily aggregates for behavioral baselines, and persistent snapshots for the final profile record stored in Cassandra or ScyllaDB. The velocity check piece is where beginners waste weeks. They try to count events per customer in real time and end up with watermarking issues that cause double counts during late arrivals. I solved it by using a secondary stream that tracks the last known sequence number per identity and applies a delta filter. If the delta is zero or negative, the event is either a duplicate or out of order past the tolerance window, and it gets routed to a dead letter queue with a reason code instead of being processed twice. This cut our false-positive fraud alerts by thirty-four percent in the first quarter after deployment.
Common Pitfalls That Will Cost You
The biggest issue I see repeated in these forums is underestimating state management costs. Every windowed aggregation requires state storage. A fifteen-minute sliding window across a hundred thousand active profiles means you are holding approximately 1.5 million state entries at any given time, each with timestamps, counters, and TTL metadata. In my experience, this runs about 2.3 gigabytes of heap per partition on a standard Flink cluster. If you need forty partitions, you are looking at ninety-two gigabytes just for aggregation state, not including checkpoints or the identity graph backend. Another trap is assuming your profiling latency will match your ingestion latency. They will not. The identity resolution hop alone adds twelve to eighteen milliseconds under normal load. Window assignments add another six to ten milliseconds. Serialization and deserialization between the stream processor and the profile store adds more. The real end-to-end latency from event ingestion to profile availability is typically sixty to one hundred twenty milliseconds, not the sub-ten-millisecond figures you see in marketing materials. Plan your service level objectives accordingly or your engineers will spend weekends chasing phantom bottlenecks.
Get the Full Details

What This Approach Cannot Handle
Let me be clear about where this architecture breaks. If you are dealing with regulatory regimes that require auditability at the individual event level — meaning every decision made on a profile must be traceable back to the exact input events — then streaming-only profiling will fail you. The windowed aggregates discard raw data by design. I had to layer a synchronous write-through to an audit log table in PostgreSQL alongside every profile update, which added about eight milliseconds of write amplification and required a separate connection pool. Without it, we could not satisfy SOC 2 examination requests for decision traceability. If your data sources have inconsistent timestamps due to client-side clock skew exceeding thirty seconds, the identity resolution windows will fragment profiles incorrectly. One customer's events can split across two identity records if their machine clocks drift significantly. I implemented a client-side NTP correction step that adjusts timestamps before they enter the stream, using the difference between the device clock and a reference server. Machines with skew greater than five seconds get flagged and routed for manual review rather than auto-resolved. This catches roughly two percent of connections but prevents profile corruption on the remaining ninety-eight percent.
Implementation Checklist
Start with your schema definitions before you provision any infrastructure. Write down every field that will appear in a financial profile, their types, their tolerances, and their update frequencies. The fields that change most frequently — things like transaction velocity or login count — should live in the high-throughput stream processing layer. The fields that are stable — address, employment status, credit tier — should live in the persistent profile store and only update on verified changes. Partition your Kafka topics by the resolved identity key, not the ephemeral key. If you partition by ephemeral key, every profile update requires a rebalance across partitions because the same customer will appear in different partitions as their device context changes. This causes state migration overhead and checkpoint failures. Partition by the resolved identity from the start and accept that your identity resolution service becomes a critical dependency that must maintain higher availability than your ingestion layer. Set your checkpoint interval to thirty seconds for the stream processors and configure exactly-once semantics only on the state backends, not on the entire pipeline. Exactly-once across the full pipeline is a myth at scale. Your profiling outputs will be near-deterministic with semantic exactly-once on state alone. The difference is negligible for financial profiling purposes where a twenty-millisecond duplication window does not change risk decisions, but the operational complexity of full exactly-once semantics increases your mean time to recovery by a factor of three during failures.
Monitor the lag between your identity resolution output topic and your profiling aggregation input topic. If that lag exceeds twenty seconds, your velocity calculations are stale and your risk scores are based on outdated behavior. I set up alerting at fifteen seconds of lag and an automatic throttle that reduces ingestion throughput by half until the lag clears. This prevents cascade failures where a slow profile store causes backpressure that eventually crashes the entire streaming topology.