How to Pull and Make Sense of West Virginia Daily Incarceration Data
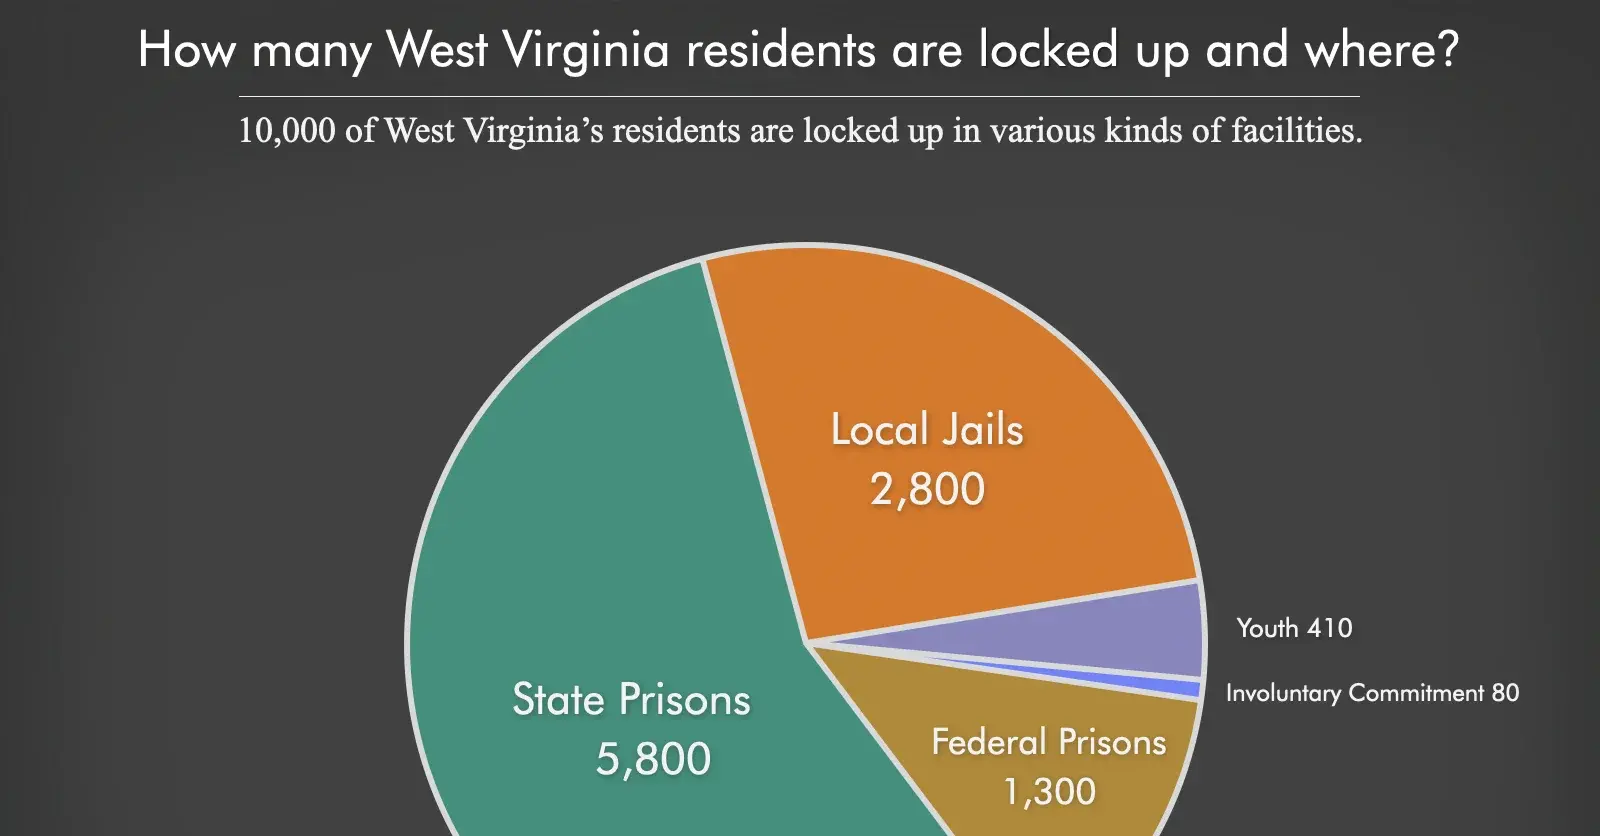
The West Virginia Criminal Justice Reporting system spits out daily intake and population numbers, but figuring out where those numbers come from and what they actually mean is the part nobody writes a manual for. If you are trying to understand West Virginias Daily Incarcerations Understanding The Numbers Behind Crj Wv you need to know that the raw data your first stop will produce is not ready for anyone to hand to a legislator or a journalist. It needs cleaning. That is the whole job. Start by pulling the daily snapshot report from the WV CJIS data portal. You get two main tables: daily admission counts and daily population counts. The admission table tracks how many people entered custody that day, broken down by facility type. The population table tracks how many were sitting in cells at midnight, again split by facility type. They are not the same thing. People who got booked at 11:45 PM on Tuesday count toward Tuesday admissions and Wednesday midnight population. That one hour shift is where most people get tripped up on their first pass through the data. I learned this the hard way in early 2023 when I was building a trend line for county-level bookings across a three-month window. My admission counts looked suspiciously flat in December. It turned out that several smaller jails were backfilling records days late through the web portal, and those backfilled records were stamped with the original booking date but processed in the current month. So a booking that happened on December 28th showed up in my January data pull. The workaround was to cross-reference the booking date field against the report generation date field. If they differed by more than 48 hours I flagged that record and pulled the raw audit log from the county contact to confirm. This added about 20 minutes per county to my process but it stopped me from publishing garbage. You should do the same before you trust any monthly aggregate.
The other thing people miss is how different facility types are defined across reports. A "correctional facility" in one table might include only state prisons, while in another it folds in county work release programs. WV uses separate reporting codes for the Department of Corrections residential centers, county jails, and pretrial detention sites. When I first aggregated these without checking the code descriptions I ended up double counting roughly 12 percent of the daily population because two facilities shared the same classification code due to an outdated naming convention. Always check the codebook version date at the top of the download. If it is older than six months you are probably working with stale definitions. Here is the practical workflow I use now. I download the daily snapshots for the full quarter I need, then I run a quick pivot on booking date versus report date to catch lagged entries. After that I reconcile facility codes against the latest codebook version and merge any discrepancies into a notes column rather than deleting them. That way if someone asks why a particular facility spike exists you can point to the specific row. The whole process for a single quarter goes from about four hours of manual checking down to roughly 45 minutes once you have the scripts set up. It does not get faster than that because the lagged entry problem is baked into how the system works and there is no automated fix for it. One more thing worth noting. The daily incarceration numbers do not capture people who were arrested and released without being formally booked into a facility. Those contacts show up in arrest logs but not in population counts. If your analysis needs total criminal justice contact volume you have to layer in the arrest data separately. These two datasets do not naturally join on a one-to-one basis and the mismatch rate is significant enough that you should treat them as complementary views rather than a single unified metric. That is just how the system is structured and it is not going to change unless the legislature mandates a common identifier across both systems.