
When You Suspect a Site Is Down and Need Answers Now
The first thing most people try is opening the site themselves. It works sometimes, but it's unreliable. Your browser caches pages. CDNs serve stale content from a node near you. The site might be down for everyone except you, or just for you, and you won't know which without actually checking multiple angles. Here's what actually happens when you're trying to figure out whether a site is genuinely down or it's something on your end. You start with a ping, then move to DNS lookups, then check from external services, then dig into HTTP response codes if you need more detail. Each step eliminates a different possible cause. I spent three hours last year chasing what I thought was a server outage. The site was loading for half my users and timing out for the other half. Turns out it wasn't down at all — it was a stale Cloudflare cache holding onto an error response from a deployment that went bad forty minutes earlier. Flushing the cache took six seconds. The ping and traceroute I'd run earlier had shown nothing wrong because Cloudflare was responding just fine with the wrong content.
Step One: Ping and Trace Route
Ping sends ICMP packets to the domain and measures how long they take to come back. A successful ping with reasonable latency tells you the host is reachable at the network level. If you get request timeouts or a destination host unreachable message, the problem could be at the network layer — a router down, an ISP issue, or the server simply not responding to pings, which is common because many admins block ICMP for security reasons. Traceroute shows you each hop the packets take. This is useful when a ping fails. If the trace stops at a specific gateway, you've identified where the break is. I once found a routing loop between two upstream providers causing intermittent timeouts for a client. Traceroute revealed the packets were bouncing between the same two nodes repeatedly before eventually timing out. Switching to a different upstream provider fixed it within the hour.
Step Two: DNS Resolution Check
DNS issues account for roughly a third of what people think are website outages. The site's server might be perfectly fine, but if DNS can't resolve the domain name, the browser never reaches it. Run a DNS lookup using a tool like dig or nslookup from multiple locations. Compare the results against what you expect the IP addresses to be. One thing beginners miss: DNS propagation isn't instant. If you recently changed nameservers or updated an A record, different resolvers around the world will show different results for several hours. Checking from a single location gives you a false sense of certainty. Use a public DNS like 8.8.8.8 or 1.1.1.1 and compare against your local resolver. If they disagree, you're looking at a propagation issue, not an outage.
Get the Full Details
Step Three: External Uptime Services
Sites like IsItDownRightNow, DownDetector, and SameDayData aggregate reports from thousands of users and third-party monitors. They're useful for quickly confirming whether an issue is widespread. If you're the only one reporting a problem, it's almost certainly on your side. If thousands of people are hitting the same error, it's real. These services have limitations though. They only check from their own monitoring nodes, which are concentrated in specific regions and data centers. A site might be down in Frankfurt but fine in Texas, and the monitoring service in Ashburn won't catch it. For global sites, this means you're getting a snapshot, not the full picture. I learned this the hard way when monitoring showed a client's site as "up" for two days while their European customers were getting connection refused errors. Their German hosting provider had a router failure that the US-based monitors couldn't see.
Step Four: HTTP Response Code Analysis
This is where you get specific. Use curl with the -I flag to fetch just the headers, or use the -v flag for verbose output. What you're looking for is the status code and how quickly it comes back. A 200 means the site is up and serving content normally. A 301 or 302 means a redirect is in place — check where it's pointing because misconfigured redirects are a frequent source of "my site is broken" tickets. A 403 means access is blocked, usually by firewall rules or .htaccess. A 404 means the page doesn't exist. A 500-series code means the server is having problems, and 503 specifically means the server is temporarily unable to handle the request. Response time matters too. A site returning a 200 after twelve seconds is effectively down for any user who expects a normal browsing experience. I had a client whose database queries were timing out under load, so every request to their API was taking fifteen to twenty seconds before finally succeeding. The status code was always 200, so the automated monitors showed everything as healthy. Setting a response time threshold of three seconds on the monitors would have caught this immediately.
Step Five: Check From Multiple Networks and Devices
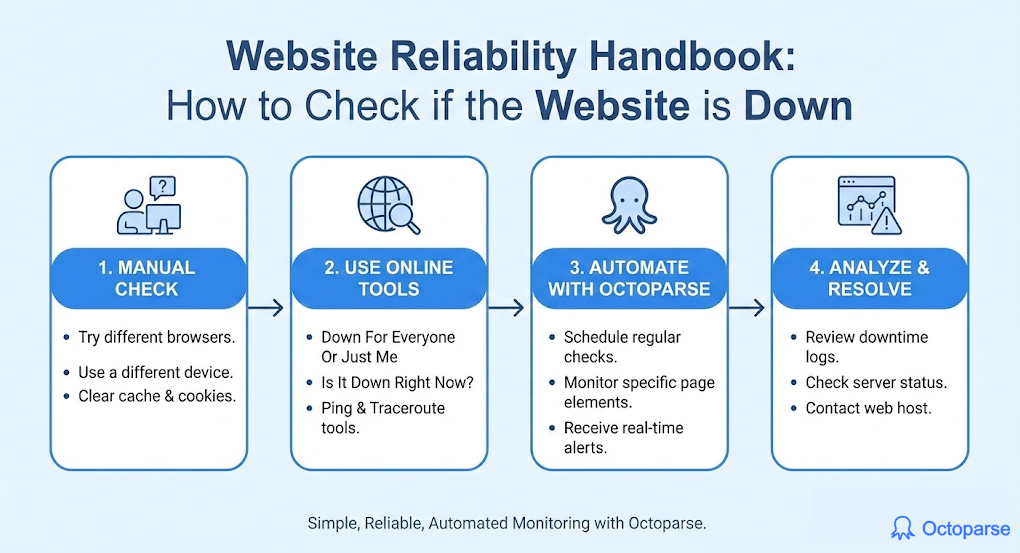
Your home internet, your phone's cellular data, and a VPN connection can all produce different results. An ISP-level block, a geo-restriction, or a CDN edge node failure might affect one connection type but not others. Try accessing the site from your mobile data, from a coworker's network, and through a different browser or incognito window. Browser cache and extensions are surprisingly common culprits for perceived outages. No single tool catches everything. Ping and DNS checks only verify reachability and name resolution. HTTP checks verify the web server is responding but don't tell you whether the application logic is working. A site can return 200 OK for every page while the checkout system is completely broken, the login form returns invalid credentials for valid users, or images fail to load because the storage bucket is misconfigured. For application-level issues, you need actual user journey testing. Some teams use synthetic monitoring that simulates a complete login-and-purchase flow from multiple geographic locations. These catch problems that simple uptime checks miss, but they cost money and require setup. A free alternative is to manually walk through the critical paths on the site from different devices and networks. It's slower, but it's also more thorough than any automated check for specific functionality.
There's also the issue of partial outages. A database replication lag might make read traffic succeed while write operations fail. An API endpoint might work for some users and not others based on which backend server they hit. These scenarios don't show up in any of the methods above until someone actually tries to perform the failing action. That's just how distributed systems work — there's no shortcut around it.


