The Reality of Multistaff Scheduling Tools
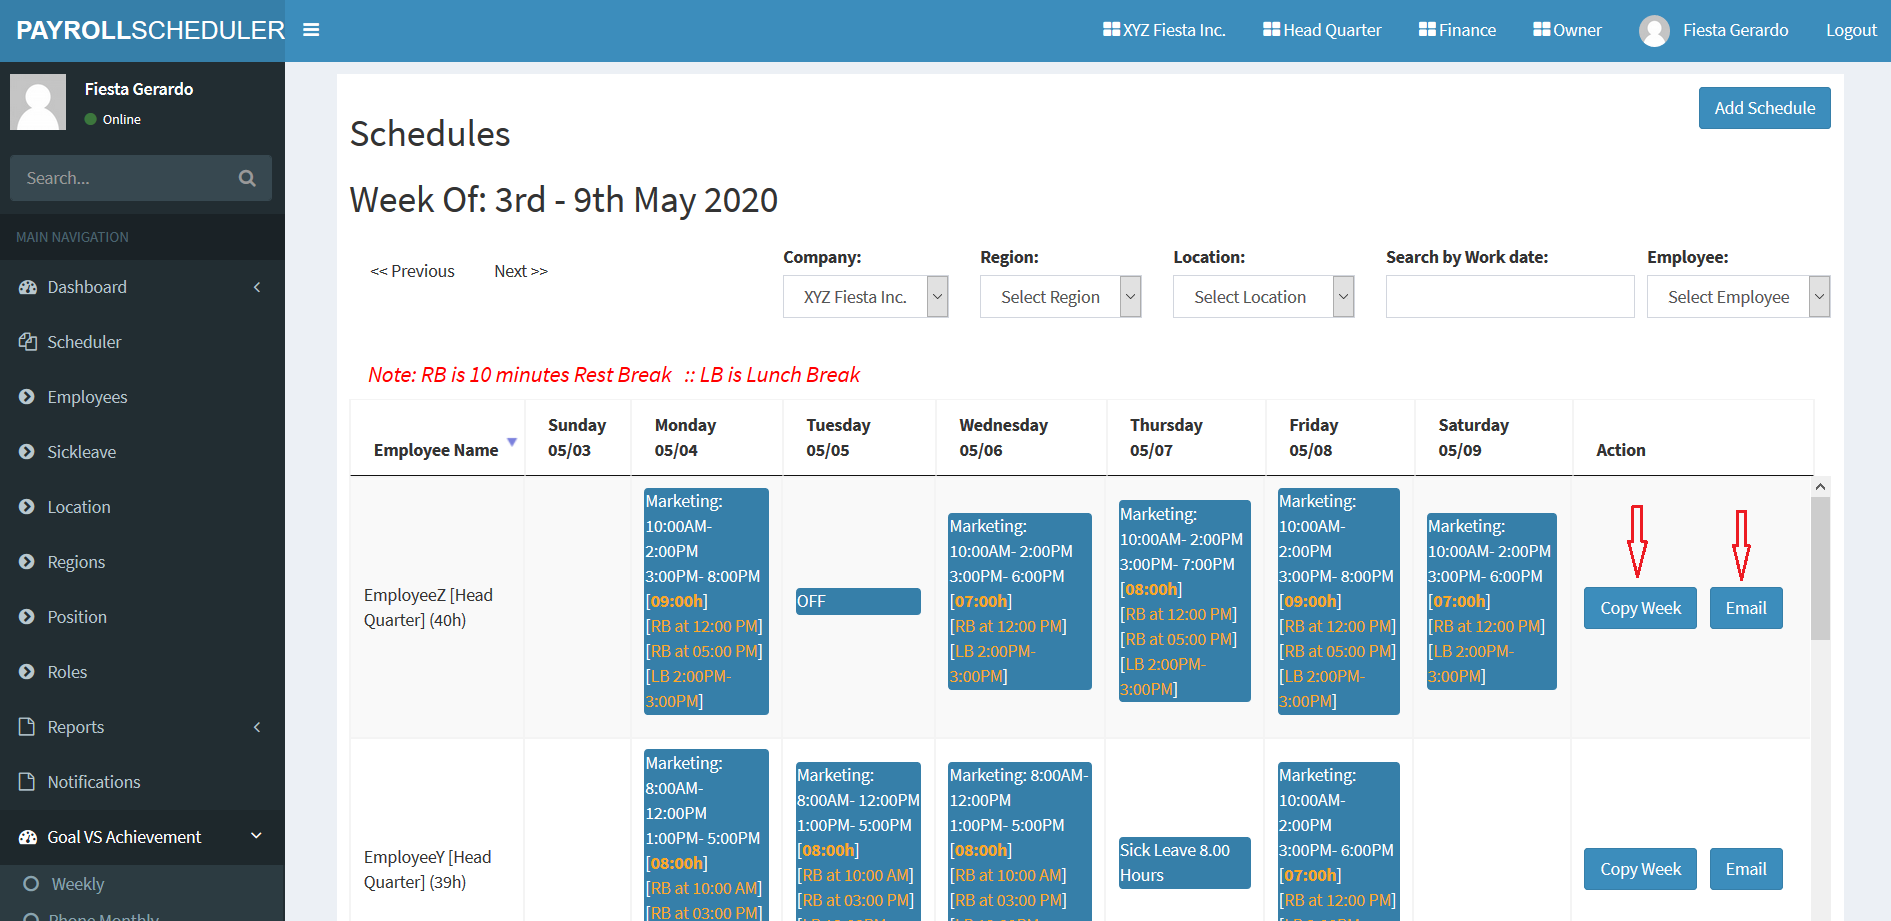
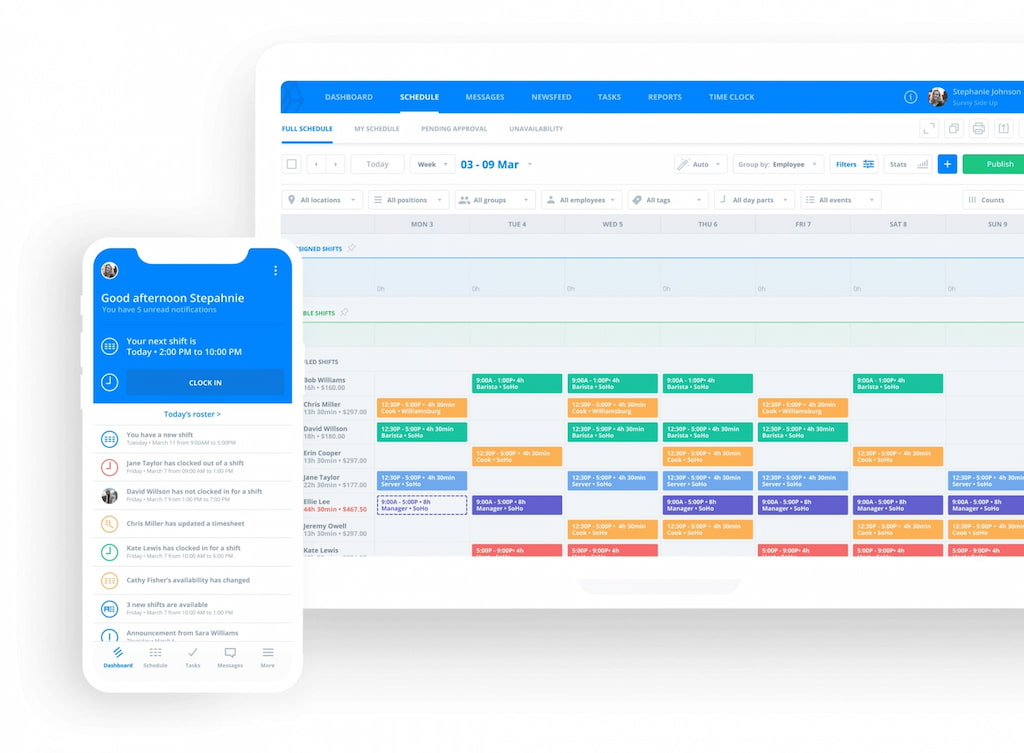
Multistaff scheduling software has become one of those things every operations manager eventually has to deal with. You start with spreadsheets, then you add a second department, then a third shifts pattern that doesn't fit the template, and suddenly your Google Sheet looks like it was designed by someone who wanted chaos. The transition to a dedicated web scheduler isn't glamorous. It is mostly just a relief at first because someone else's engineers actually thought about edge cases you have been encountering for years. The core function is straightforward. You define shifts, constraints, and staffing requirements, and the system assigns available employees to those slots. What happens after that is where the platform choices matter significantly. A basic scheduler will dump names into cells and call it done. A proper multistaff scheduling tool handles overlapping constraints, legal rest requirements, union rules, skill-tag matching, and the constant reality that Sarah called in sick three hours before her shift. I built and then maintained scheduling workflows across four different departments for about six years before moving to automated systems. The thing nobody tells you during a demo is how much time actually gets consumed by the mismatch between what the scheduler assumes and what your workforce does. The tool will happily assign someone who just worked eleven hours straight if you haven't hardcoded the rest period rule. It will not call out that two nurses with a dependency relationship ended up on the same closing shift unless you specifically configured the constraint. This is why multistaff scheduling often breaks in production even when the pilot run looked fine.
How the System Actually Works Under the Hood
At its foundation, most web schedulers use a combination of constraint satisfaction and optimization algorithms. You provide hard constraints such as maximum hours per week, mandatory break durations, and certification requirements. Then you provide soft constraints like employee preferences or desired shift distribution. The engine runs through iterations trying to satisfy as many constraints as possible while optimizing for the objectives you set. The process typically involves these stages: Configuration phase: You input your staffing model, define roles, set shift templates, and establish the constraint library. This is where most implementations fail. People rush through it because it feels tedious, then spend months dealing with the fallout.
Data import phase: Employee availability, PTO requests, and historical attendance patterns get loaded into the system. Clean data here matters enormously. Garbage in produces garbage out, which sounds obvious until you have inherited a schedule from someone who marked everyone as always available. Scheduling phase: The engine generates candidate schedules, either automatically or with a scheduler manually adjusting. Modern systems offer a hybrid approach where the algorithm proposes assignments and humans refine them. Publication and communication: The final schedule gets pushed to employee self-service portals, mobile apps, or integrations with payroll and time tracking systems.
Get the Full Details
The Hidden Complexity That Makes or Breaks Implementation
The counter-intuitive part about multistaff scheduling platforms is that the hardest component is rarely the algorithm itself. It is the configuration and maintenance of business rules. Every department operates differently. Healthcare requires ratio-based staffing. Retail needs coverage windows. Manufacturing deals with shift handoff overlaps. A single poorly defined rule can cascade through your entire scheduling cycle. I encountered a specific problem once with a mid-size healthcare network that adopted a popular web scheduler. The system allowed a certain number of weekend rotations per quarter, and the default setting was configured for a five-day workweek model. When we tried to schedule their night shift staff, the algorithm kept violating an implicit constraint around consecutive days off. It wasn't broken. The constraint had just been defined using day-counts instead of hour-counts, and the night rotation spanned approximately thirty-six real hours across two calendar days. The scheduler counted it as one shift and moved on. The workaround was to create a custom attribute mapping each night rotation to a fractional shift value and to override the standard constraint validation with a weighted scoring function that penalized back-to-back night assignments more heavily. It took about an afternoon of configuration work, but after that the engine produced viable schedules consistently. The vendor's support team couldn't explain why it happened initially because they were looking at the feature documentation, not the actual constraint evaluation logic.
Common Pitfalls When Setting Up Your Scheduler
Underestimating constraint complexity is the most frequent mistake. Teams create broad rules like "no more than five consecutive shifts" without considering that different departments have different intensities. An ambulance crew working five consecutive days faces a fundamentally different fatigue profile than a front desk worker doing the same pattern. Another pitfall is ignoring historical data quality. If your past schedules contain systematic errors, like managers consistently overstaffing Friday nights because they couldn't find coverage, the algorithm will replicate those patterns or worse. The scheduler optimizes based on what you feed it, not what you actually need. A third issue involves change resistance disguised as configuration demands. When a new scheduling tool is introduced, managers often request excessive customization because they want the system to replicate exactly what their spreadsheet did. This is a trap. If your current process is broken, automating it just makes the broken process faster and harder to undo later. Take the time to redesign the workflow before you automate it.
When a Web Scheduler Won't Help You
Not every organization benefits from investing in a dedicated multistaff scheduling platform. If you have fewer than fifteen employees across all locations, a well-maintained spreadsheet or a shared calendar often does the job adequately. The overhead of implementing and maintaining a scheduling tool exceeds the time you would save for another six months of actual usage. Similarly, organizations with highly irregular scheduling needs that fall outside standard constraint models struggle with most commercial schedulers. If your operations depend on real-time volunteer coordination, last-minute gig worker placement, or ad-hoc shift swapping that happens dozens of times per day, a traditional scheduler becomes a bottleneck rather than a solution. In those cases, a lightweight shift-swap platform or even a purpose-built internal tool may serve you better. There is also the cost of ongoing administration to consider. A scheduling system requires someone to maintain it. This means updating policies, managing new hire onboarding, handling constraint exceptions, and troubleshooting when the engine produces unexpected results. If no one in your organization has the time or inclination to manage the tool, it will become stale and eventually get bypassed, which is worse than never having implemented it in the first place.
What to Look For in an Actual Deployment
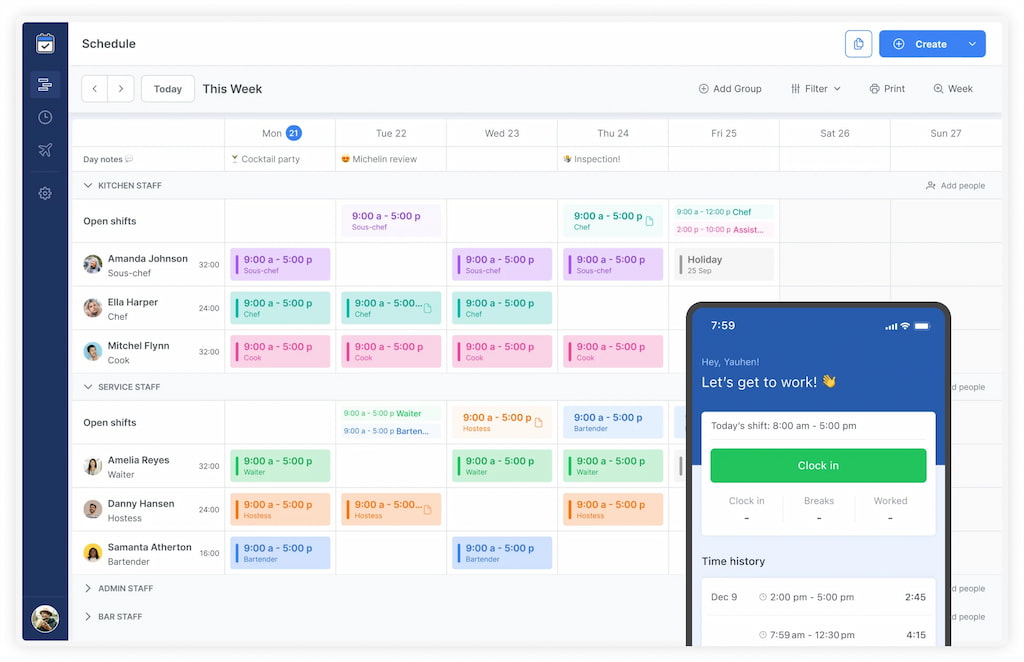
The features that matter most in practice are fairly different from the ones highlighted in marketing materials. Employee self-service is essential because it offloads scheduling communication onto the staff themselves. When people can view their schedule, request time off, and swap shifts through a portal, your administrative burden drops significantly. Without it, every schedule change generates an email or a phone call. Integration capabilities are equally important. Your scheduler needs to connect with payroll, time tracking, and potentially your HRIS. The friction of manually transferring schedule data into another system erodes the efficiency gains within weeks of going live. Reporting should go beyond basic headcount summaries. Useful reports track schedule adherence, overtime accumulation, forecasted versus actual staffing levels, and constraint violation rates. These metrics tell you whether your scheduling model is actually working or just producing assignments that look correct on paper.
One feature that receives less attention but proves valuable is what I call graceful degradation. This is the system's ability to produce a usable schedule even when constraints conflict. A scheduler that either crashes or returns an empty result when faced with impossible parameters is not useful in production. Look for a system that flags conflicts and presents the manager with the trade-offs so a decision can be made rather than automated.
The Practical Timeline for Getting Value
Expect a three to six month ramp-up period before a multistaff scheduling tool delivers measurable ROI. The first month involves configuration and data migration. The second month covers pilot testing with a single department or location. The third through sixth months handle organization-wide rollout and the inevitable adjustment period where staff learn the new system and exception handling becomes routine. If you are running a small organization with simple scheduling needs, this timeline compresses considerably. Large enterprises with complex regulatory environments may need longer. The variable that matters most is how clearly your organization has defined its scheduling policies before starting implementation. Ambiguous policies create ambiguous configurations, and ambiguous configurations produce unreliable schedules. The bottom line is that multistaff scheduling software transforms your operations only if you treat it as a systems project rather than a software installation. The tool does the calculation. You have to provide the correct constraints, clean data, and ongoing management attention. Done right, it eliminates the most tedious parts of scheduling and surfaces the strategic decisions that actually require human judgment. Done poorly, it just automates your existing confusion at scale.