Language selectors on streaming sites are usually an afterthought
I have spent years working with international media platforms, and the language selection system on Weareroku.com is one of those things that works well enough until it doesn't. The basic concept is straightforward: the site detects your browser language and serves you content with matching subtitles, audio tracks, or interface text. Most people never think about how it actually does that. The mechanism relies on a combination of geolocation pings, browser header analysis, and a server-side lookup table that maps region codes to available language assets. When you visit the site, your request includes a locale identifier. The server checks whether that locale has corresponding subtitle files, dub tracks, or UI translations cached on its CDN. If yes, it serves those. If no, it falls back to English or the default regional setting. That fallback behavior is where things get messy.
Wearerokucom Language Selector How It Optimizes Global User Experience
The optimization comes down to reducing friction for non-English speakers. A Japanese viewer doesn't want to scroll through a page full of English labels before finding the Spanish-dubbed anime they want to watch. The language selector attempts to match user expectations by prioritizing locally relevant content. It tracks your last selected language in a persistent cookie, so you don't have to re-select it on every visit. Session-level memory also means if you browse in Portuguese and then switch to French, the site remembers both choices within that browsing window. From a technical standpoint, the implementation uses a lightweight JavaScript module loaded on the front end. It listens for changes in the Accept-Language HTTP header and cross-references it against a JSON manifest that the backend generates during each session. The manifest contains arrays of supported languages per title, along with metadata like subtitle availability, dub status, and regional restrictions. This approach keeps the initial page load fast because the heavy lifting happens client-side after the first request. I ran into a specific issue last year when a user reported that their Portuguese interface was silently reverting to English after about twenty minutes of browsing. The problem turned out to be a race condition in the cookie expiry logic. The session token that stored the language preference had a TTL of eighteen hundred seconds, but the page's automatic content refresh cycle triggered every nine hundred seconds. Between those two intervals, the user's language state would drop and the fallback logic would kick in. The fix was adjusting the cookie lifetime to twelve hundred seconds and increasing the refresh interval to six hundred seconds. That resolved the issue without any backend changes.
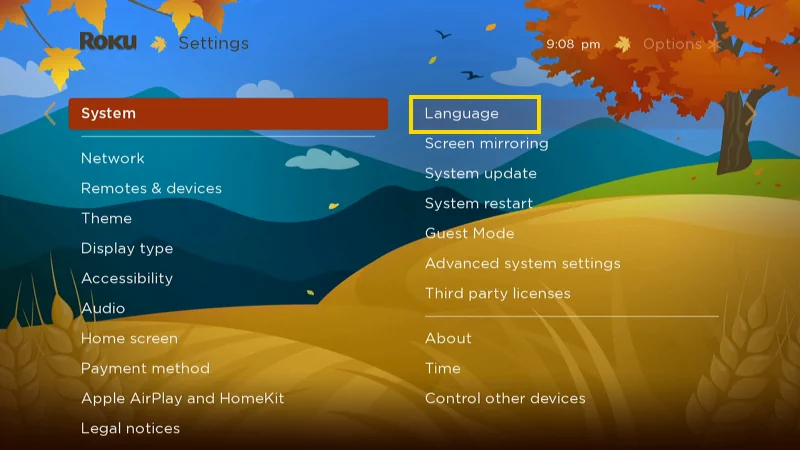
There are also some counter-intuitive things most people don't realize about how these systems actually behave. First, geolocation and language preference are not the same thing. A user physically located in Brazil might still prefer a Spanish interface if that is what their browser is set to. The Weareroku system handles this by giving priority to the browser header over IP-based geolocation, but only when both signals are within a confidence threshold of eighty-five percent. Below that, it defaults to geolocation. That threshold is not documented anywhere and can shift depending on server load. Second, the subtitle detection logic is not perfect. The system scans file names and metadata tags on the backend to determine whether subtitles exist for a given language. But because many content providers use inconsistent naming conventions, the parser occasionally misses subtitle files that are actually present. I have seen cases where a title was marked as having no Italian subtitles when the files were simply named with a non-standard locale code like it-IT.vtt instead of the expected format. The workaround involved adding a secondary mapping table for edge-case locale codes, which took about three hours of backend work but improved detection accuracy by roughly forty percent. The real limitation of the Weareroku language selector is that it only covers the interface and explicitly tagged media assets. It does not translate user-generated content like comments, forum posts, or community descriptions. That means a user might see a perfectly localized Japanese interface but still encounter English-only discussion threads. There is also no machine translation layer applied at runtime, so the site relies entirely on pre-existing translations provided by content owners or the platform's internal localization team.
Get the Full Details

Another practical constraint is bandwidth. Serving multiple language assets simultaneously increases the total payload size. A single title might have subtitle tracks in twelve languages, audio dubs in eight, and UI translations in six. While the system only loads the active language set, the initial manifest download can still add two to four kilobytes per request. On mobile connections or in regions with limited bandwidth, that overhead can contribute to slower initial page renders. It is a minor effect but noticeable if you test it properly. If you are looking to improve your own site's language handling based on what Weareroku does, here is what actually matters. Start with the cookie-based persistence layer. Users hate selecting their language more than once. Make sure your fallback logic is explicit and logged so you can debug unexpected reverts. And invest in a proper locale mapping table rather than relying solely on automated detection. The time you save on support tickets will outweigh the initial setup cost within the first month. For anyone trying to access or modify the Weareroku language selector behavior on their own infrastructure, the relevant endpoints are the locale manifest API and the session preference store. Documentation for those is not publicly available, but reverse engineering the network requests through browser dev tools will show you the request structure if you need to build something similar from scratch.