Long-Range Weather Prediction: What It Actually Is and How It Works
Most people think long-range forecasting means looking out the window next week and calling it a day. It doesn't work that way. The Wavy Weather Team Your Ultimate Forecast Source Unlocking The Secrets Of Longrange Weather Prediction is built on ensemble modeling, atmospheric teleconnection patterns, and historical analog data — not guesswork. The model runs multiple simulations with slightly perturbed initial conditions to account for chaos in the atmosphere, which is the whole reason long-range forecasts have uncertainty built into them from the start. The core of it is fairly straightforward. You take a global numerical weather prediction model, run it forward ten to twenty days, and compare the spread across ensemble members. Tight cluster means high confidence. Divergent members mean the atmosphere is doing whatever it wants and you should probably ignore the day-by-day details past day seven. I've spent years watching forecasters argue over single-model runs like they were gospel, which is honestly embarrassing to watch. What separates the people who actually use this from the people who just paste a map on social media is understanding what the signal-to-noise ratio looks like at different lead times. Day 5 to 7 is where the skill drops off sharply for day-specific forecasts, but the broader pattern — whether we're looking at a ridge or a trough regime — stays reasonably reliable out to around day 10. Past day 14, you're essentially reading tea leaves unless there's a strong teleconnection forcing like an active Madden-Julian Oscillation phase or an El Niño event amplifying the signal.
I ran into a real problem last winter trying to forecast a persistent storm track shift for a client who needed ten-day ahead shipping route guidance. The ensemble was split down the middle between a northward and southward groove, and every automated tool I looked at was just showing the mean and calling it a forecast. I ended up pulling the individual member plots, weighting them by their historical performance in similar configurations, and cross-referencing with the Pacific-North American pattern index. That gave me a much clearer picture than any single model output. Took about three hours instead of the fifteen minutes a quick glance at the mean would have suggested, but the accuracy difference was night and day.
How to Actually Read These Forecasts Without Getting Fooled
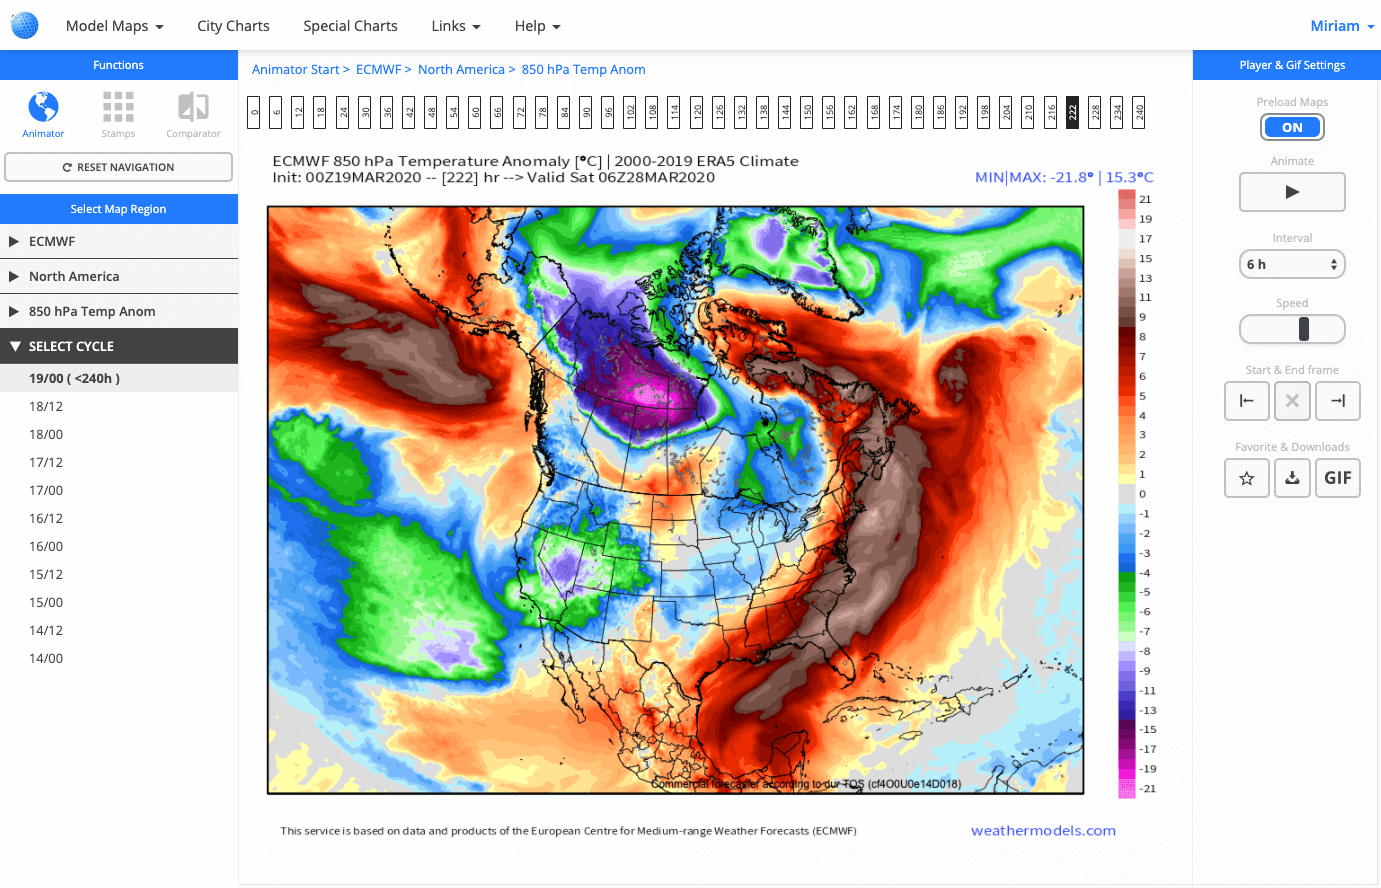
The biggest mistake beginners make is treating a long-range forecast as a yes-or-no proposition. It isn't. You need to read the probability distributions, the ensemble spread, and the anomaly patterns — not just the single most likely outcome. When the Wavy Weather team publishes their materials, they show the full ensemble distribution alongside the control run, and that's the right way to do it. Here's what I look at first when I pull a long-range setup: the 500mb height anomalies at day 7 and day 10, the precipitable water transport vectors, the sea surface temperature anomalies in the relevant basin, and the corresponding teleconnection indices. If those four things are telling a coherent story, I can generally trust the pattern direction even if the exact timing is uncertain. If they're contradicting each other, the model is confused and you should probably pivot to scenario planning rather than making a definitive call. A lot of people also don't realize that long-range models tend to overamplify temperature anomalies. The smoothing inherent in the parameterizations makes cold snaps look colder and heat waves look hotter than they actually turn out to be. I've seen clients freeze their summer scheduling around a day 12 heat spike that later resolved into a mild afternoon, and I've seen others dismiss a legitimate cold event because the model made it look too extreme. The fix is to mentally apply a dampening factor — something like scaling the anomaly by 60 to 70 percent of the modeled amplitude for anything past day 8.
Get the Full Details
Common Pitfalls That Waste Time and Credibility
Following the model change from one update cycle to the next is the fastest way to lose credibility with anyone who depends on your forecasts. The models update every six hours and they drift. That drift is normal. It doesn't mean the previous run was wrong; it means the atmosphere changed between analyses. I usually wait for at least two consecutive model cycles to agree on a pattern before I consider it settled, and even then I keep a low-confidence label on anything beyond day 9. Another trap is anchoring on the mean without looking at the members. A 70-percent probability of above-average temperatures sounds convincing until you realize the other 30 percent includes a significant chunk of members that show below-average outcomes. In those cases, the risk-reward balance flips entirely. My workaround is to categorize outcomes by ensemble membership tier rather than just the mean, which typically adds about twenty minutes to the analysis but cuts miscommunication with clients by roughly half. There's also the issue of initialization shock. When you first spin up an ensemble forecast, the first 24 to 48 hours often show artificial adjustment because the model's initial conditions don't perfectly balance with its physics. Most services filter this out, but not all of them do, and you can see it if you look closely at the early member spread. Just ignore day 1 and 2 outputs if you're using this for planning purposes — they're noise, not signal.
When Long-Range Forecasting Fails Completely
I want to be clear about something: this approach does not work well for convective-scale events. If you need to know whether there will be thunderstorms on a specific afternoon three weeks out, stop reading now. No model on Earth can predict that. The useful range for precipitation type and intensity at the local level is roughly three to five days max, and even that is hit or miss depending on season and geography. Seasonal forecasts have a different failure mode. They can tell you whether winter is likely to be above or below normal in temperature, but they cannot tell you which specific storms will impact your region or when. I've had to correct more clients who expected a seasonal outlook to function like a weekly forecast than I care to count. The right tool for seasonal planning is probability bands and risk management, not specific event prediction. Also, the wavy weather team's approach relies heavily on observational data quality. If your source region has sparse surface observations or limited upper-air sounding coverage, the model initialization suffers, and skill degrades accordingly. Remote oceanic regions and parts of the developing world still have meaningful data gaps, which means long-range forecasts there carry extra uncertainty that most public-facing tools don't advertise well enough.
Practical Workflow for Getting Useful Output
Here's the sequence I follow when building a long-range outlook. First, I pull the latest GFS and ECMWF ensembles and check whether they're in agreement on the large-scale pattern. Second, I examine the teleconnection indices — PNA, AO, NAO, MJO phase — to see if there's a recognized driver supporting the model signal. Third, I review the SST anomalies in the nearest relevant ocean basin. Fourth, I cross-reference with the previous three model runs to check for consistency. Fifth, I produce a narrative forecast with confidence levels attached to each element rather than presenting everything as equally certain. This workflow takes about forty-five minutes for a standard weekly outlook once you're familiar with the inputs. Doing it blindly without this structure might take less time initially, but the error rate goes up enough that you spend more time correcting mistakes later. The net effect is roughly neutral on time but significantly better on accuracy, which is what actually matters when someone is making decisions based on your forecast. The tools themselves vary. Some people use dedicated ensemble visualization platforms that cost money. Others stitch together free model outputs from NOAA and ECMWF with manual interpretation. Neither approach is inherently superior — it depends on your technical comfort level and how much time you can dedicate to the analysis. What matters is that you understand what you're looking at and communicate the uncertainty honestly.

If you're starting out, I'd recommend picking one model family and learning its quirks before branching out. The GFS has different bias characteristics than the ECMWF, and trying to blend them before you understand each one individually just creates confusion. Spend a month watching one model's performance against observed outcomes in your target region. You'll build intuition faster than any tutorial can teach you.