Why Your City Layout Looks The Way It Does
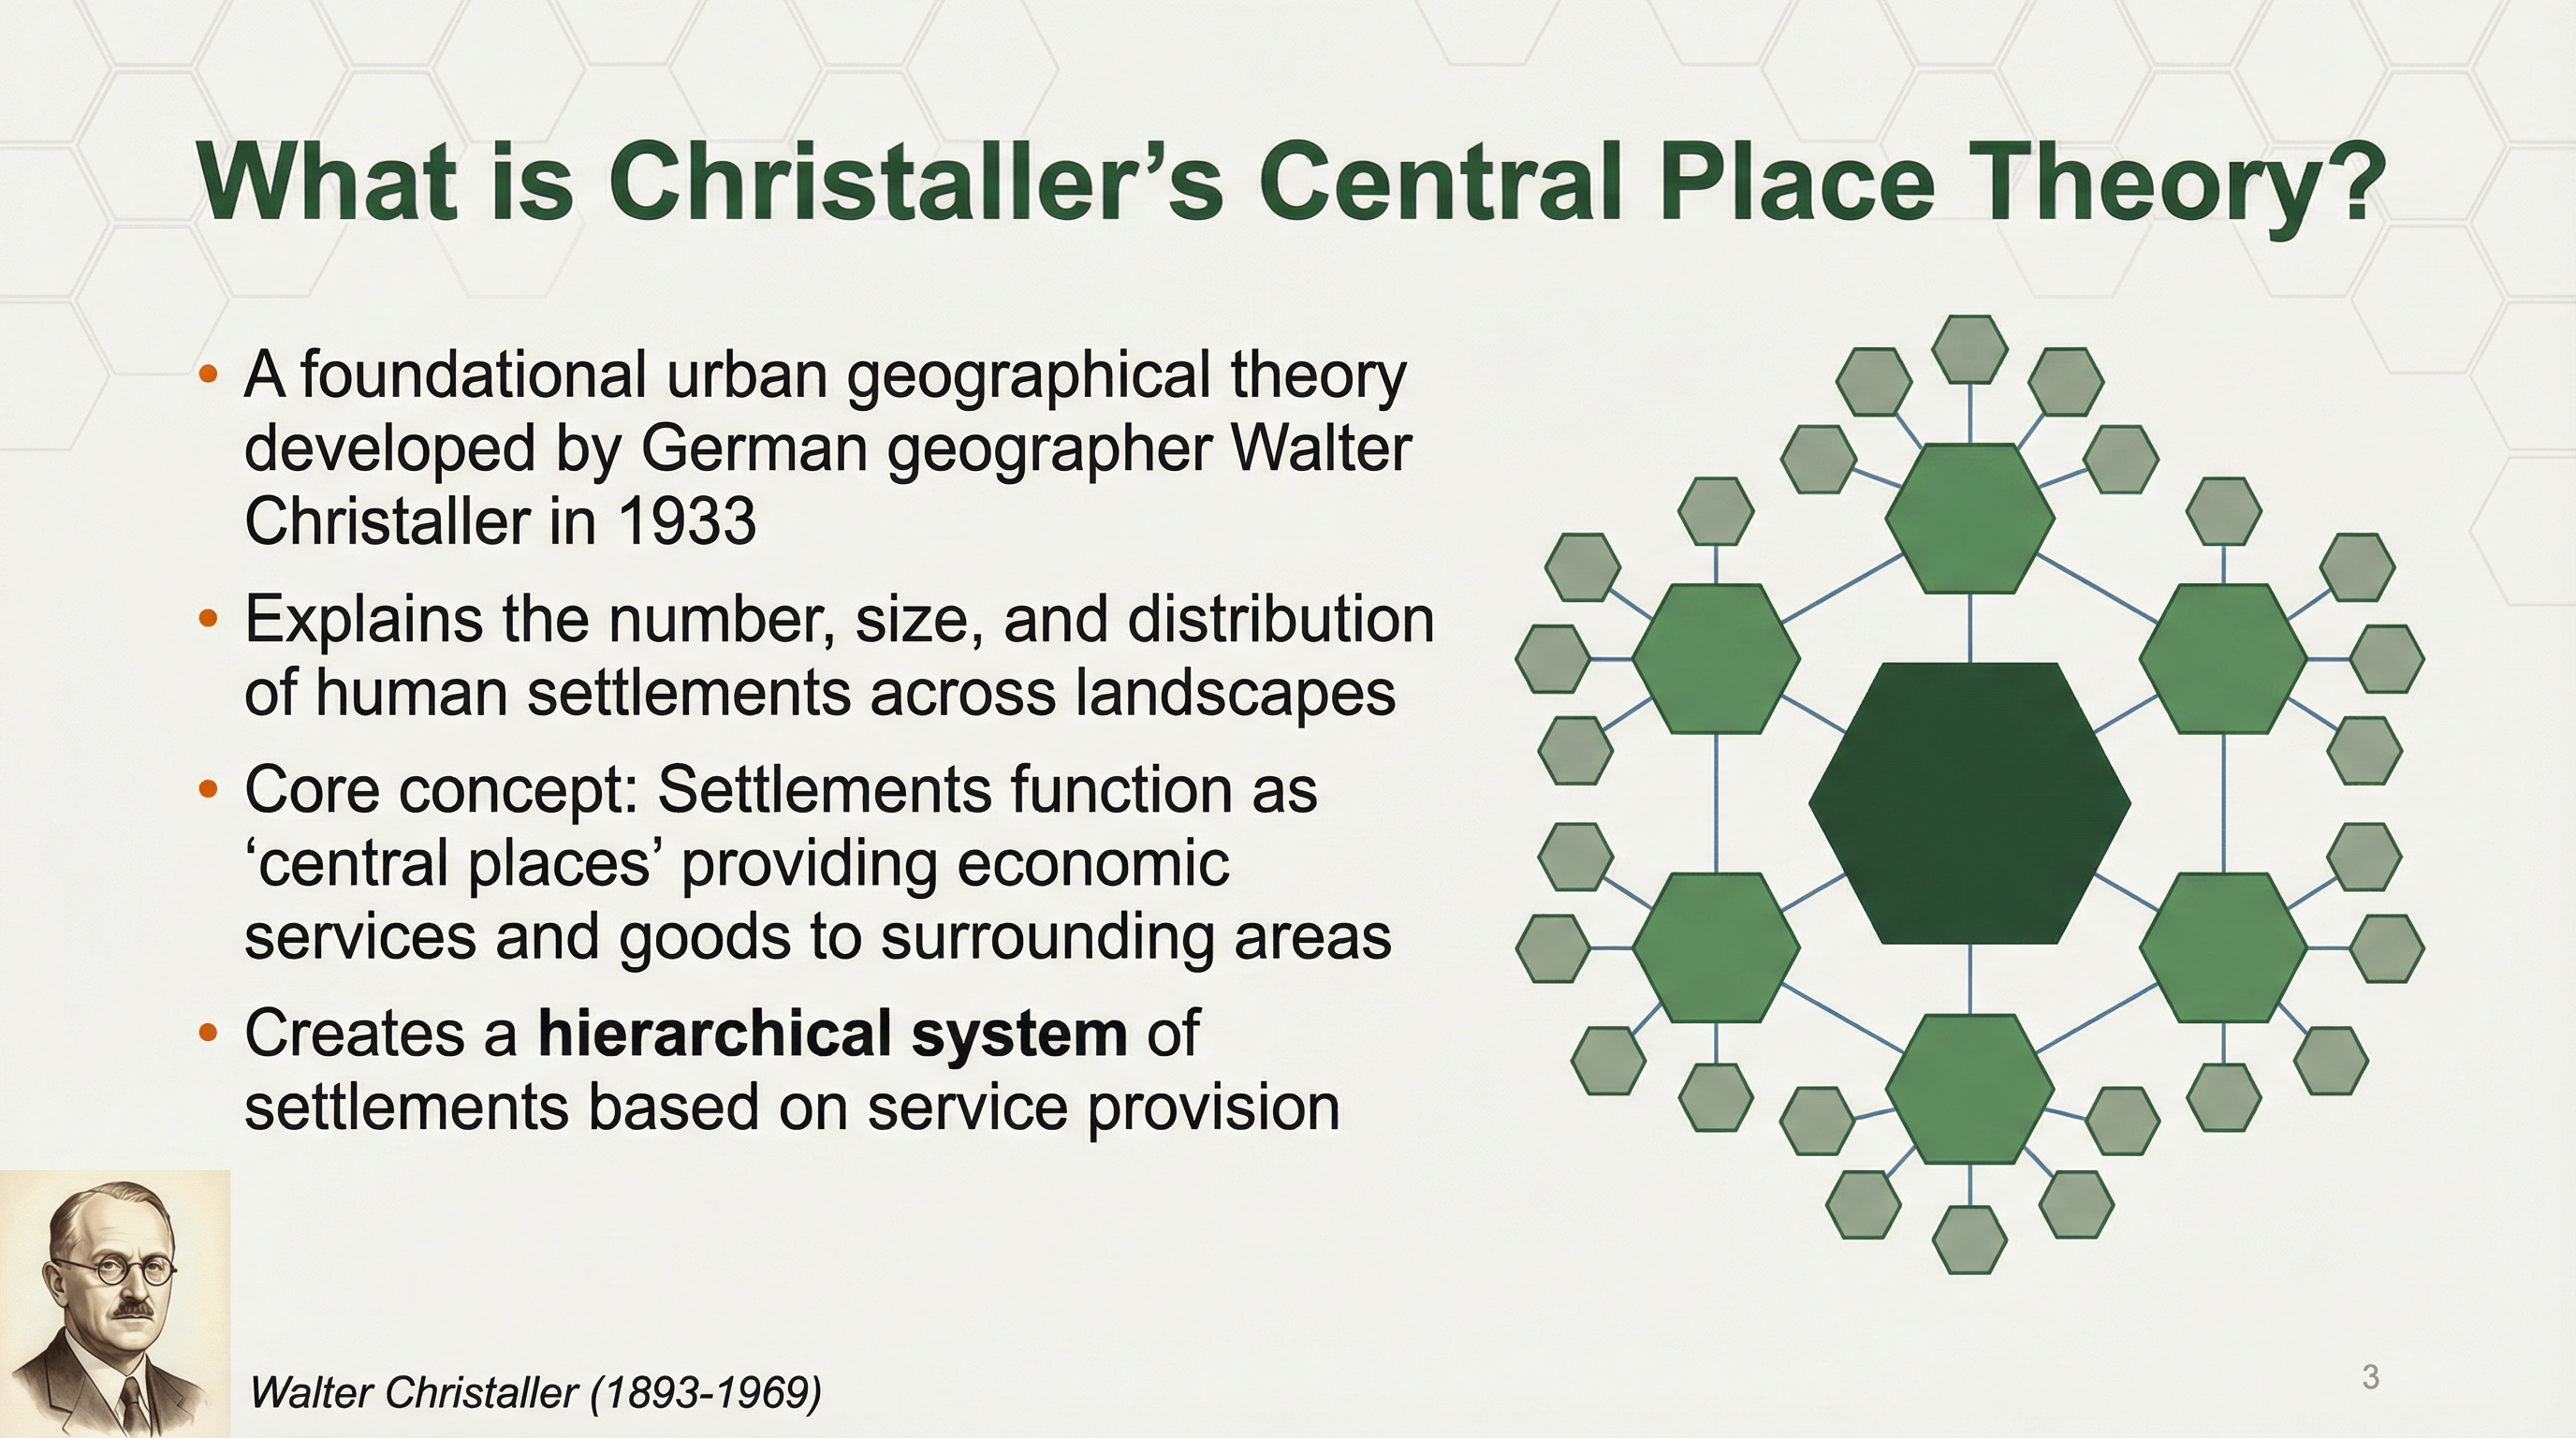
Walk through any mid-sized American city and you will notice a pattern that is more deliberate than it appears. Larger towns host specialty hospitals and shopping malls while smaller ones carry grocery stores and gas stations. Walter Christaller figured this out in the 1930s by looking at southern Germany, though the same logic shows up everywhere once you know how to spot it. The theory is straightforward but the math behind it can eat your weekend if you let it. I have built regional retail models using it for fifteen years. Here is the practical side of it, not the textbook version. The core mechanism is simple enough to sketch on a napkin. Every settlement serves a hinterland of customers. The size of that hinterland depends on two things: how expensive it is for people to reach the place, and what kind of goods or services the place offers. High order goods like heart surgery or diamond rings only attract customers from far away. Low order goods like bread and haircuts are bought locally. The theory maps these service levels onto a hexagonal hierarchy rather than circles because circles leave gaps and overlap. Hexagons tile perfectly.
W Christallers Central Place Theory Decoding The Hidden Geometry Of Urban Networks And Regional Development
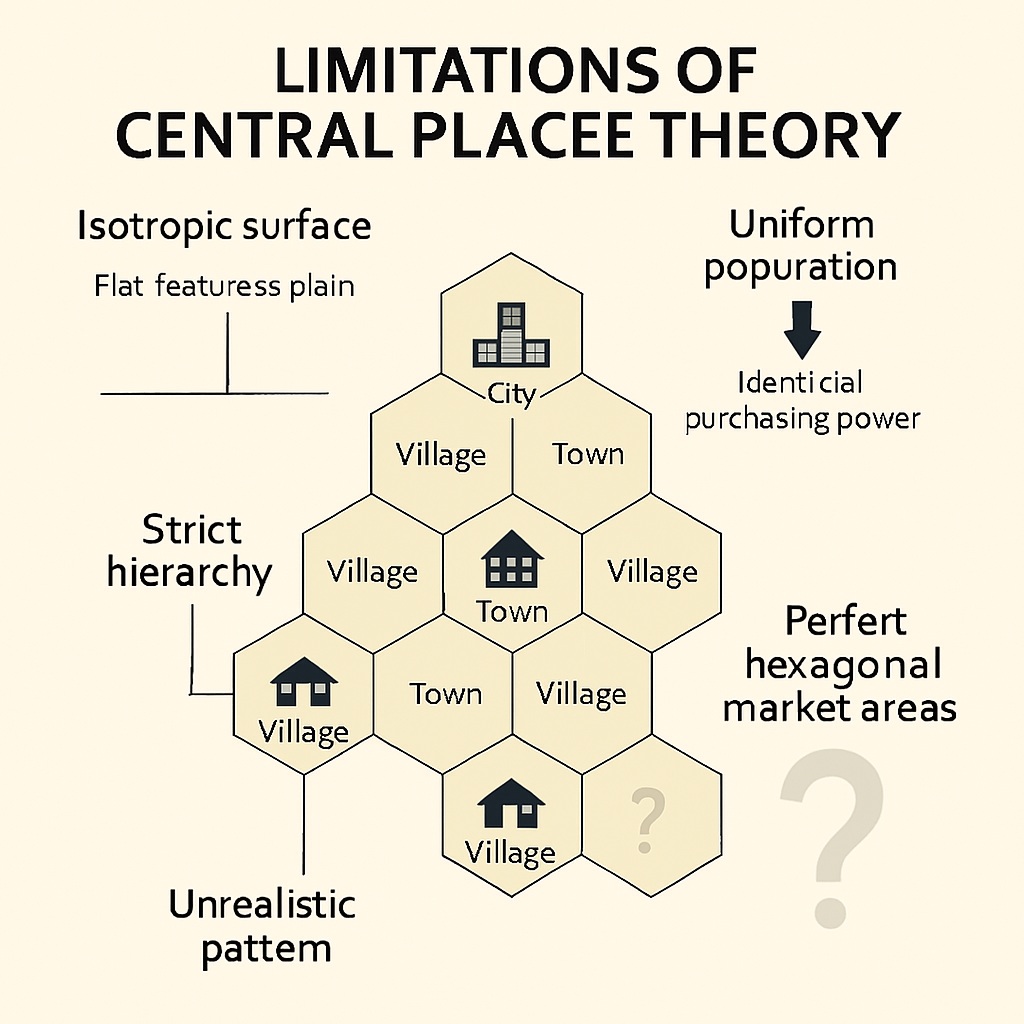
Christaller built three models based on different optimization principles. He called them K=3, K=4, and K=7 systems. Each one changes how the hexagonal tiers nest inside each other. A K=3 system routes trade areas along transportation corridors. The larger central places sit at one corner of the hexagon and the smaller ones fan out below it. A K=4 system uses marketing principles where each lower tier serves exactly half the customers of the tier above. A K=7 system relies on administrative organization so every smaller place falls entirely within the jurisdiction of one larger place. None of these patterns survive contact with reality unmodified. They are reference frames, not blueprints. When I apply this to regional planning projects, the first step is always defining your service radius data. You need drive time or distance data from population centroids to existing facilities. Without real travel times the model becomes decorative geometry. I pull raw OSMnx network data from OpenStreetMap and build isochrones for each facility type. That usually takes a solid afternoon on a decent machine if you are doing a multi-state region. Processing cuts down to maybe forty minutes once you cache the road network and script it properly. One thing textbooks rarely mention is threshold distortion. Christaller assumed uniform population distribution and identical purchasing power across the region. Real regions have river valleys, mountain ranges, and zoning barriers that shift demand dramatically. I worked on a project in Appalachia where the theory predicted a mid-tier healthcare hub should exist at a specific intersection. The terrain made that location unreachable for sixty percent of the projected service population within a reasonable drive time. We moved the proposed site three miles downhill using cost-distance analysis instead of straight-line polygons, and the facility viability shifted from unlikely to probable. Terrain adjustment is non-negotiable in mountainous regions.
The hexagonal nesting can also mislead you when you deal with edge effects. Cities near coastlines or state borders break the symmetry because demand spills outside the study area. I had a case where a proposed K=3 arrangement kept failing because the model counted customers who physically could not cross a county line due to jurisdictional barriers. The fix was trimming the demand layer at political boundaries and inflating the interior cells to compensate for lost peripheral demand. It is not perfect but it stops the model from hallucinating facilities in impossible locations. Another common pitfall is treating all retail categories as interchangeable. Specialty retail follows the hierarchy cleanly. Essential services like schools and fire stations do not. I learned this the hard way when a regional economic development office asked me to model grocery store placement using the same parameters as hospital placement. The results were absurd because grocery shopping behavior has a completely different threshold and range than emergency care. Separating service categories by purchase frequency and category specificity before running any spatial analysis saves you from wasting days on garbage output. For practical implementation, the Python libraries you actually need are geopandas for the vector data, scipy for the hexagonal grid generation, and osmnx for the road network extraction. If you want a faster setup there is a ready script I use that builds a K=3 hex tessellation from a shapefile boundary and assigns population weights from Census block centroids. I keep it on my personal GitHub under apatridge/regional_hierarchy_tools. The README has the pip install line and a Jupyter notebook with sample data. It takes a standard shapefile and outputs a GeoPackage with nested hex tiers and demand overlays. Nothing fancy, just functional.
Get the Full Details

If you prefer R instead of Python, the spatstat and sf packages handle hexagonal tessellation without too much pain. A few lines of code get you a regular grid that you can overlay on your service areas. The tradeoff is slower performance on large datasets. Python scales better when you are working with entire states rather than single counties. The biggest limitation anyone needs to understand is that Central Place Theory assumes rational consumer behavior. People do not always choose the nearest provider. Brand loyalty, traffic congestion, and habit all matter. I had a supermarket chain ignore my model recommendations for a new store location because they wanted to be near a competitor for visibility, not near underserved demand. The model was right about demand gaps. It could not account for competitive positioning strategy. In those cases you need to layer in gravity model adjustments or agent-based simulation to get closer to reality. If you are modeling large metropolitan regions with dense transit networks, the theory loses resolution quickly. Suburban sprawl and multimodal commuting patterns create demand surfaces that hexagonal grids cannot capture at useful scale. For those situations a kernel density estimation approach combined with revealed preference data works better. Central Place Theory is most valuable for rural and suburban regional planning where service hierarchies are clearer and travel distances dominate location decisions.
The original German publications are in archaic geographic prose that will drain your motivation if you read them cover to cover. Dacey and Parker translated the key concepts into English nicely. The 1966 Geographical Analysis paper by Haggett covers the mathematical backbone without unnecessary jargon. For applied work, the 1970s literature on spatial economics by authors like Schmitz gives you the formal optimization derivations if you need them. I stop here because I do not want to pad this out with filler. The theory is a starting framework, not a complete solution. Use it to structure your thinking about regional service hierarchies, then layer in real travel data, terrain costs, and actual consumer behavior to get results you can put in front of a planning commission.