What Actually Happens When You Deploy Policy Tech on a Medical Campus
I ran into this system about three years ago when we were doing a compliance audit for our IRB and research governance divisions. What I saw was less of a magical transformation and more of a painful but necessary modernization. Let me walk through how it actually works in practice. At its core, this is a policy management platform combined with compliance monitoring and AI governance tools. It pulls together disparate policy documents, tracks their revision history, flags outdated language against current regulations, and runs algorithmic assessments on any AI or automated decision-making systems deployed across the institution. The idea is to stop relying on people manually checking whether policy X still aligns with regulation Y. Instead, the system maps those relationships and surfaces conflicts automatically. The compliance engine works by ingesting federal, state, and institutional regulations—HIPAA, Clery, FERPA, state Medicaid rules, internal board policies—and creating a traceability graph. When a new regulation drops, the system flags every policy section that might be affected. That's the part that actually saves time. A full manual cross-reference review of our research compliance policies used to take two to three people about four weeks. With the mapping in place, the initial pass takes a couple of days, and you spend the rest of the time verifying the flags rather than hunting for them.
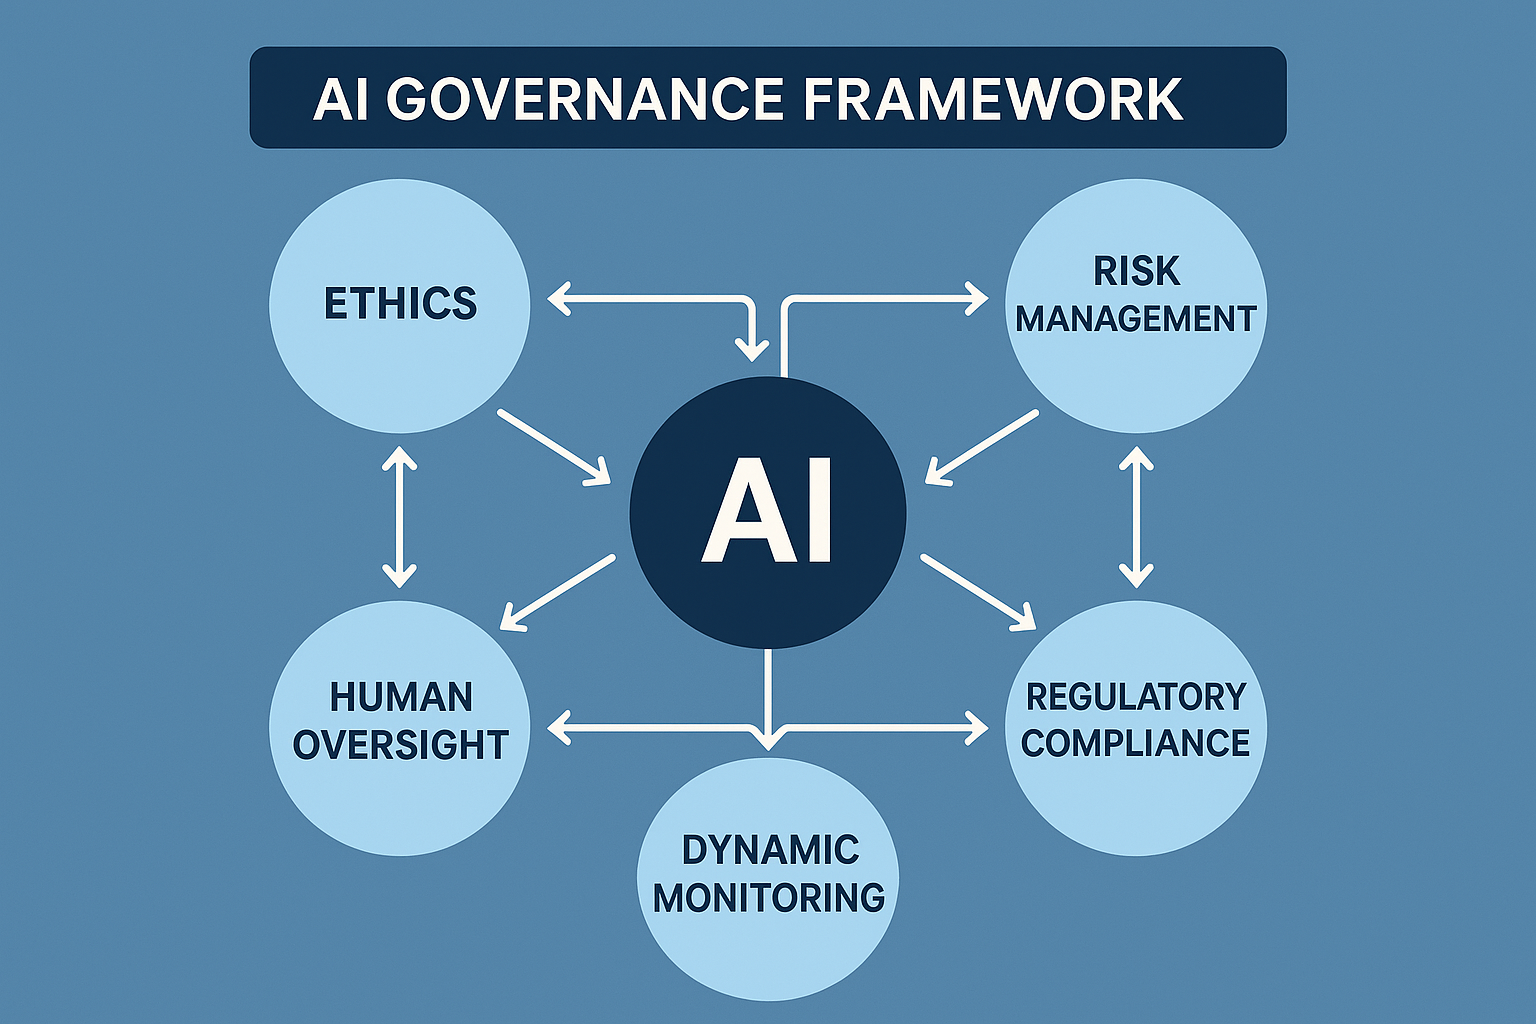
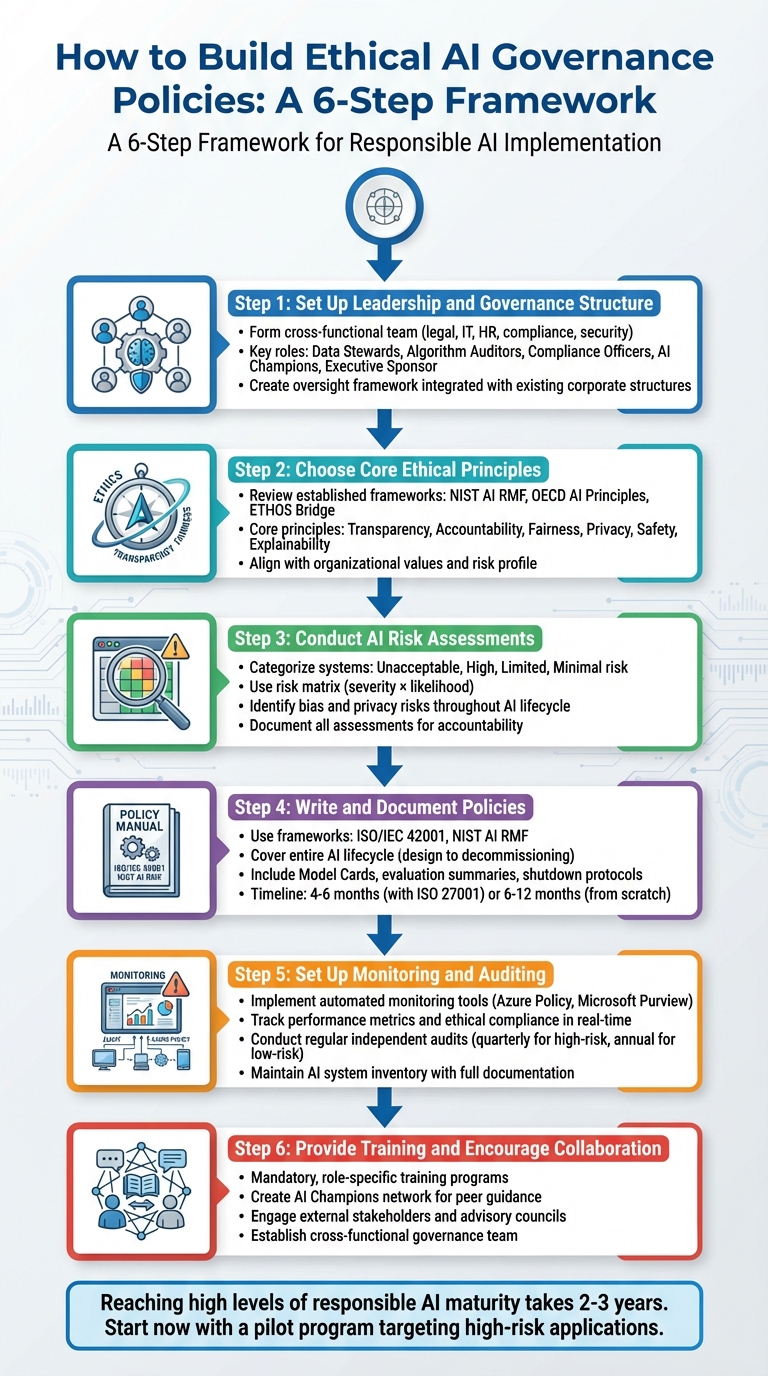
The ethical AI framework component is where things get more complicated. Any department running an automated system—prioritization algorithms, fraud detection models, admission or referral triage tools—needs to register that system in the framework. The framework then requires an impact assessment covering data inputs, potential bias vectors, and human oversight mechanisms. It's not just a form you fill out. The system checks whether the inputs include protected characteristics, whether the model has been tested across demographic segments, and whether there's a documented appeal process for adverse automated decisions. Here's where I hit a wall in practice. About a year after rollout, the oncology research group flagged a referral prioritization model that used clinical risk scores. The model looked clean on paper. No protected class variables were direct inputs. But when I dug into the training data distribution, the risk scores correlated heavily with insurance type and zip code, which in our area correlated with race. The framework caught this eventually, but not on the initial assessment. The false negative came from relying on a static impact questionnaire rather than continuous monitoring of model outputs against population demographics. My workaround was to build a supplemental dashboard that pulled periodic stratified performance data from any registered model and compared outcome rates across demographic groups. If the variance exceeded a threshold we set—0.05 standard deviations on key outcome measures—the system escalated it to the AI oversight committee for review. This caught issues the initial assessment missed. It also created more work. We had to negotiate with department heads who didn't want to share their model output data, and we had to establish what the escalation threshold should actually be without grinding operations to a halt every time a minor fluctuation showed up.
The platform does have real limitations. One is data quality at the source. If your policy repository contains outdated or incorrectly tagged documents, the traceability graph propagates those errors everywhere. We found about 30 percent of our historical policy documents had incorrect regulatory mappings from a previous manual classification effort. Fixing that took a dedicated cleanup sprint that consumed six weeks of analyst time across two departments before the system started producing reliable alerts. Another limitation is adoption fatigue. The framework requires ongoing registration and reassessment for any AI system. Departments that adopted early and understood the workflow handled it fine. Others treated it as a checkbox exercise and registered incomplete or misleading information. The system can't distinguish between a genuinely compliant submission and a carefully worded one designed to pass the automated checks. You still need domain experts reviewing the flagged items, which means the time savings from automation get eaten by the review workload if your staffing doesn't scale with the volume of registrations. The governance structure around this matters more than the tool itself. We established a cross-functional committee with representation from compliance, legal, IT security, and individual academic departments. The committee meets monthly to review escalated findings, set threshold parameters for the monitoring dashboard, and approve exemptions for edge-case systems. Without that structure, the platform becomes either a bottleneck or a rubber stamp depending on who has the authority to override its flags. That power dynamic is something you figure out the hard way.
Get the Full Details
If you're evaluating whether to deploy something like this, start with a scoped pilot. Pick one compliance domain—research compliance or student conduct policy enforcement, for example—and map the relevant regulations against your existing policy documents. You'll learn quickly whether your document management practices are mature enough to support the system. If your policies live in shared drives with inconsistent naming conventions and no version control, you need to fix that infrastructure first or the platform will produce garbage results faster than a manual process would. The ethical AI governance piece requires a different kind of readiness. You need data engineering capacity to pull the stratified performance data, statistical literacy to interpret the variance metrics, and the organizational authority to compel departments to share model outputs. None of that is trivial in an academic medical center where departments operate with significant autonomy and shared data is often treated as a competitive asset rather than an institutional responsibility. We've been running this framework for roughly three years now. The compliance tracking portion delivers on its promise. The AI ethics oversight portion is still evolving and still generates more questions than answers. That's honest to report. The system doesn't solve governance problems. It makes them visible earlier and forces you to address them with evidence instead of intuition. In my experience, that's actually worse in some ways because you can't ignore the gaps anymore once you can see them clearly. But it's also the only way to build something that holds up under scrutiny from accreditors, auditors, and increasingly, from the departments themselves who now expect these systems to catch their own blind spots.