Understanding Voiceless and Boisterous Voice Qualities in Speech Analysis
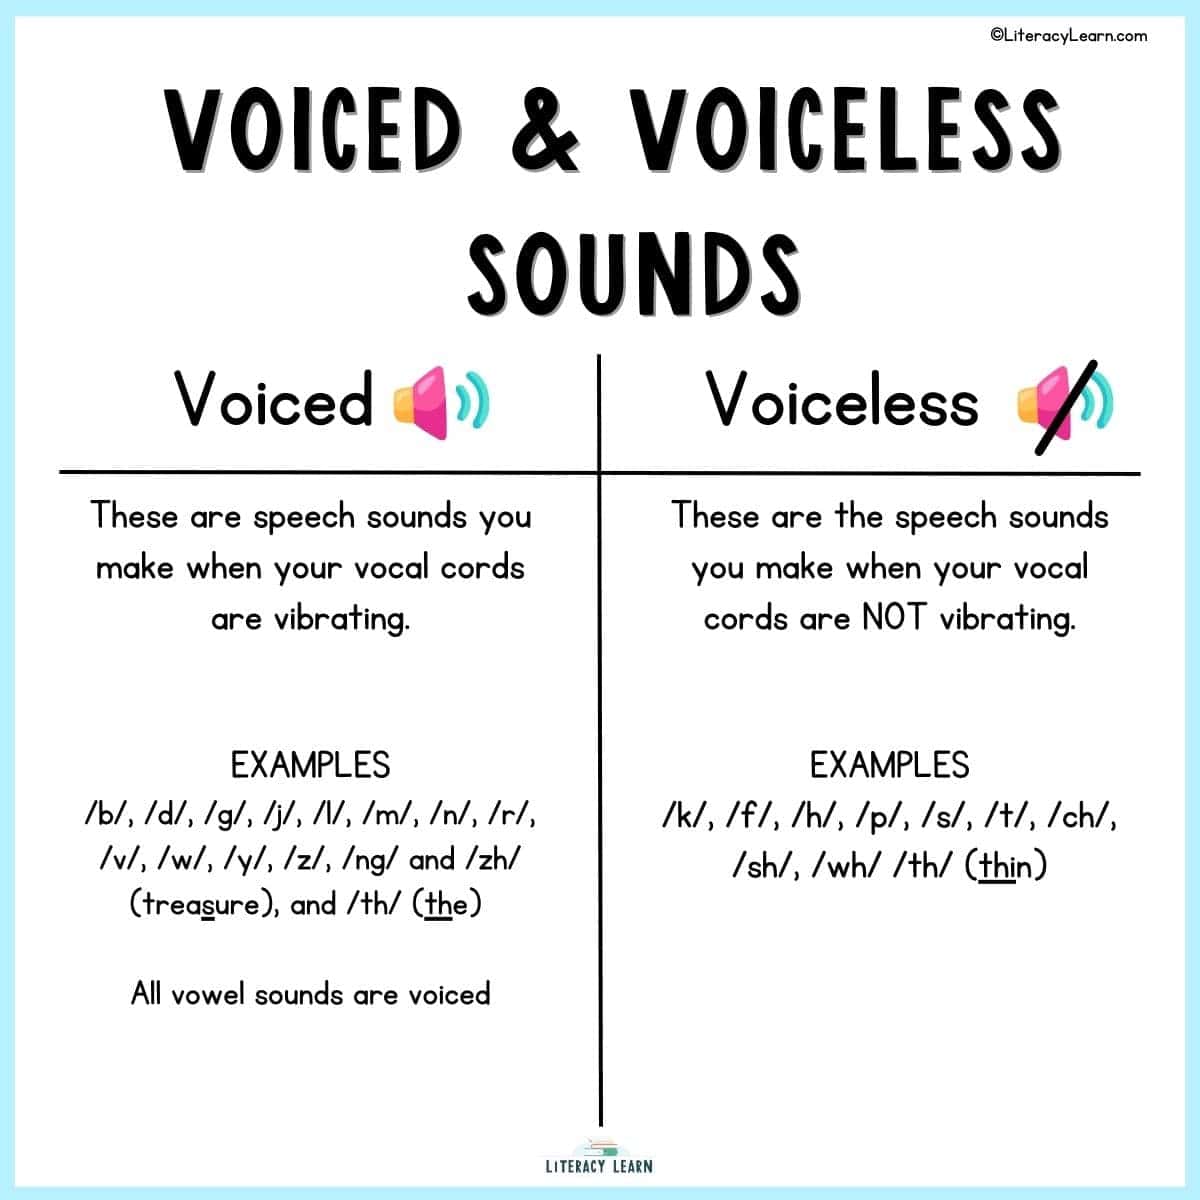
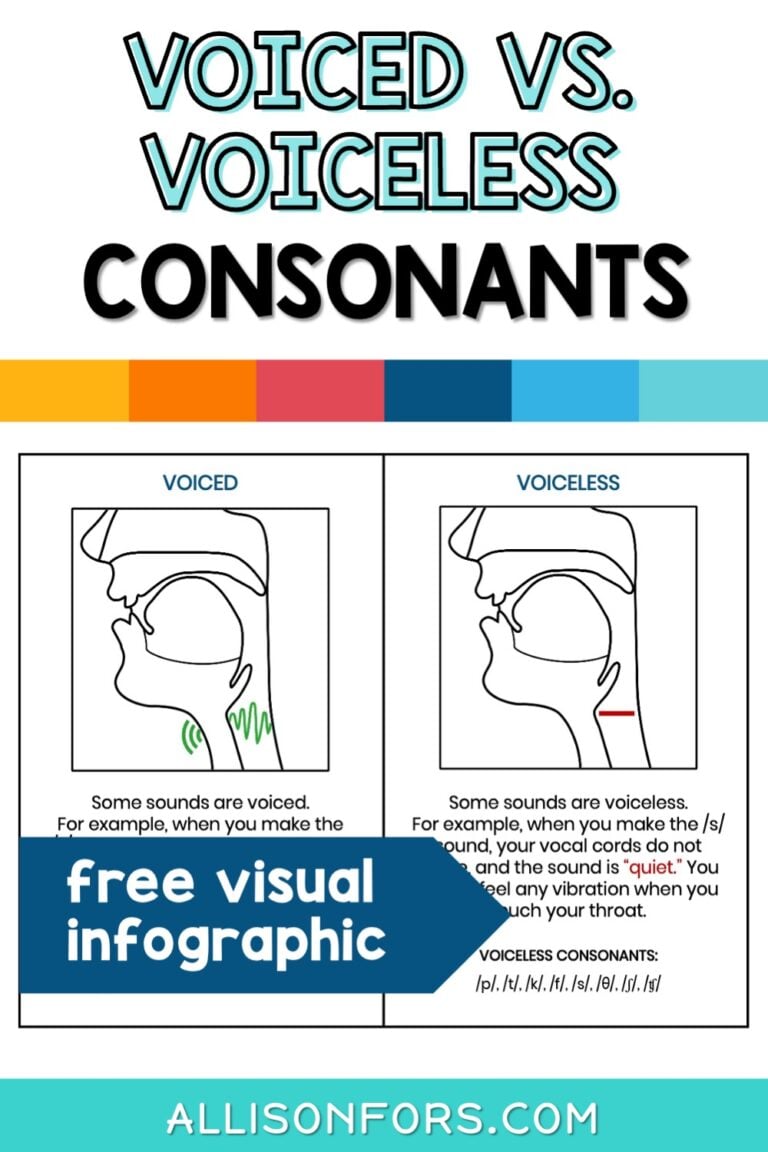
When you are recording voiceovers, working on dubbing, or analyzing speech patterns for any reason, the distinction between voiceless and boisterous delivery comes up more often than most people expect. I ran into this repeatedly while cleaning up production audio for a series of documentary narrations a few years back. The difference between the two isn't just about volume. It is about breath control, vocal fold engagement, and how much acoustic energy sits above and below the fundamental frequency. Voiceless speech refers to sounds produced without vocal fold vibration. Think of consonants like p, t, k, f, s, sh. These are phonetically defined, and they carry energy primarily in the higher frequency range, usually above 2000 Hz. Boisterous speech is something different entirely. It describes a quality of delivery that is loud, forceful, and often emotionally charged. The vocal folds are engaged, sometimes pressed together too tightly, which creates a noisy but pitched sound. What separates a boisterous voice from normal loud speech is the amount of irregular noise and the way the formants get pushed around.
Voiceless Vs Boisterous Understanding The Key Differences
The key differences show up immediately when you look at a waveform or a spectrogram. A voiceless segment like an sibilant will appear as concentrated high-frequency noise with no clear harmonic structure. A boisterous vocal passage will show strong harmonics, but they will be messy. You will see excessive amplitude variation, pitch drift, and a lot of low-frequency rumble from subglottal pressure. I learned this the hard way on a project where the narrator had recorded several takes using the same microphone setup. The engineer asked me to "clean up the boisterous parts," which in practice meant the narrator was getting more animated as the sessions went on. The early takes were fine. By take six, the delivery had become strained, the plosives were distorted, and there was audible breath noise mixed with the vocal. My workaround was to isolate the clean mid-range, use a multiband compressor to tame the lower frequency build-up, and blend in a quieter, closer-mic'd alternate take for the words that had gotten too forceful. It took about three hours for a ten-minute piece, which is longer than I would like, but it preserved the emotional intensity without the distortion. On the voiceless side, the challenge is different. If you are transcribing or doing phonetic analysis, you need to separate true voiceless consonants from fricatives that have gotten noisy because of poor mic technique or room resonance. A common pitfall is misidentifying a breathy voiceless sound as a regular voiced segment. I once spent an afternoon troubleshooting what I thought was a faulty preamp, only to realize the speaker was consistently producing a weak aspiration that my spectral analysis tools were reading as low-frequency voicing. Switching to a higher sample rate and applying a narrow band-pass filter around the formant region fixed the classification error instantly.
For anyone trying to train their own voice or analyze speech, here is the practical approach I use. Record at least two takes with a gap of thirty seconds between them. This gives your vocal folds a chance to recover and resets your breath pattern. Use a consistent mic distance, ideally six to eight inches, and keep the angle slightly off-axis if you are dealing with plosives. When reviewing, don't just listen. Look at the spectrogram. Voiceless segments show up as diffuse noise without horizontal lines. Boisterous segments will show strong, dense harmonic stacks that sometimes exceed the dynamic range of your recording system. There is a counter-intuitive point that people often miss. Being louder does not automatically make a voice boisterous. You can produce a very loud, controlled speech signal that is technically clean. Boisterousness is about the quality of the excess energy, not the decibel level. A whisper can be analyzed for voiceless components and will look completely different from a shouted sentence, even if the shouted sentence has less overall amplitude in certain frequency bands. If you are working with automated tools like speech-to-text or voice activity detection, be aware that both extremes cause problems. Voiceless sounds confuse many ASR systems because they lack the periodic signal these models are trained on. Boisterous delivery causes pitch-tracking failures and can trigger false positives in voice activity detectors. The workaround is usually to preprocess the audio with a mild de-esser and a gentle compression pass before feeding it into the tool, or to adjust the tool's sensitivity thresholds manually rather than using defaults.
Get the Full Details
I also want to note where this kind of analysis falls short. If you are working with heavily compressed audio, music with dense instrumentation, or recordings made in untreated rooms, separating voiceless consonants from background noise becomes unreliable. The signal-to-noise ratio simply drops below the threshold where spectral analysis is useful. In those cases, switching to a different methodology, like manual transcription with waveform inspection, or using a dedicated noise reduction pipeline with adaptive filtering, is the only realistic option. There is no quick fix for bad source material. The practical takeaway is that voiceless and boisterous are not just opposites on a volume scale. They represent two fundamentally different acoustic states. Understanding how to identify each one, what causes the problems associated with each, and how to handle them in a real workflow is what separates someone who just listens to audio from someone who actually analyzes it. The methods described above are what I rely on, and they have held up across a wide range of project types and budget constraints.