Understanding VMware IU Health in Practice
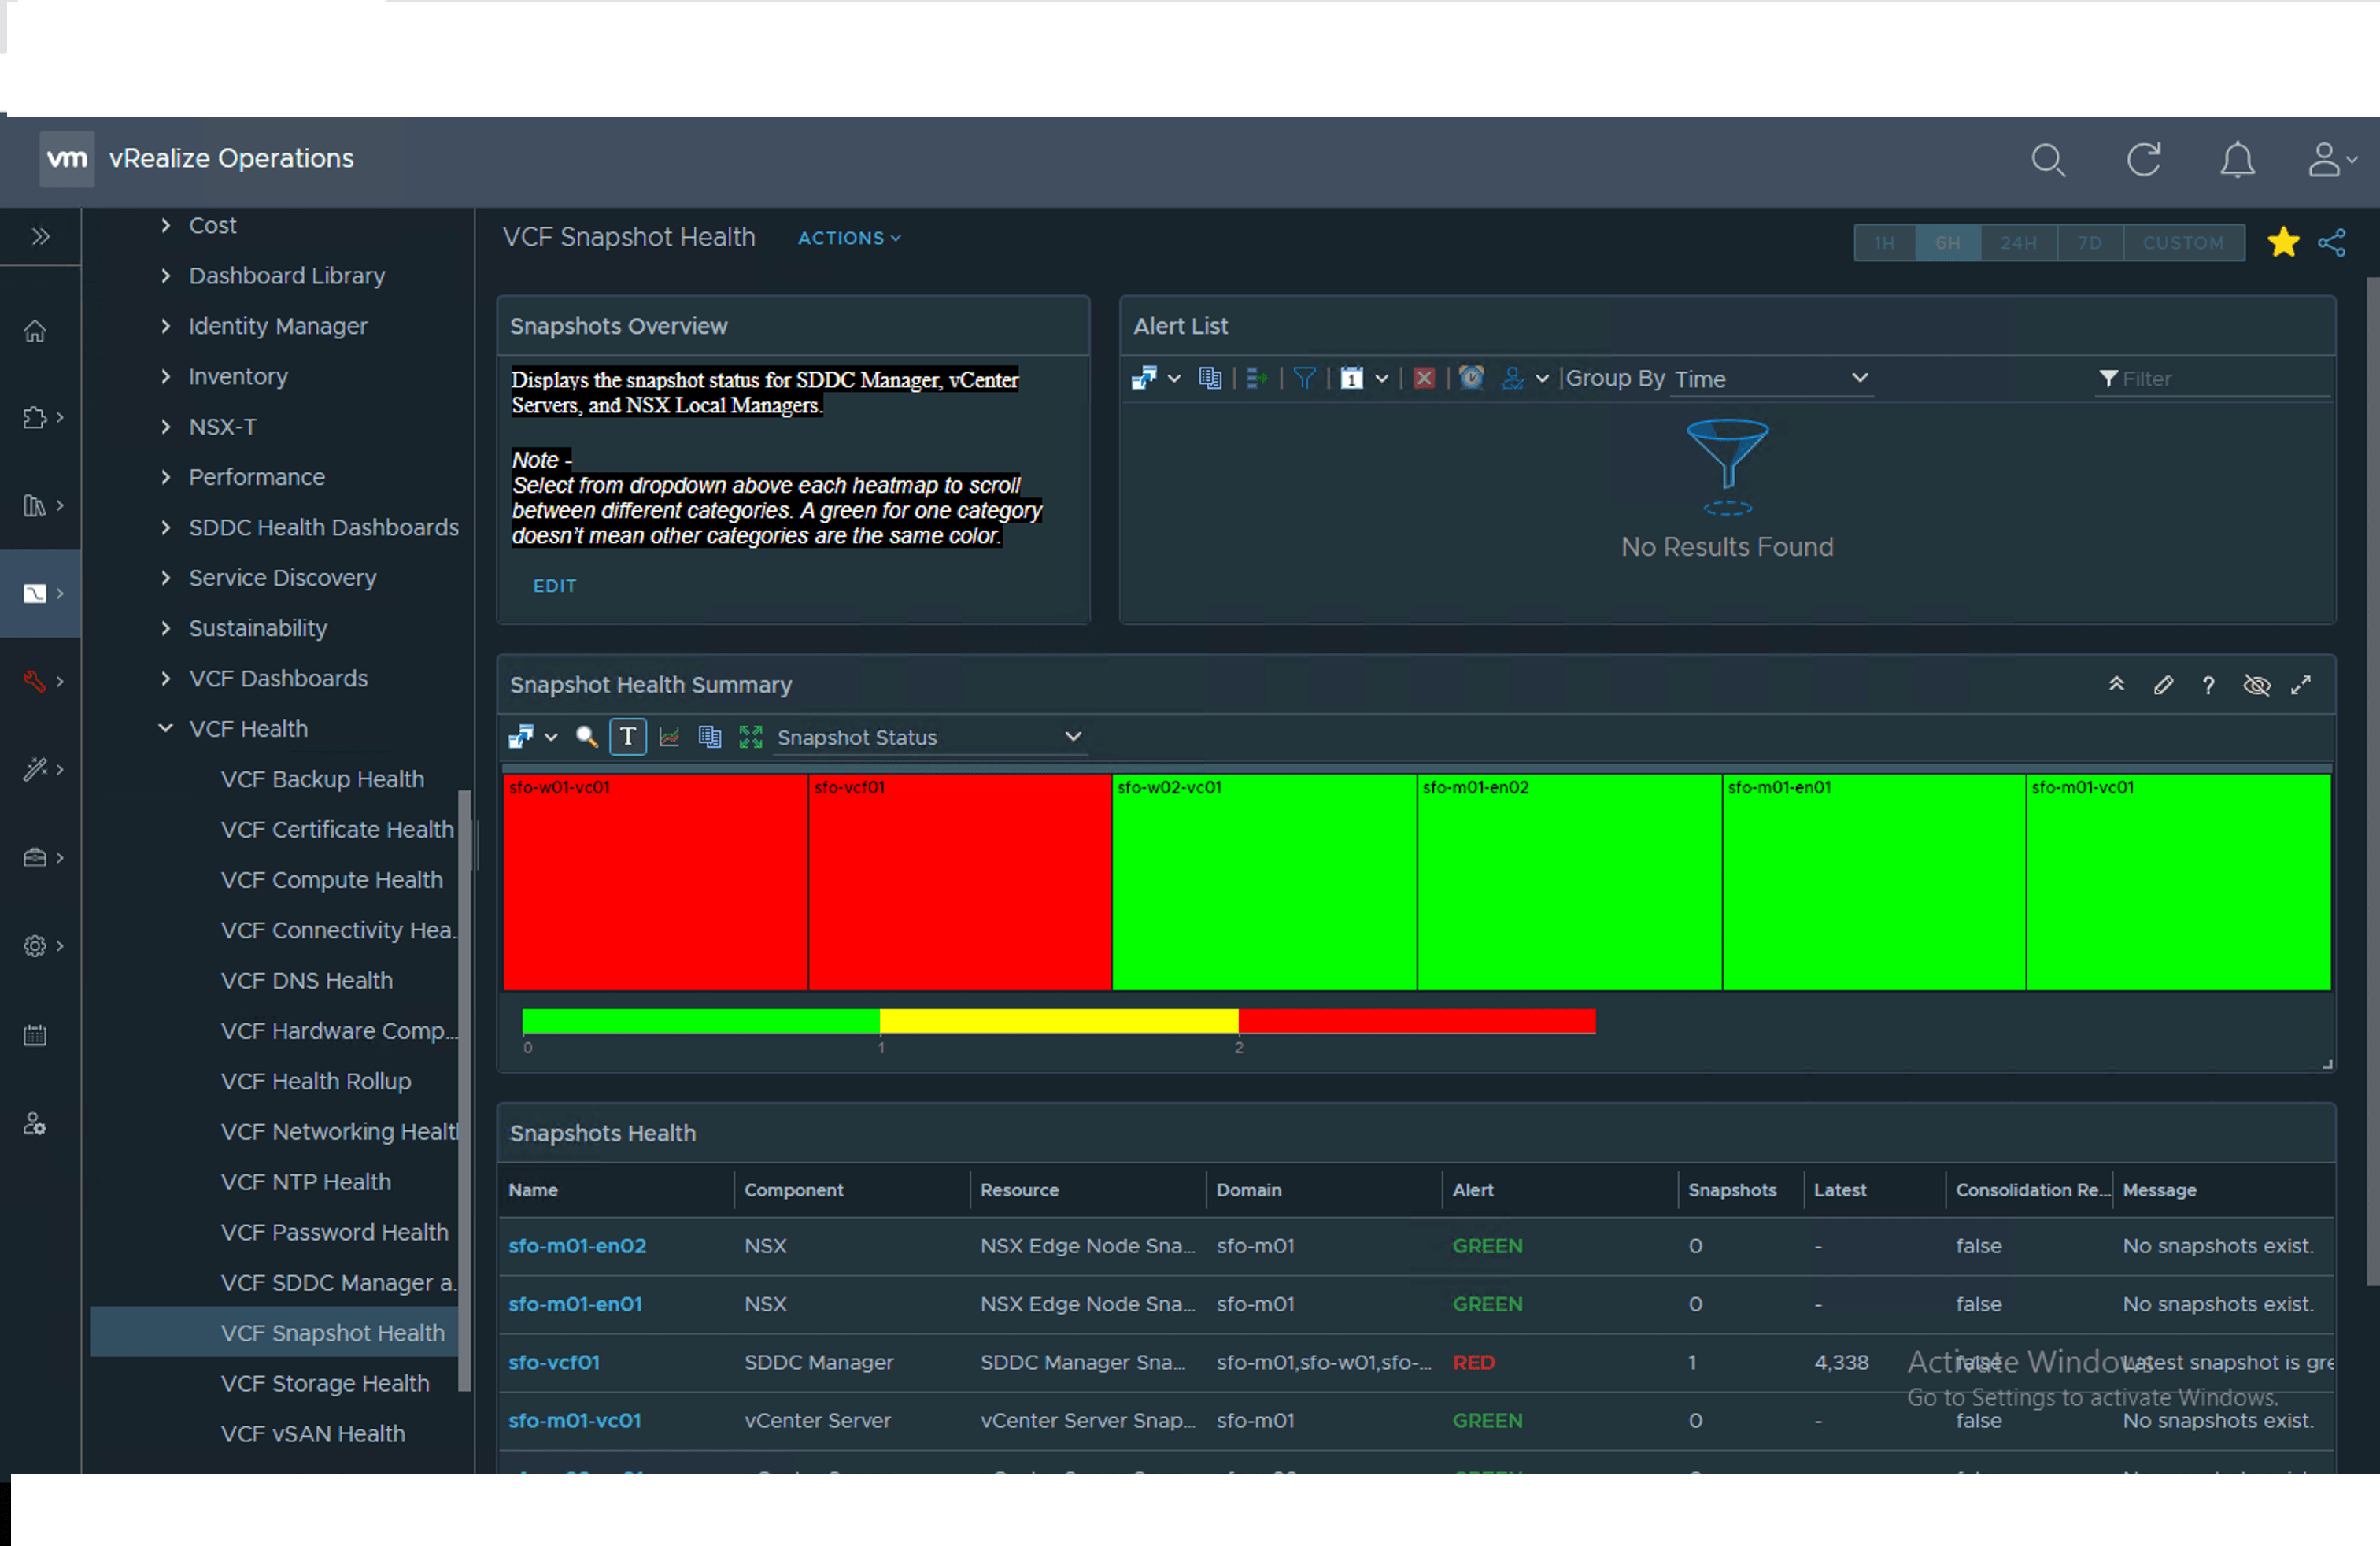
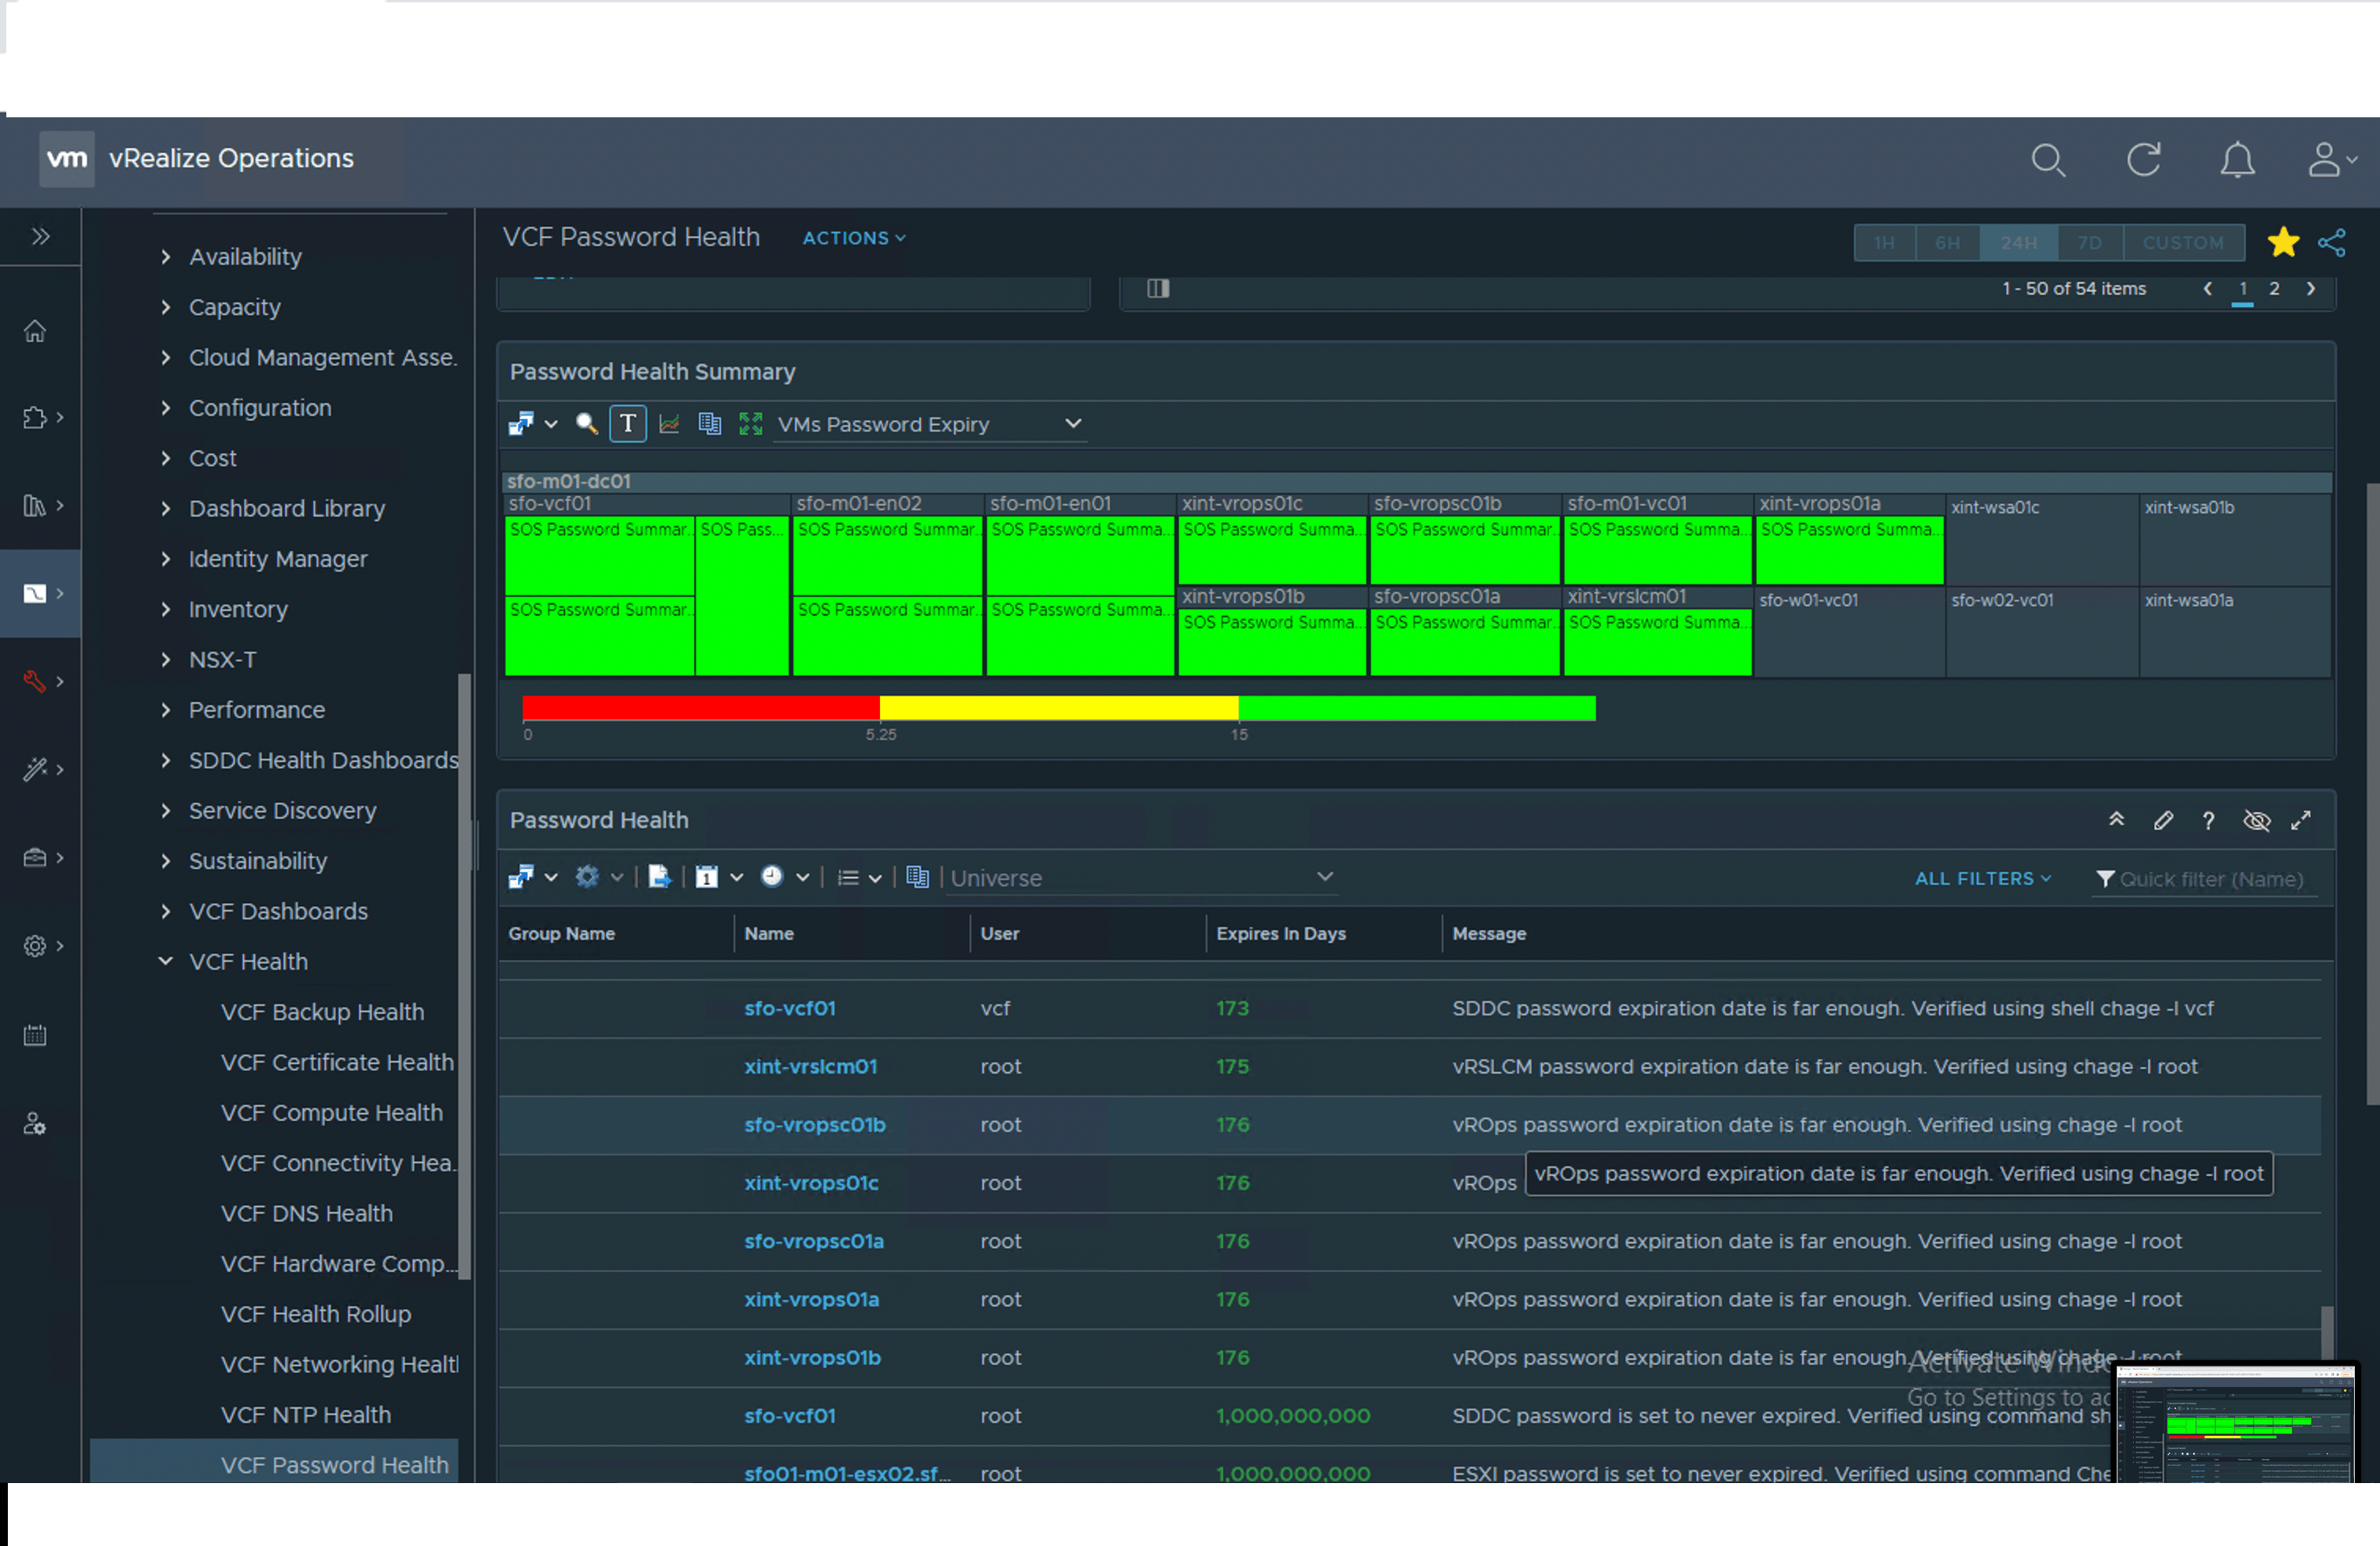
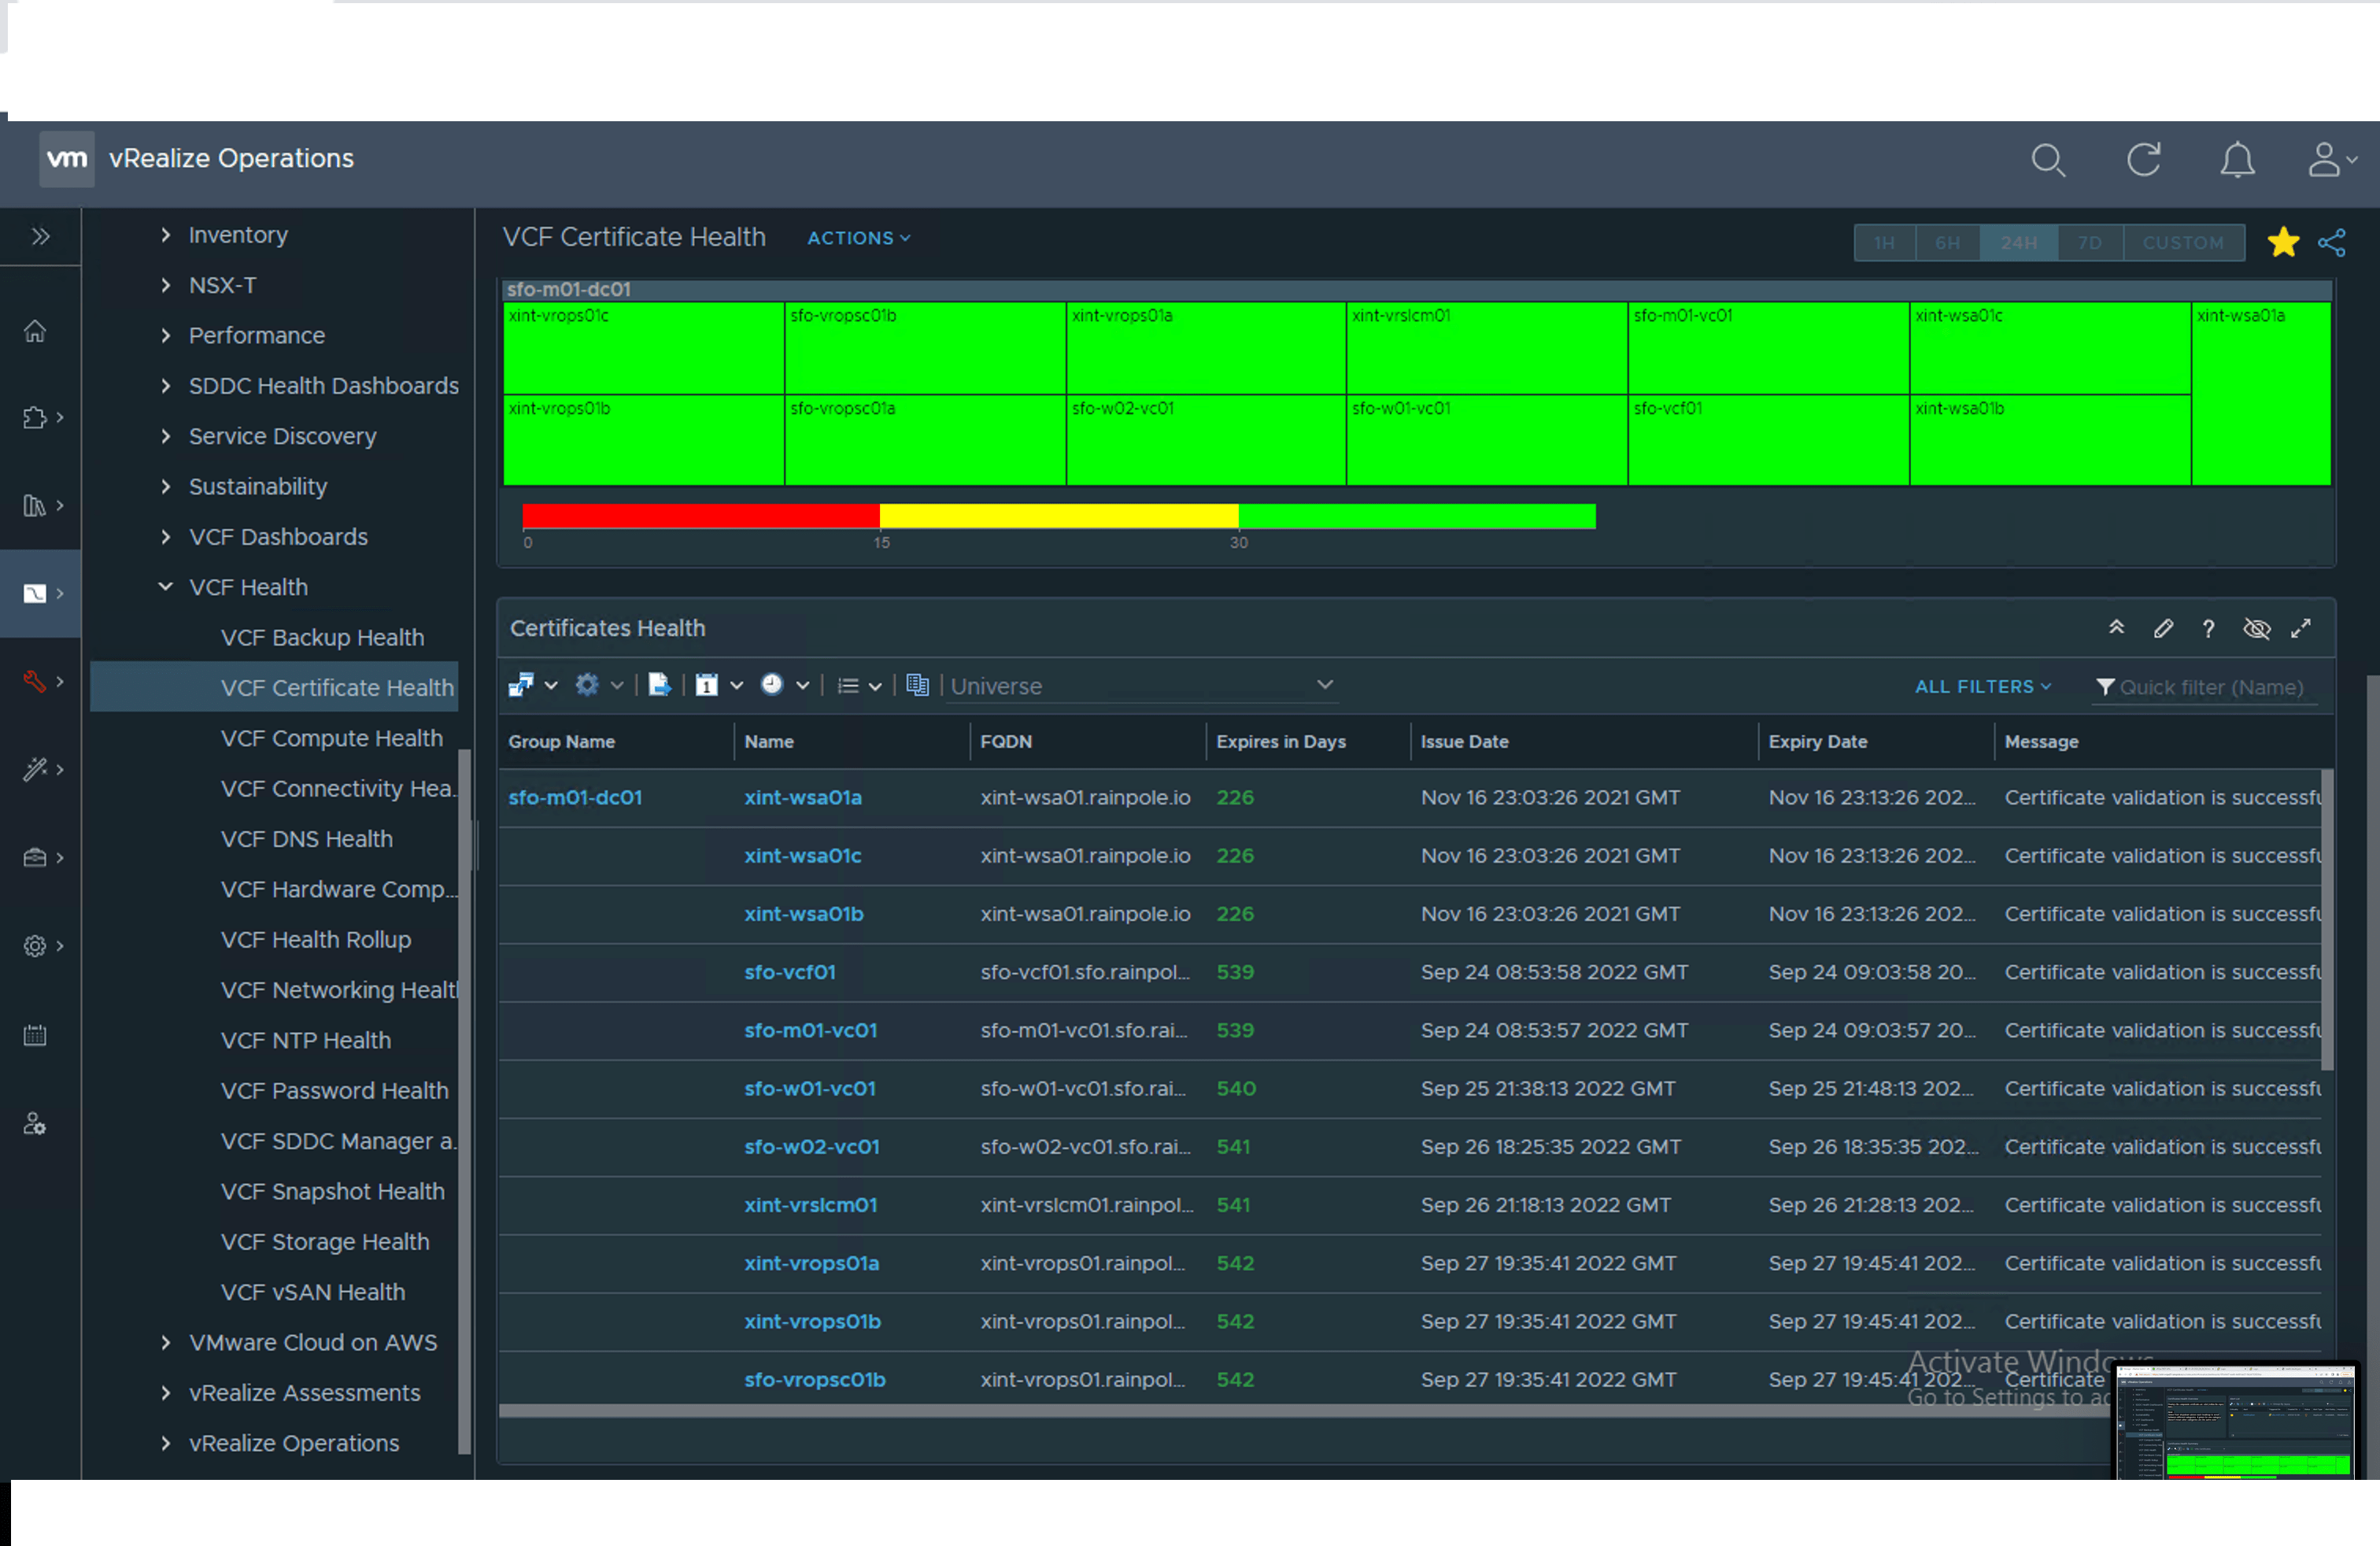
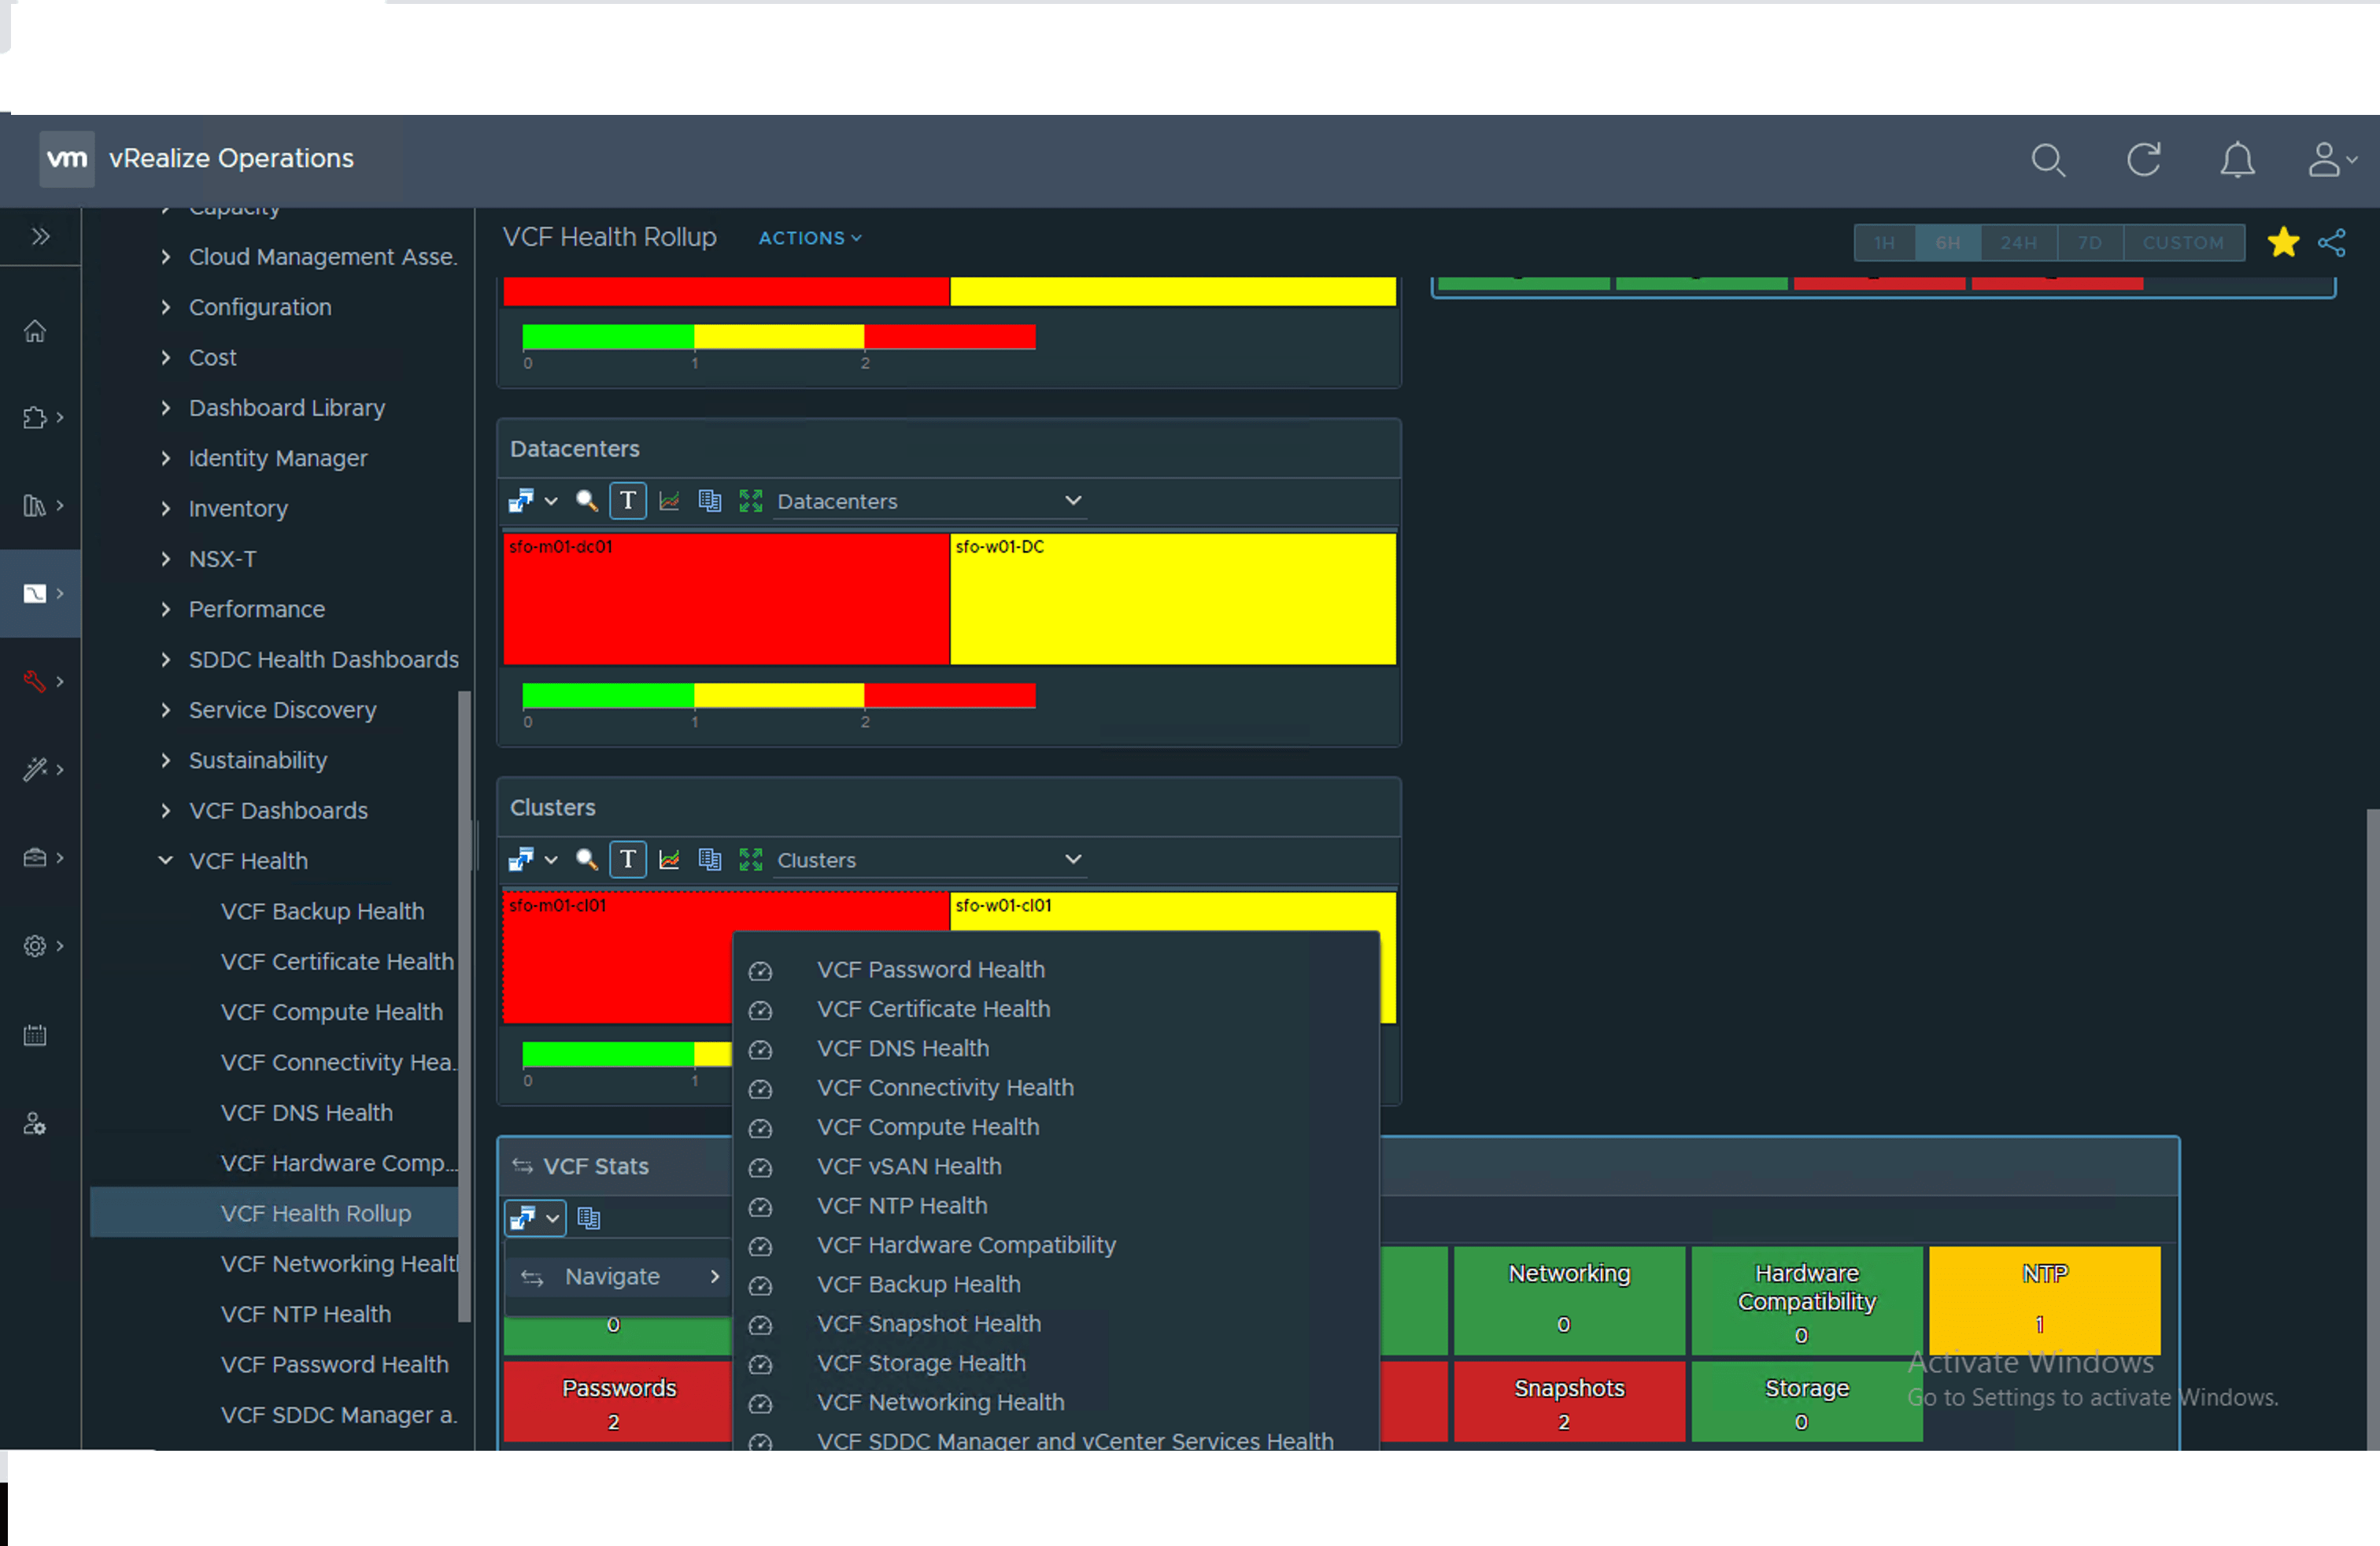
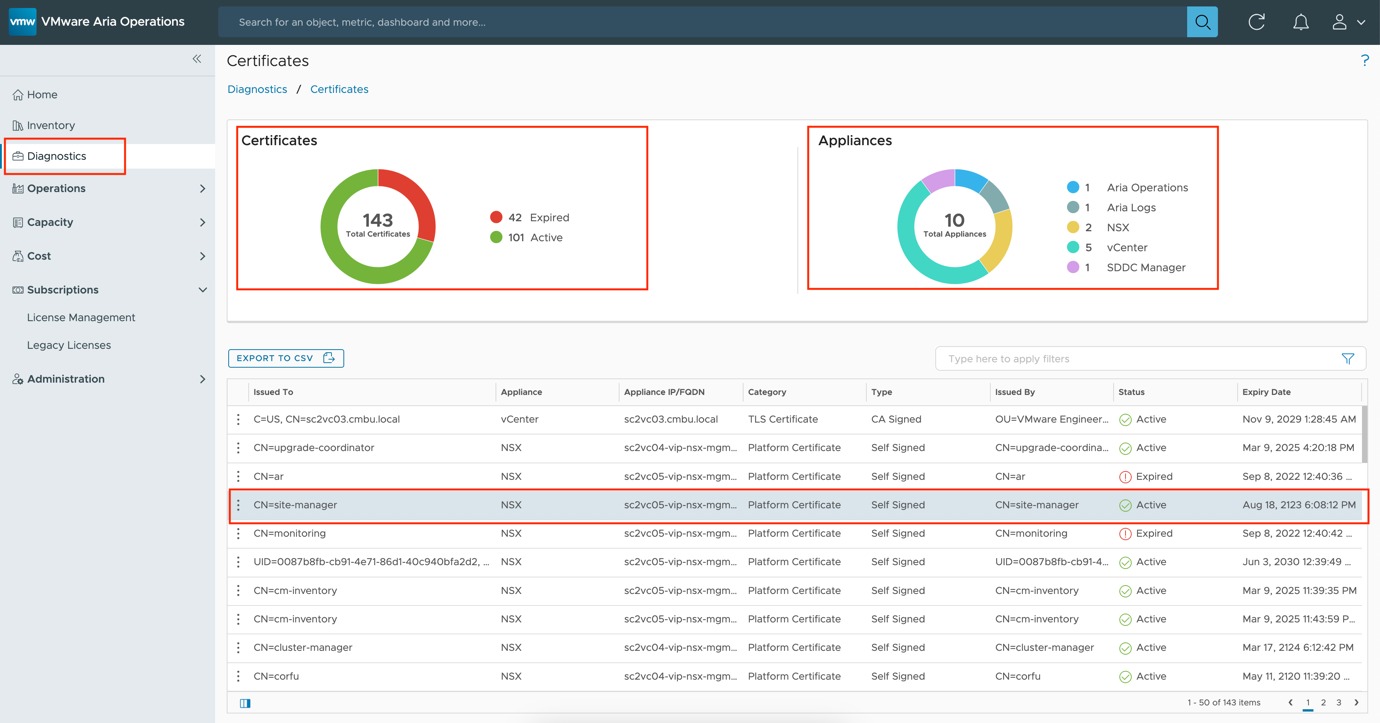
VMware IU Health is the centralized health monitoring layer that comes with vSphere and the broader VMware stack. It gives you a single pane of view across hosts, clusters, datastores, and virtual machines rather than having to chase down individual component statuses through separate interfaces. The actual architecture pulls telemetry from multiple sources, correlates it, and presents actionable health scores instead of raw metrics that mean nothing without context. What makes this different from the old approach is the correlation engine. Before unified health management, you had vSphere Health Status showing red or yellow icons that required deep investigation. Now the system aggregates alerts from host agents, storage paths, network switches, and even backup jobs to surface the most probable root cause. You're not looking at fifty individual warnings anymore; you're looking at one consolidated issue with a ranked list of contributing factors. Setting this up starts with making sure you're running a supported version of vSphere 8 or later. The health services are built in but need proper configuration to function correctly. You need vCenter Server at least version 8.0 Update 3 or later for the full feature set. Here's what the initial configuration involves: you navigate to the vSphere Client, go to the Administration section, and select IU Health from the menu. From there you configure the data collection intervals, the alert thresholds, and the notification recipients. The default settings work for most environments but they're conservative. I usually adjust the collection interval from the default 5 minutes down to 1 minute for production clusters where I need faster detection. The tradeoff is increased storage usage in the vCenter database, which matters if you're on an external PostgreSQL or Microsoft SQL Server backend with limited capacity.
One thing beginners miss is that IU Health doesn't replace your monitoring tools. It complements them. If you're already running something like Datadog, Prometheus, or Zabbix, IU Health provides the vSphere-native context that those tools can't see on their own. The sweet spot is integrating the two so alerts from IU Health feed into your existing ticketing or incident management system. Most teams just set up email notifications, which is fine for small deployments but breaks down when you have hundreds of clusters generating daily health reports. I configured webhook integration with PagerDuty at my last environment and routed high-severity health events directly into incident channels. That cut our mean time to acknowledgment from roughly 40 minutes to under 8 minutes for critical infrastructure issues. There's a specific problem I ran into that took me a while to figure out. We had a cluster where IU Health was consistently reporting degraded performance on two hosts, but the hosts themselves were functioning normally. CPU ready times were low, memory pressure was absent, and storage latency was within acceptable ranges. The health score kept hovering around yellow. After digging into the underlying telemetry, I found that the issue was related to an outdated version of the VMware ESXi Host Agent that wasn't pushing network metrics correctly. The fix was patching the agent to match the cluster-wide version, then clearing the cached health data through the vSphere API. The command I used was a simple REST call to the /api/vcenter/health endpoint with a reset flag. That cleared the stale entries and the health scores corrected within the next collection cycle. This kind of ghost degradation happens more often than you'd think, usually after a partial upgrade or when hosts have been manually migrated between clusters without proper agent synchronization. The counter-intuitive part about IU Health is that it's most valuable during normal operations, not during outages. When everything is healthy, the baseline data it collects becomes the reference point for detecting anomalies. Without several weeks of clean health telemetry, the system has nothing to compare against when something actually breaks. I've seen teams deploy IU Health right before a major infrastructure migration and then wonder why the dashboards look noisy. The noise is normal. It takes about two to three weeks for the system to calibrate to your environment's typical behavior patterns. During that calibration period, I recommend disabling non-critical alert notifications so you're not drowning in threshold warnings that will stabilize on their own.
Another nuance that isn't well documented is how IU Health handles multi-site vCenter configurations. When you have Federated vCenter or HCX deployed across multiple sites, health data aggregation can create unexpected latency in the dashboard updates. The remote site health information has to traverse the WAN connection back to the primary vCenter, and depending on your link quality, you might see health scores that are up to five minutes stale. For most operational purposes this is acceptable, but if you're troubleshooting a cross-site issue in real time, the delays can be frustrating. The workaround is to check the health status at each site individually through its local vCenter first, then review the aggregated view at the primary for the overall picture. On the downsides side, IU Health has some genuine limitations. The first is storage overhead. Enabling full health monitoring with detailed metrics collection can add anywhere from 2 to 5 GB per month to your vCenter database depending on cluster size. If you're running vCenter on a virtual appliance with default disk allocation, you'll hit capacity faster than you expect. I've had to expand vCenter storage on two separate occasions in the first year of deployment. The second limitation is that IU Health only covers VMware infrastructure components. It won't monitor your applications running inside the VMs, your network switches outside the vSphere fabric, or your third-party storage arrays unless you've configured the appropriate integration plugins. You still need a separate monitoring solution for those layers. The third limitation is probably the most significant: the alerting logic can generate fatigue. The system is designed to be thorough, which means it will flag things that are technically outside specification but operationally harmless. A datastore with slightly uneven extents, a host with a minor NTP drift under 100 milliseconds, or a VM with a temporary snapshot consolidation pending will all trigger alerts. Over time, this trains your team to ignore the notifications because too many are false positives or low-severity items that resolve themselves. I've found that tuning the alert thresholds to match your actual operational standards rather than accepting the defaults makes a substantial difference. After three months of adjusting the thresholds, our alert volume dropped by roughly 60 percent while still catching the issues that actually require intervention.
Get the Full Details
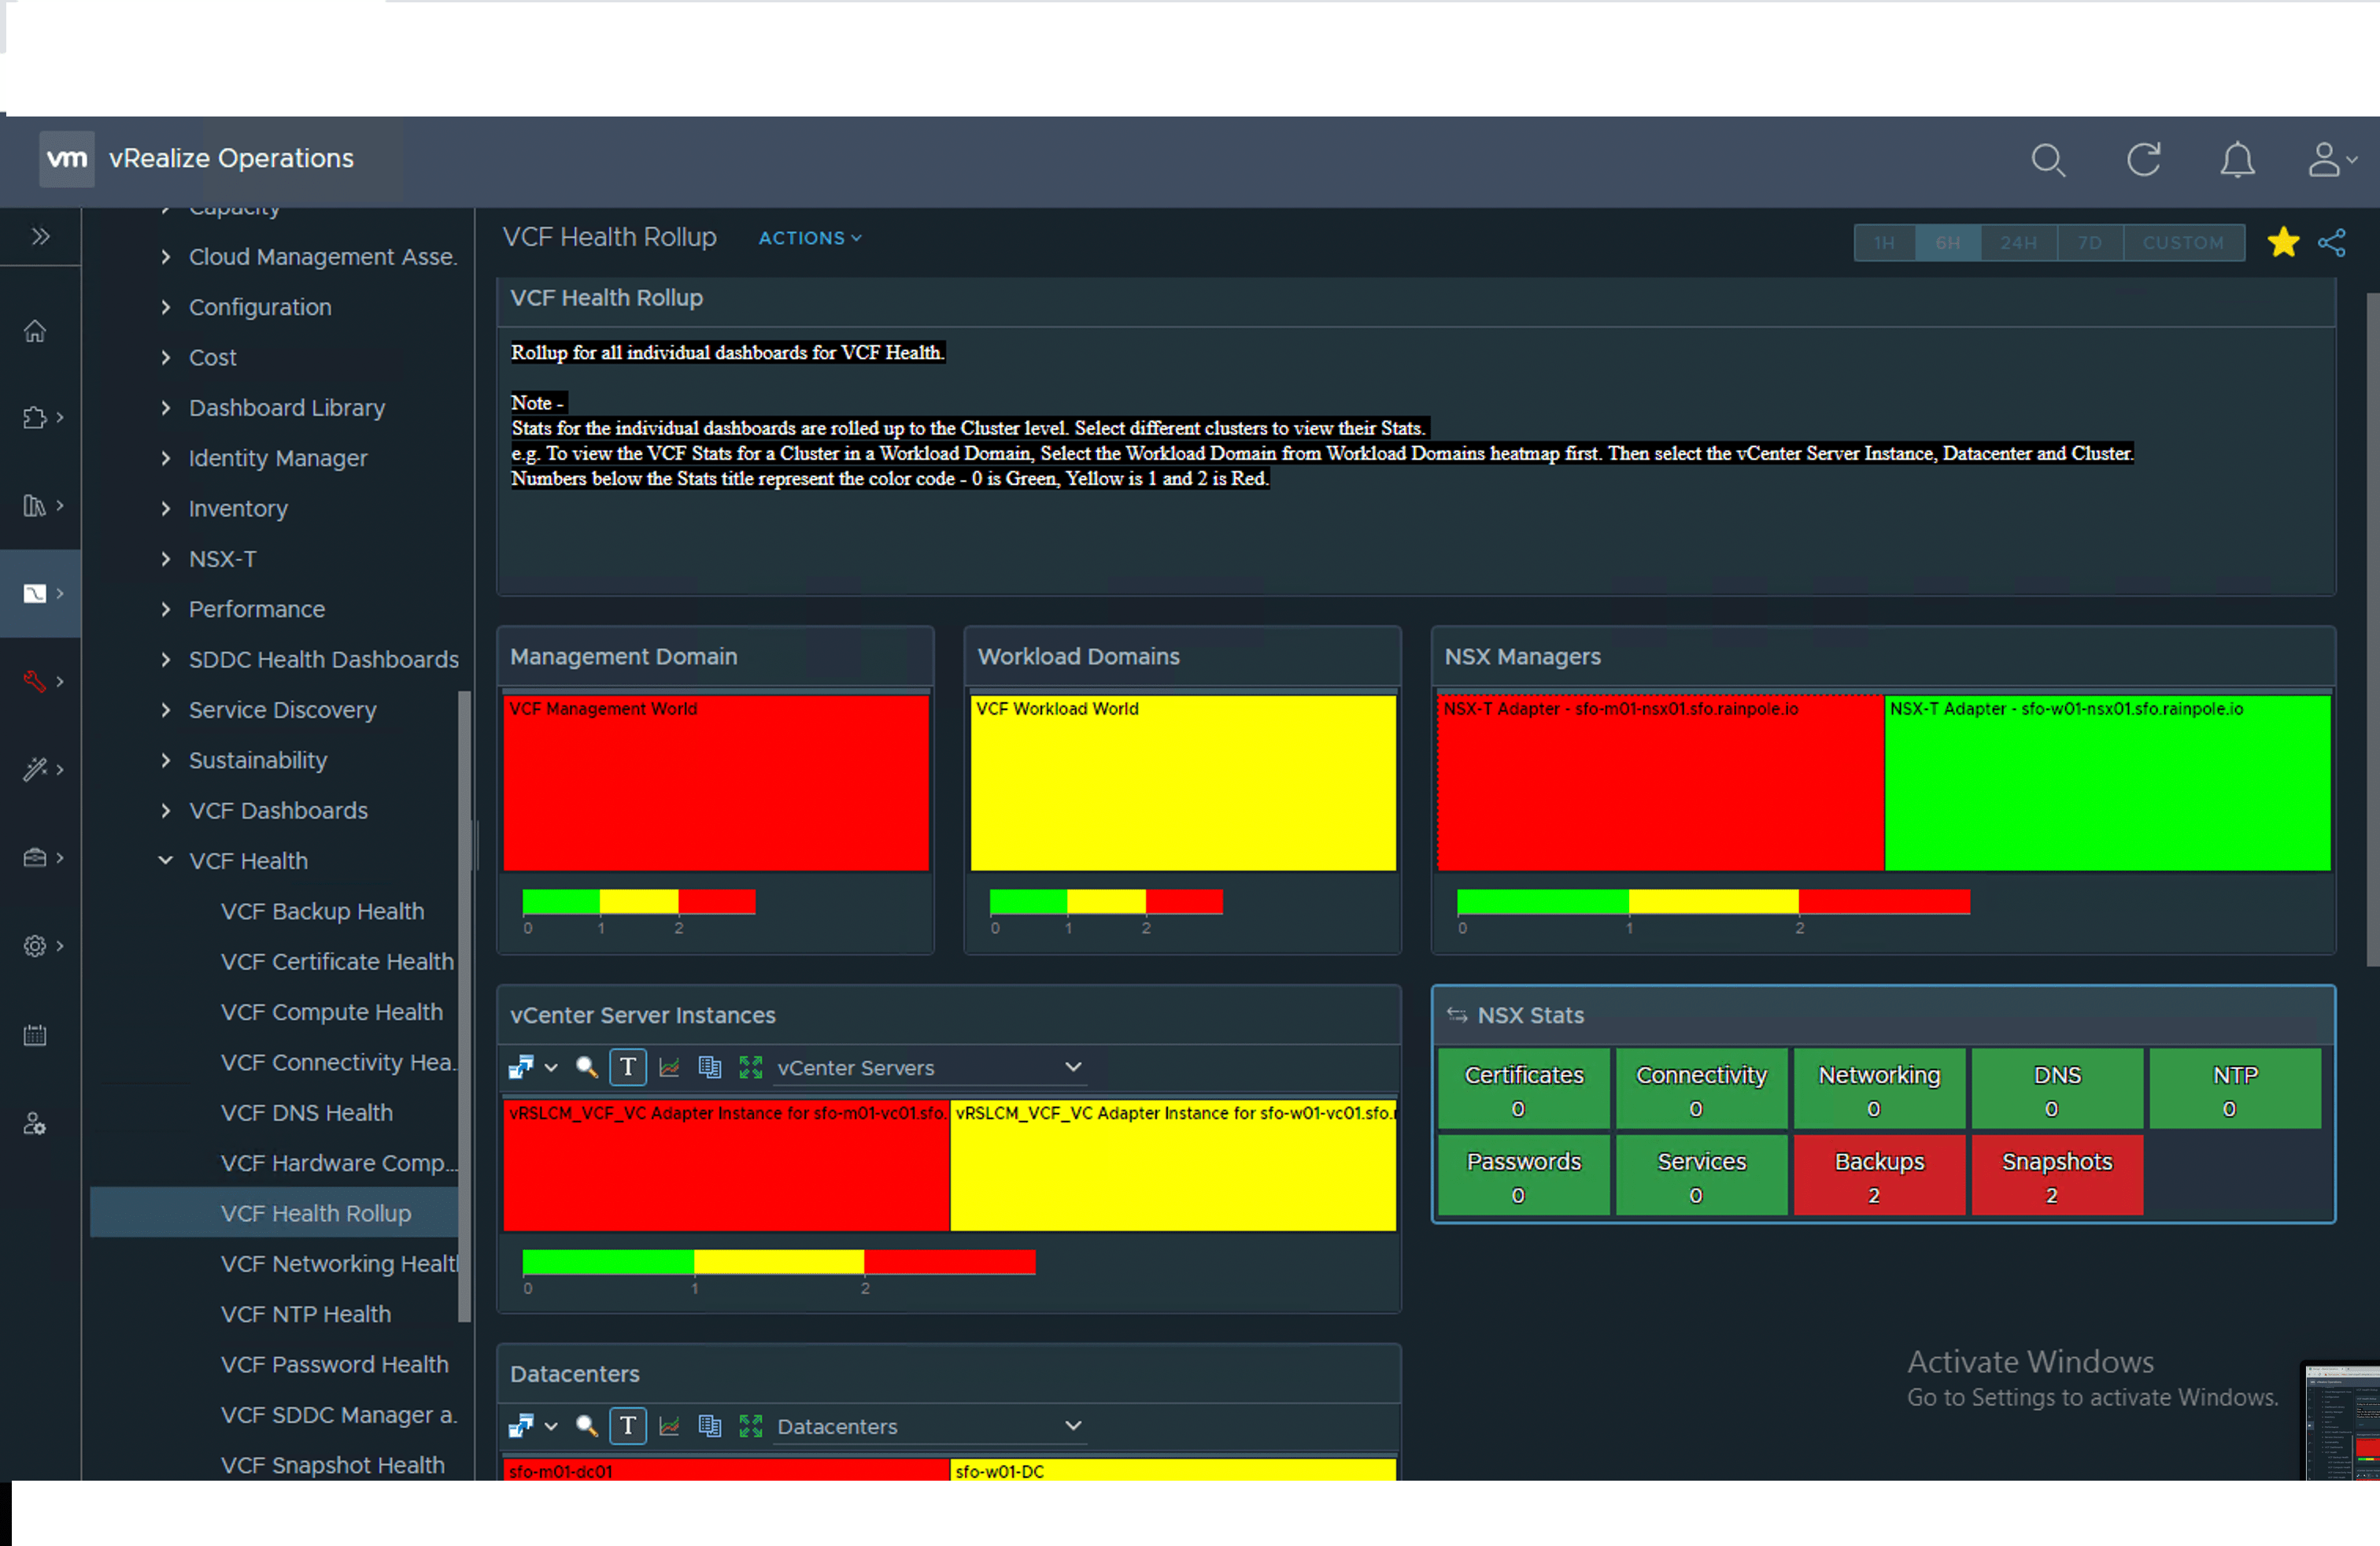
If you're working with older VMware environments that predate vSphere 8, the IU Health features simply aren't available. In those cases, you're stuck with the legacy vSphere Health Status and Dashboard views, which are functional but lack the correlation intelligence. There's no upgrade path for existing installations. You need to migrate to a supported vSphere version to get the full IU Health experience. For teams managing mixed environments during transition periods, I recommend running both the legacy health views and IU Health in parallel during the migration window. This gives you historical health data to compare against the new system's assessments and helps validate that nothing is being missed or misreported. The official documentation for IU Health configuration and the download for the vSphere Client plugins and related components is available through the VMware Customer Connect portal. You need an active support contract or evaluation license to access the full download library. From there you can find the vSphere Health Agent installer, the integration connectors for third-party tools, and the latest version compatibility matrices. Keep these updated. Running a mismatched agent version against your vCenter version is the fastest way to get unreliable health data, and it's easier to do than you'd think when you have dozens of hosts across multiple clusters.