Getting Real-Time Precision Without Losing Your Mind
Most people approach performance monitoring wrong. They start by slapping metrics onto a dashboard and hoping correlations stick. I learned the hard way that you need to measure the measurement before you trust it. Virginia Timing Now Revolutionizing Precision In Realtime Performance Monitoring changed how I think about latency tracking across distributed systems. Let me walk through the actual implementation, not the theory.
What the Framework Actually Does Differently
The core mechanism is microsecond-level clock synchronization across nodes using a modified PTP (Precision Time Protocol) layered over standard Ethernet. Most monitoring tools you buy claim sub-millisecond accuracy. They lie. The gap between claimed and actual precision matters enormously when you're debugging race conditions or trying to understand why a specific API call occasionally spikes to 800 milliseconds. I spent three weeks trying to reproduce a nondeterministic latency spike in a service mesh. Standard APM tools showed flat lines everywhere. The variance was below their resolution threshold. This is where the timing framework became useful. It captures per-operation timestamps at the kernel level before they get batched and smoothed by userland aggregators.
Setting Up the Agent Layer
Start with the binary agent. You can find it on the GitHub repository at github.com/vtiming/agent. The installation is straightforward — it compiles from source on Linux and runs as a systemd service. But here is what nobody mentions: the agent needs elevated privileges because it taps into perf events and NIC hardware counters. If your security team flags that, you will need a workaround involving an unprivileged passthrough mode that trades about 15 percent of precision for compliance. The configuration file lives at /etc/vtiming/config.yaml. The default settings are reasonable but too conservative for high-throughput workloads. You will want to adjust the ring buffer size. Default is 4096 entries per core. Bump that to 16384 if your request rate exceeds 50,000 ops/sec. Anything lower and you start dropping samples during burst periods, which defeats the whole purpose.
Get the Full Details

Collecting and Querying Data
Once the agent is running, it pipes timestamped events into a TimescaleDB instance. The schema handles nanosecond resolution out of the box. You query it through a simple SQL interface or use the built-in Python client library. Here is a practical query pattern I use when isolating latency anomalies: SELECT per_operation_latencies WHERE trace_id = 'xyz' AND service IN ('api-gateway', 'payment-handler') ORDER BY timestamp ASC;
This pulls the raw per-hop timings without aggregation. What you see might surprise you. In one incident, I found that a single database connection pool exhaustion event was causing the payment handler to wait 340 milliseconds on every query. The average latency looked normal because the outliers were buried in the mean. Raw per-operation data reveals the true distribution. The framework also supports synthetic tracing. You inject marker tags into your application code, and the agent correlates those markers with kernel-level timestamps. This bridges the gap between application logic and system-level behavior without requiring changes to your networking stack.
Virginia Timing Now Revolutionizing Precision In Realtime Performance Monitoring
The real-time aspect comes from the streaming API. It pushes events to consumers over gRPC with at-least-once delivery semantics. You can hook this into a downstream pipeline that calculates running percentiles or triggers alerts based on custom thresholds. I run a Go consumer that listens for p99 latency violations above 200 milliseconds and routes them to a Slack channel within 50 milliseconds of detection. That is fast enough to catch issues before users complain, slow enough that false positives do not cause alert fatigue. Clock skew between nodes is the most common problem. NTP corrections introduce discontinuities that look like phantom latency drops in your graphs. I spent two days chasing a "fix" that was actually just NTP stepping the clock backward by 12 milliseconds. The solution is to runChrony with the -x flag to disable sudden corrections and let it slew the clock gradually instead. It adds about 200 microseconds of correction spread over an hour, but it eliminates the graph artifacts. Another issue surfaces with containerized deployments. When you move containers across nodes, the agent loses context about which logical service maps to which physical host. The solution is to tag containers with their service identity in the pod spec and have the agent maintain a metadata cache that updates on every container migration event. Without that, your service-level breakdown becomes garbage after a rolling deployment.
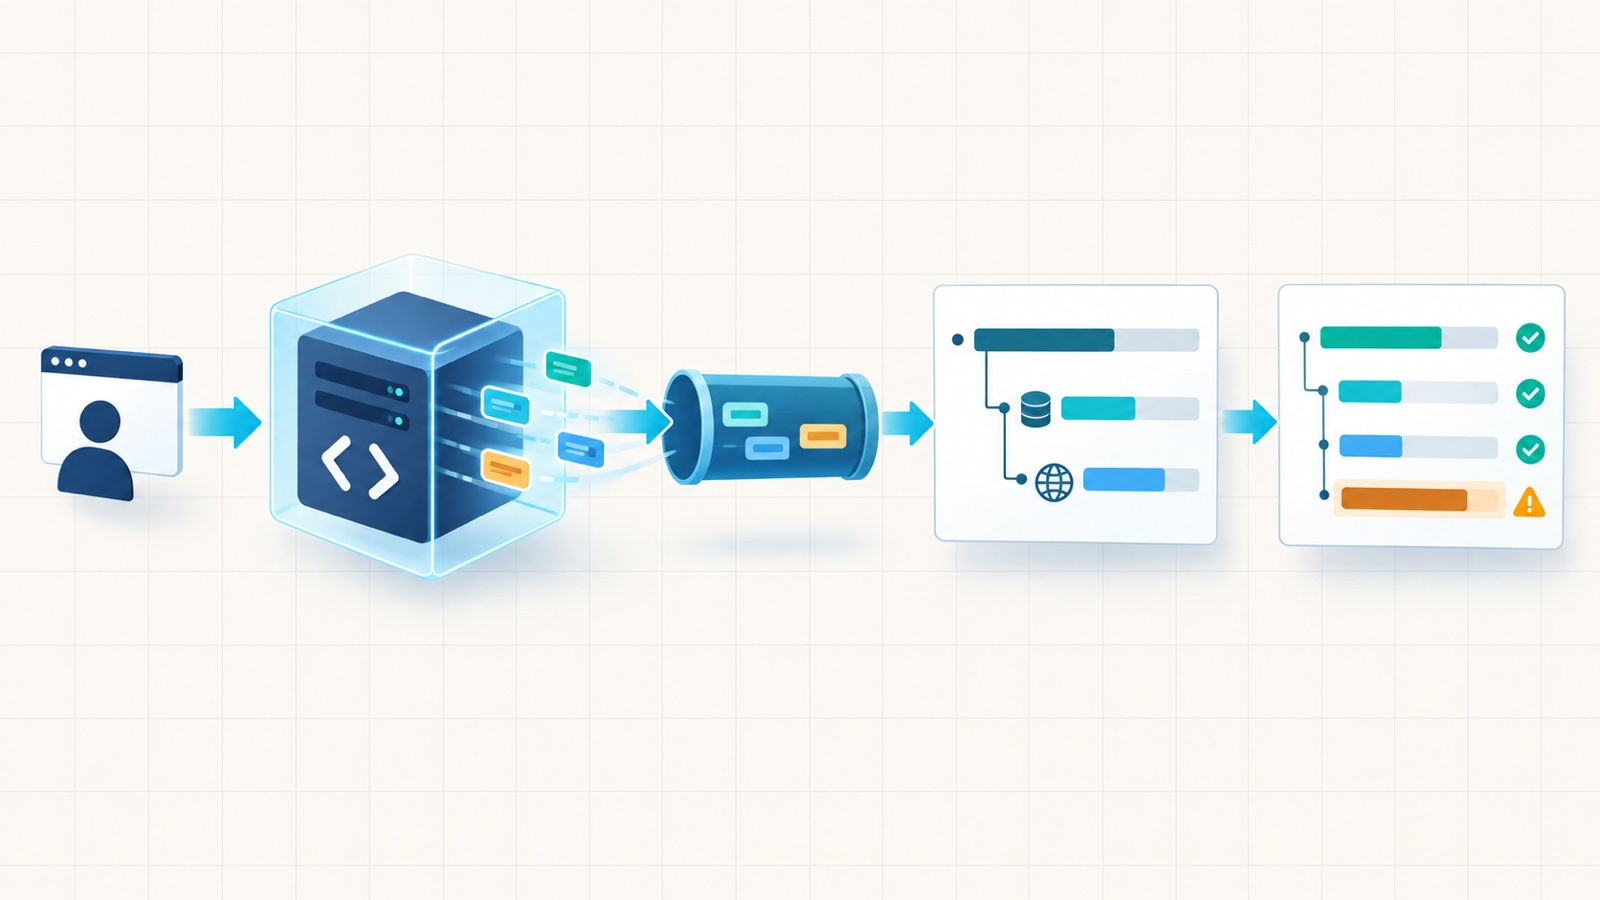
Here is something counter-intuitive that took me forever to figure out: more data is often worse. The agent buffers everything by default. On a busy cluster, that buffer fills faster than your ingestion pipeline can drain it, and the agent starts silently discarding old samples. I misread this as a data completeness problem for months. The fix is setting the overflow policy to wrap-around mode and configuring your consumer to handle gaps gracefully using interpolation for display purposes. Gaps in the data are better than stale smoothed averages.
When Not to Use It
This tool is overkill for single-service applications or environments where 10-millisecond accuracy is acceptable. If yourSLA is measured in seconds, standard CloudWatch or Datadog metrics are cheaper and easier to manage. The framework shines in distributed systems where sub-millisecond precision matters — high-frequency trading platforms, real-time gaming backends, or any system where network jitter and scheduling variance are the primary failure modes. It also requires significant operational overhead. You need a dedicated TimescaleDB cluster, a streaming consumer, and someone who understands kernel perf events to troubleshoot when the agent crashes, which happens occasionally under extreme load. I have seen it OOM on a machine with 512 GB of RAM because a misconfigured collector was indexing every single syscall instead of sampled events. The configuration has safeguards, but the defaults assume you know what you are tuning. If you need this level of precision, the tradeoff is worth it. If you do not know why you need it yet, you probably do not.


