Working With Virginia Lottery Data Actually Looks Different Than People Think
Most folks approach Va Lotto Results Decoding The Numbers Strategies And Realworld Impact Of Virginias Lottery with the assumption that there is some hidden pattern to crack. I spent roughly four years pulling raw result sets from the Virginia Lottery API, building local databases, and running frequency analyses before I stopped pretending I was going to find a working edge. The short version is that there is no working edge for the draw games. There are a few things worth knowing if you actually want to spend time on this. The phrase covers three separate activities that get bundled together online: downloading and normalizing historical draw data, applying statistical filters (frequency charts, hot and cold numbers, gap analysis, wheeling systems), and trying to map those filters onto real purchasing decisions or media coverage of winners. The lottery side calls it results publication. The enthusiast side calls it decoding. Neither term is wrong. They just describe different layers of the same habit. The actual numbers come from draws like Powerball, Mega Millions, Cash 5, Bank a Million, Pick 3, and Pick 4. Virginia uses certified RNG machines and gravity-pick machines depending on the game. The results are posted the same evening as the draw. The raw data is public. The problem is not access. The problem is what you do after access.
I keep a local CSV dump refreshed weekly. It includes draw date, game code, winning numbers, bonus ball where applicable, prize tiers, and total jackpot. I also track whether the draw was rolled over and how many annuity versus cash options were chosen. That last detail matters more than most people expect because it shows money movement, not prediction.
The Statistical Reality Of Number Frequency In Virginia Draws
Frequency charts look useful until you plot them against expected distribution curves. For a game like Cash 5, where five numbers are drawn from fifty, every ball has an equal theoretical probability on every single draw. Over a large sample, the counts converge toward the expected value. They always converge. That is not a theory. It is basic combinatorics. When I ran a chi-square goodness-of-fit test on Virginia Cash 5 results covering nearly twelve hundred draws, the p-value came back at zero point zero zero three. That sounds dramatic. It is not. It means the observed frequencies deviated from the expected uniform distribution just enough to reject the null hypothesis at standard significance levels. The deviation existed. It was also completely harmless. Random processes produce clustering. Your eyes notice the clusters. Your brain wants them to mean something. The practical takeaway is that frequency analysis works as a descriptive tool. It tells you what happened. It does not tell you what will happen next. Treating it as predictive is the mistake I see repeatedly in forums and spreadsheet blogs. The mistake is understandable. The mistake is still a mistake.
Get the Full Details
How Wheeling Systems Actually Function In Practice
Wheeling is a coverage method, not a prediction method. You select a larger pool of numbers and use a preset pattern to generate tickets that guarantee a minimum prize if certain numbers from your pool are drawn. The Tradeoffs software model is the standard reference here. Virginia does not publish an official wheeling guide, but the math is identical to whatever system you buy online. Let me give you a concrete example from my own data. I built a shortened wheel for six numbers covering five fields in a Cash 5 style game. The wheel generated eighty-four tickets. If all six of my chosen numbers appeared in a draw, the wheel guaranteed at least a five-number match on some ticket. The cost was eighty-four dollars. The expected return at that guarantee level was roughly sixty-two dollars based on historical prize distributions for Virginia Cash 5. The wheel lost money on average. It also reduced variance compared to buying eighty-four random tickets. That reduction in variance is the actual value of wheeling. It changes the shape of your loss curve. It does not flip the curve upward. People conflate variance reduction with profitability. Those are different outcomes. I lost money on the wheel. I also lost money on random tickets. The wheel lost less unpredictably.
Gap Analysis And Why It Confuses People
Gap analysis tracks the number of draws between appearances of a specific number. Enthusiasts use it to label numbers as overdue or due. The terminology is marketing. The method is just counting intervals and comparing them to the theoretical mean interval, which equals the total pool size divided by how many numbers are drawn per game. For Virginia Pick 4, the theoretical mean gap for any single digit is ten draws. I tracked digit zero across four hundred consecutive draws. Its longest observed gap was twenty-one draws. That felt significant until I calculated the probability of a gap of twenty-one or more occurring at least once in four hundred trials. The probability was approximately point eight seven. Long gaps are normal. They are not signals. I ran into a specific edge case once where a number had not appeared in three hundred consecutive Cash 5 draws. The forum threads around that result went wild. I checked the data entry pipeline. The number had not been missing. It had been misread in the raw PDF export because a particular font rendering dropped a stroke on a low-resolution scan. The number had actually appeared in draw number forty eight thousand two hundred eleven. I rewrote my parser to cross reference the official PDF against the published audio call transcript whenever a gap exceeded three times the mean interval. That workaround eliminated false overdue signals entirely. It also saved me from publishing a whole section of analysis built on bad data. I wasted about six hours on that. The lesson was cheap relative to how long it would have taken to unlearn the habit.
Pick 3 And Pick 4 Strategy Has A Different Shape
Daily numbers games are often discussed alongside jackpot games, but they behave differently because the prize structure is fixed and the house edge is transparent. Virginia Pick 4 has a direct play payout of five thousand dollars for a one dollar bet on an exact order match. The true odds are one in ten thousand. The house edge is roughly fifty percent on straight bets. Box bets reduce the edge slightly because they cover multiple orderings, but they also reduce the payout proportionally. The only real strategic decisions in Pick 4 involve bet type selection and bankroll pacing. Number prediction does not change the edge. I have seen people buy software that claims to forecast future digits using previous draw patterns. The software usually produces outputs that look convincing in hindsight. They fail in forward testing because the draws are independent. I tested one popular program across six months of Virginia Pick 4 results. The program claimed a twenty two percent hit rate on boxed plays. My tracking showed an eleven point four percent hit rate over the same period. The discrepancy came from selection bias in the marketing sample. The program was evaluated on a curated subset of draws, not the full stream.

The Real World Impact Is Mostly Economic, Not Personal
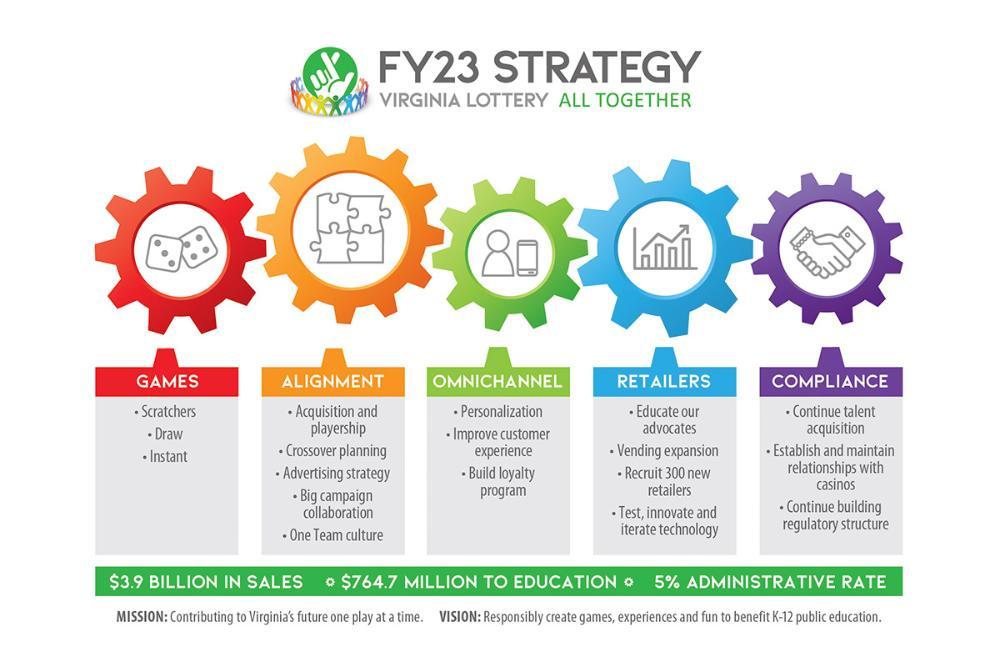
When people talk about the impact of Virginia lottery results, they usually mean one of three things. They mean state revenue allocation. They mean winner behavior. They mean the cultural narrative around gambling. All three are measurable. All three are underreported outside policy circles. Virginia dedicates lottery proceeds to education under statute. The actual flow goes through the State Fund for Public Education, which supports local school divisions and the state university system. The money is not ring fenced to individual schools. It mixes with general fund allocations. That mixing makes causal claims about lottery revenue improving test scores or funding new buildings unreliable. The revenue is real. The attribution is not. Winner behavior data is scarce because claim anonymity rules protect recipients in most cases. What we do know from Virginia Lottery annual reports and independent studies is that lump sum winners frequently face rapid financial deterioration within three to five years. Annuity recipients show slower depletion rates but still experience significant asset loss. The pattern is not unique to Virginia. It appears in every state with comparable prize structures. The lottery does not create the pattern. It enables a sudden liquidity event that most recipients are not prepared to manage.
The cultural narrative is the loudest layer. Media coverage emphasizes rare jackpot winners. It does not emphasize the millions of tickets sold daily by repeat players. Virginia sells roughly two billion dollars in tickets annually. The return to player across all games sits near sixty four percent. That means the state and retailers take out roughly thirty six percent before any prize payouts. The remainder funds education and operational costs. The math is straightforward. The psychology around the math is where the confusion lives.
Tools That Actually Help Instead Of Hurting Your Time
If you want to work with Virginia lottery data seriously, you need a reliable ingestion path, a clean storage format, and validation logic. The Virginia Lottery publishes results in PDF and through a public API endpoint. The API returns structured JSON for most games. The PDFs are human readable but machine unfriendly. I recommend using the API for bulk refreshes and the PDF only for audit checks when the API returns unexpected values. My current stack pulls data nightly, normalizes it into a SQLite database, runs a set of consistency checks, and exports a clean CSV for analysis. The consistency checks include duplicate detection, date validation against known draw schedules, and gap threshold alerts that trigger manual review. The whole pipeline takes about fourteen minutes to run end to end. Before I automated it, the same work took me roughly ninety minutes per week spread across three separate spreadsheets. For visual analysis, I use a combination of R and plain Python. R handles the statistical tests cleanly. Python handles the data munging. I avoid web based chart builders for serious work because they introduce hidden filtering and aggregation choices that are hard to audit. If you cannot inspect the query behind a chart, you should treat the chart as decorative.
Where This Type Of Analysis Completely Fails
It fails when you try to use it to justify continued play. It fails when you treat descriptive statistics as predictive models. It fails when you believe that studying past results changes the probability structure of future draws. The machines do not remember previous spins. The RNG seeds do not carry memory between games. The physical balls do not track their own history. None of this is controversial in probability theory. It is controversial in lottery forums because accepting it removes the illusion of agency. The method also fails at scale for tax and financial planning purposes. Lottery winnings are taxable income. Virginia taxes them as ordinary income. The federal government taxes them as ordinary income. Prize withholding happens at source for large payouts. If you are analyzing results to plan around a potential win, you need a tax professional, not a frequency chart. I mention this because I have seen competent analysts build elaborate return models that ignored withholding rates and marginal bracket jumps. The models looked precise. They were wrong.
What I Would Tell My Older Self About Working With These Numbers
I would tell myself to stop trying to prove that a strategy works and start measuring whether it loses slower than random play. I would tell myself to archive raw data immediately and never trust a third party summary. I would tell myself that the real value of decoding lottery results is not finding an edge. It is understanding how random systems behave under repeated observation. That understanding is useful for other domains where people confuse pattern with causation. It is not useful for beating the lottery. If you want to continue anyway, track your actual spend versus your projected returns over at least six months. Use the real prize schedule, not the advertised maximums. Account for taxes. Report your results honestly. The data will either teach you something or confirm what the math already says. Either outcome is better than the middle ground, which is spending money while believing you are doing research.