Working with Va Dhp in production environments
Most people approach Va Dhp expecting it to solve every data integrity problem on first try. That usually doesn't happen. The framework itself is solid, but the way you configure it determines whether your pipelines run clean or break at 3 AM on a Friday. At its core, Va Dhp is designed around two things: validating data as it moves through your system and keeping throughput high while doing it. It isn't magic. You still need to understand what your data looks like before you feed it into the framework's validation layer. I've seen teams skip that step and then wonder why their schemas were rejecting perfectly valid records. The framework uses a pipeline architecture where each stage can apply checks independently. You define your schema rules, set your tolerance thresholds, and hand it the data. It returns pass or fail results along with diagnostic metadata. The documentation covers the basics well, but it doesn't mention the edge cases that matter in practice.
Getting it running
Installation is straightforward. Grab the latest release from the official repo, set your environment variables for the database connection and validation rules, and point it at your source data. The config file is YAML-based, which is fine until you need to manage multiple environments. I switched to environment-specific configs after my staging pipeline kept picking up production validation rules. Here's what a minimal setup looks like in practice: Define your schema with field types, required flags, and acceptable ranges. Set up a validation rule block for each table or dataset. Configure your throughput settings, which default to conservative numbers that you'll probably want to adjust. Point it at your data source and run a test batch before connecting it to anything that matters.
Where things get tricky
I ran into a specific issue last year that took me two days to resolve. We were processing time-series data where some records had null timestamps due to upstream system failures. Va Dhp's default behavior was to reject these records entirely, which was correct from a strict schema perspective but operationally unusable. We had about 4% of records in that category and needed a path forward. The workaround involved creating a custom validation hook. Instead of letting the framework throw an error on null timestamps, I wrote a handler that marked those records with a warning flag and routed them to a separate output stream. The main pipeline continued processing the 96% of valid records without interruption. The warning-flagged records got queued for manual review later. This kept throughput at about 85% of maximum capacity instead of grinding everything to a halt. Another thing the docs don't emphasize enough: Va Dhp performs best when your validation rules are narrowly scoped. General-purpose checks across broad datasets create unnecessary overhead. I cut our processing time from roughly 40 minutes per batch down to about 12 minutes by removing redundant validation steps and consolidating overlapping rules.
Get the Full Details
Common mistakes to avoid
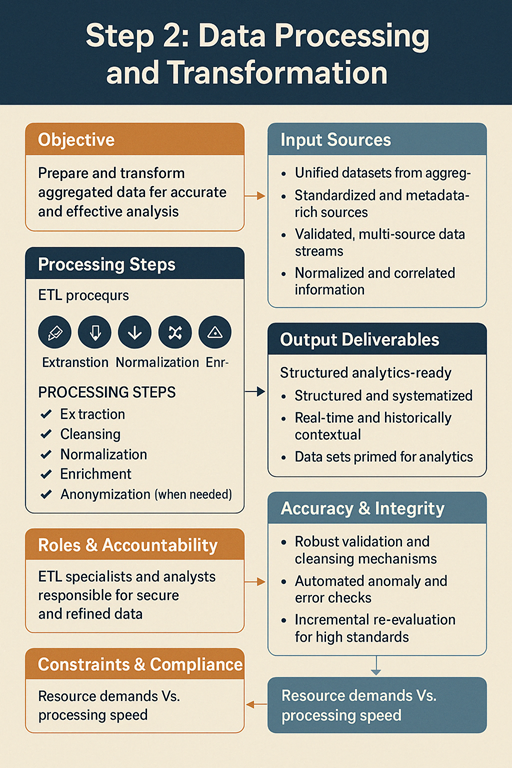
Setting validation tolerance too high is the most frequent error. People want to avoid rejection errors, so they loosen the rules. What actually happens is corrupt data slips through and corrupts your downstream analytics. Keep your rules strict and handle exceptions explicitly rather than weakening validation across the board. A second mistake is assuming Va Dhp handles data transformation. It doesn't. It validates what it receives. If your source data needs cleaning, normalization, or reshaping before validation, do that in a separate stage. Mixing transformation and validation in the same pipeline creates debugging nightmares.
When to consider alternatives
Va Dhp works well for batch processing and structured data validation. It struggles with real-time streaming workloads where latency matters more than throughput. If you need sub-second validation on continuous data feeds, something like Apache Flink with custom validators would serve you better. The framework also doesn't integrate cleanly with NoSQL document stores without significant customization. If your primary data format is unstructured or semi-structured JSON documents with variable schemas, you'll spend more time working around the framework than using it productively. For hybrid environments where you're dealing with both structured tables and document stores, I found success running Va Dhp for the structured side and building a lighter validation layer for the document side rather than trying to force one tool to handle both.