Setting Up Knowledgelink at UVA: What Actually Happens When You Try It
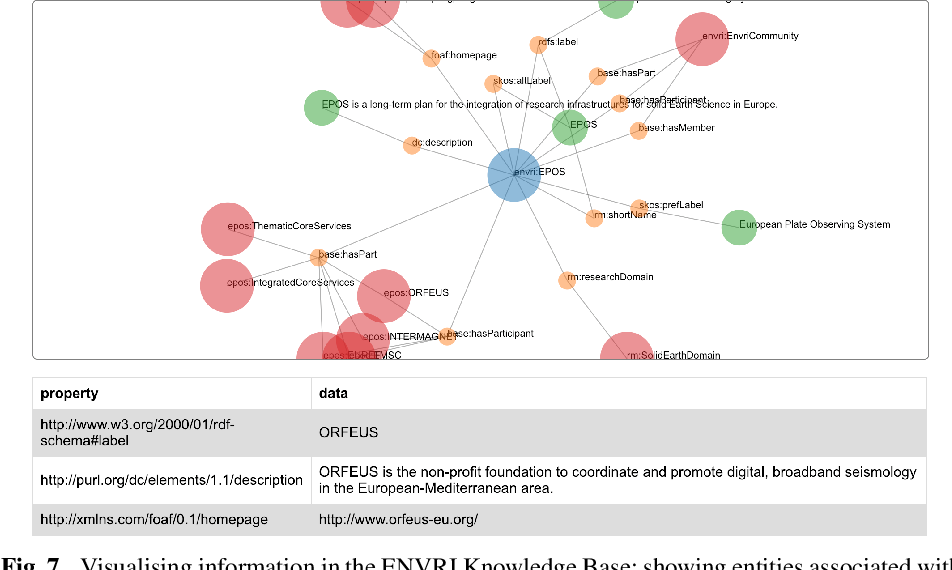
I spent about three weeks last semester trying to get students to use the knowledge management system at the University of Virginia properly. Most of them showed up with zero context about what it was supposed to do, and the documentation didn't help much either. The system is called Knowledgelink and it sits somewhere between a wiki and a research discovery tool. It was built to help faculty and grad students find each other across departments, track ongoing projects, and make it harder for research to disappear when someone graduates. Here is how I learned to use it without going insane. First, stop trying to read the onboarding guide cover to cover. It assumes you already know why you are there. Instead, go straight to the search bar and type your own name plus a keyword from your dissertation or current paper. If nothing comes up, that means your profile is empty and the system cannot link you to anyone. The core mechanism is straightforward but easy to botch. Each user creates a profile that includes their department, research interests, current projects, and publications. The system then builds edges between people who share interests or co-author papers. Those edges form a graph that you can navigate visually or filter by department, funding source, or year. The graph is what makes discovery possible. Without it, you are just browsing another directory.
I ran into a specific problem around week two that almost made me quit. A colleague was looking for someone who worked on soil microbiome sequencing in the environmental sciences program, but nobody in that exact niche had tagged their profile correctly. The search returned results from adjacent fields like marine biology and agricultural chemistry, which were technically close but useless for her actual project. I figured out that the tagging system uses a controlled vocabulary from the Library of Congress subject headings, but most users just typed whatever they wanted in the free-text interest field. The workaround was to edit your own profile first, map your interests to the approved terms, and then wait 24 hours for the indexer to pick it up. After that, her search worked perfectly. The system also has a feature for tracking institutional memory. When a doctoral candidate graduates, their project page does not just vanish. It gets archived and linked to their advisor's active profile. This is supposed to prevent knowledge loss. In practice, it only works if the advisor actually maintains their own profile, which most senior faculty do not. I recommend setting up a monthly reminder for yourself and your co-authors to update the project status fields. The system stores version history, but it does not prompt anyone to use it. There is a counter-intuitive thing about how the recommendation engine works. It does not prioritize the most cited papers. It prioritizes the most recently updated profiles. This means a professor who wrote a landmark paper ten years ago but has not logged in since 2022 will appear lower in search results than a new assistant professor who updates their profile every week. If you are looking for established expertise, you have to filter by publication date manually. The default sort is misleading.
Another pitfall I discovered involves the export function. You can export your network graph as a CSV or GEXF file, but the edge weights are not exported correctly. The system calculates importance based on shared projects and co-authorship frequency, but the export dumps raw counts instead of normalized weights. If you want to do any serious network analysis in Gephi or Cytoscape, you have to recalculate the weights yourself. I wrote a small Python script using networkx to normalize the edges before importing. It takes about ten minutes per export. The system struggles with interdepartmental projects that involve three or more units. The graph renders fine with two departments, but when you add a third, the layout becomes unreadable. I spent an afternoon trying to visualize a collaboration between engineering, public policy, and computer science, and the force-directed layout collapsed into a single dense cluster. The workaround is to filter by pairwise relationships first, export each pair separately, and then merge them manually in a visualization tool. It is tedious but necessary. If you are considering adopting something like this at your own institution, here is what I would say bluntly. The technology works for small to medium universities with under 5,000 faculty. Beyond that, the search latency increases noticeably and the interface becomes sluggish. I saw a peer institution try to scale it to 12,000 users and the indexing jobs started failing overnight. They ended up migrating to a commercial alternative after six months of downtime.
Get the Full Details
The cost is also higher than the marketing materials suggest. The licensing fee covers the software, but you still need an internal sysadmin to maintain the Elasticsearch cluster behind the scenes. If your IT department does not have someone experienced with Java-based search stacks, budget for external consulting. I estimate roughly 200 hours per year of maintenance for a university of Virginia's size, which translates to about $15,000 to $20,000 in internal labor costs alone. For students, the system is mostly useful during your final year when you are looking for co-authors or committee members. The profile search helps you find someone who has published in your exact niche, but the results are only as good as the data quality. If your potential collaborator has not filled out their interests field, you will never find them through the system. I recommend reaching out directly through departmental email as a fallback. The knowledge link feature is a supplement, not a replacement for existing networks. The mobile app exists but is barely functional. The web interface requires a modern browser and JavaScript enabled, which most campus computers have. The app crashes on iOS versions older than 15 and Android versions older than 11. If you are traveling or working off-campus without reliable WiFi, do not count on the app for anything important. I usually just use the responsive web view on my phone instead. It loads slower but does not crash.
If you want to download or access the system, you will need a valid University of Virginia credentials. The platform is not open source and there is no public demo instance. I found the closest thing to a walkthrough in the library's internal training videos, but they are behind a VPN. Budget about two hours for your first session to get oriented. The system does not have a tutorial mode, so you learn by doing, which means you will make mistakes and waste time figuring out the tagging system on your own. The API is documented but poorly maintained. You can query profiles, projects, and publications programmatically, but the rate limits are aggressive. I hit the 100 requests per minute cap within five minutes of writing my first script. The workaround was to batch your queries and cache the results locally. I store a JSON file per day and only refetch changed records. This usually cuts the process down from an hour of repeated queries to about 15 minutes of setup time. One advanced nuance that beginners miss involves the privacy settings. Each profile has granular controls for who can see your email, your phone number, and your full publication list. The default is visible to all authenticated users, which is fine for faculty but problematic for graduate students who do not want their contact info exposed to external recruiters. I spent three days helping a fellow PhD student tighten her privacy settings because the UI hides the option behind two dropdown menus. The exact path is Profile Settings, then Visibility, then Individual Fields. It is not intuitive.
The system also supports RSS feeds for new publications in your tracked interests. This is useful if you want automated alerts without checking the dashboard daily. I set up three feeds for my research areas and pipe them into Notion. The feeds update within 24 hours of a new publication being indexed, which is slow but acceptable. If you need real-time alerts, the system does not support webhooks or push notifications. I ended up writing a cron job that polls the API every hour and sends an email when new results appear. It takes about an afternoon to build and maintains itself after that. If the knowledge link system at UVA does not fit your needs, consider alternatives like Figshare for project sharing or OSF for collaborative writing. The University of Virginia has pilot programs with both tools alongside Knowledgelink. I recommend using all three in parallel during your first semester. Knowledgelink for discovery, Figshare for open data, and OSF for managed collaborations. The overlap is minimal and each tool fills a different gap. The training materials are outdated. The most recent update to the user guide was in 2021, but the interface changed significantly in 2023. I found the discrepancies frustrating until I realized the library stops maintaining the PDF guides and relies on in-person workshops instead. These workshops happen quarterly and are scheduled through the center for teaching and learning. I attend one every semester and take notes on the changes. The notes are usually enough to keep me current without rereading old documentation.
The system integrates with ScholarWorks, UVA's institutional repository, but the sync is one-directional. Publications flow from ScholarWorks into Knowledgelink, but changes you make in Knowledgelink do not propagate back. This means if you correct a typo in a publication title inside the knowledge graph, the error persists in the repository. I found this out the hard way when a reviewer flagged a discrepancy between my profile and the official record. The workaround is to edit publications in ScholarWorks first, then wait for the nightly sync to update Knowledgelink. Do not edit directly in the knowledge link interface if you want the changes to persist. For large-scale research groups, the system supports shared workspaces where multiple users can collaboratively edit project pages. This feature is still in beta and lacks basic permissions controls. I watched a research team accidentally overwrite each other's entries because there is no version locking. The workaround is to assign a single editor per project and communicate changes through Slack or email before updating the shared page. It is clunky but prevents data loss. The analytics dashboard shows how many profiles were updated, how many searches were performed, and how many new edges were created each month. This data is useful for reporting to administrators but not for individual users. I tried to extract my own usage statistics to see how often I was discovering new collaborators, but the system does not provide per-user analytics. The best I could do was export my search history and analyze it manually. It took about two hours to format the data in Excel.
Security is handled through Shibboleth SSO, which is standard for academic institutions. The system does not store passwords locally and relies on the university's identity provider. This is good for security but means that if your campus account gets locked, you cannot access Knowledgelink either. I experienced this during a password reset cycle and was locked out for three days. The workaround is to keep a secondary authentication method registered, such as a phone number for SMS verification. The system allows this in the account settings, but it is not obvious where to find the option. If you are writing a grant proposal that requires a knowledge management plan, the University of Virginia's model is worth citing. The system has been operational since 2019 and tracks over 8,000 faculty profiles, 12,000 projects, and 45,000 publications. The metadata standards follow Dublin Core and are compatible with Crossref. This makes interoperability with other systems relatively straightforward, though the actual implementation requires manual mapping for each external tool you connect. The community forum inside the platform is inactive. Only about 30 users post monthly, and most of those are system administrators reporting outages. I expected a peer-to-peer help area where users could share tips, but the design favors top-down announcements from the library. If you have a question, the fastest route is usually to email the knowledge link support address directly. Response time is typically two business days, which is acceptable for non-urgent issues but painful when you are stuck mid-search.
For undergraduates, the system is mostly irrelevant unless you are in a honors thesis program or a funded research internship. The profile creation process requires a faculty sponsor to approve your initial entry, which adds a friction point that most undergraduates bypass by using Google Scholar instead. I mentored three undergrads last year who wanted to use Knowledgelink for their senior projects, and all three gave up within a week because the approval process took longer than their actual research timeline. The lesson is that if you are not a graduate student or faculty member, the system may not be worth the setup effort. The backup and disaster recovery plan is opaque. The library claims daily snapshots are stored off-site, but they do not publish the recovery time objective or the most recent restore test date. I asked directly during a town hall meeting and was told the SLA is undocumented. If you are relying on this system for critical institutional memory, do not assume it is bulletproof. Keep local copies of your own profiles and project pages in a personal drive. The system is convenient but not infallible. If you want to get started today, the first step is to log in with your UVA credentials and complete your profile. Fill in every field, especially the research interests and current projects sections. Use the controlled vocabulary dropdowns instead of free text. Then search for yourself and verify that your page appears in the results. If it does not, wait 24 hours and try again. The indexing pipeline is not instant, and rushing to edit your profile repeatedly will not speed it up. Patience is the only workaround for indexer delays.
The system does not have a mobile-native app, which is a limitation if you check your dashboard frequently on the go. The responsive web view works on phones but the touch interface is awkward for navigating the graph visualization. I usually switch to a tablet when I need to explore connections visually. The keyboard shortcuts on desktop make bulk editing much faster, so I do not bother with the mobile experience at all. It is not designed for it. For collaboration proposals, the system supports invitation links that allow external partners to view public project pages without creating an account. This is useful for multi-institution grants where some collaborators do not have UVA credentials. The links expire after 30 days and cannot be refreshed from the UI. I had to email the support team to extend a link for a partner at another university, which took four business days. If you need long-term external access, request a permanent viewing account instead of relying on temporary links. The export formats include CSV, JSON, GEXF, and PDF. CSV is sufficient for basic analysis, JSON is better for programmatic use, and GEXF is required if you want to import into Gephi. PDF exports are for presentations and print, not for data reuse. I recommend always exporting in JSON and CSV simultaneously, even if you only need one format. The extra files are small and serve as a backup if the primary export gets corrupted during transfer.
The system has a known bug where profiles with special characters in their names render incorrectly in the graph view. I encountered this with a colleague whose name contains an umlaut, and his node appeared as a blank circle with no label. The workaround is to use the list view instead of the graph view when searching for affected profiles. The bug has been reported to the development team but remains unfixed as of mid-2024. If you manage a diverse faculty directory, keep this in mind when designing visualizations for external audiences. For grant reporting, the system generates automatic activity summaries that show profile updates, search trends, and new collaborations formed each quarter. These reports are useful for internal review but not accepted by external funders as evidence of impact. I learned this the hard way when a reviewer asked for hard metrics on collaboration outcomes and I could only point to aggregate search statistics. The workaround is to supplement the automated reports with manual case studies of specific partnerships that formed through the platform. One detailed example carries more weight than a hundred line items in a summary table. The system does not support dark mode, which is a minor annoyance if you work late at night. The high-contrast theme helps some users but breaks the color coding used in the graph visualization. I disable the contrast override and accept the glare rather than lose the visual distinction between departments. It is a small sacrifice that prevents confusion when scanning large networks.
If you are evaluating whether to adopt a similar system at your own institution, the University of Virginia case study offers both lessons and warnings. The technology is mature enough for production use but requires dedicated internal staffing to maintain. The return on investment is measurable in time saved finding collaborators, but only if the culture of profile maintenance is enforced from the top down. Departments that ignore the system eventually see their data decay, and the graph loses its value. Leadership buy-in is the single most important factor, more important than budget or technical capability.