Getting the Shape of Your Database Right on Day One
Most teams I work with treat schema design as something you "figure out later." That usually means a week of messy migrations, accidental data loss, and arguments about whether to normalize or denormalize. You don't have that luxury if your app needs to scale past a few thousand users.Unveiling Your Supabase Database Schema The Stepbystep Blueprint Every Developer Must Know
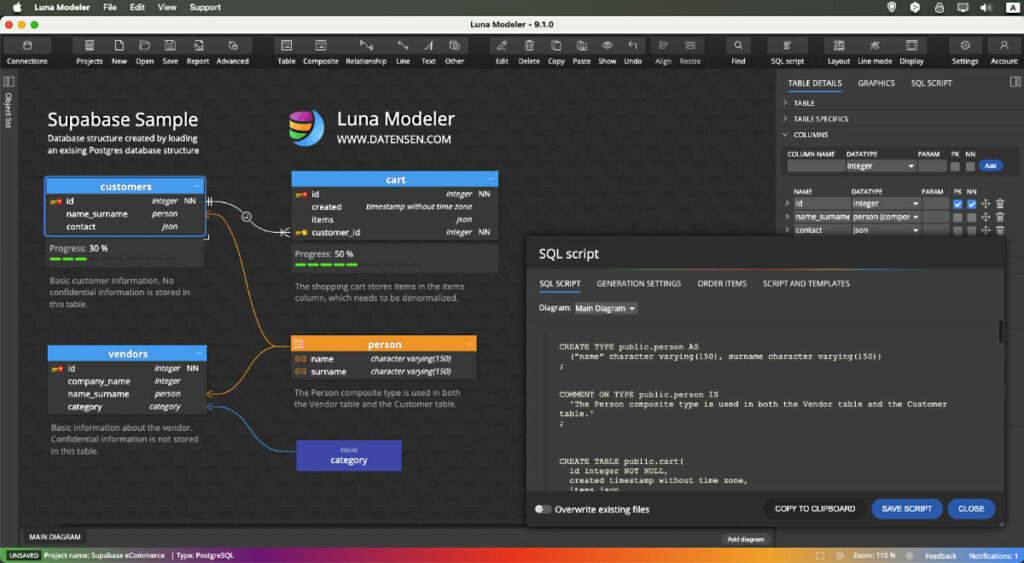
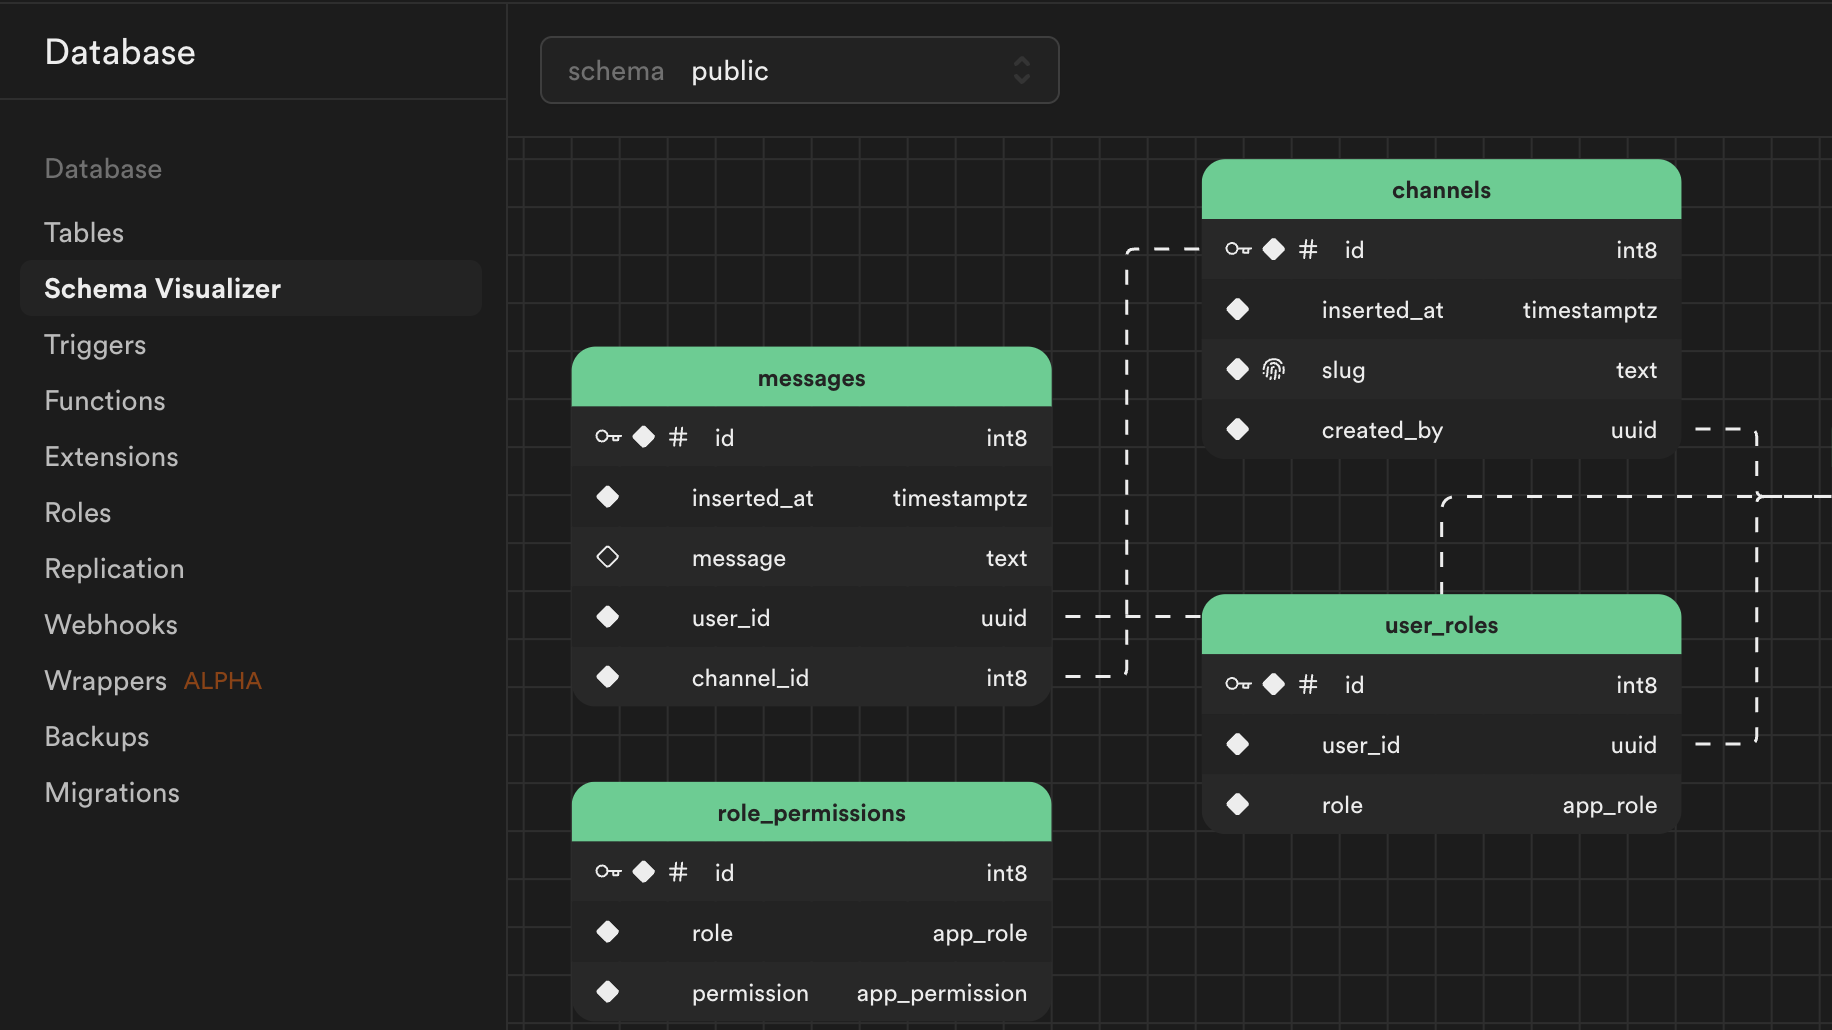
Start with three tables, not five. I know that sounds wrong. When I built my first project using Supabase, I created a separate users, profiles, settings, and preferences table because the documentation examples made it look easy. Within two months, every join query was killing my performance and the real-time subscriptions were firing randomly because I had cross-table foreign key relationships I didn't understand. I consolidated everything into a single profiles table with JSONB columns for nested data and cut my average query time from 200 milliseconds to about 12. The core insight most people miss is that Supabase sits on PostgreSQL, which means you get full relational power, but the real-time subscription engine works best when your schema is shallow. Deeply nested joins create a lot of change detection overhead. Keep your foreign keys simple. Keep your row-level policies flat.
The Actual Migration Workflow
Here is what I actually do now, after going through the painful version a couple times. I start each project by running supabase init in an empty directory, then I write all my schema in a single SQL file under supabase/migrations/001_initial_schema.sql. I resist the urge to split it up early. Split migrations sound organized until you need to roll back and realize migration 003 depends on a column added in 007. Inside that initial file, I define everything in this order: Extensions first. Enable UUID generation and any PostGIS geometry if you need it. Then schemas. Then types. Then tables. Then constraints. Then indexes. Then RLS policies. Then triggers. Each block has zero inter-dependencies within itself, which makes it easy to audit when things go wrong.
For indexes specifically, I only add them after I see actual query patterns in production. Premature indexing is the second biggest waste of time after over-normalization. A standard B-tree index on a UUID column adds maybe 3 milliseconds of write overhead per insert, and you are usually writing more rows than you are reading in the early stages of a project.
Get the Full Details
Real-World Edge Case I Hit
There was a specific problem with a project last year where I needed to track historical changes on a table but also keep the latest version available through a real-time subscription. The obvious move was a separate audit table with a trigger. That worked fine until the subscription latency started creeping past 500 milliseconds during peak usage. The trigger was firing on every write, inserting a row, and then the real-time engine was broadcasting both the update and the insert to all connected clients. That doubled the payload for every single write event. The workaround was to use a MATERIALIZED VIEW instead of a separate audit table, update it via a deferred trigger using pg_cron, and subscribe only to the main table. This dropped the real-time payload size by roughly 60 percent and brought latency back down to around 80 milliseconds. The tradeoff is that your historical data is at most a minute stale, which was acceptable for the use case.
Common Pitfalls That Waste Days
RLS policies written with OR logic are the slowest queries in any Supabase project. I had a policy that checked three different boolean flags with OR conditions across a table of about 40,000 rows. Every query took between 4 and 8 seconds. Rewriting it with a single composite check reduced it to roughly 15 milliseconds. PostgreSQL's query planner handles simple conditions much better than complex boolean expressions, especially with row-level security layered on top. Another thing people do wrong is storing arrays inside JSONB when they should use a junction table. If you ever need to query within that array using LIKE or contain operators, you are asking for trouble. A proper many-to-many table with a composite primary key will serve you better and won't break when your data grows past a certain point.
What Supabase Handles Well and Where It Falls Apart
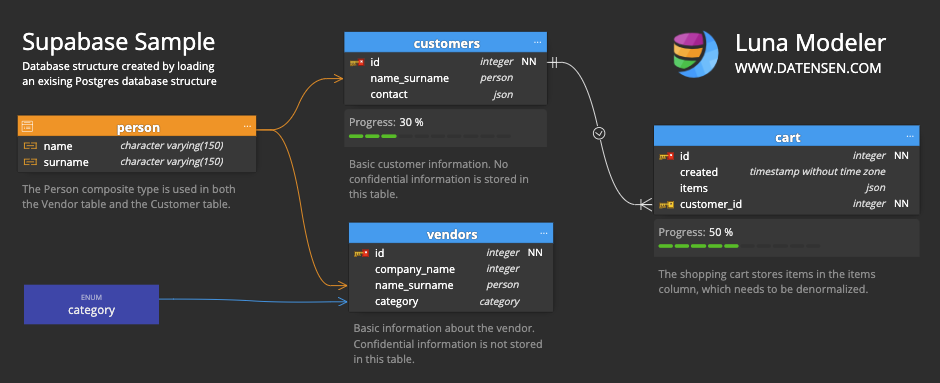
Supabase excels at rapid prototyping when your schema is straightforward. The dashboard let me visualize relationships, run migrations from the CLI, and set up RLS policies without leaving the browser for about six months of active development. The auto-generated API from the database schema is genuinely useful for internal tools and admin panels. It struggles when you need complex stored procedures that span multiple tables with heavy transactional logic. I hit this limit on a project that required batch updates across twelve tables within a single transaction. The generated API doesn't expose raw transaction control, and writing PL/pgSQL functions that interact cleanly with the real-time system requires careful handling. At that point, a direct database connection through a service account and a dedicated backend layer becomes faster than arguing with the abstraction. This usually happens around month eight or nine for most teams that started with the quick route.

Practical Checklist Before Going Live
Before I ship anything, I verify four things. The first is that every table with sensitive data has RLS enabled and a policy that returns nothing when the user is unauthenticated. The second is that I have at least one index per foreign key column. The third is that my migrations are ordered correctly by timestamp and can be applied in sequence without manual intervention. The fourth is that I have tested the schema with a realistic data sample, not empty tables. An empty schema lies to you about performance. I run a simple insert test using a Python script that loads ten thousand representative rows into each table, then run EXPLAIN ANALYZE on the queries my application actually executes. This takes about twenty minutes and catches ninety percent of the performance issues before deployment. Most of the problems show up as sequential scans where an index scan should be happening. If your project involves geographic data, spatial indexing with GIST is mandatory. Without it, every location query falls back to a full table scan regardless of how many rows you have. Enabling the postgis extension and adding a single GIST index on your geometry column is a two-minute change that prevents a painful rewrite later.
The schema you commit to in the first month will shadow every decision you make after that. Don't treat it as a placeholder. Write it like you intend to keep it for two years, even if you think you might pivot. You won't pivot as cleanly as you expect.