The basics nobody tells you the right way
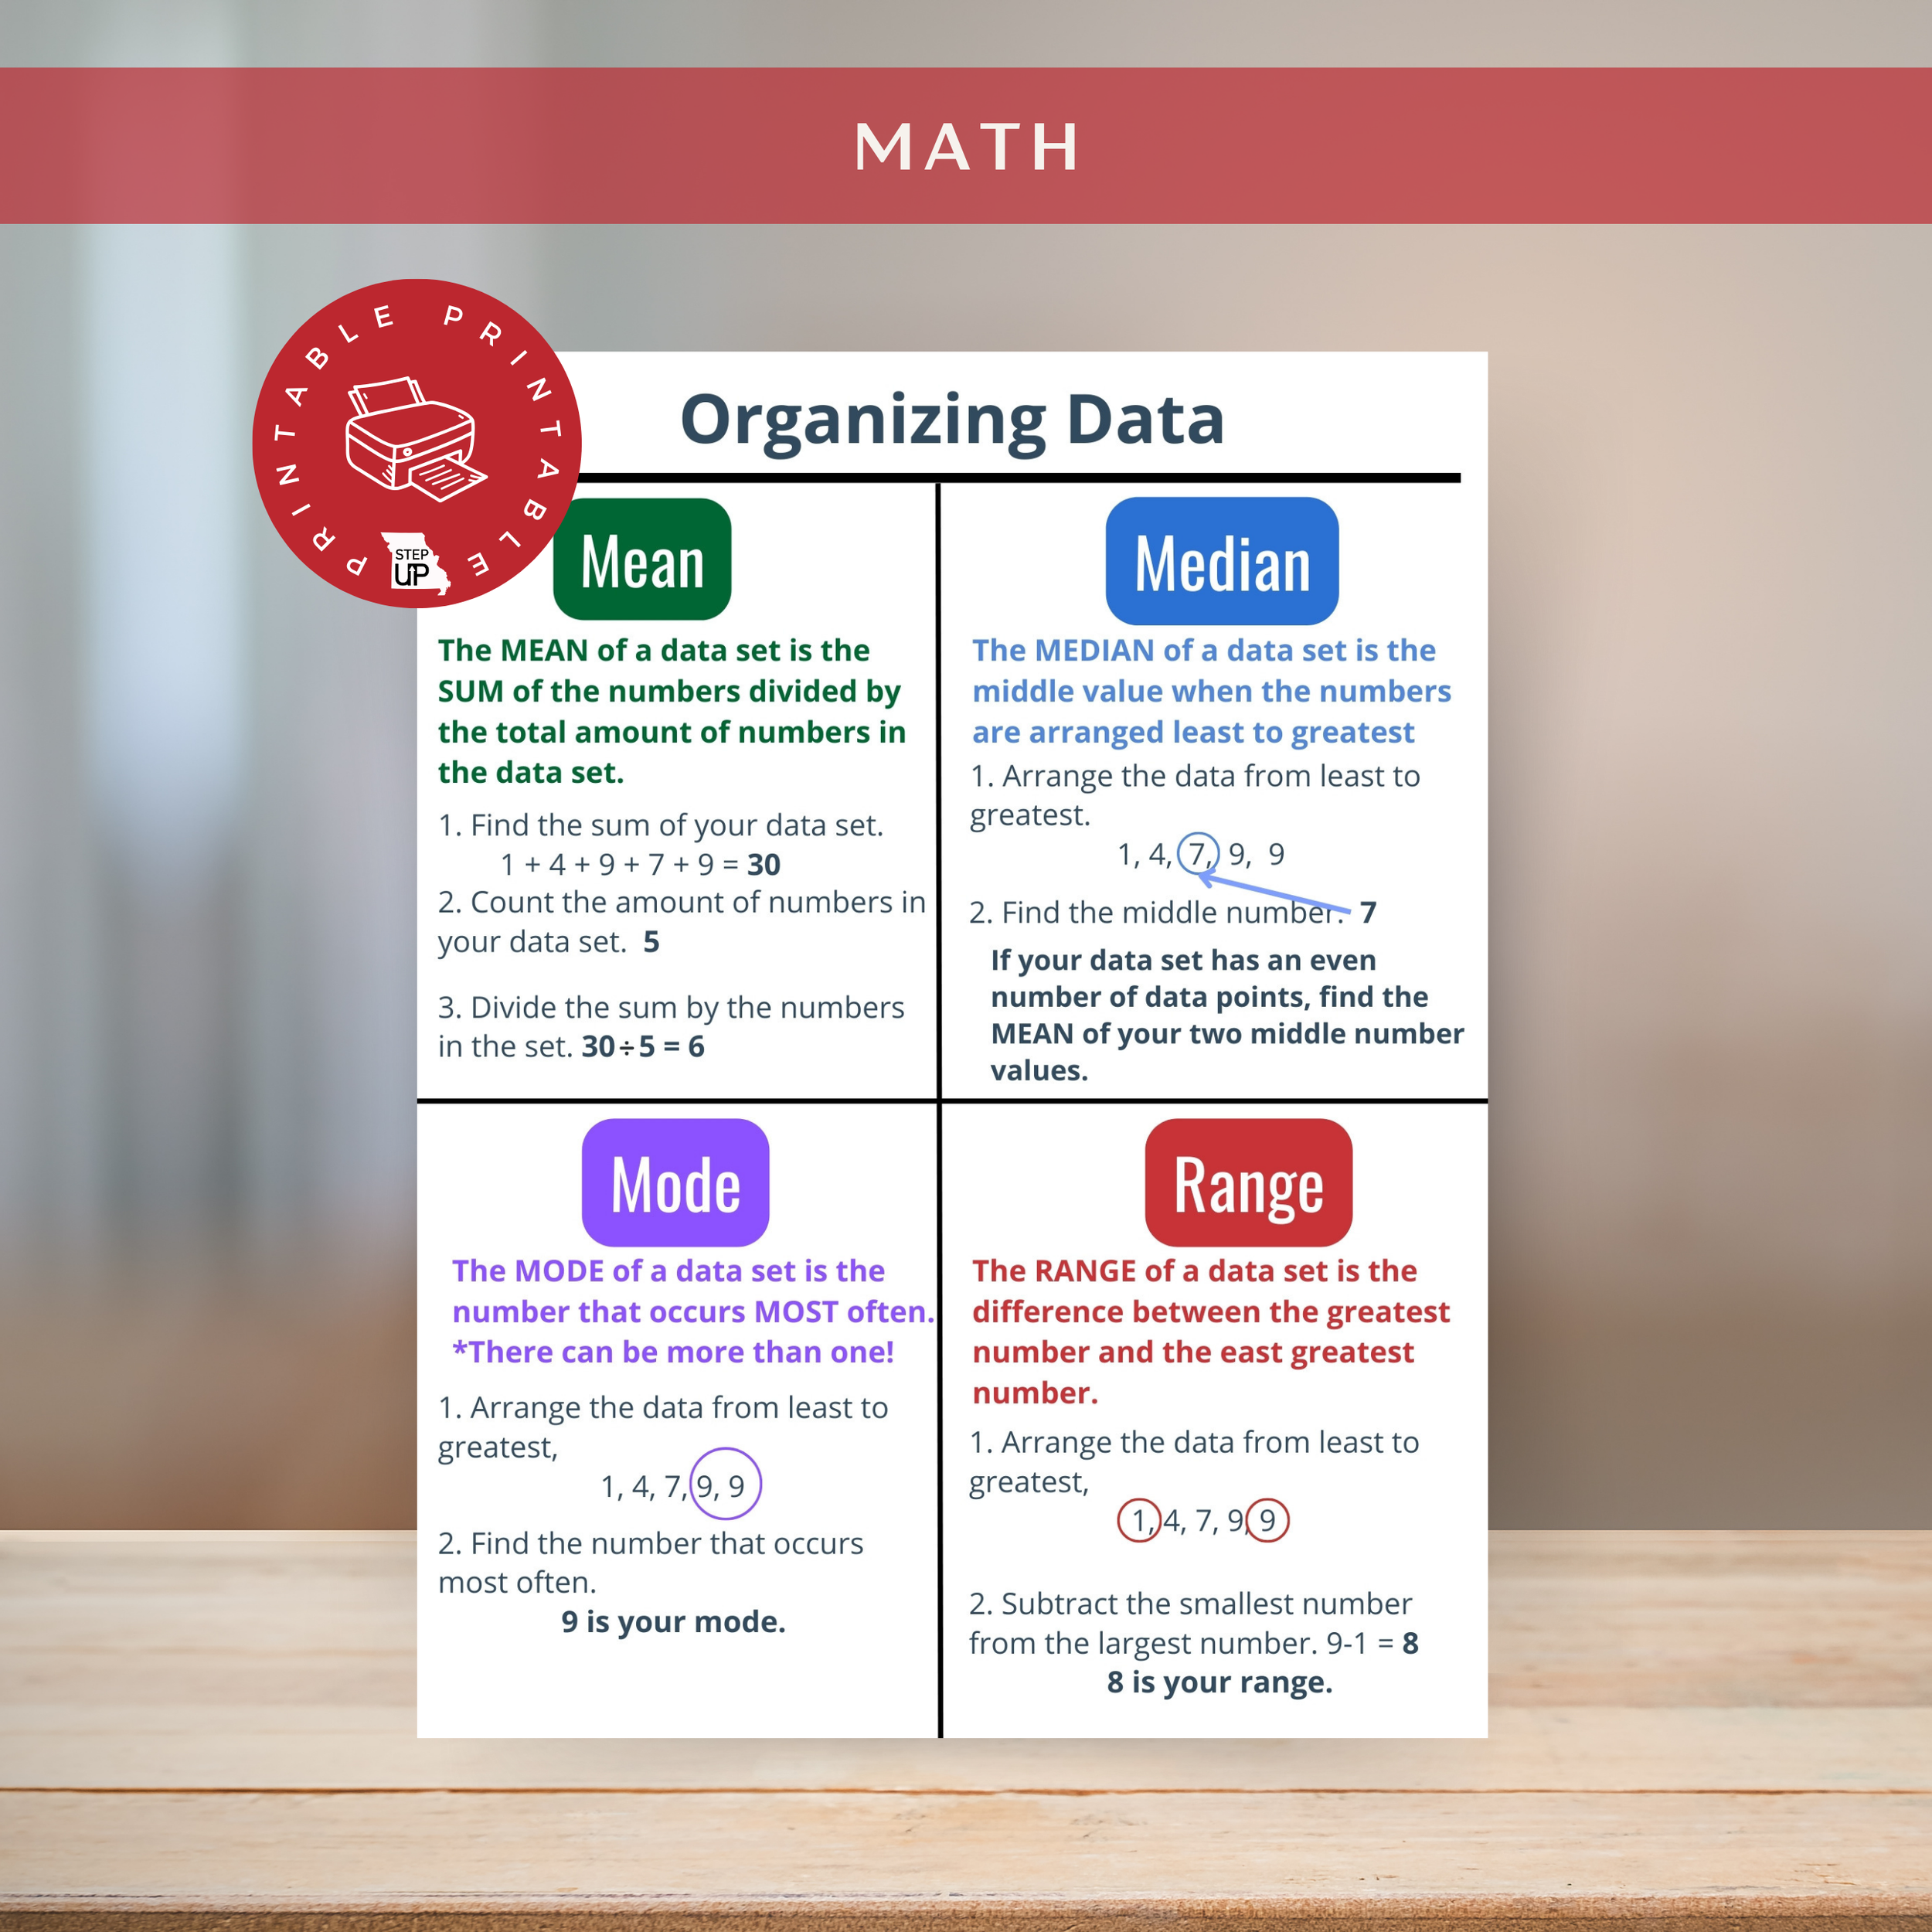
I ran into this exact problem last year when a marketing team handed me a dataset of customer spend values. The numbers looked normal at first glance, but the mean was pulling way above what anyone actually paid. I checked the distribution and found two billionaire customers who had skew the average by over 400 percent. The median was nowhere near the mean. That was my first reminder that these four measures are not interchangeable, even though every intro stats course treats them like they belong in the same toolbox. Mean is the arithmetic average. Add every value, divide by the count. Median is the middle value when the data is sorted. Mode is the most frequently occurring value. Range is the difference between the highest and lowest value. That is the textbook version. The practical version is that each one fails differently under pressure. I used to teach people to memorize the formulas. It does not help when your data has gaps, outliers, or is measured on an ordinal scale. Here is the order I actually use when I start a new dataset.
First, calculate the range. It takes about three seconds and immediately tells you the spread. If the range is tiny relative to the values, the data is tightly clustered. If the range is huge, something is going on. Second, find the median before you touch the mean. The median is far more resistant to skew. Third, compute the mode for categorical or discrete data. Fourth, compute the mean only after you have examined the mean-median relationship. When the mean is substantially higher than the median, the distribution is right-skewed. When it is lower, the distribution is left-skewed. That single comparison saves you from making decisions based on a misleading average. I saw this exact pattern in a logistics dataset where delivery times were recorded in minutes. The mean delivery time was 42 minutes. The median was 28 minutes. The range was 310 minutes. Two drivers had vehicle breakdowns that turned their trips into all-day events. The mean was basically useless for planning. The median gave a realistic target. The mode cluster sat at 26 minutes, which matched the normal flow of traffic for the busiest route. I reported the median and the interquartile range to the operations team, not the mean. They adjusted staffing based on that and reduced overtime costs by roughly 18 percent in the next quarter. Mode is not just for nominal data. People overlook it for numerical datasets because they think it is trivial. In a dataset of 1,200 product prices rounded to the nearest dollar, the mode was $19. That was the psychological price point that dominated inventory. The mean was $23.47, which told you nothing actionable. The mode revealed the concentration point. If you are working with continuous numerical data, bin the values first. Group them into ranges of appropriate width, then count frequencies. The mode of the binned data will be stable if your bin width is reasonable. I use bin widths equal to about one-fifth of the range as a starting point, then adjust based on histogram appearance.
Range has a serious blind spot that beginners ignore. It only uses the two extreme values and discards everything else. If your dataset is 2, 4, 5, 6, 100, the range is 98. That number sounds dramatic. It is also meaningless for describing the bulk of the data. I always pair range with the interquartile range. The IQR removes the top and bottom 25 percent and gives you the spread of the middle half. In the example above, the IQR is 2. That tells you the actual story. The range is noise. The IQR is signal. One edge case that costs people money is missing data handling. I had a payroll dataset where 3 percent of entries were blank. The mean calculation silently dropped those rows in most spreadsheet tools, which changes the denominator without warning. I caught it because the headcount in the summary did not match the employee list. The fix was explicit. I imputed missing values using the median, not the mean, because the salary distribution was right-skewed with executive comp dragging the average up. Using the mean to impute would have inflated every filled-in value and shifted the overall mean further upward. Median imputation kept the central tendency honest. Another counter-intuitive point is that the mean minimizes the sum of squared deviations. That is why it is sensitive to outliers. The median minimizes the sum of absolute deviations. That is why it is robust. If you need a single value to represent the dataset for loss calculations, pick the measure that matches your loss function. Squared loss means use the mean. Absolute loss means use the median. This is not theoretical. I redesigned a commission model around this exact principle. The old model rewarded reps based on mean sale price. A few high-ticket clients skewed the incentive structure. We switched to median sale price and saw the rep behavior normalize within two billing cycles.
Get the Full Details

When the data is bimodal or multimodal, the mean can sit in a valley between peaks where no observations actually exist. The median falls somewhere in between too. The mode reveals the true structure. I encountered this in an e-commerce dataset where purchases split cleanly into two groups: budget shoppers spending under $30 and premium shoppers spending over $150. The mean was $67, which was a number no real customer matched. The modes were $24 and $179. Reporting the mean would have led to poor inventory and pricing decisions. We segmented the customer base and built separate funnels for each mode cluster. If you need a practical workflow, start here. Load your data. Check for missing values and record the percentage. Compute range, median, mode, and mean. Compare mean and median. If the ratio of mean to median exceeds 1.2 or falls below 0.8, flag skew. Plot a histogram or a box plot. The box plot will show you whiskers and outliers immediately. Use the IQR to identify mild outliers at 1.5 times the IQR beyond the quartiles and extreme outliers at 3 times the IQR. Decide whether to keep, transform, or exclude outliers based on domain knowledge, not arbitrary thresholds. Document every decision. These measures are descriptive, not inferential. They summarize a sample. They do not tell you whether a difference is statistically significant. If you need to compare groups, run a proper test. The mean and median difference between two groups can look large in raw numbers and still be insignificant if the variance is high and the sample size is small. I have seen product teams make feature rollout decisions based entirely on mean differences without checking variance or sample size. That is how you ship broken features.
Range also fails as a standalone reliability metric for small samples. With five data points, the range is wildly unstable. Add one extreme value and it doubles. Use confidence intervals or standard error estimates when sample size is under 30. These give you a sense of precision that range never will. None of this requires fancy software. I routinely calculate all four measures in a spreadsheet in under two minutes for datasets up to 10,000 rows. The bottleneck is never the math. It is cleaning the data, handling missing values, and deciding what the numbers actually mean for the business question at hand. That part takes most of the time. The arithmetic is the easy bit.