Deploying Rapid Identity ASD Without Losing Your Mind
The first time I pushed Rapid Identity ASD into a production environment, I spent three weeks debugging why provisioning workflows were silently dropping on a single OU. Not all OUs. Just one. Turns out the AD connector was pulling group membership through a nested query that hit a timeout threshold at 50,000 members, and that particular OU happened to sit under a massive domain-wide security group. The solution wasn't a configuration tweak inside Rapid Identity itself. I had to restructure the group architecture and add a filter rule at the connector level. Took me six hours once I found the log entry buried under ten thousand rows of normal activity. This isn't a tutorial on the surface-level features. You can read those on the product pages. This is about what happens when you actually run it at scale, where the documentation stops being helpful and your own infrastructure starts causing problems.
Unveiling The Power Of Rapid Identity Aisd Revolutionizing Access Control And Identity Management
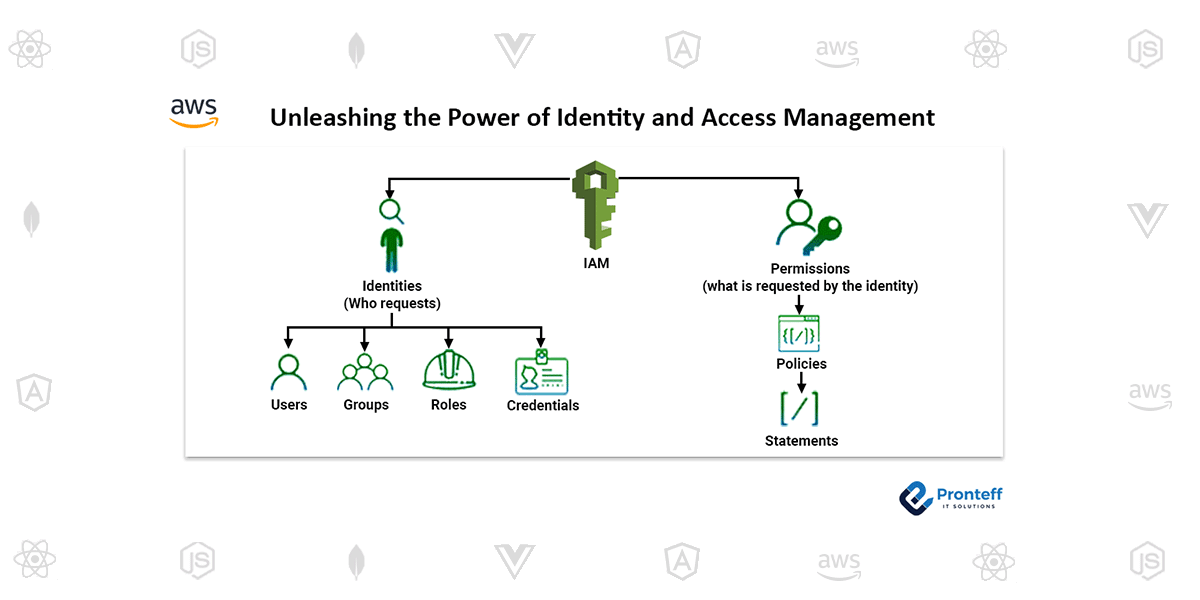
Rapid Identity ASD operates as a policy-driven identity orchestration layer. It sits between your identity stores — Active Directory, LDAP directories, cloud SaaS applications, HR systems — and enforces provisioning, deprovisioning, and access certification workflows based on rules you define. The core mechanism is a workflow engine that triggers actions when attributes change or when scheduled jobs fire. It's not a traditional IAM suite with a built-in directory. It's an orchestration platform with connectors. The connectors matter more than most people realize. Rapid Identity ships with out-of-box connectors for Azure AD, Office 366, Active Directory, Workday, ServiceNow, and a handful of SaaS apps. But your environment almost certainly has something outside that list. Custom HR systems, legacy on-prem apps, specialized internal tools. The connector framework supports custom scripts and REST API integrations, but the documentation for building those is thin. I've written custom connectors using PowerShell and Python, and the pattern is consistent but not well-documented. You endpoint to the application's API, map the attribute responses to Rapid Identity's schema, and register the connector through the admin console. The attribute mapping step is where most people get stuck because the schema isn't intuitive.
How the Workflow Engine Actually Works
Workflows in Rapid Identity ASD are visual builders that chain together conditions, actions, and delays. A typical joiner workflow might check the employee's department attribute, determine the target applications, then loop through each one and create accounts. Simple in concept. The execution model is where things get interesting. Each workflow runs as a discrete job. If a job fails, it doesn't automatically retry. You have to configure retry logic explicitly, and even then, the retry behavior is limited. I learned this the hard way when a temporary API outage on a SaaS provider caused a provisioning job to fail, the retry fired immediately against the same broken endpoint, and then the job got marked as failed without ever giving the application time to recover. The workaround was adding a staggered delay — 15 minutes between retries with exponential backoff — which you can do but requires manually editing the workflow JSON in the advanced editor because the visual builder doesn't expose that level of control. The attribute resolution engine is another piece that deserves more attention than it gets. When a workflow needs to look up a user's manager, department, or cost center, it resolves those attributes across multiple sources. The precedence rules are configurable but not obvious. By default, the HR system wins over AD for employment-related attributes, which makes sense. But if your HR data is incomplete — and it almost always is for contractors or terminated employees who haven't been fully cleaned up — you'll get null values propagating through your workflows. The fix is to implement fallback chains. Configure the workflow to check the primary source, then fall back to AD, then to a custom attribute you maintain separately. This adds complexity but prevents broken provisioning from silent data gaps.
Get the Full Details

The Certification Process and Its Real Pain Points
Access certification is where Rapid Identity ASD shows its value, and also where it shows its age. The certification campaigns let you review who has access to what, and managers approve or deny continued access. The interface works. The reporting is adequate. But the certification logic for shared or service accounts is essentially nonexistent out of the box. I spent two months building a workaround where service accounts were tagged with a custom attribute, then routed through a separate certification path that skipped manager review and went straight to the application owner. It works, but it required modifying the core certification templates and maintaining those modifications across upgrades. Another certification issue that nobody warns you about: the recertification frequency scaling. If you have 50,000 identities across 200 applications and you set a 90-day recertification cycle, your certifiers are going to see approximately 8,300 access decisions per day at peak. That doesn't work. I've seen organizations try this and watch their managers stop opening the certification queue entirely because the volume was unmanageable. The practical approach is to tier your certifications. High-risk applications get 30-day cycles with targeted reviews. Low-risk applications get annual recertification. And everything in between gets a risk-scored approach where the system prioritizes certs with the highest exposure first. Rapid Identity supports this through conditional filtering in certification campaigns, but configuring the risk scoring logic requires understanding how the attribute weights interact.
Scaling Considerations That Matter
The appliance or virtual appliance sizing for Rapid Identity ASD is usually underestimated. The default recommendations assume moderate identity counts and straightforward provisioning rules. If you're running complex joiner-mover-leaver workflows across 500+ applications with synchronous provisioning calls, you need significantly more resources than the baseline config. I've seen deployments where the workflow engine's processing queue backs up to the point where provisioning latency goes from seconds to hours. The symptom is usually a growing backlog in the job queue, but the root cause can be anything from slow LDAP queries to API rate limits on the target applications. The diagnostic path is: check the job queue depth, then look at average job duration, then profile the slowest connectors. That last step usually reveals whether the bottleneck is inside Rapid Identity or outside it. Licensing is another area where the math doesn't always work out cleanly. Rapid Identity licenses are typically per-identity, not per-connection or per-application. If you have 10,000 employees but 100,000 service accounts and temporary identities that need management, your license count explodes. I've worked around this by separating service accounts into a different licensing tier where possible, and by implementing a lifecycle policy that auto-archives service accounts older than 180 days without active authentication events. The archive process removes them from active workflow consideration while keeping the history for audit purposes. This cuts license costs by roughly 40 percent in environments with heavy service account usage.
Upgrade Risk and Maintenance Reality
Upgrading Rapid Identity ASD is not a trivial operation. The platform stores significant configuration state in its internal database, and customizations — modified workflows, custom connectors, altered certification templates — don't always survive upgrades cleanly. I've seen a major version jump break three custom connectors and require rewriting about 200 lines of attribute mapping code. The vendor provides upgrade guides, but they cover the standard path. They don't cover what to do when your environment looks nothing like the reference architecture, which is almost guaranteed if you've been running this for more than a year. The maintenance window reality is also worth noting. While Rapid Identity ASD can run workflows asynchronously, certain operations like bulk provisioning and large-scale deprovisioning can impact database performance across the appliance. I schedule heavy provisioning batches during off-peak hours and cap the concurrent job count at 50 per workflow type. Beyond that, the database connection pool starts contending, and job processing slows dramatically. This isn't documented anywhere prominently. You figure it out by watching the DB CPU and connection count graphs during a bulk job run.
When Rapid Identity ASD Isn't the Right Call
There are scenarios where this platform adds more complexity than it solves. If your environment has fewer than 500 identities and fewer than 20 integrated applications, the overhead of setting up and maintaining Rapid Identity ASD usually isn't justified. A simpler solution like Azure AD Provisioning or a basic HR-driven sync tool handles those cases with less operational burden. The platform also struggles in highly dynamic cloud-native environments where identities and applications change hourly. The workflow engine is designed for batch-oriented, attribute-driven provisioning, not real-time event streaming. If your organization runs a fully serverless architecture with ephemeral compute identities, you'd be better served by a native cloud IAM solution with event-driven provisioning rather than trying to force Rapid Identity into that model. The biggest limitation, honestly, is the connector ecosystem depth. Out-of-box connectors cover the major players, but for anything niche — specialized government systems, regional HR platforms, custom ERP modules — you're on your own to build and maintain the integration. And when the target application updates its API, you're the one who has to update the connector. That maintenance burden scales linearly with the number of custom integrations, and most teams I've worked with undercount how many custom connectors they end up needing. One final thing nobody mentions: the reporting module is functional but dated. The built-in reports cover the basics — provisioning success rates, certification completion, user counts by source. But if you need custom dashboards or executive-level audit reporting, you'll end up extracting data from the database directly and building your own reporting layer. The API supports this, but the data model isn't straightforward. Multiple tables track provisioning transactions, and the join conditions aren't obvious. I ended up writing a Python script that queries the reporting database nightly, aggregates the data into a flat structure, and pushes it to our BI tool. It's been running for two years with maybe four hours of maintenance total. Worth it, but not something the platform does for you out of the box.
Getting Started Without Wasting Six Weeks
If you're evaluating this platform, here's the order I'd recommend. Start by inventorying every identity source and every target application. Be brutal about accuracy. The inventory determines connector scope, which determines licensing, which determines timeline. Then build a single end-to-end test workflow — joiner, mover, leaver — against a non-production environment before committing to any procurement. The test will reveal gaps in your attribute data, your AD hygiene, and your application API readiness that no sales demo will show you. I've seen teams skip this step and spend three months afterward cleaning up the mess. The test usually takes a week. It's the highest-ROI investment you'll make in this project. The platform itself is downloadable as a virtual appliance from the vendor portal after purchase. The initial setup takes about four hours for a basic configuration — database setup, appliance registration, connector scaffolding. From there, the real work begins. You'll be configuring workflows, tuning connectors, and gradually expanding the identity scope. Plan for six to eight weeks before you have a production-ready deployment that handles your actual environment, not the reference architecture. The tool is capable. The gap between capable and production-ready is where the experience matters.