Mass notification infrastructure is a mess until you stop treating it like broadcasting
I spent four years managing a multi-campus incident communication setup before anyone admitted the problem wasn't the technology, it was the architecture. What we call NSS IMSS — the National Security Integrated Mass Notification System, though some vendors rebrand it depending on who writes the RFP — is less of a single tool and more of a wiring diagram that tells five different subsystems how to talk to each other when the clock starts ticking. The short version: it replaces a stack of standalone alert platforms with a single orchestration layer. Long version: you learn that quickly because you watch the old system fail during a drill, then replace it piece by piece. Here's what that looks like in practice.
Unveiling The Power Of Nss Imss Revolutionizing Mass Notification Systems
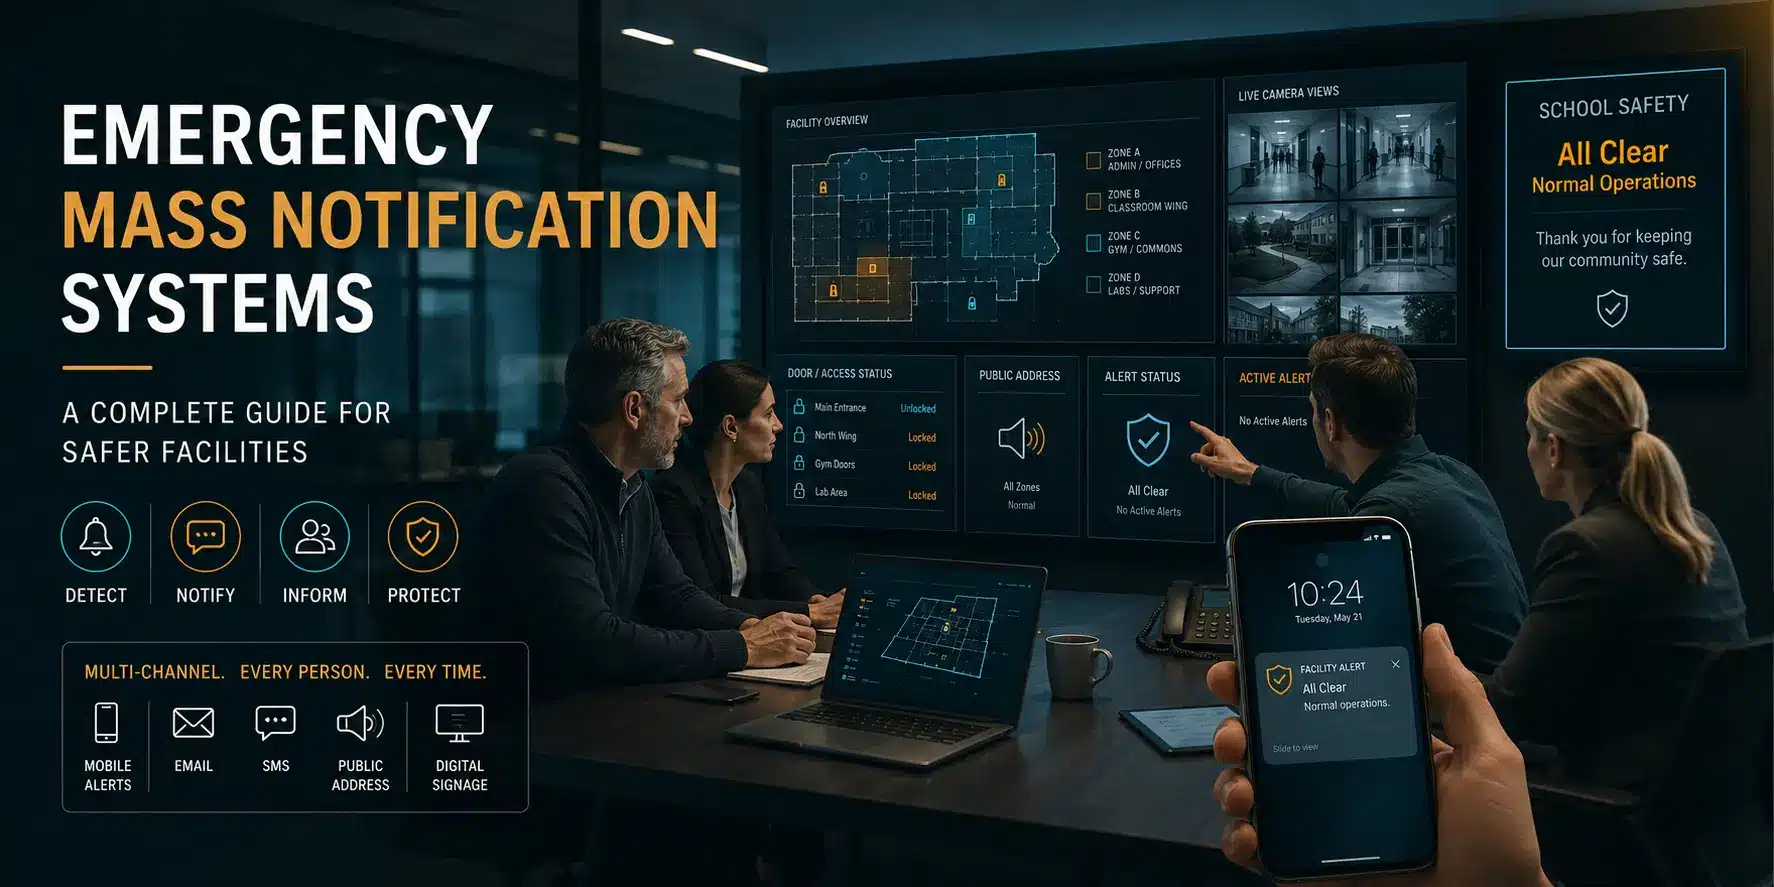
NSS IMSS isn't one piece of software you download and install. It's a framework. You're looking at three main components that always show up together: the notification engine (the thing that pushes messages out), the subscriber directory (the thing that knows who should get what), and the decision interface (the thing operators use when something actually happens). These can come from one vendor or three different ones. Your job is making sure they actually sync. The engine handles outbound channels — SMS, voice calls, emails, desktop popups, SIREN integration, PA/LA announcements, mobile push, and in some setups, social media triggers. The directory is where people live. Not just names and numbers, but roles, locations, shift schedules, accessibility flags, device preferences, and exclusion lists. The decision interface is the console. It's supposed to be simple under stress. Most aren't. When these three components operate independently, you get drift. I've seen directories that hadn't been reconciled against HR feeds for eight months. I've seen engines queuing alerts for people who'd retired two years earlier. NSS IMSS-style platforms try to close that gap through real-time sync connectors and automated validation loops. They work well enough until the connector breaks and nobody notices until an actual event fires.
There's a specific reason people are moving toward this model. Legacy mass notification setups were siloed. One platform for fire alarms. Another for IT outages. A third for security incidents. A fourth for weather. Each had its own contact list. Each required separate operator training. During a compound event — a seismic event that triggers both structural evacuation and hazmat lockdown — you ended up running parallel broadcasts from different consoles with different audience segments, and the overlap was chaotic. NSS IMSS centralizes audience routing and message templating so one operator can push a coordinated multi-channel alert without switching interfaces. That coordination is where the actual power lives. It's not the alert itself. It's the reduction of cognitive load during the first three minutes of an incident.
Get the Full Details

How the system actually works under the hood
Let me walk through the data flow because this is where most implementations go wrong. When an alert is authored, it passes through a recipient resolution engine. That engine queries the directory, applies rules based on incident type and location, checks exclusion lists, factors in device capability, and produces a final target list. Only then does the engine fan out to channels. The order matters. If your directory lookup is slow, your time-to-first-ping increases. If your rules engine has overlapping conditions without priority ordering, people get duplicate alerts and tune them out. I once configured a rules engine where a building-wide lockdown and a floor-level shelter-in-place triggered simultaneously for the same person. They received four messages in twelve seconds across three channels. Every subsequent drill, that person disabled auto-accept on their phone. That's an operational failure caused by a logic bug, not a technology failure. The fix was straightforward: deduplication windows at the subscriber level and a minimum interval threshold between sends to the same endpoint. Both are configurable in NSS IMSS platforms but neither is enabled by default. Channel performance is another area where theory and reality diverge. SMS deliverability depends on your aggregator relationships and message content filtering. Voice call success depends on cell coverage in blind spots on your campus. Email gets caught in spam filters unless you have proper SPF, DKIM, and DMARC records pointing to your notification domain. Desktop and push notifications require pre-installed agents that employees often ignore or remove. An effective NSS IMSS deployment treats every channel as unreliable and designs around that assumption. Redundancy isn't optional. It's the baseline configuration.
Configuration realities you won't read in a datasheet
Directory management is 60 percent of the work. Not the alerting. The people side. You need a process for onboarding, role assignment, contact verification, and offboarding that runs on schedule, not reactively. The best NSS IMSS platform in the world sends alerts to ghosts if your directory contains former employees, incorrect phone numbers, or stale location data. Integration with physical security systems is where most budgets get consumed. You'll need connectors for access control, video management, fire alarm panels, HVAC shutoff, elevator recall, and electronic sign boards. Some come as native integrations. Others require custom API work. I've written custom connectors for legacy fire panels that only communicated via serial output. That took three weeks and cost more than the notification license itself. Budget for that contingency. Testing cadence matters more than most organizations realize. NSS IMSS platforms support different test types: simulated (no actual alerts sent), broadcast tests (live channel pings to a restricted group), and full-scale drills (organization-wide, usually scheduled). The problem is that simulated tests don't catch delivery failures because they bypass the engine. I started running monthly unannounced broadcast tests to a rotating group of twenty-five volunteers across all channels. Within six months, we discovered three dormant email addresses, two disconnected landlines, and a push notification agent that had stopped receiving tokens after a corporate MDM policy change. None of that would have shown up in a simulated test.
Operator training is the bottleneck nobody plans for. NSS IMSS interfaces assume a certain fluency with decision trees, escalation paths, and message approval workflows. A new operator taking over a night shift should be able to push a Level 1 alert within ninety seconds without guidance. Achieving that requires deliberate practice, not reading the manual. I structured training around scenario cards: specific incident types with increasingly complex constraints. First drill, they had full documentation. By the fifth drill, documentation was removed. By the tenth, they were running dual-channel alerts while processing a secondary incoming event. The ones who made it to that level became your permanent alert operators. The ones who didn't got reassigned or retrained.

When NSS IMSS doesn't solve the problem
It doesn't replace crisis communication strategy. A better notification system still delivers bad messaging faster. If your templates are vague, your escalation authority is unclear, or your post-incident analysis process doesn't exist, NSS IMSS amplifies those failures rather than hiding them. The system is a force multiplier, not a substitute for operational discipline. It also doesn't handle regulatory compliance automatically. Depending on your jurisdiction and industry, you may need audit trails, message retention, acknowledgment tracking, or reporting to specific government bodies. NSS IMSS platforms can generate these records, but configuring them correctly requires someone who understands the actual regulatory requirements, not just the software settings. I've seen two organizations in the same sector implement identical platforms with completely different compliance configurations because their legal teams interpreted the requirements differently. Vendor lock-in is a real constraint. Once your directory, templates, rules engine configurations, and integrations are built around a specific NSS IMSS platform, migration costs are significant. Data export is usually possible but not always clean. Custom connectors may not have equivalents in other systems. I recommend building a minimal abstraction layer between your core directories and the notification engine wherever possible. It adds complexity upfront and saves weeks of work if you ever need to switch.
If you're operating at a scale where NSS IMSS feels like over-engineering — small campuses, limited IT staff, infrequent incident types — a well-configured standalone mass notification tool with a solid directory process may deliver eighty percent of the capability at thirty percent of the cost. NSS IMSS architectures shine when you have compound event scenarios, multiple stakeholder groups, and existing physical security integrations that need central coordination. They don't shine when you're sending weather delay announcements and occasional security walk-throughs. The technology exists. The gap is always in the operational maturity surrounding it.