Why Japanese names are harder to work with than they look
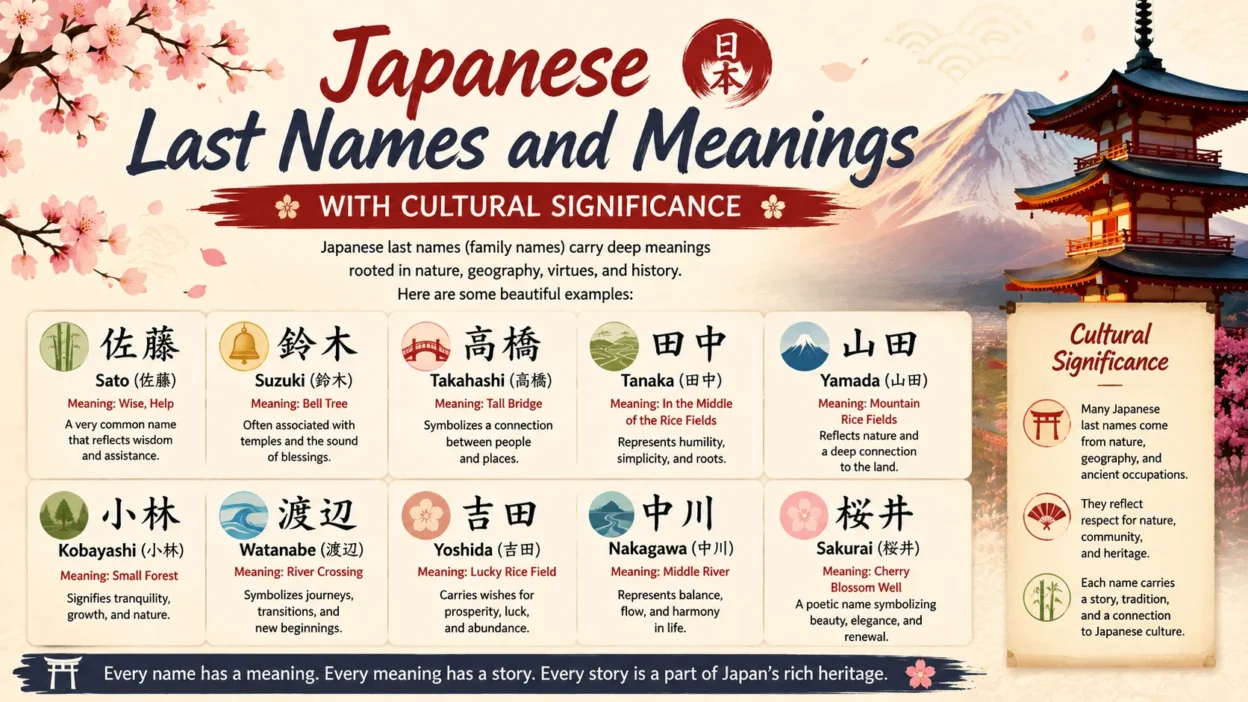
Japanese names follow a system that seems straightforward on the surface but breaks down fast once you try to apply it in practice. Family names come first, then given names. That alone isn't the problem. The problem is that kanji choices carry meaning, that readings vary by context, and that romanization schemes don't map cleanly to anything consistent. I spent three months dealing with a client who needed to process historical records spanning the Edo period into the Showa era. They handed me a spreadsheet with roughly fourteen hundred name entries and told me to standardize everything. It took longer than expected. The biggest issue wasn't the kanji-to-romaji conversion. It was inconsistencies in how people had recorded names across different time periods, regional dialects, and occasional deliberate name changes that had no paper trail. I ended up building a reference table cross-referencing common family name variants with their documented historical readings. Without that, you're just guessing, and guessing gets you wrong results repeatedly.
Unveiling The Mystique Of Japanese Names That A Dive Into The Cultural Significance
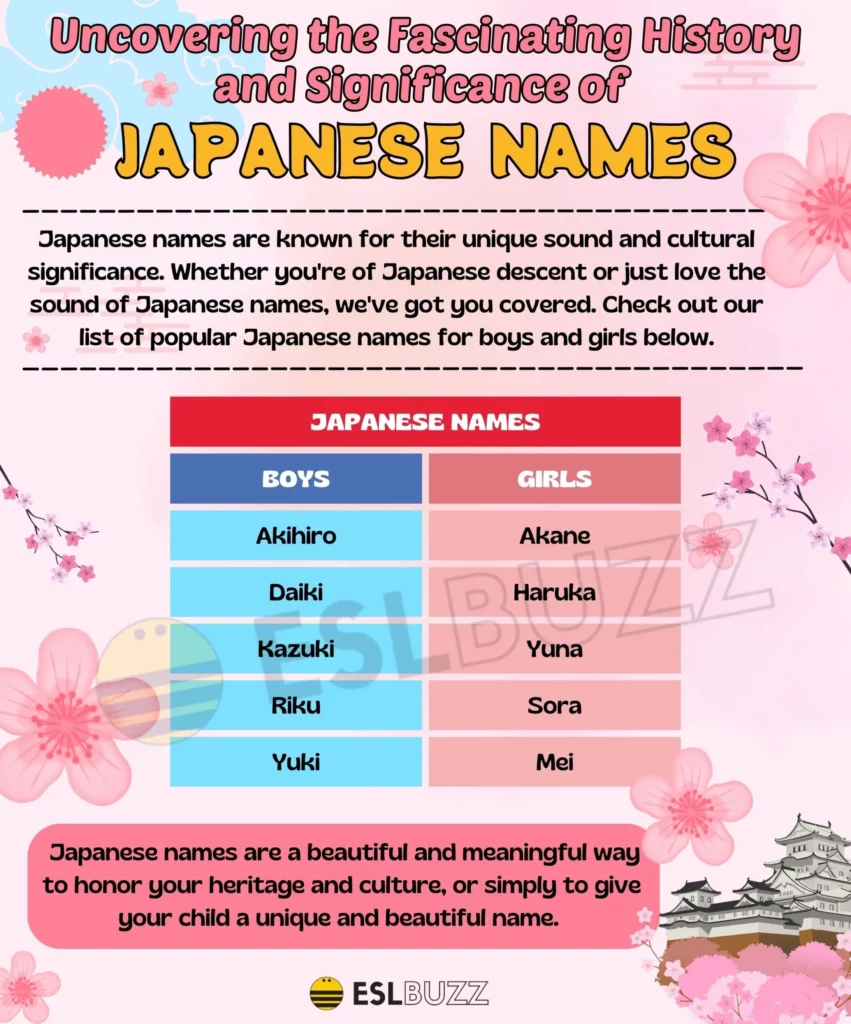
The cultural layer matters more than most people realize when they start working with Japanese names. A name isn't just a label. It carries generational expectations, reading choices that parents make based on fortune-telling traditions called onmyodo, and sometimes deliberate ambiguity in how a name is written so it can be read multiple ways. When you strip away the cultural context, you miss half of what the name actually is. Take the name Takeshi. You'll see it written with kanji like (warrior), (tall), or (healthy). Each version carries a different meaning the parents intended. A database that only stores the romaji version has lost information. The kanji is the real name. Romaji is just a phonetic shadow. Here is the part beginners always get wrong. Japanese names don't have a fixed number of characters. Some family names are single kanji. Others are five or six. Given names follow the same pattern. There is no rule. You will encounter (one-character given names) and (four-character given names) in the same household. If you're building a validation rule that limits names to a certain length, it will fail.
How readings actually work in practice
Kanji have multiple readings. On-yomi comes from Chinese pronunciation during the Nara and Heian periods. Kun-yomi is the native Japanese reading. A single kanji can have anywhere from two to over ten valid readings. The name can be read as Shou, Sho, Kakeru, or Tou depending on context and family preference. You cannot determine the correct reading by looking at the kanji alone. I ran into this exact problem when a colleague asked me to verify a set of employee records. The kanji for one person's name was . Most systems would romanize that as Daisuke. The person in question was actually read as Naosuke in their household. There was no note explaining the deviation. I had to call the person directly to confirm. That conversation took about forty minutes including the small talk that is unavoidable in Japanese business communication. There is a system called kunyomi and onyomi that you need to understand before you start auto-generating romanizations. But even experts get tripped up because names often use ateji — kanji chosen for sound rather than meaning. The kanji might say one thing while the reading says another entirely. Your conversion tool will give you the standard reading. The actual name might be completely different.
Get the Full Details

What you need to know before processing names at scale
If you're building a system that handles Japanese names, here is what I learned the hard way. First, never assume furigana or reading guides are available. Most databases don't include them. Second, account for name changes after marriage. Japanese law allows a wife to take her husband's surname, but it doesn't require it in all cases, and the reverse happens too. Third, honor names like myouji and sei are not interchangeable in formal contexts. Myouji refers to the family name cluster. Sei refers to the specific kanji characters. Using them wrong in a legal document is a real problem. There is also the issue of ryakuji — abbreviated kanji forms that appear in older documents and handwriting. A simplified form might look completely different from the standard kyouiku kanji version. OCR systems struggle with these. I had a project where about eighteen percent of scanned documents contained ryakuji variants that standard lookup tables couldn't resolve. I ended up manually cross-referencing with regional government archives for those entries.
Where this approach falls apart
No system handles Japanese names perfectly. Automated converters will give you plausible readings that are still wrong roughly ten to fifteen percent of the time on real-world data. Name validation rules based on character count will reject legitimate names. Systems that only store romaji lose meaning and create ambiguity. If you need one hundred percent accuracy for legal or official purposes, you need a human review step. There is no software workaround for that. The most reliable approach I've found combines automated initial processing with a manual verification tier for ambiguous entries. You run the kanji through a standard converter first, flag any names with multiple possible readings, and send those to a human reviewer who has access to the original documents or can contact the relevant parties. It adds about two hours of work per thousand entries, but it catches the errors that would otherwise sit in your database indefinitely. For casual use — ordering things online, filling out basic forms, general research — a standard romaji converter is fine. You'll get the right answer most of the time. Just don't rely on it for anything where accuracy actually matters.