A Practical Guide to Working With Social Stratification
Unveiling The Hierarchy Understanding The Complex World Of Social Stratification
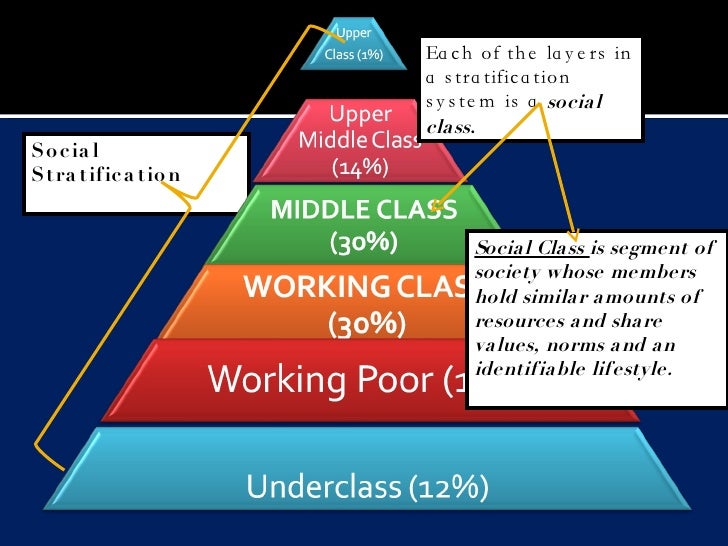
Most people encounter stratification through news cycles or policy debates. The reality is messier than any single category can capture. I spent years building survey instruments and regression models to map these patterns, and the main takeaway is that the frameworks most people rely on break down at the edges. That is the point where actual analysis begins. Start with the basics, but move through them quickly. Social stratification refers to the structured ranking of individuals and groups across dimensions like income, education, occupational status, and social capital. It is not simply inequality. Inequality is a distribution. Stratification is the system that assigns meaning and consequence to that distribution over time. The three dominant traditions in this field are Marxist class analysis, Weberian multidimensional stratification, and Bourdieu's forms of capital. They overlap, and they also contradict each other. A researcher who treats any single tradition as complete will make mistakes. The workaround I ended up using after two years of frustration was to build a hybrid coding scheme. I treated economic capital as the baseline layer, education as the credentialing layer, and social networks as the enforcement layer. That produced cleaner results than any pure model.
Setting Up Your Analytical Framework
Before running any analysis, you need to define your units and your measures. Pick one. Then pick another, and reconcile them. For economic measurement, most people reach for household income or individual earnings. These are useful but incomplete. Property wealth, debt loads, inheritance trajectories, and informal income streams often matter more for long-term stratification than annual income. In one project I worked on, two neighborhoods had nearly identical median incomes but vastly different patterns of wealth retention across generations. Income data alone would have missed that entirely. The fix was adding asset and liability data from local tax records, which took an extra three weeks of data cleaning but changed the conclusions completely. For education, years of schooling is the lazy measure. Field of study, institution type, and credential recognition across borders produce very different stratification effects. A degree from a vocational college and a degree from a selective university may represent the same number of years but function differently in the labor market. Cross-reference both.
For occupational status, the standard approach uses standardized scales like the International Standard Classification of Occupations or Treiman's subjective scoring. These work well for broad comparisons. They fail when you need to understand informal economies, gig work, or care labor, none of which map cleanly onto occupational categories. I stopped using occupational scales as primary variables and started using them alongside network position data. That combination captured far more variance.
Get the Full Details
Common Pitfalls That Wreck Analysis
The first pitfall is ecological inference. Aggregating data to the neighborhood or county level and then drawing conclusions about individuals produces systematic errors. This is called the ecological fallacy, and it is extremely common in stratification research. If a district has a high concentration of professionals, that does not mean professionals live there in stable patterns. It could mean a small elite cluster distorting the average. Always work at the individual level when possible, or use multilevel modeling if you must aggregate. The second pitfall is treating mobility as linear. Social mobility is not a straight line from low to high or high to low. It is recursive. People move up, fall back, plateau, and sometimes move across dimensions rather than within a single hierarchy. Someone might gain income while losing social capital, or gain education while remaining trapped in a low-status occupational track. Tracking multiple dimensions simultaneously is essential, and most quick analyses skip this step. The third pitfall is ignoring historical path dependence. Current stratification patterns are the product of decades of policy decisions, zoning laws, school funding mechanisms, and institutional practices. A snapshot analysis will attribute patterns to individual characteristics when the real driver is structural. I learned this the hard way when my initial model attributed a neighborhood's economic stagnation to resident education levels. After adding historical redlining maps and school funding timelines as controls, the education variable dropped to near zero. The real explanation was policy history.
Tools and Techniques That Actually Work
Descriptive statistics should come first. Build contingency tables, cross-tabulate your key variables, and look for non-linear relationships before running any regression. Most stratification effects are not linear. Income and health outcomes, for example, show sharp drops below certain thresholds that linear models smooth over completely. For multivariate analysis, ordered logit and probit models are standard for ordinal outcomes like education level or occupational prestige. Fixed effects models help control for unobserved heterogeneity when you have panel data. Propensity score matching works reasonably well for causal claims about specific interventions, but the quality depends entirely on having good pre-treatment covariates. Qualitative work should not be an afterthought. Stratification operates through institutional routines, cultural practices, and everyday interactions that numbers miss. Adding semi-structured interviews or ethnographic observation to a quantitative study usually reveals mechanisms that the regression coefficients cannot show. Budget at least fifteen percent of your time for this. It changes the interpretation of everything else.
Where This Approach Fails
The hybrid framework I described does not solve every problem. It struggles with populations that exist outside formal institutions, including undocumented workers, homeless populations, and people engaged in fully informal economies. Data availability is the bottleneck, not the method. In those cases, purposive sampling and targeted snowball recruitment produce better results than random surveys, though they sacrifice generalizability. Another limitation is that stratification models tend to underweight gender and racial dynamics when those factors interact with class in non-additive ways. A Black woman and a White woman in the same income bracket do not experience the same stratification position. An intersectional adjustment, even a simple one, is necessary to avoid erasing these differences. The biggest honest limitation is that no model captures the full complexity of social hierarchy. Any framework you build will simplify. The goal is not perfect representation. It is choosing the simplifications that matter most for your specific question and being clear about what you left out.

If you are starting a new project, begin with a clear research question, choose your measures deliberately, validate your instruments against known data sources, and plan for the complications before they appear in your results. The people who skip that step usually discover them too late.