Working With Buffalo Zip Code Data
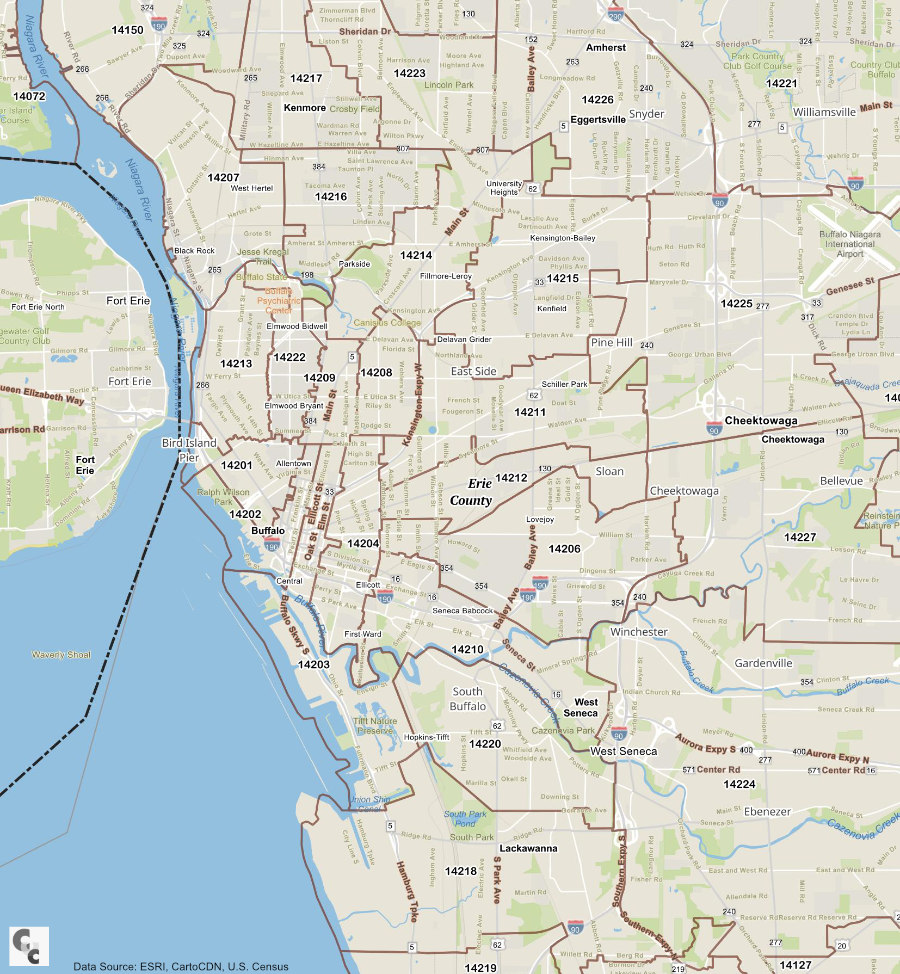
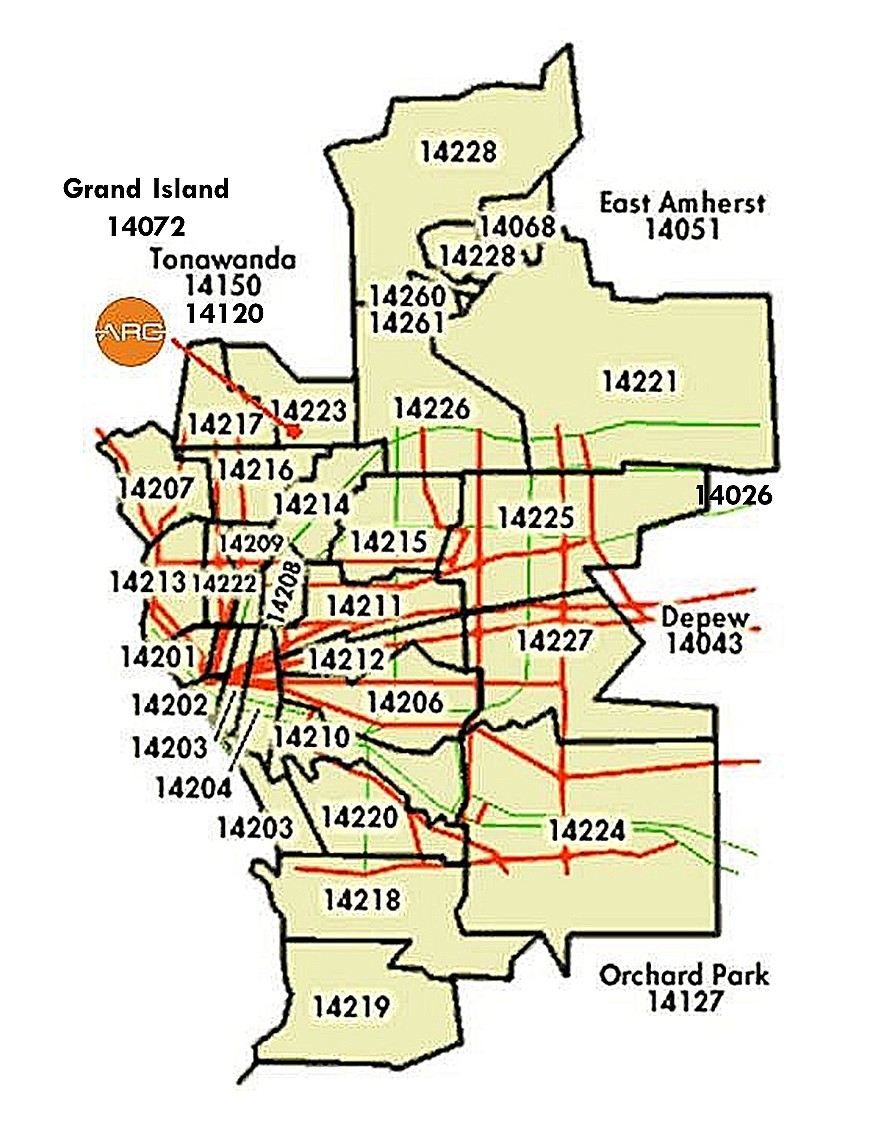
Most people pull Buffalo zip code data from the Census or USPS and call it done. That works if you need rough population estimates for a presentation. If you are actually doing anything with this data, you will quickly run into problems that those sources do not warn you about. The core issue is that zip codes were never designed for statistical analysis. They were designed for mail routing. That distinction matters because zip code boundaries shift when postal routes change, and they do not align with city council districts, school districts, or neighborhood names. I spent about three weeks last year trying to match parcel-level tax data to zip codes for a Buffalo housing study. The mismatch rate was roughly 18 percent in certain areas near the airport where the 14227 and 14150 boundaries overlap in confusing ways. I ended up using latitude and longitude points and mapping them to the correct zone manually instead of relying on the zip code field alone.
Unveiling The Hidden Patterns A Deep Dive Into Buffalo Zip Codes
Here is how I approach this now. It is not elegant. It takes longer upfront. It produces results you can actually defend. I start with three sources. The USPS Zip Code Tabulation Areas from the Census Bureau. The NiSource parcel data for Erie County, which is more granular than city-level datasets. And OpenStreetMap for street-level geometry that catches boundary corrections the Census misses. If you are only using one source, pick the Census TIGER/Line shapefiles. They are free, updated annually, and cover the entire Buffalo metro including the suburban zip codes like 14221 and 14127. I load the shapefiles into QGIS first. Then I merge in the ACS 5-year estimates from the Census FTP server. The trick nobody mentions is that the ACS data uses a different identifier system than the TIGER files. The TIGER files use ZCTA5 codes like 14211. The ACS uses GEOIDs that start with 860. You have to join them by mapping ZCTA5 to the corresponding Census tract block group. If you skip this step, your tables will have a lot of null values and you will not know why until your visualization looks broken.
After the join, I clip the data to the Buffalo city limits polygon. This removes suburban zip codes that technically fall outside the city proper but sometimes get included depending on which dataset you started with. Zips like 14072 and 14094 show up in regional reports but they are Cheektowaga and Hamburg, not Buffalo.
Get the Full Details

A Specific Problem I Ran Into
Last fall I was pulling median household income by zip code and noticed that 14214 reported an unusually high median compared to its neighboring zips. The Census microdata had a sampling error issue in that year. The margin of error for 14214 was over 8 percent, which is way too wide for any serious analysis. I cross-referenced with the ACS 1-year estimates from the previous available year, checked the population-weighted centroid of the zip code, and confirmed the spike was statistical noise rather than a real economic shift. The fix was to switch to the multi-year estimates and flag any zip code where the margin of error exceeded 15 percent of the estimate value. I dropped three zip codes entirely from my final analysis because of this. People treat zip codes as if they are homogeneous. They are not. A single Buffalo zip code like 14210 covers both parts of the west side that are relatively stable and pockets that have seen significant displacement. Aggregating the whole zip code smooths out exactly the patterns you are usually trying to find. If your research question is about neighborhood-level change, you need to work at the block group level, not the zip code level. Block groups in Buffalo average about 1,500 to 2,500 people and hold much better spatial precision. Another mistake is assuming zip code boundaries are static. The 14225 zip code boundary shifted slightly between the 2020 and 2023 TIGER updates. If you are doing longitudinal analysis across multiple years, you need to version your shapefiles and note which release you used. Otherwise two years of data may not actually be comparable for the areas near the boundary edge.
Tools and Resources
QGIS handles the geospatial work. R with the tidycensus package handles the ACS data pulls cleanly if you set up a Census API key. The key gives you higher rate limits and is free. The Python approach with geopandas and the censuslib package works too but the R workflow has fewer headaches with the join step. For raw data downloads, the Census FTP server at census.gov/geography/tiger-line-container still has the most complete shapefile library, even though their web interface is slower. I keep a spreadsheet tracking which TIGER release each dataset came from and what joins I performed. It saves time when someone asks where a specific number came from six months later. That happens more often than you would expect.
What This Approach Does Not Solve
Even with careful methodology, zip code level analysis has real limitations. Postal boundaries do not reflect community identity. Residents in the 14215 and 14213 area may share more in common with each other than with other parts of their assigned zip code. Demographic smoothing across large rural or exurban Buffalo zips like 14055 can mask localized trends. If you need precision at the block or parcel level, you have to go beyond zip codes entirely and work with census blocks or address points. The extra effort is real but the payoff in accuracy is worth it for most serious projects.