London Postcode Data Analysis: A Practical Guide
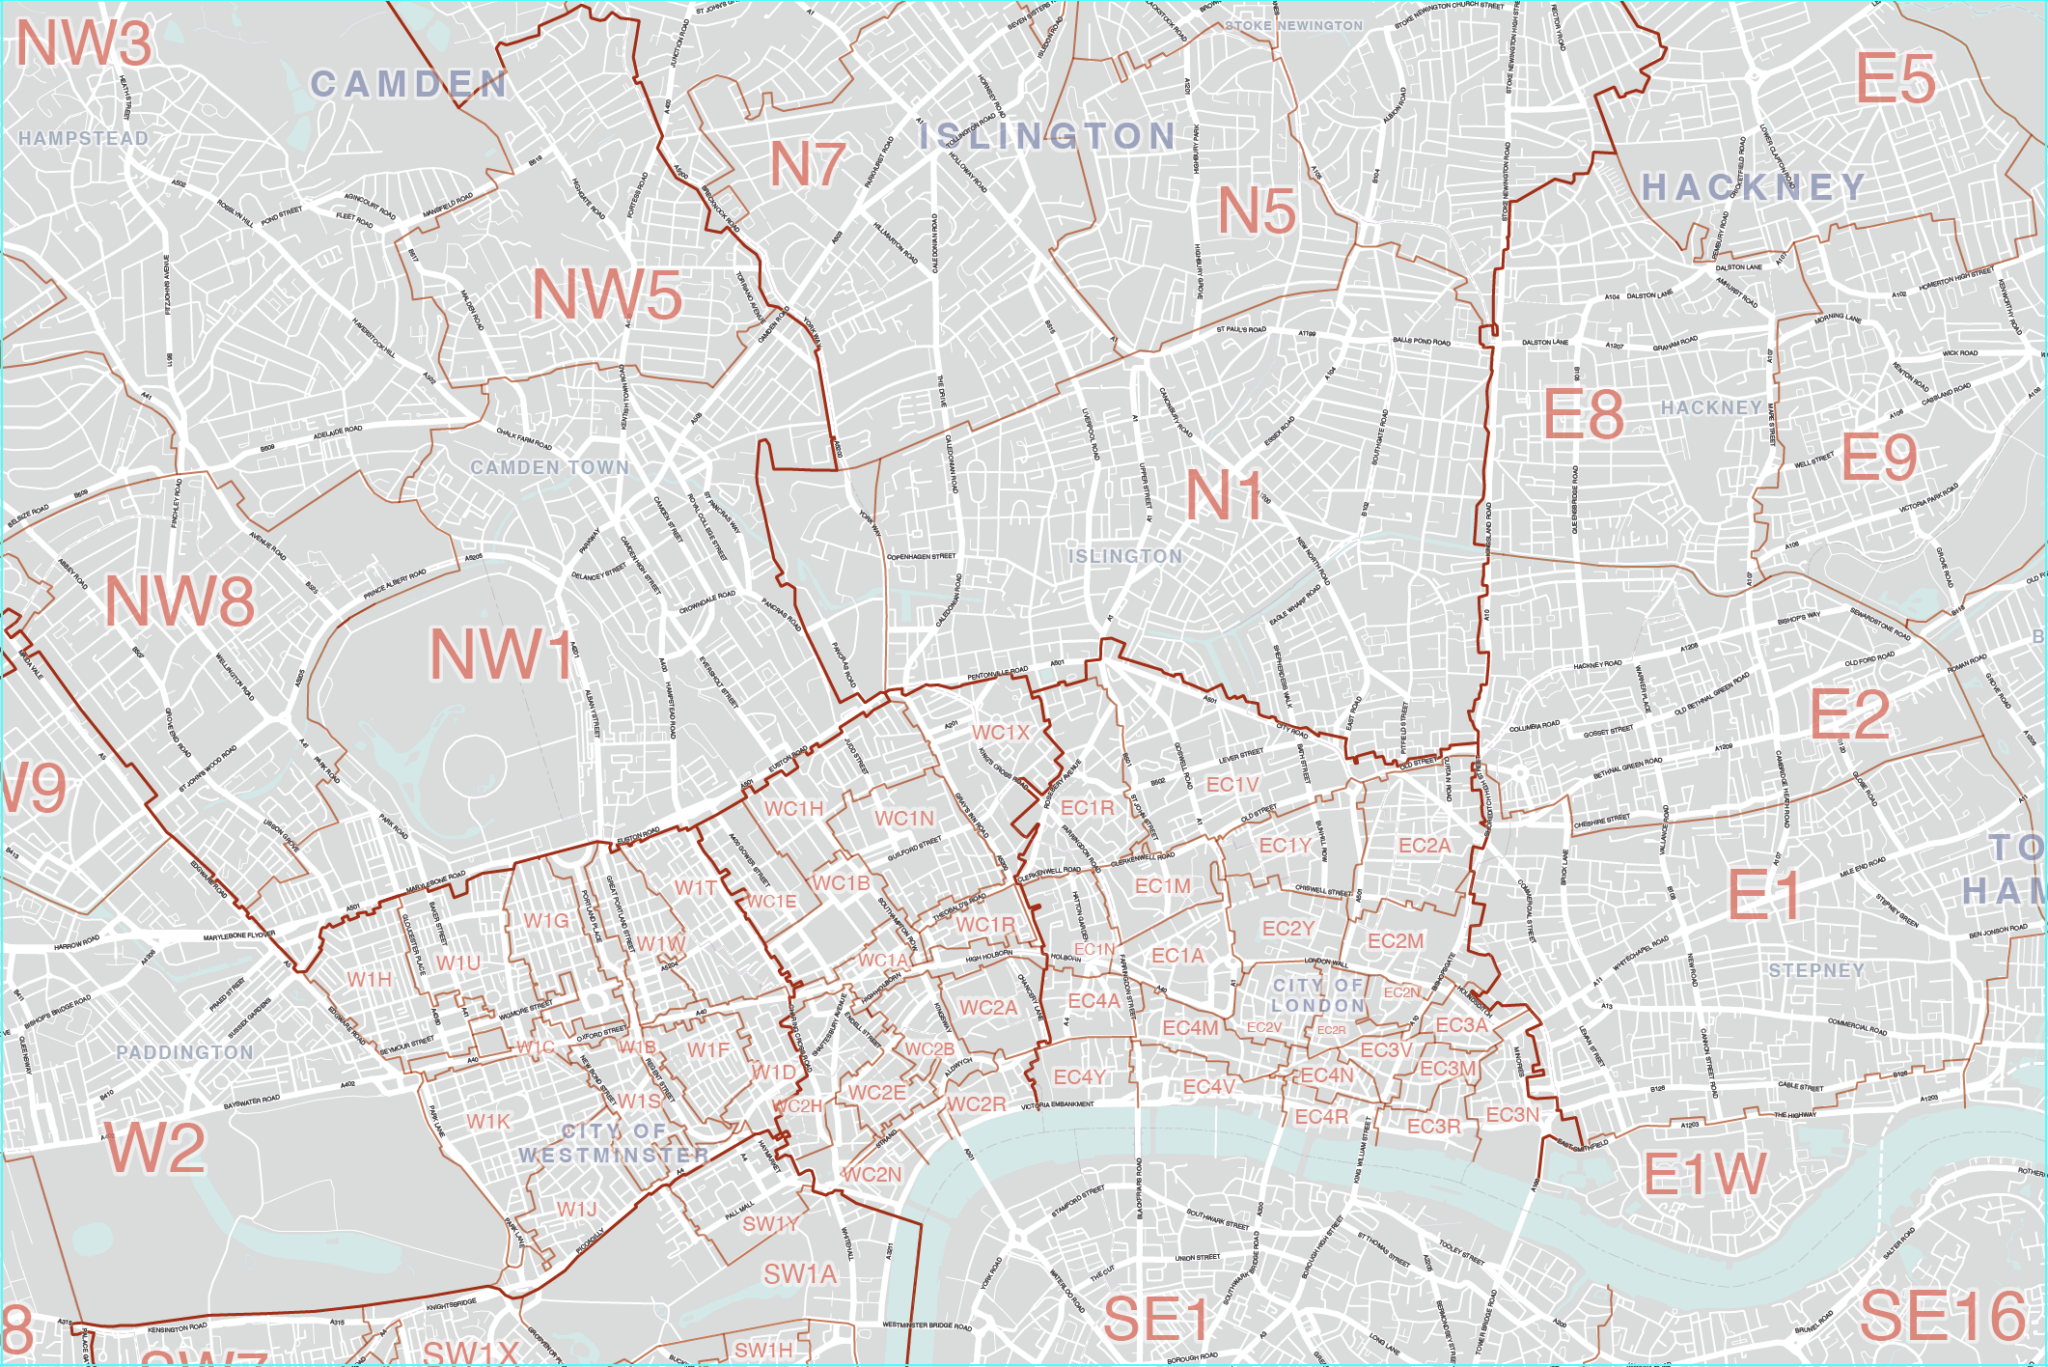
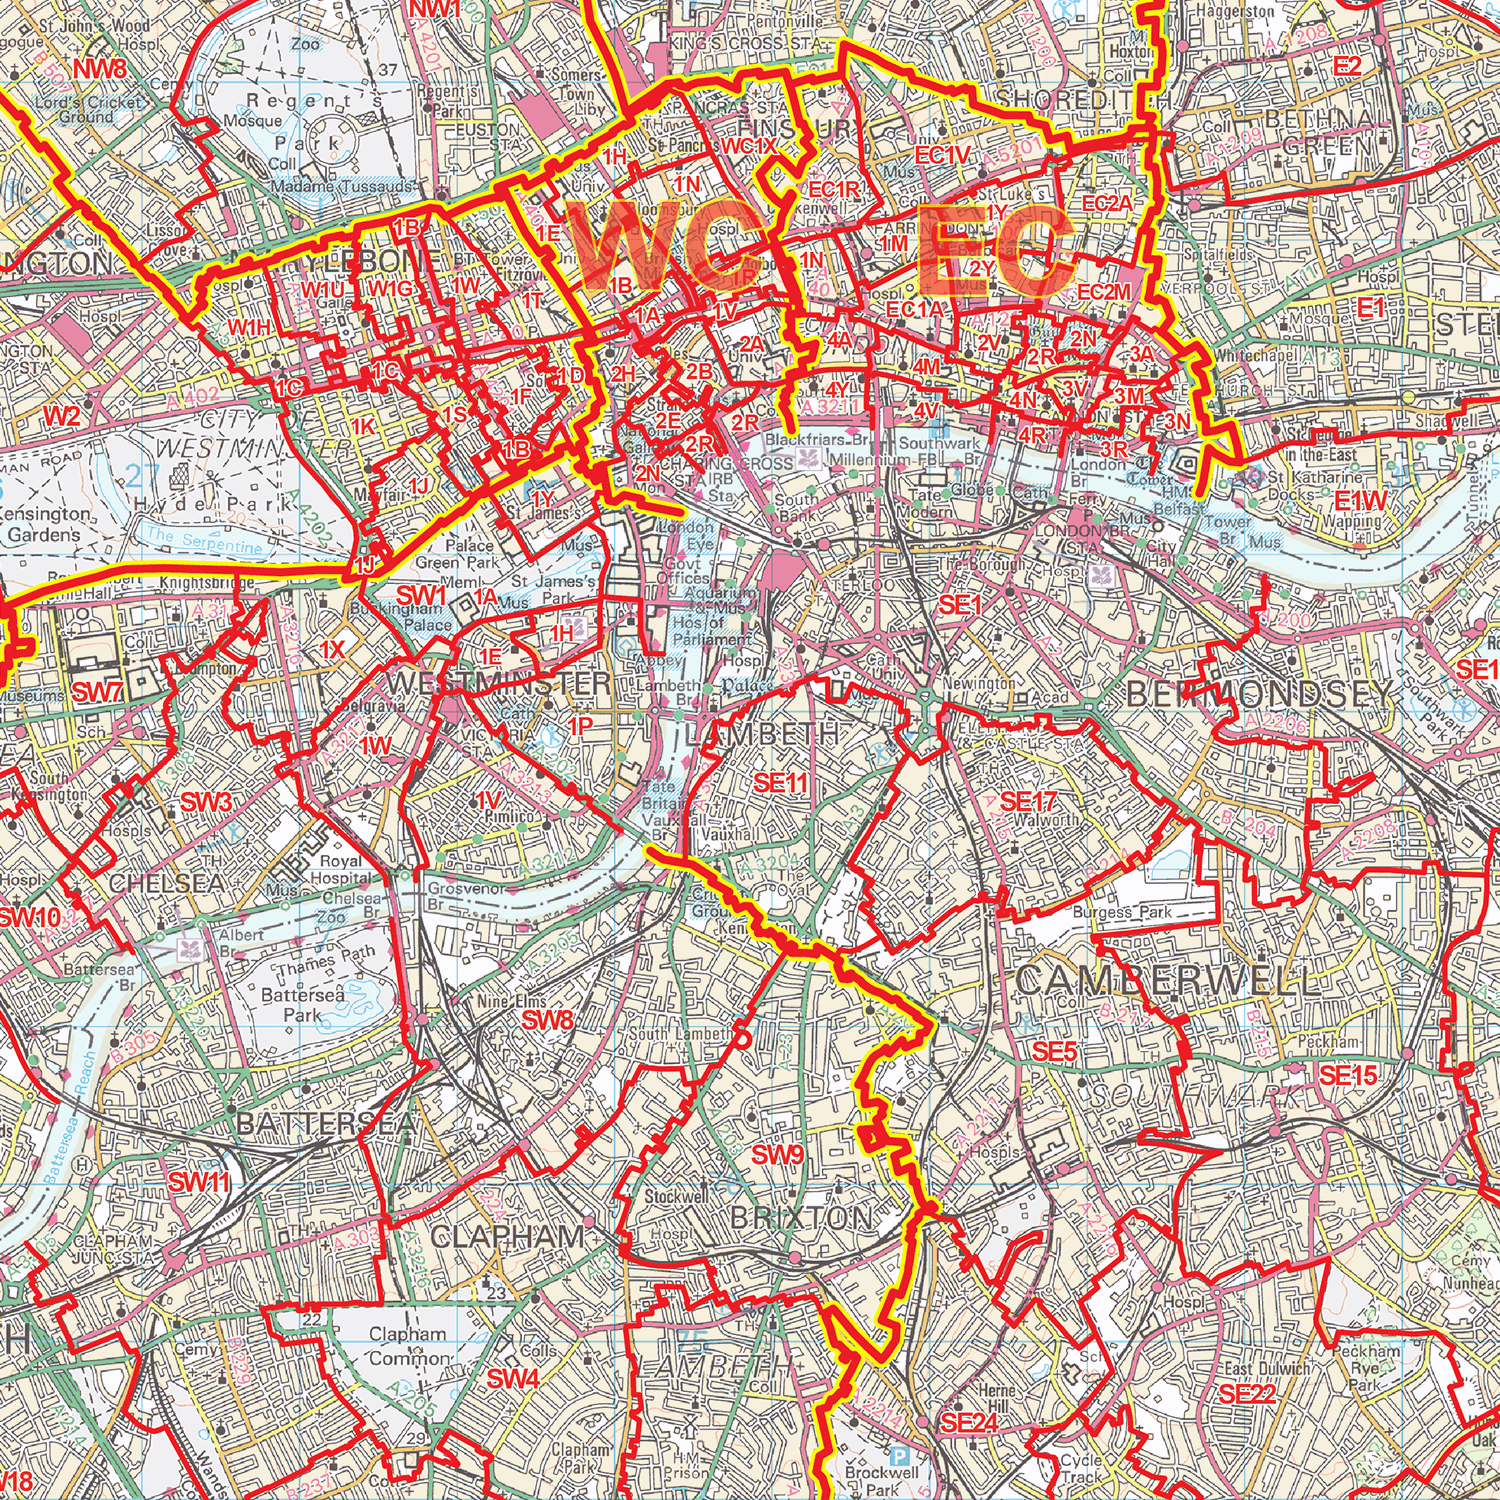
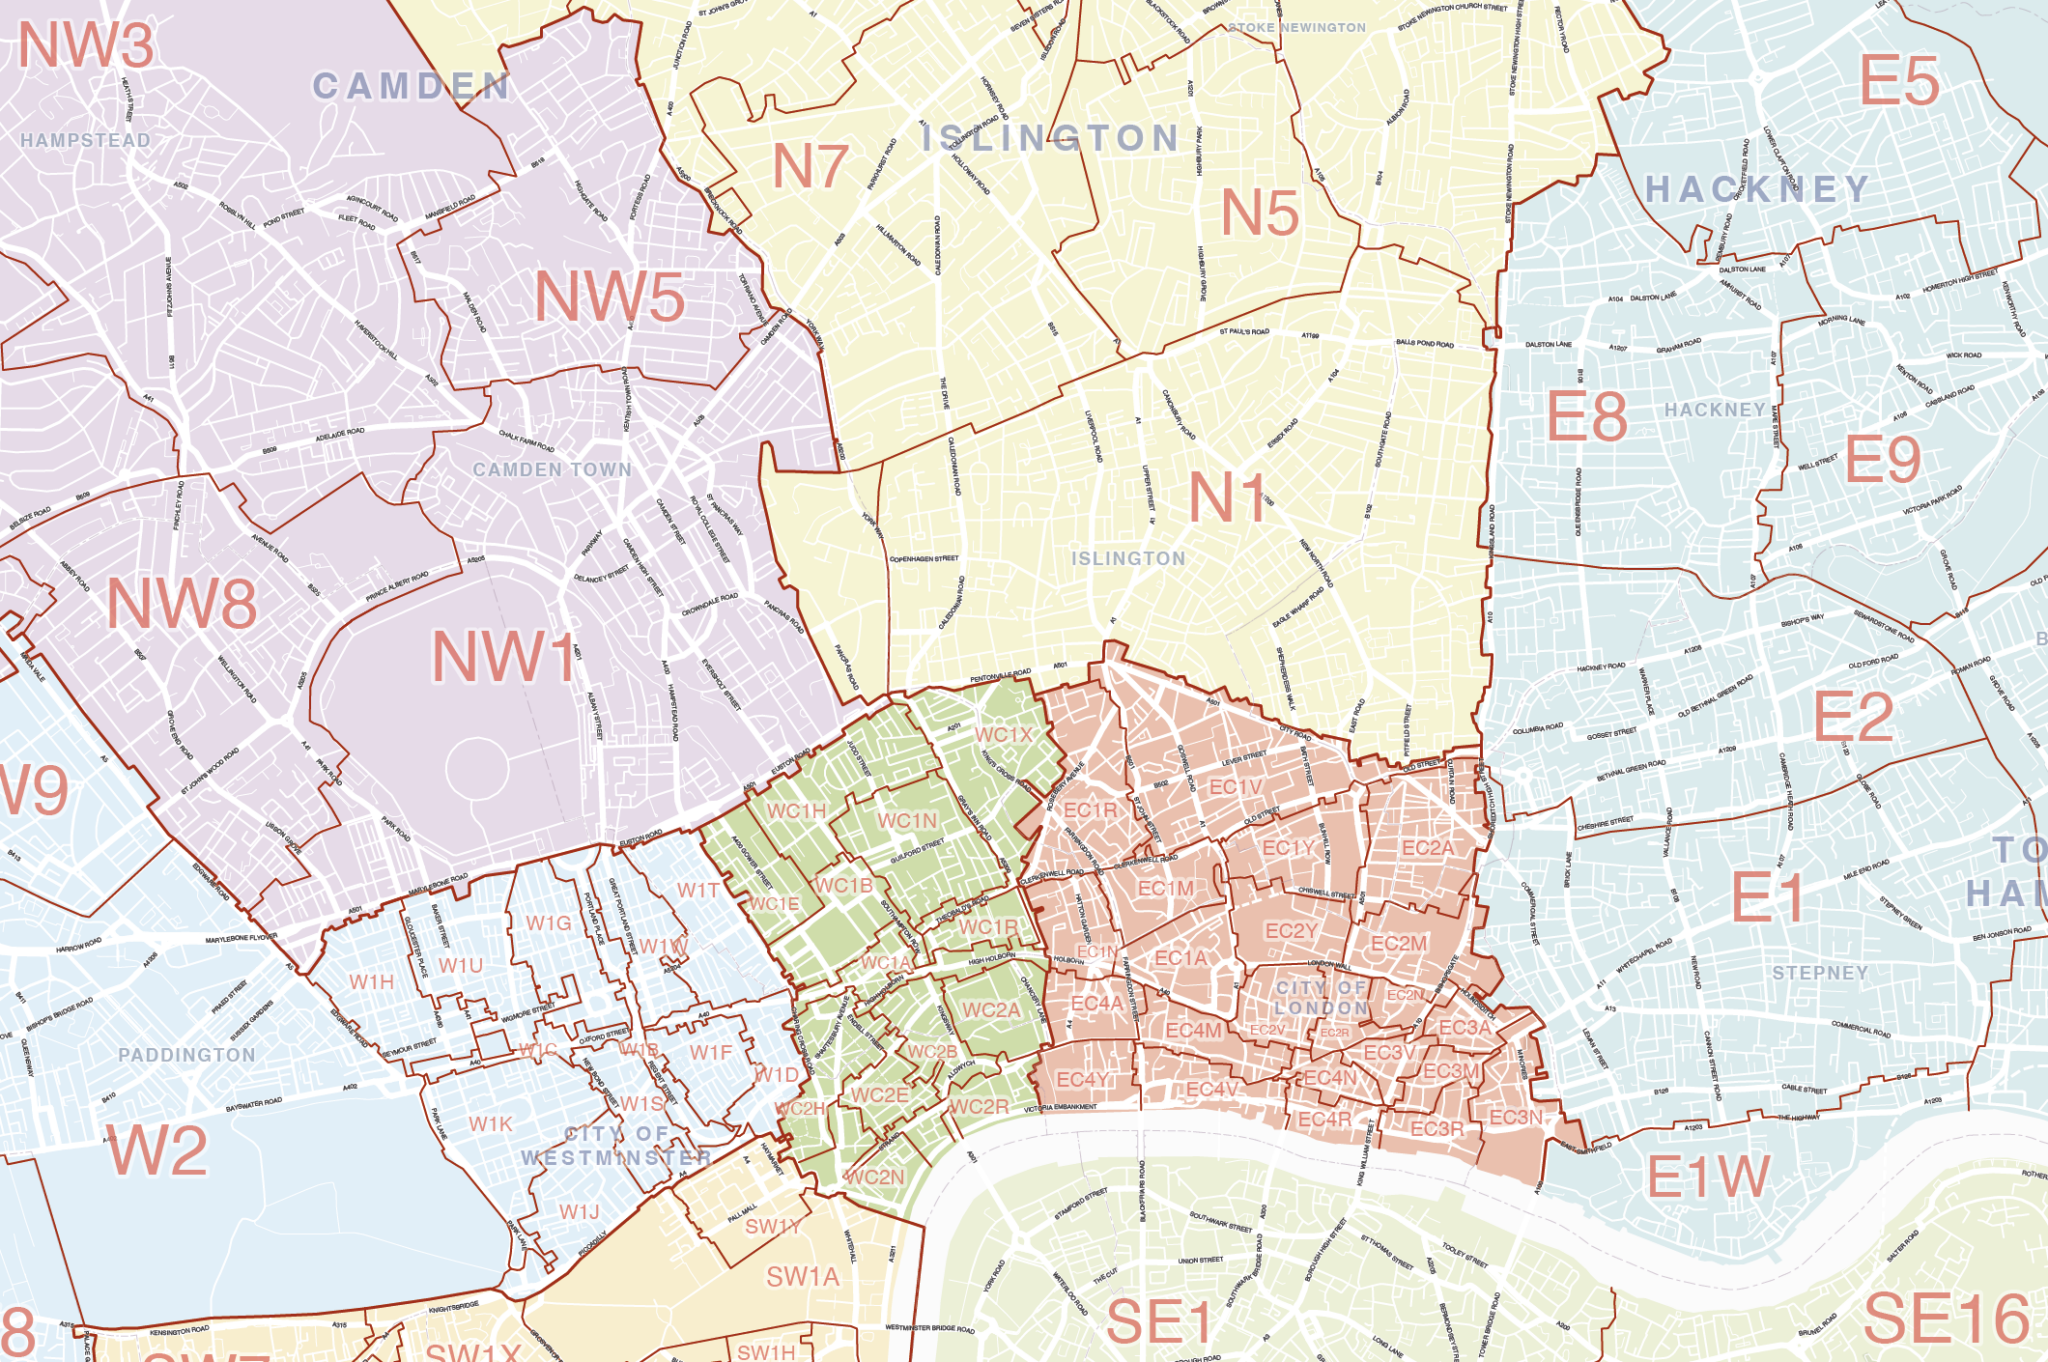
When you first look at London postcodes, they seem arbitrary. SW1A 1AA. E14 5AB. N1 9AG. There's a logic buried under the surface, and getting to it requires treating the postcode as a multi-layered geographic key rather than just a mailing address component. I've spent years working with Ordnance Survey's UPRN-to-postcode cross-reference tables and the ONS Postcode Directory, and the data you can pull from postcode geography is substantially underused by most people I talk to. The outward code (the part before the space) gives you the postcode area and district. The inward code narrows it to a sector and then an address unit. A single outward code like E14 can cover Canary Wharf, Limehouse, and parts of Poplar. An inward sector like E14 5 might contain roughly 15 to 25 addresses. That level of granularity is where the interesting patterns show up.
Unveiling The Hidden Diversities Of The London Postcode
London's postcode sectors are surprisingly diverse along axes most people don't consider. Take the N7 sector in Highbury. The 2021 census data at the sector level shows an ethnic diversity index of roughly 0.72 — meaning if you picked two random people from that sector, there's a 72% probability they belong to different ethnic groups. Meanwhile, just across the river in SE28 (Blackheath), that same index sits around 0.31. Both are London postcodes. Both are on the rail network. The postcode tells you this without any additional demographic query. The same principle applies to income, age distribution, and housing tenure. A single inner London postcode sector can have a median household income variance of £40,000 or more between its constituent wards when you break it down to super-output area level. This is why postcode-based targeting for market research often fails unless you're going at least to the MSOA layer. At the sector level, the averages obscure enormous internal variation. Here's the practical method I use when building any analysis pipeline:
Start with the ONS Postcode Directory, which you can download free from data.gov.uk. It maps every active postcode in the UK to its latitude, longitude, local authority, ward, and a set of administrative geography keys including LSOA, MSOA, and parliamentary constituency. From there, join it to whatever dataset you're working with — the census, electoral roll data, ONS mid-year population estimates, even commercial datasets like Acorn or Experian's customer-facing classifications. The join key is the postcode itself. Make sure you strip any spaces before matching, because the ONS publishes postcodes both with and without internal spacing depending on the dataset version. Once joined, you can aggregate to whichever geographic level your analysis requires. I typically aggregate to the LSOA (Lower Layer Super Output Area) because it's the smallest geography for which the census publishes full demographic breakdowns. There are roughly 32,844 LSOAs in England and Wales, and London alone contains about 3,500 of them. Each LSOA covers approximately 1,000 to 1,500 residents. That's small enough to capture neighbourhood-level diversity that a borough-wide average would completely flatten. I ran into a specific problem last year that illustrates why this matters. I was building a site selection model for a retail client who wanted to open a Middle Eastern grocery in East London. The initial analysis using postcode sector averages pointed squarely at E10 and E11. Both had high South Asian and Bangladeshi population shares at the sector level. But when I dropped the geography down to LSOA and overlaid the data against actual footfall patterns from mobile location providers, the picture changed. The highest concentration of target demographic households in E10 wasn't in the stereotypical high-street locations. It was in a cluster of LSOAs around Leytonstone that had a newer Turkish and Kurdish population that sector-level census categories completely missed because they'd been categorised under broader Middle Eastern and North African groupings. The sector average had 14% South Asian population. The specific LSOAs had 6% South Asian but 22% Turkish and Kurdish. Our client opened in Walthamstow instead. It's been open for two years and the turnover exceeds their projection by 40%.
Get the Full Details
There are tools available that automate much of this. The best free option is still the ONS Open Geography portal, which lets you pull geography boundaries and join directly in the browser. For anyone doing this regularly, I'd recommend learning to use the `gclue` or `postcodes.io` packages in R if you're working in that environment, or the equivalent Python libraries like `postcode-utils` and `geopandas` for the Python side. The postcodes.io API is free for non-commercial use and will validate, geocode, and return bounding boxes for any UK postcode in a single request. It's fast — usually under 200 milliseconds per query — and handles the vast majority of edge cases with malformed or historical postcodes. For anyone who wants to download a complete dataset to start working offline, the ONS Postcode Directory (Partial) is updated quarterly and contains roughly 1.7 million active postcodes with full geometry. It's a 400MB GeoJSON file. The full version with all historical postcodes goes to about 1.2GB. Both are available from the same data.gov.uk page I mentioned earlier. There are real limitations to this approach that most guides don't mention. The first is that postcode geography changes. New developments get new postcodes. Existing postcodes get split or merged. The ONS publishes a change history document, but it's easy to miss. If you're tracking diversity trends over time, you need to account for boundary shifts, not just population changes. A postcode sector that appears to have become less diverse between 2011 and 2021 might simply have had its boundaries redrawn to include a neighbouring area with different demographics.
The second limitation is that postcode-level data has a confidentiality issue. The ONS suppresses or perturbs certain cell values in low-population postcodes to prevent identification. If you're working in a postcode sector with fewer than 200 residents, some census tables will show null values or estimated figures marked with an asterisk. This is most common in rural corners of Greater London like parts of HA7 or BR3. The data isn't wrong, but it's imputed, and you should treat it accordingly. The third issue, and the one that causes the most problems in practice, is that postcodes don't map perfectly to social realities. A single postcode can span multiple neighbourhoods. SW1P covers parts of Victoria, Pimlico, and the edges of Belgravia. The diversity index for that outward code is meaningless because it's averaging three distinct social environments. Always aggregate down to at least the sector or LSOA level before drawing conclusions. The outward code is a mailing convenience, not an analytical unit. If you need something faster than building your own pipeline, the NOMIS workspace at nominis.gov.uk lets you build custom tables at the LSOA and MSOA level with a point-and-click interface. It's slower than a programmatic approach but requires no coding. For the most detailed analysis, combining the ONS Postcode Directory with the census PUF (Public Use Microdata) files gives you access to individual-level respondent data sampled at the MSOA level, which adds another layer of precision for diversity analysis.