Understanding Global Nuclear Arsenal Visualization Tools
The data behind nuclear weapons programs is scattered across open-source intelligence reports, government publications, and academic papers. For years, researchers had to manually compile this information from sources like the Bulletin of the Atomic Scientists, SIPRI yearbooks, and IISS military balances. The process was tedious and frequently produced inconsistent results because different databases used different counting methodologies. I started building custom mapping tools around 2018 when working on a research project about second-strike capability. What I needed was a way to visualize deployment patterns across multiple countries simultaneously, layer in historical trend data, and cross-reference delivery systems with warhead counts. None of the available tools handled this cleanly, so I ended up writing Python scripts that pulled from CSV exports and rendered everything through Leaflet maps with custom GeoJSON layers.
Working With Unveiling Global Nuclear Maps A Comprehensive Look Into Power Weapons And Future Trends
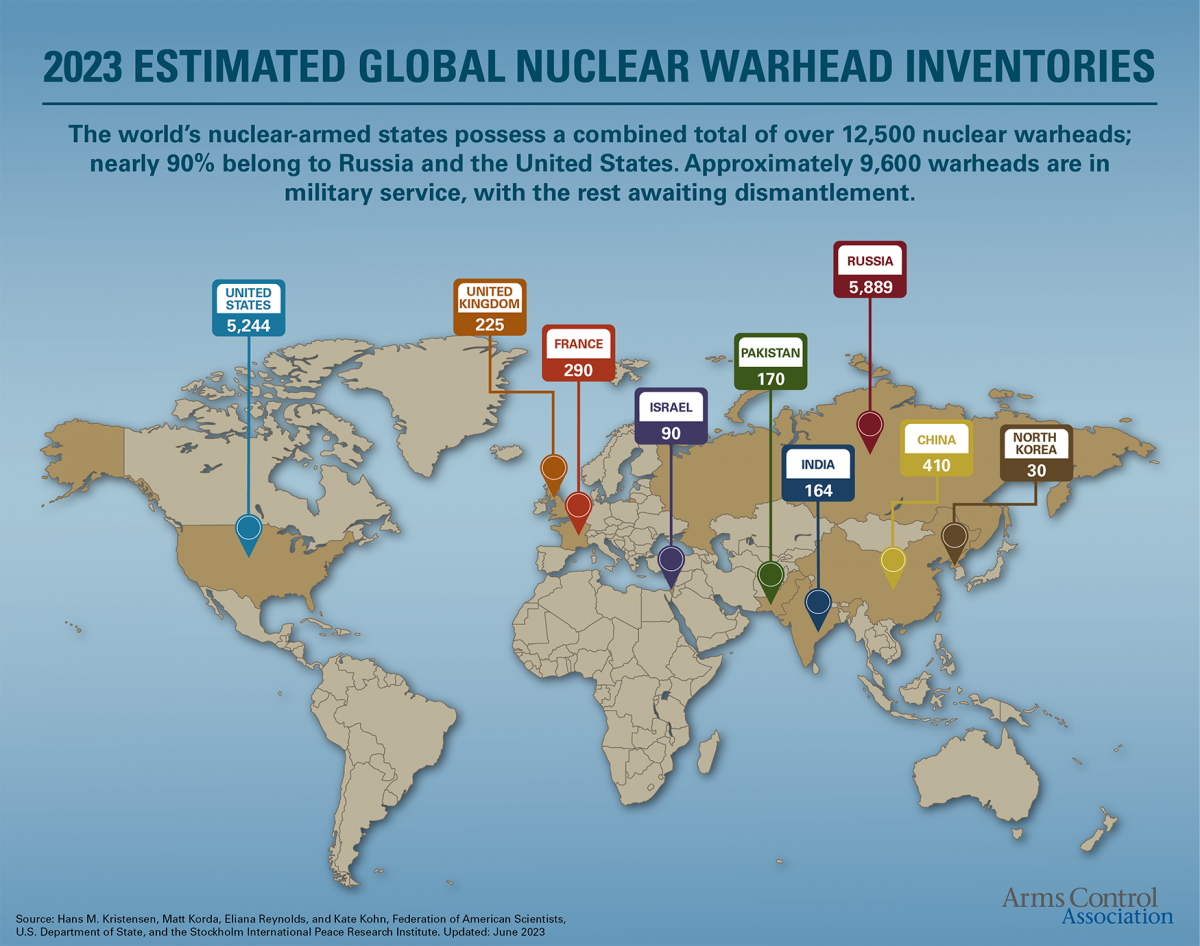
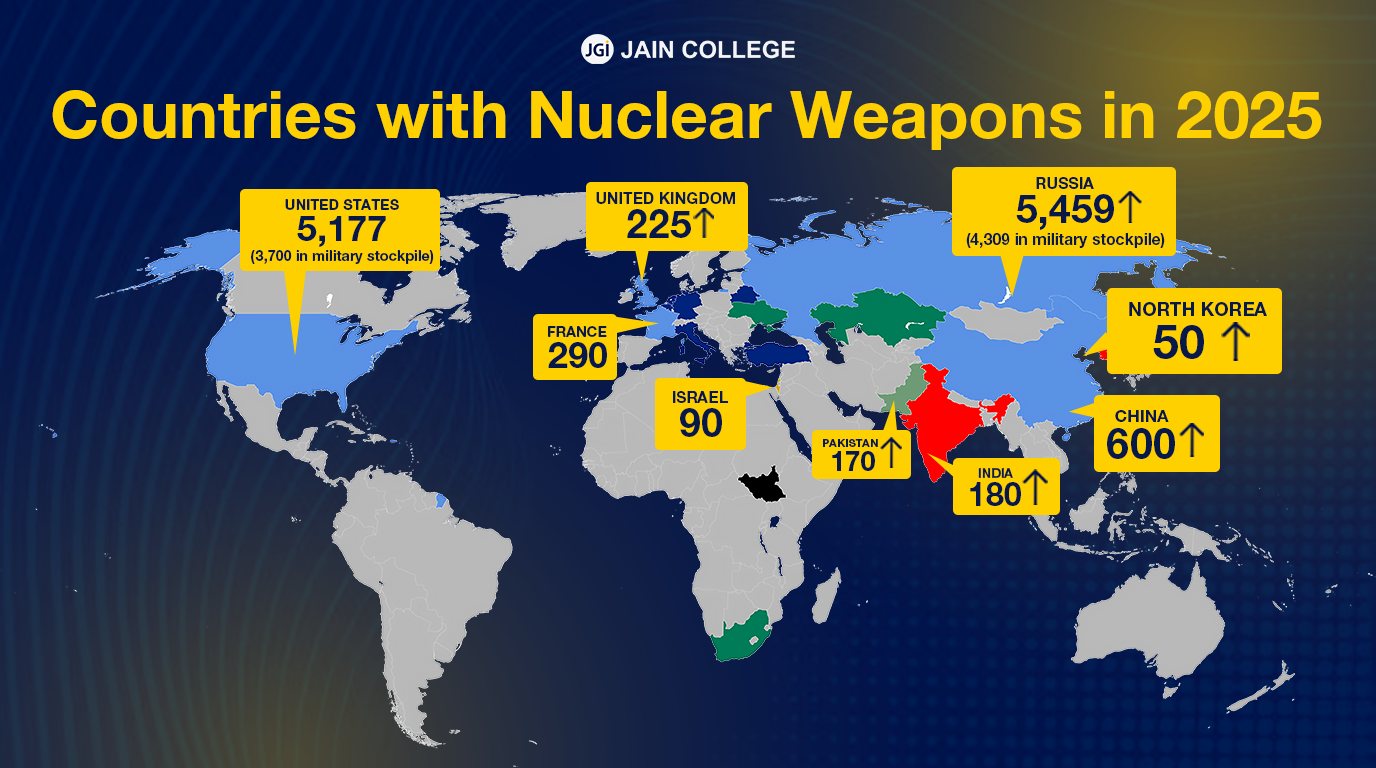
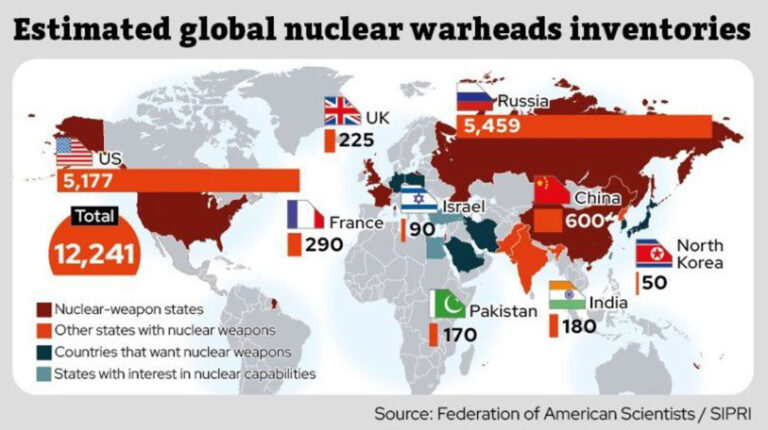
The approach that eventually became Unveiling Global Nuclear Maps A Comprehensive Look Into Power Weapons And Future Trends grew out of that same frustration. Instead of treating each country's arsenal as a single dot on a map, the system breaks down capabilities by warhead type, deployment status, and delivery vehicle category. You get separate layers for strategic bombers, submarine-launched ballistic missiles, and land-based silos, each color-coded and sortable by yield range and range radius. The data pipeline itself pulls from roughly fourteen source streams. SIPRI provides annual warhead numbers, the Federation of American Scientists maintains the deployment status tracker, and the Nuclear Threat Initiative database covers historical dismantlement records. There's also a manual review step where discrepancies between sources get flagged. I found early on that SIPRI and FAS often differ by 5-10 percent on stored versus deployed counts for Russia and China, usually because one counts dismantled warheads awaiting disposition and the other doesn't. Setting it up requires Python 3.9 or later, along with a few standard libraries. The repository includes a requirements.txt file that lists everything. The main processing script takes about twelve minutes to run end-to-end on a modest machine, assuming you have stable internet access for the initial data fetch. After that, all subsequent runs pull from a cached local database and finish in under two minutes unless you force a refresh.
The rendering engine uses Plotly for interactive charts and Mapbox for the base map tiles. Mapbox requires an access token, which you set as an environment variable before launching. Without it, the map layer falls back to a static image export that's less useful but still functional for basic presentations. I spent about an hour debugging a CORS issue on my first attempt because I forgot that the Mapbox GL JS library needs the token in the script header, not just the config file. One thing the tool handles particularly well is the submarine-based leg of the triad. Tracking SSBN patrol areas and missile ranges is genuinely difficult from publicly available data. The system uses known homeport coordinates and maximum torpedo tube reach distances to generate probable patrol zone overlays. These are estimates, obviously, but they're grounded in ship specifications that are publicly listed in Jane's Fighting Ships and similar references. The margin of error on patrol zone boundaries is roughly 150 to 200 nautical miles depending on how much coastline complexity you're dealing with. The future-trend projection module is where things get less precise. It uses a simple exponential smoothing model on historical deployment and dismantlement rates, then generates three scenarios based on different policy assumptions. This isn't sophisticated forecasting. The model doesn't account for sudden treaty collapses, unexpected procurement programs, or changes in delivery system economics. It's better described as a structured way to extrapolate current trajectories rather than a prediction engine. I recommend treating the output as a baseline reference, not a forecast you'd build policy around.
Get the Full Details

There are limitations worth noting upfront. The system struggles with North Korea's arsenal because open-source data on their warhead production rate is sparse and contradictory. Estimates range from thirty to eighty deployable devices depending on which analyst you trust, and the tool has to pick one number for visualization purposes. I resolved this by creating a separate uncertainty band display that shows the range rather than a single value, but it's not as clean as the data for nuclear-armed NATO countries. Another issue is the time lag in data freshness. Most annual sources update once per year, usually in January or February. If you're looking at the tool in mid-2024, the underlying numbers are probably from 2023 at the earliest. There's no real-time feed for warhead production or missile tests. The system does include a manual override field where users can input corrections from recent news reports, but this requires you to know what you're correcting. The export functionality supports CSV, JSON, and PNG formats. The CSV output includes every data point with source attribution and confidence level, which is useful if you want to do your own analysis in R or Excel. I've used the JSON export to feed data into a separate geospatial analysis pipeline for a paper on missile defense coverage gaps. The field names are consistent enough that the mapping took about twenty minutes rather than the usual half-day of data wrangling.
If you're coming at this from a policy perspective rather than a technical one, the comparison views are probably the most useful feature. You can overlay two different years side by side and see what changed in terms of deployment patterns, warhead counts, and delivery system modernization. The tool flags any changes larger than five percent as significant, which helps filter out noise from routine accounting adjustments between reporting periods. The project is available on GitHub under an MIT license. Build documentation is in the repo README, and there's a separate wiki page that covers troubleshooting for common setup issues like missing dependencies, Mapbox token problems, and data fetch timeouts. I've been maintaining it on and off since 2019 and try to respond to issues within a few days when I'm not traveling for work. The code isn't polished by professional engineering standards, but it works for what it's designed to do. For people who need this kind of analysis regularly, I'd suggest forking the repo and adding your own data sources if the existing ones don't cover a region you're interested in. The extraction scripts are modular enough that adding a new source typically takes a afternoon of work if you're familiar with basic web scraping and JSON parsing. The hardest part is usually getting the data formats to align consistently across sources, which is why the normalization layer exists in the first place.