
Peer-to-Peer Networks Explained from Someone Who Has Managed Them
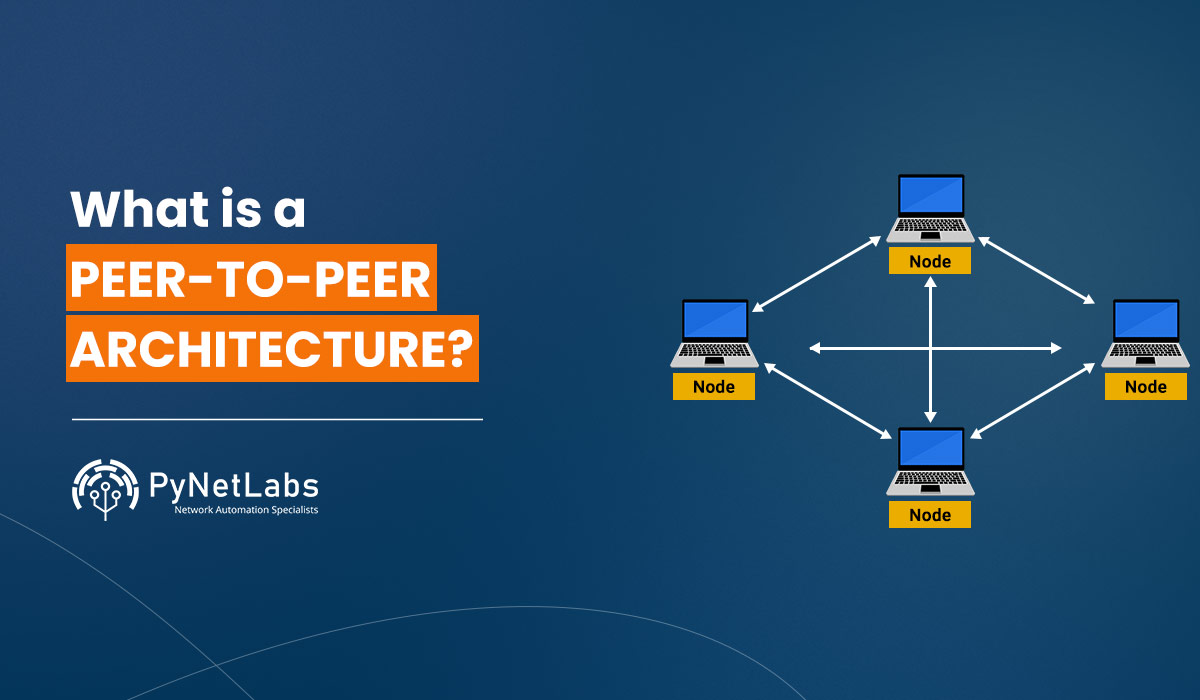
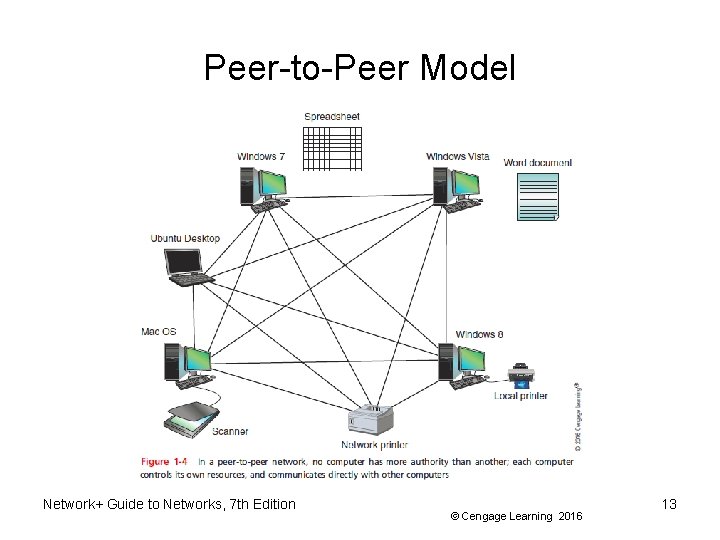
I spent about three years running a small P2P file-sharing network for an internal research group. Not the torrent kind. We built something custom on top of libp2p because our data had to stay within a certain set of machines in three different cities, and we couldn't put it on a single server without breaking compliance rules. That experience taught me more about how these systems actually behave than any textbook ever did. A peer-to-peer network is simply a group of computers that talk to each other directly, without going through a central server that controls everything. Each node can act as both a client and a server. You have probably encountered this already. BitTorrent is the most well-known example. When you download a large file through a torrent client, your machine is simultaneously receiving data from other peers and sending pieces you already have back to them. The more people who join, the faster the whole system tends to run, which is the opposite of what happens with a traditional client-server model where more users just slow everything down. Blockchain technology is another obvious example. Bitcoin and Ethereum are fundamentally P2P networks where every node maintains a copy of the transaction history. There is no bank or company running the system. The network validates itself through consensus mechanisms like proof of work or proof of stake.
Unraveling The Web Of Peertopeer Networks A Comprehensive Guide
This phrase keeps coming up in search results even though it is not a standard technical term. I think people are trying to describe what I am about to walk through here: how to understand and work with P2P networks when you are actually dealing with them. Let me start with the practical side. The core problem that any P2P system has to solve is discovery. In a server-based setup, you know exactly where the data lives. It is at a specific IP address. In a P2P network, every node needs to find other nodes without asking a central authority. This is usually done through a distributed hash table, commonly called a DHT. The Kademlia protocol is the most widely used implementation. It assigns every piece of data and every node a unique identifier and uses XOR distance to figure out which nodes are closest to any given ID. When a node wants to find information about a specific file or service, it queries the DHT. The query hops from node to node, getting closer to the target identifier with each step. In a network of ten thousand nodes, you typically find what you need in about five to seven hops. That logarithmic scaling is the main reason P2P networks are so resilient. Adding more nodes does not slow the system down significantly.
I learned this the hard way when our internal research network experienced a partition between our London and Tokyo nodes. The DHT split into two separate groups, and each group only knew about its own peers. Data that should have been available globally was locked in one partition. The fix was to manually seed the cross-partition routing tables with a few known-good bootstrap nodes. Without those seeds, the partitions would have stayed isolated until someone restarted the entire network.
Get the Full Details
The Main Types of P2P Architectures
Not all P2P networks are built the same way. The architecture you choose determines everything about how the system behaves under load. Unstructured networks are the simplest. Nodes join and leave randomly. There is no fixed topology. Gnutella, the original file-sharing network, used this approach. Query messages flood through the network using a technique called TTL, or time-to-live, where each message can only be forwarded a certain number of times before it dies. This works fine for small networks but becomes chaotic at scale. You end up sending thousands of redundant queries to find a single file. Semistructured networks add some organization without giving up the decentralized nature. Super nodes are used to index content. KaZaA and early versions of eDonkey2000 relied on this model. The problem is that super nodes become single points of failure. If the super nodes go down, the whole indexing system collapses. You lose the ability to find anything even though the underlying network might still be running.
Structured networks use DHTs to create a predictable topology. Every node knows exactly where to send queries. Kadence and Chord are classic examples. This is the most efficient approach for large-scale systems. The trade-off is that maintaining the structure requires constant background communication. Nodes that join or leave too frequently cause instability. The network has to rebuild routing tables continuously. Hybrid networks combine central servers with P2P components. Skype used this model for many years. The central servers handled authentication and discovery, while the actual media streams went directly between peers. This approach gives you the reliability of a central authority with most of the scalability benefits of P2P. The downside is that you still depend on those central servers. If they are taken down or censored, the system stops working even though the P2P layer could theoretically function on its own.
Practical Use Cases Beyond File Sharing
People assume P2P is only about sharing movies and music. That is a narrow view. Here are some real applications I have seen work well in practice. Distributed computing is one of the most valuable uses. BOINC, the Berkeley Open Infrastructure for Network Computing, lets volunteers donate idle CPU cycles to scientific projects. SETI@home analyzed radio signals. Fold@home studies protein folding. The individual contributions are tiny. Together they create computing power that rivals supercomputers. The P2P layer handles distributing work units and collecting results without a central server becoming a bottleneck. Content delivery networks benefit from P2P principles. When a popular video gets millions of requests, a single origin server cannot handle the load. CDN providers use P2P techniques to distribute cached content across thousands of edge nodes. Viewers get data from the nearest node instead of traveling all the way back to the origin. This usually cuts load times from several seconds down to under half a second for geographically distant users.
Decentralized storage has become more prominent recently. Systems like IPFS and Filecoin let you store data across a network of nodes. You do not trust a single provider. If one node goes offline, other nodes that have replicated your data can serve it. The trade-off is that retrieval can be slower than traditional cloud storage. You have to wait for the network to locate and assemble your data from multiple sources. Communication networks are another area where P2P shows its value. Signal and Wire use centralized servers for messaging. But projects like Matrix and Session build federated or fully P2P communication layers. Messages can route directly between users when possible. This reduces latency and eliminates the single point of failure that central servers represent.
Common Pitfalls That Catch People Off Guard
Building or using a P2P network is not as simple as downloading some software. There are real problems that people underestimate. Sybil attacks are a serious threat. An attacker creates thousands of fake identities and joins the network. If the system relies on voting or reputation, the attacker can dominate decision-making. Bitcoin addresses this through proof of work, which makes creating fake identities computationally expensive. But many smaller P2P projects do not implement adequate Sybil resistance. The result is that a single malicious actor can control a significant portion of the network. Network partitions are another frequent issue. As I described earlier, our London and Tokyo nodes split during a routine maintenance window. Internet routing changes caused the two regions to lose connectivity to each other. The network looked healthy from each side. Nodes were connected to their local peers. But the global view was completely broken. Data available in London was invisible to Tokyo and vice versa. This is a fundamental problem with decentralized systems. There is no central monitor that can tell you the whole network is healthy. You have to infer health from local observations, which is inherently unreliable during a partition.
Legal and regulatory risk deserves mention. P2P networks make it difficult to control what happens on them. If someone uses your network to distribute copyrighted material or illegal content, you may face legal consequences depending on your jurisdiction. The US DMCA has safe harbor provisions for certain types of P2P services. The EU's Digital Services Act imposes different obligations. You should consult legal counsel before building or deploying a P2P system, especially if it involves user-generated content or financial transactions. Performance unpredictability is a real concern. In a client-server model, you know the bandwidth and processing capacity of your servers. In a P2P network, every node has different characteristics. Some machines are powerful desktops with fast connections. Others are low-end laptops on mobile data. Your application has to handle this variability gracefully. If you assume all nodes can serve content equally, your system will perform poorly when many nodes are weak or slow.

What I Would Do Differently Now
Looking back at our three-year project, there are several things I would change. The biggest mistake was not implementing comprehensive monitoring from day one. We spent the first six months troubleshooting problems without adequate visibility into what was actually happening across the network. By the time we added proper monitoring, we had lost important diagnostic data. I would also invest more time in bootstrapping strategy. Getting a P2P network to grow organically is harder than most people expect. New nodes need to find existing nodes to join the network. If the initial population is too small, new nodes give up before they can contribute meaningfully. We solved this by running a small number of always-on relay nodes that helped new participants discover the network. This hybrid approach gave us the best of both worlds: reliable discovery and eventual full decentralization. Finally, I would be more careful about data replication. Our network stored research data that could not be lost. We replicated each piece of data across at least five nodes before considering it safely stored. This meant we used five times more disk space than a centralized system would require. But it also meant we could tolerate the loss of four nodes without any data damage. That redundancy is the price you pay for decentralization. It is not optional if you want real resilience.
The landscape has changed since we built our system. New protocols like libp2p have made it significantly easier to build P2P applications. The Go ecosystem around libp2p provides well-tested implementations of DHTs, connection management, and NAT traversal. If you are starting a P2P project today, I would recommend building on top of libp2p rather than writing your own networking layer from scratch. The development time savings are substantial. You avoid reinventing solutions that have already been stress-tested in production environments.


