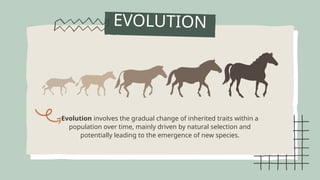
Selection And Speciation Are Not The Same Thing, And Most People Treat Them Like They Are
People conflate natural selection with speciation constantly. Natural selection is a mechanism that shifts allele frequencies within a population. Speciation is the outcome where one lineage splits into two reproductively isolated ones. You can have selection without speciation. You can have speciation with minimal selection. Understanding the distinction matters because it changes how you approach studying either process. I spent years working with population genetic data trying to tease apart which pattern was driven by selection versus drift. One thing that trips people up immediately is that selection signatures and demographic history look almost identical in genome-wide data. A selective sweep reduces diversity in a region. So does a population bottleneck. When I was first learning to interpret these patterns, I kept attributing diversity reductions to selection when the real cause was a recent founder event. The workaround was running coalescent simulations under the inferred demographic model first, then checking whether the observed signal exceeded what drift alone could produce. This usually takes a few days of computation but saves you from publishing an incorrect selective sweep claim. Let me walk through how selection actually operates before getting into speciation, because the mechanisms are different enough that merging them causes confusion.
How Selection Actually Works In Practice
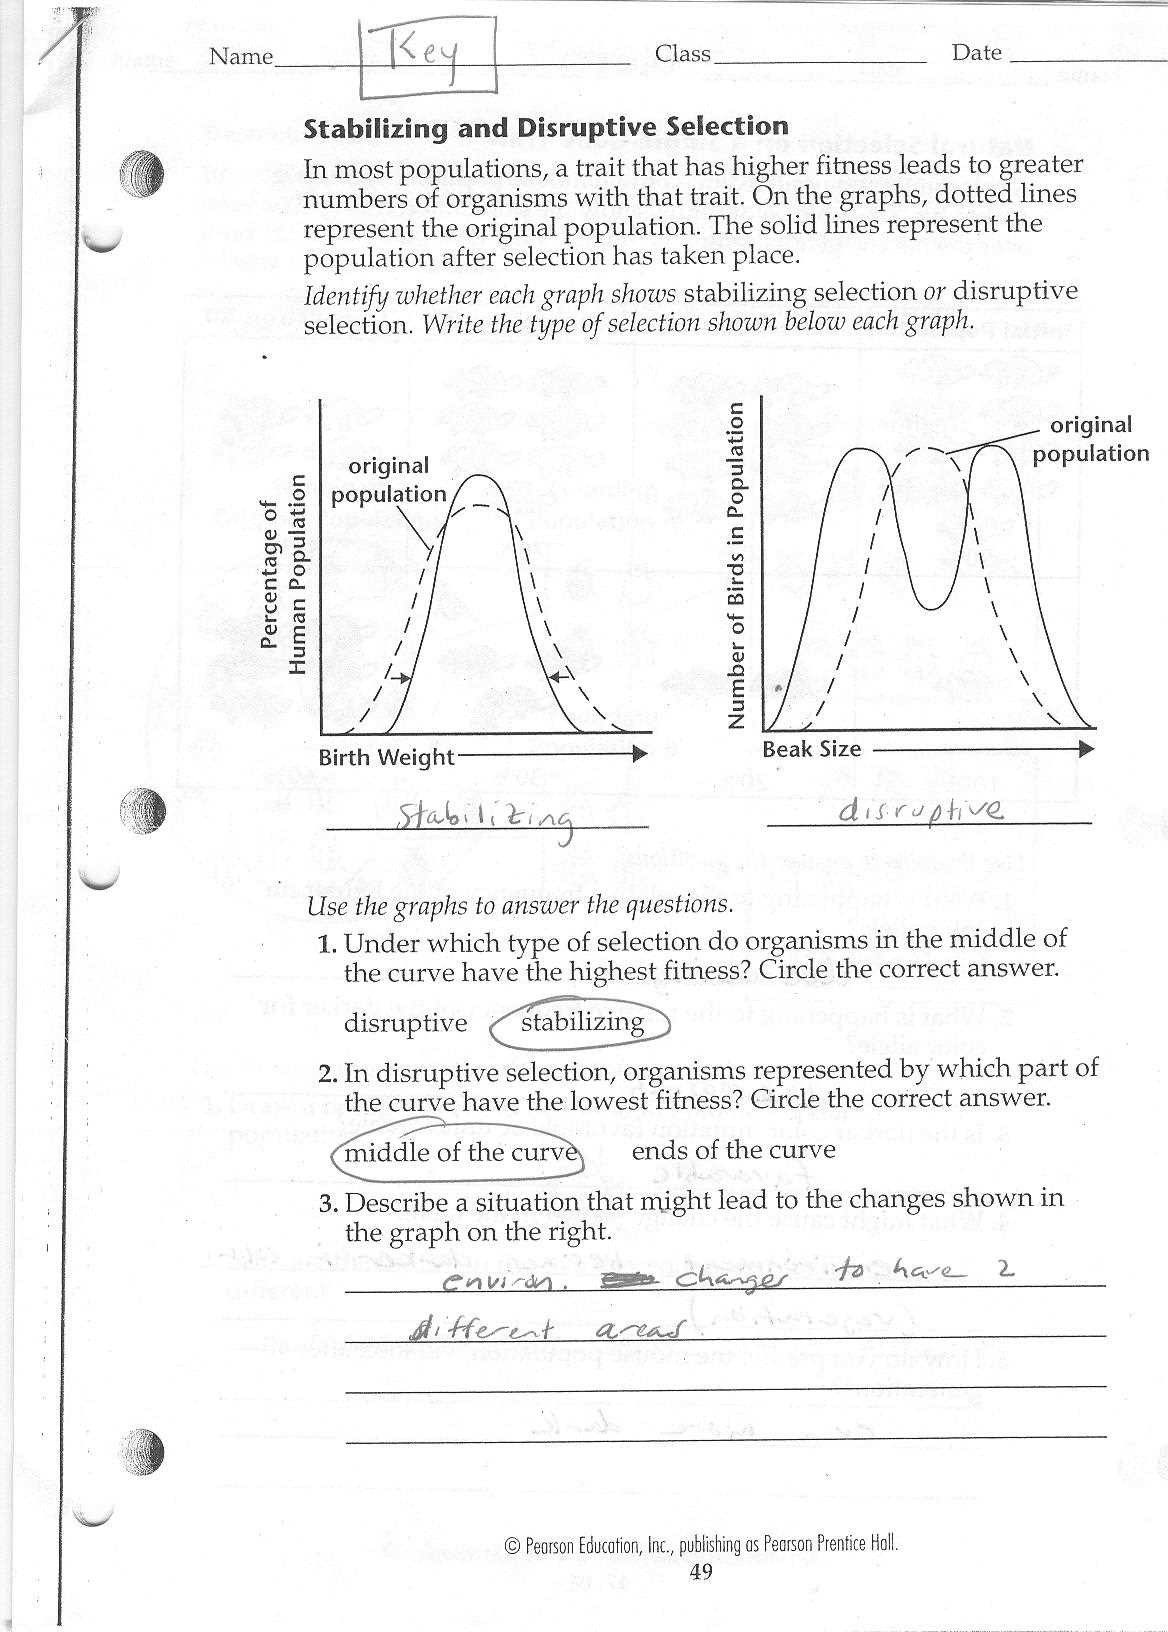
Natural selection acts on phenotypes, but it changes genotypes. The unit of selection is often misunderstood as the individual, but gene-level and group-level selection are real phenomena that complicate the picture. Directional selection shifts a trait mean toward one extreme. Stabilizing selection trims variation around an optimum. Disruptive selection favors both extremes over the intermediate phenotype. Most traits in nature are polygenic, meaning they are shaped by many loci of small effect, not one or two genes with large effects like the textbook examples suggest. The strength of selection is measured by the selection coefficient, s. If a genotype has a fitness of 1 and an alternative has fitness 1 minus s, then s represents the selective disadvantage. In real populations, s values for most selectable mutations are tiny. We are talking about differences in the range of 0.001 to 0.01 for most adaptive mutations. That means selection takes a long time to move alleles to fixation, and genetic drift can easily overwhelm weak selection in small populations. Here is something most introductory materials do not emphasize enough: background selection and linked selection complicate everything. When purifying selection removes deleterious mutations at one locus, it also reduces genetic diversity at nearby neutral sites because recombination has not had time to separate them. This creates regions of low diversity that look like selective sweeps but are actually the result of constant deleterious mutation removal. I have seen multiple papers get this wrong, especially in species with low recombination rates like Drosophila melanogaster inversion regions or the Y chromosome. The fix is to control for recombination rate variation and compare your signal against neutral expectations conditioned on local recombination rate.
Hard sweeps versus soft sweeps matter more than people realize. A hard sweep happens when a single new mutation arises and rises to fixation. A soft sweep occurs when selection acts on standing genetic variation or multiple independent mutations at the same locus. Soft sweeps leave weaker and more diffuse genomic signatures, making them much harder to detect with standard sweep detection methods like Tajima's D or XP-EHH. If you are scanning a genome for selection and find very few candidates, the problem may not be that there is no selection occurring. It may be that most adaptation is coming from standing variation rather than new mutations, and your methods are not tuned to catch that pattern.
Get the Full Details
Speciation Mechanisms And Where They Break Down
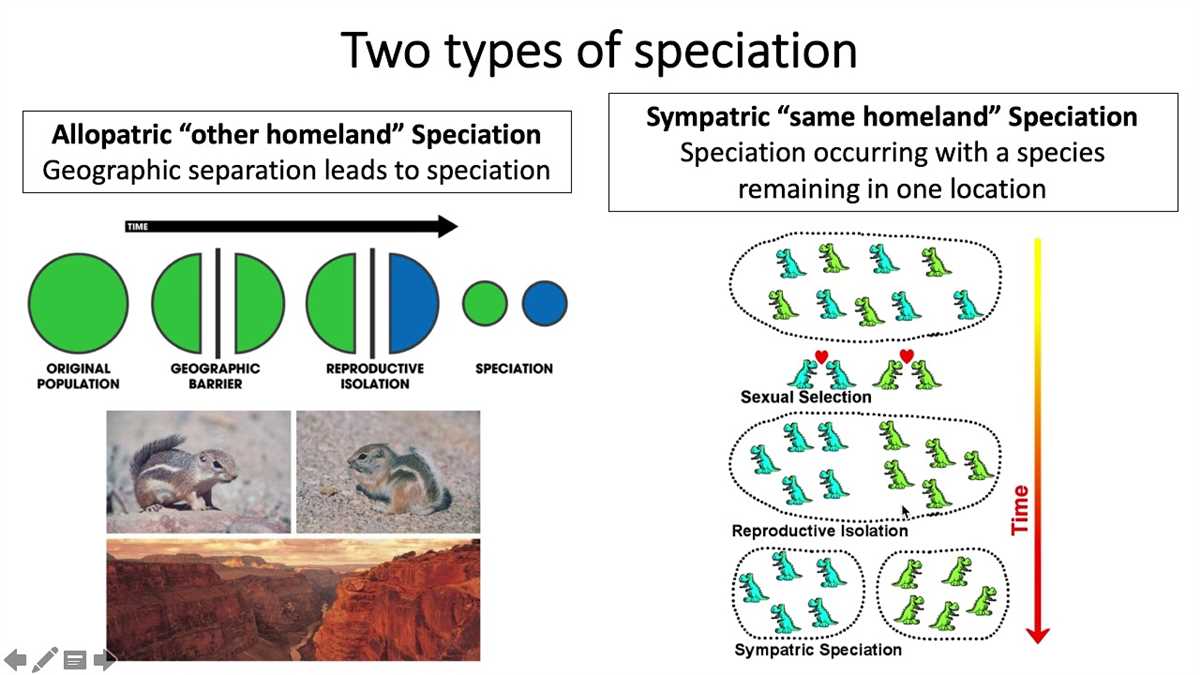
Speciation requires reproductive isolation to evolve. The question is not whether it happens but how. Allopatric speciation occurs when a physical barrier divides a population. This is the textbook model and it is correct for many systems. But it is not the only model, and assuming it is the default model leads to errors in interpretation. Parapatric speciation happens when populations diverge along an environmental gradient without complete geographic separation. Gene flow continues at the boundary between the two populations, but selection against hybrids or strong divergent selection across the gradient maintains the split. This is harder to demonstrate empirically because you need to rule out past fragmentation. I worked on a project involving stickleback fish in a series of connected lakes where the ancestral population had marine ancestry. The morphological and genetic divergence between lake and stream forms was sharp, but there was some gene flow at the interface. Distinguishing parapatric divergence from secondary contact after allopatric isolation required ancient DNA and careful dating of the colonization events. Without that temporal data, you could easily misinterpret the pattern. Sympatric speciation remains controversial but is not impossible. The best-supported examples involve host-plant shifts in phytophagous insects. Rhagoletis pomonella, the apple maggot fly, shifted from hawthorn to apple trees in North America roughly 200 years ago. The two host races now differ in mating timing because apple fruits ripen earlier than hawthorn fruits. There is partial reproductive isolation despite ongoing gene flow. This is speciation in action, but it is also speciation with gene flow, which means the classic biological species concept does not apply cleanly.
The biological species concept itself is a tool, not a law of nature. It defines species by reproductive isolation, but many valid species groups do not fit this definition. Hybridizing plant species, ring species like the Larus gull complex, and bacterial taxa all break the concept. I recommend using a pluralistic approach. Combine phylogenetic criteria with ecological and morphological data rather than relying on one species definition for everything.
Practical Problems You Will Encounter
If you are actually studying selection or speciation and not just reading about it, here are the issues that will slow you down. Sample size and sampling design matter enormously. Sequencing ten individuals from a widely distributed species gives you a misleading picture of population structure. I once analyzed a dataset where the sampling covered the range edges but missed the center of the distribution. The apparent pattern of isolation by distance looked strong, but filling in the central populations revealed a completely different story with multiple refugia during the last glacial maximum. Always map your sampling locations against known biogeographic features before interpreting the genetic results. Genome-wide association studies for speciation traits are powerful but prone to false positives if population structure is not properly corrected. Using principal components as covariates helps but does not fully eliminate stratification, especially in recently diverged lineages. Mixed models like EMMAX or GEMMA are better, but they assume a specific genetic relationship structure that may not fit your system. Validate your findings with independent crosses or reciprocal transplant experiments whenever possible.
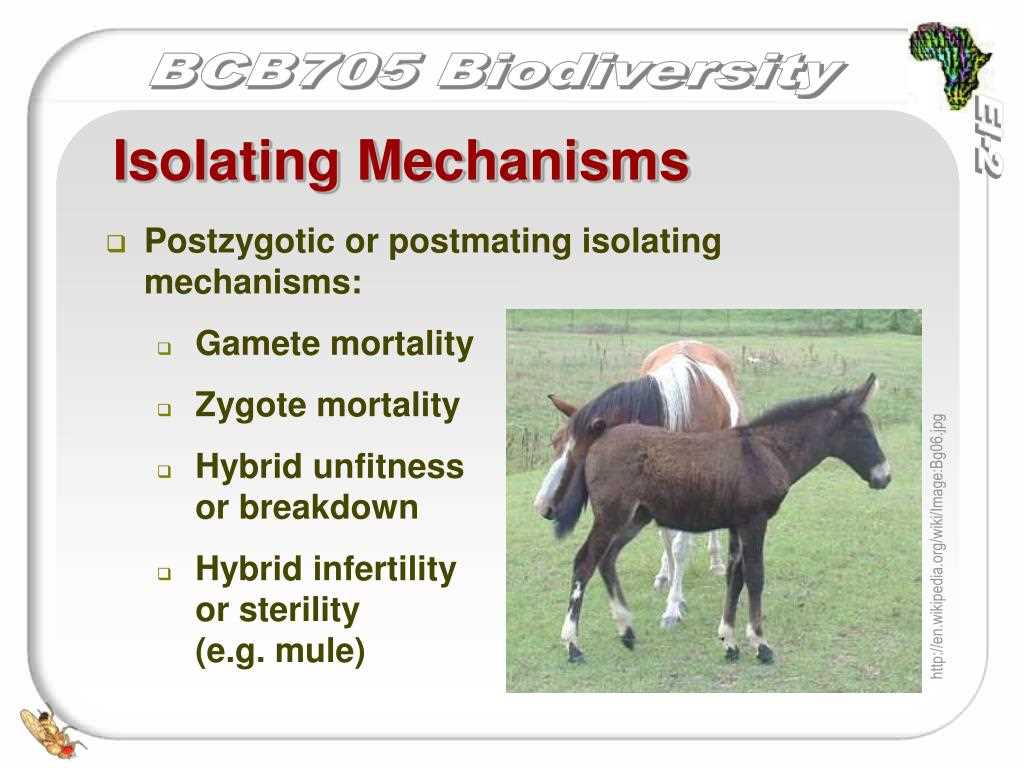
Gene flow after initial divergence complicates phylogenetic inference. Many speciation events are not clean splits. There is often prolonged gene flow during divergence, which means a single species tree does not accurately represent the history. Coalescent-based methods like ASTRAL or SVDquartets account for incomplete lineage sorting, but they do not handle gene flow well. If you suspect admixture, use methods like D-statistics, f4-ratio testing, or phylogenetic networks. Interpreting a standard bifurcating tree as the true species history when gene flow occurred will give you incorrect divergence time estimates and misleading conclusions about the speciation process.
What Selection And Speciation Research Gets Wrong Frequently
Overinterpreting correlation as causation is the most common error. Finding a genomic region associated with a phenotypic difference and calling it a speciation gene is premature. That region may contain the causal variant, or it may be in linkage disequilibrium with the causal variant, or it may be a neutral region that happens to be near the causal variant. Fine mapping and functional validation are necessary steps that many papers skip because they are expensive and time-consuming. Another frequent mistake is assuming that divergence peaks in genome scans represent actual barriers to gene flow. Divergence peaks can arise from reduced recombination, background selection, or local adaptation to different environments. Only when a peak coincides with reduced gene flow in multiple independent comparisons or shows up in reciprocal transfer experiments can you confidently call it a barrier locus. The rest is suggestive at best. Speciation timelines are often estimated incorrectly. Molecular clocks are approximate, and calibration points from the fossil record are sparse for many groups. Using a single calibration point and applying it genome-wide introduces systematic error. Multiple calibrations across different genes and loci improve accuracy, but even then, ancestral population sizes and generation times add substantial uncertainty to divergence estimates. Report confidence intervals, not point estimates, and be honest about how wide those intervals are.
When These Approaches Fail Completely
There are systems where selection and speciation leave almost no genomic trace. Rapid radiations, such as cichlid fishes in the East African rift lakes or Hawaiian silverswords, produce short internal branches on the species tree. Incomplete lineage sorting is pervasive, and gene trees conflict with each other extensively. No amount of additional sequencing will resolve the phylogeny cleanly because the divergence events happened faster than coalescence. In these cases, phylogenetic methods reach their limit, and you need to rely more heavily on ecological and behavioral data to understand the speciation process. Asexual organisms do not speciate in the conventional sense. Bacteria and archaea exchange genes horizontally, and their lineage boundaries are blurry at best. Applying vertebrate or angiosperm speciation models to microbial systems produces nonsense results. Use pangenome frameworks and average nucleotide identity thresholds instead, and accept that the species concept itself is fuzzy in these domains.

A Practical Framework For Approaching The Problem
Start with a clear hypothesis about the mechanism you think is driving divergence. Is it ecological selection, sexual selection, drift, or a combination? The hypothesis determines your sampling strategy and your analytical methods. Collect genomic data from multiple populations across the suspected divergence gradient. Include outgroups. Sequence enough individuals per population to distinguish selection from demography. Ten diploid individuals per population is a reasonable minimum for most population genomic analyses. Fewer than that and your allele frequency estimates are too noisy to be reliable. Test for demographic history first. Run structure analyses, compute FST, estimate migration rates, and fit demographic models using methods like fastsimcoal2 or dadi. Only after you have a demographic model can you reliably identify selection outliers. Doing it in the opposite order inflates false positive rates dramatically.
Validate candidate regions with independent evidence. Look for expression differences, phenotypic assays, or experimental crosses. Genomic data alone rarely provides conclusive evidence for adaptive divergence, but combined with functional data it becomes much stronger. The field has moved past simple gene-for-gene adaptation stories. Most speciation involves hundreds or thousands of loci, many with small effects, interacting with gene flow and demography in complex ways. The mystery is not whether selection and speciation are connected. They clearly are. The mystery is understanding the relative contribution of each mechanism in any given system, and that requires careful work, not dramatic claims.