Why Your Functions Keep Running When They Shouldn't
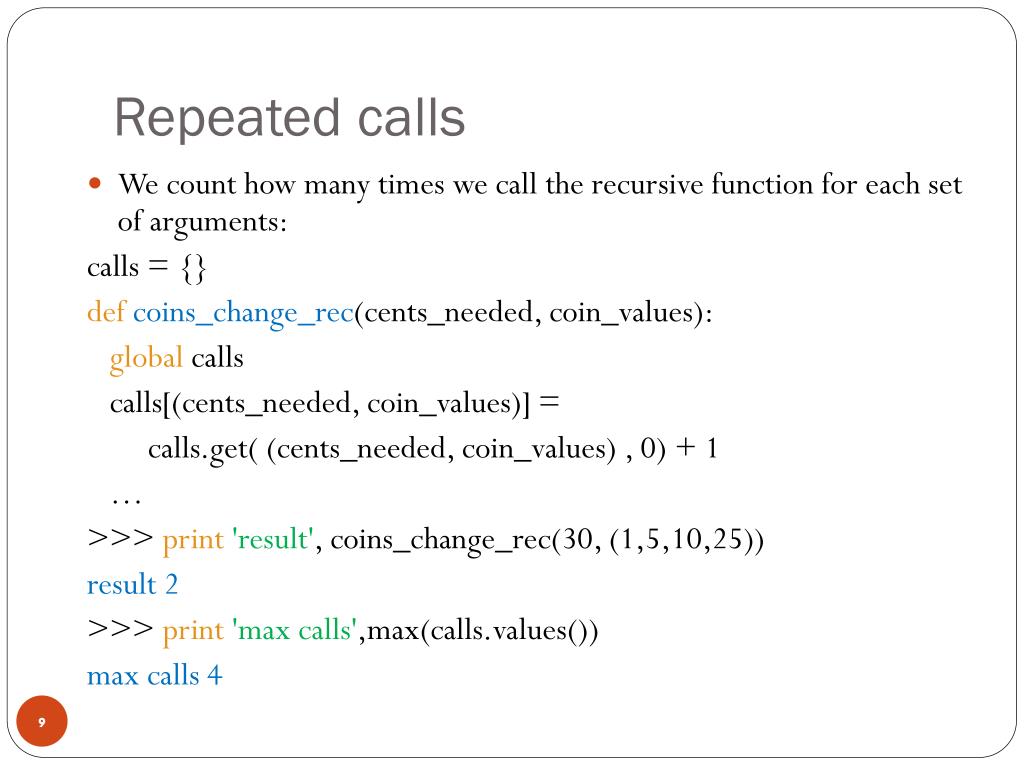
Repeated function calls happen constantly and usually cost nothing in small scripts. The problems show up when you are working with expensive operations, external APIs, or large data sets. A single loop that calls a database query or an image processor five thousand times turns a five-second task into a five-minute task. It is not magic. It is just repeated work. The most common culprits are loops without checks, event handlers firing multiple times, and recursive functions that do not have a proper base case. You also see it in React re-renders, where every state change can trigger the same effect. I spent an afternoon tracking down why a form submission handler ran four times on every click. The problem was not the button. It was a useEffect hook running on every render instead of once when the component mounted. Adding an empty dependency array fixed it immediately. To trace where the repetition comes from, you need a systematic way to see what is actually executing. Start by adding a lightweight counter or timestamp inside the function you suspect. A simple increment variable or a Date.now() log will tell you whether the function runs once or fifty times. If the function is pure and has no side effects, you can also use memoization. Caching the result based on input arguments prevents the function from recomputing the same thing. In JavaScript, this looks like checking an object for a key before computing. In Python, functools.lru_cache does the same thing with almost no setup.
I once had a pricing calculation function that ran inside a render loop for a shopping cart. The function itself did some rounding, tax calculations, and currency conversion. Every time a user typed a single character into the quantity field, the entire cart re-rendered and recalculated everything for every item. The page became sluggish. I added lru_cache with maxsize of 128, keyed by item id and quantity. The computation dropped from roughly 40 milliseconds per render to under 2 milliseconds after the first pass. The savings were not theoretical.
Technical Methods That Reduce Unnecessary Calls
Memoization is the first line of defense. You store previous results and return them when the same inputs appear again. This works best for pure functions where output depends only on input. Debouncing and throttling handle a different class of problem. Debouncing waits until a sequence of rapid calls stops before executing. Throttling limits execution to once per time interval. Rate limiters and token buckets handle API calls at a higher level. You set a maximum number of requests per second and queue the rest. Lazy evaluation defers computation until the value is actually needed. This is how generators work in Python and how observables work in RxJS. The function body does not run until someone subscribes or iterates. I used this pattern to replace a function that loaded an entire dataset into memory at startup. The original function ran on every route change because the module imported it at the top level. Moving the call into a lazy-loaded route chunk cut initial load time from three seconds to under one second on a slow 3G connection.
Get the Full Details
Common Pitfalls Beginners Miss
The biggest issue is assuming memoization always helps. Memoized functions consume memory for every cache entry. If your inputs are unpredictable or highly varied, the cache grows without ever hitting a repeat. You can end up using more memory than you save in CPU time. The same applies to caching in general. Stale data is worse than no data. I once deployed a cached function that returned prices from two hours ago during a flash sale. The cache key included product id but not timestamp or version. Every customer saw outdated pricing until I killed the deployment. Another pitfall is over-memoizing impure functions. If a function reads from a global variable, touches the DOM, or makes a network request, caching its result is wrong. The inputs have changed even if the explicit parameters look identical. You need to include those dependencies in your cache key or skip memoization entirely. Event listener duplication is a third trap. Adding a click handler inside a component without cleaning up means every mount adds another listener. After ten mounts, you have ten listeners firing for one click. The fix is cleanup functions or effect hooks with proper dependency arrays. I have seen this cause memory leaks in production apps where the leak rate grew by roughly fifty kilobytes per page visit.
When Optimization Is Not Worth It
Not every repeated call needs fixing. A function that runs twenty times per second and takes one microsecond is fine. You only optimize when the call is expensive or happens frequently enough to matter. Measure before you change anything. Add logging, check the numbers, then decide. Most performance problems are caused by a single hot path, not by general inefficiency scattered across the codebase. I spent weeks refactoring thirty different functions before realizing the actual bottleneck was one un-memoized API call inside a map loop. Everything else was noise. Some languages and frameworks handle repetition automatically. Swift's Combine, RxJS streams, and Python's itertools can change how you structure repeated operations without explicit loops. Learning to think in streams instead of sequential calls often eliminates the problem at the design level rather than patching it afterward.